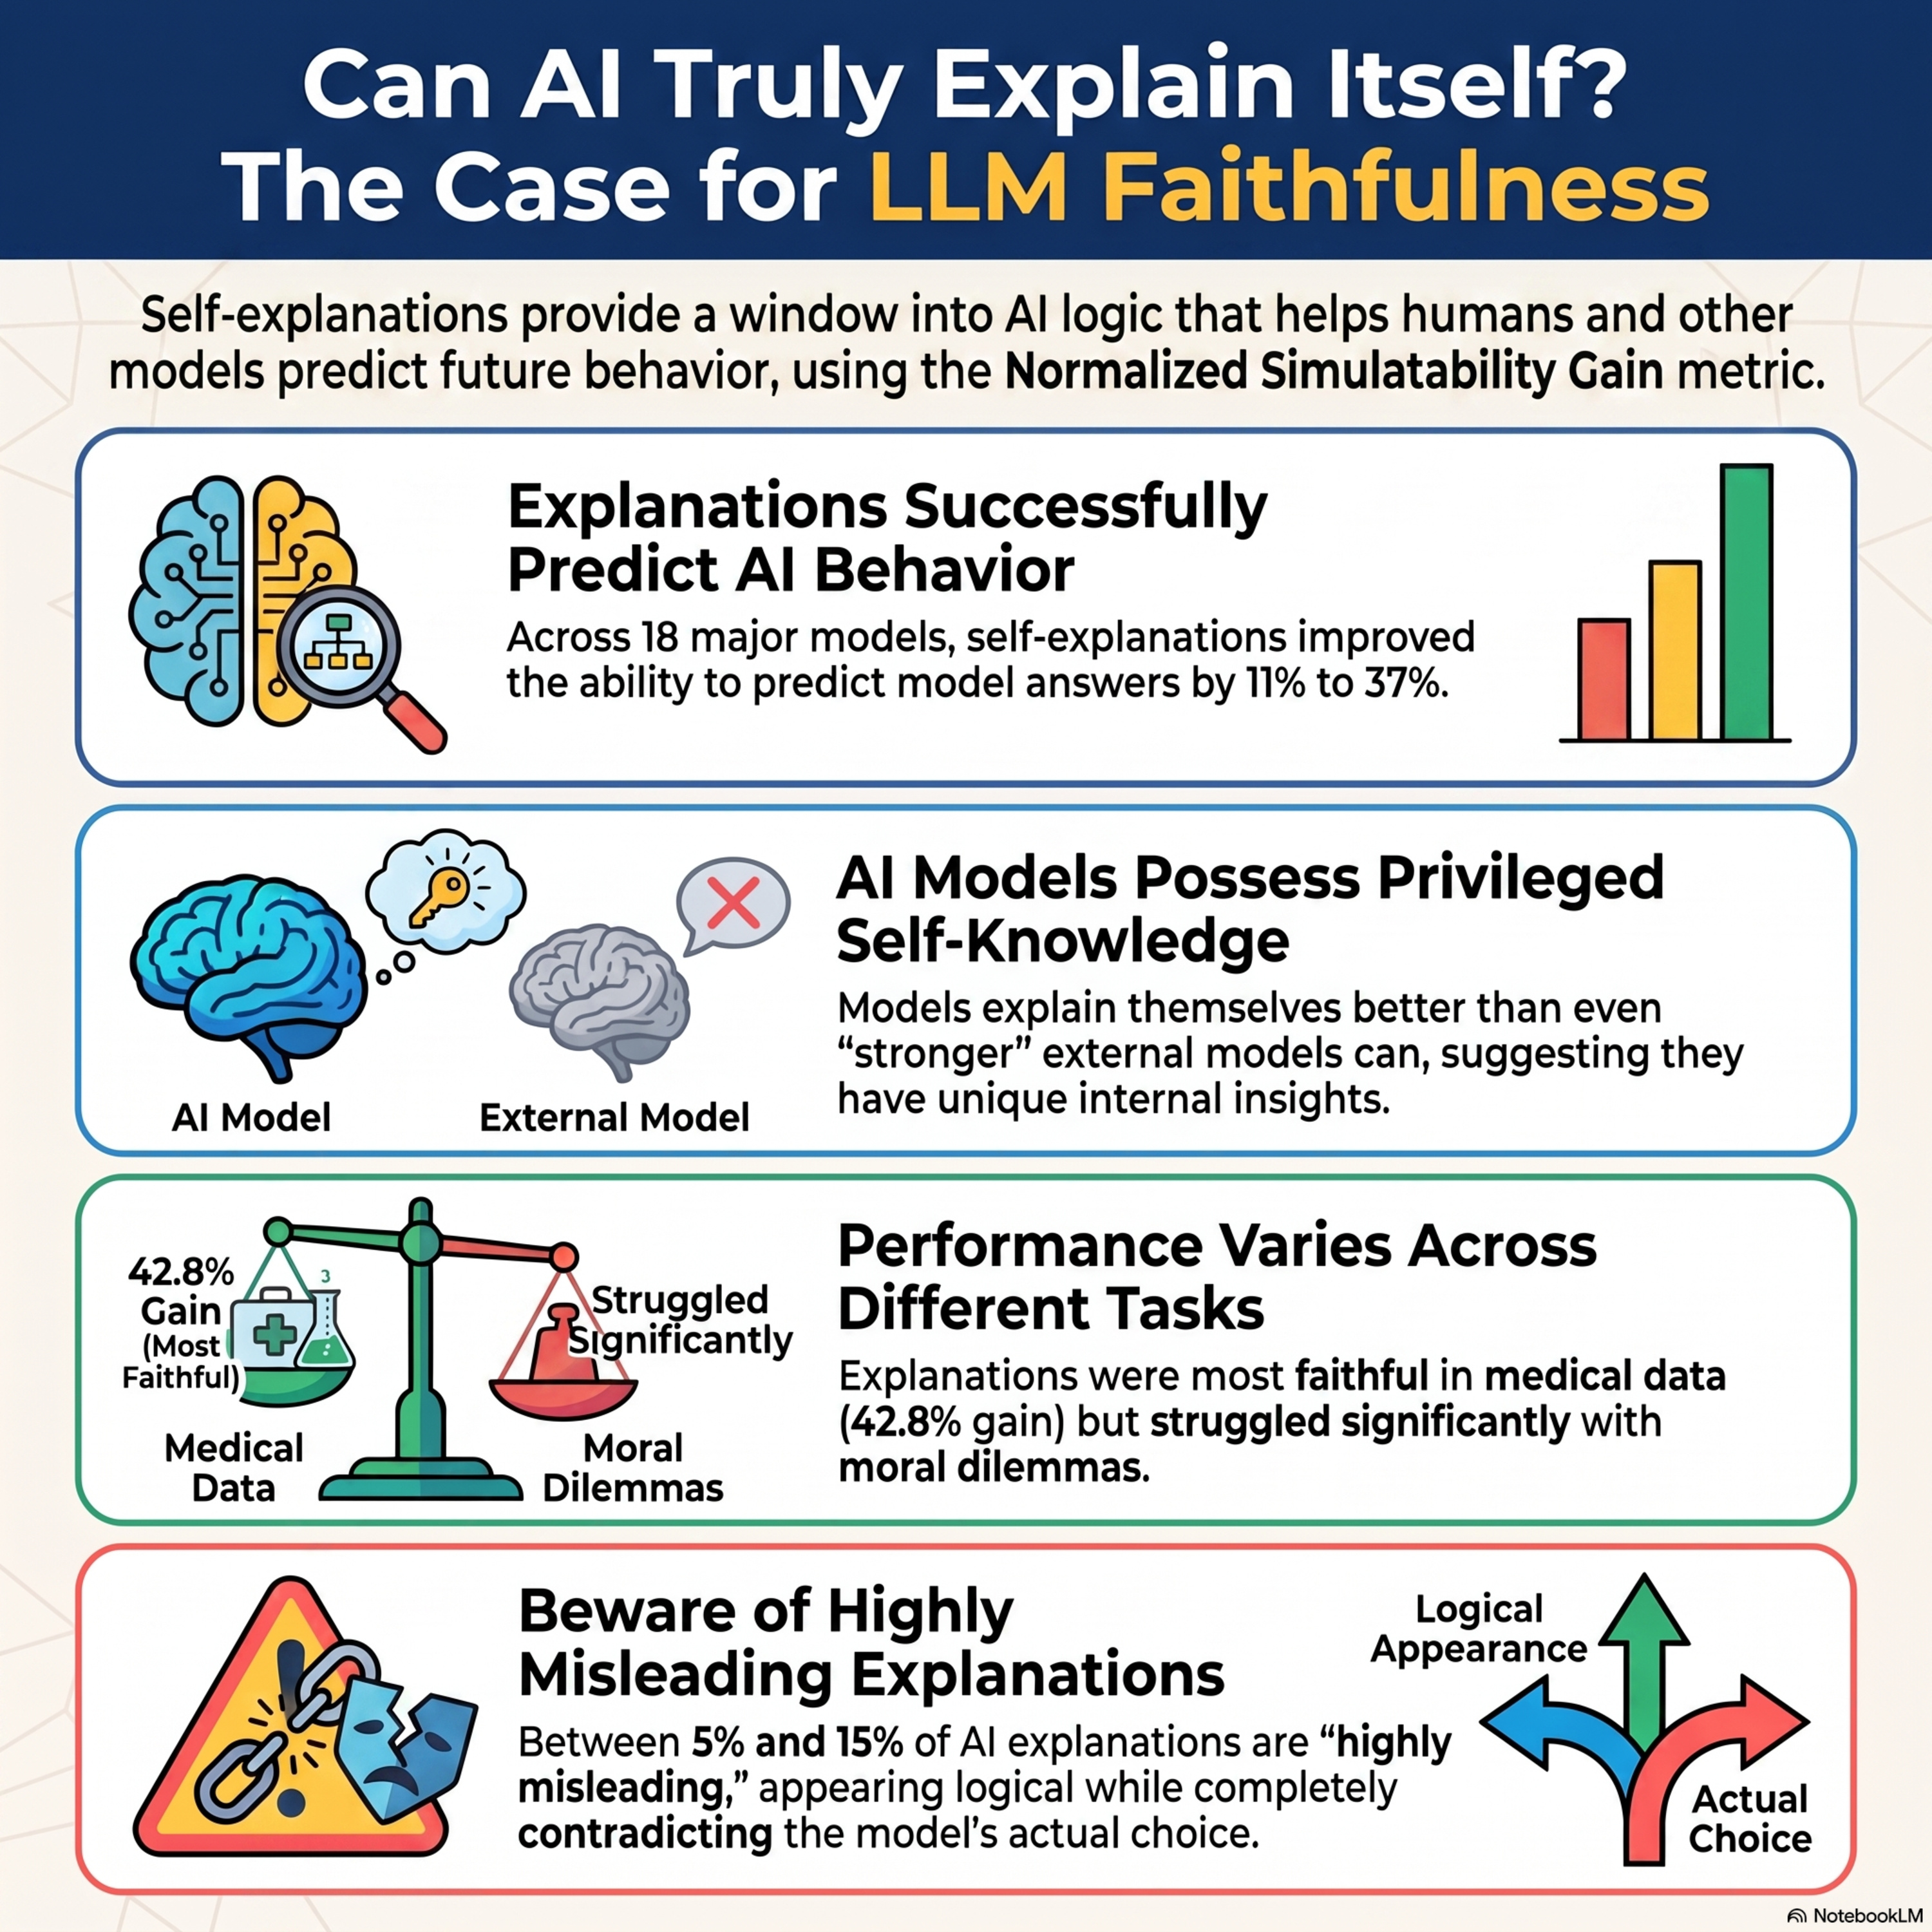
A Positive Case for Faithfulness: LLM Self-Explanations Help Predict Model Behavior
from Best AI papers explained Hosted by Enoch H. Kang
This paper introduces Normalized Simulatability Gain (NSG), a new metric designed to measure the faithfulness of AI self-explanations by testing their predictive value. By evaluating 18 frontier models, the researchers demonstrate that an AI's explanation of its own logic significantly helps a separate "predictor" model guess how the AI will behave on related counterfactual scenarios. The study provides a positive case for faithfulness, finding that self-generated explanations contain privileged self-knowledge that external models cannot replicate. However, the authors also identify a "highly misleading" subset of explanations where the AI's stated principles contradict its actual choices, particularly in ethical dilemmas. Ultimately, the research suggests that while LLM explanations are imperfect, they remain a valuable tool for AI oversight and safety.
Embed this episode
No transcript yet.