
EPISODE · Feb 20, 2026 · 25 MIN
Anthropic: Claude Prompt自动缓存
from 每日AI · host 每日新闻
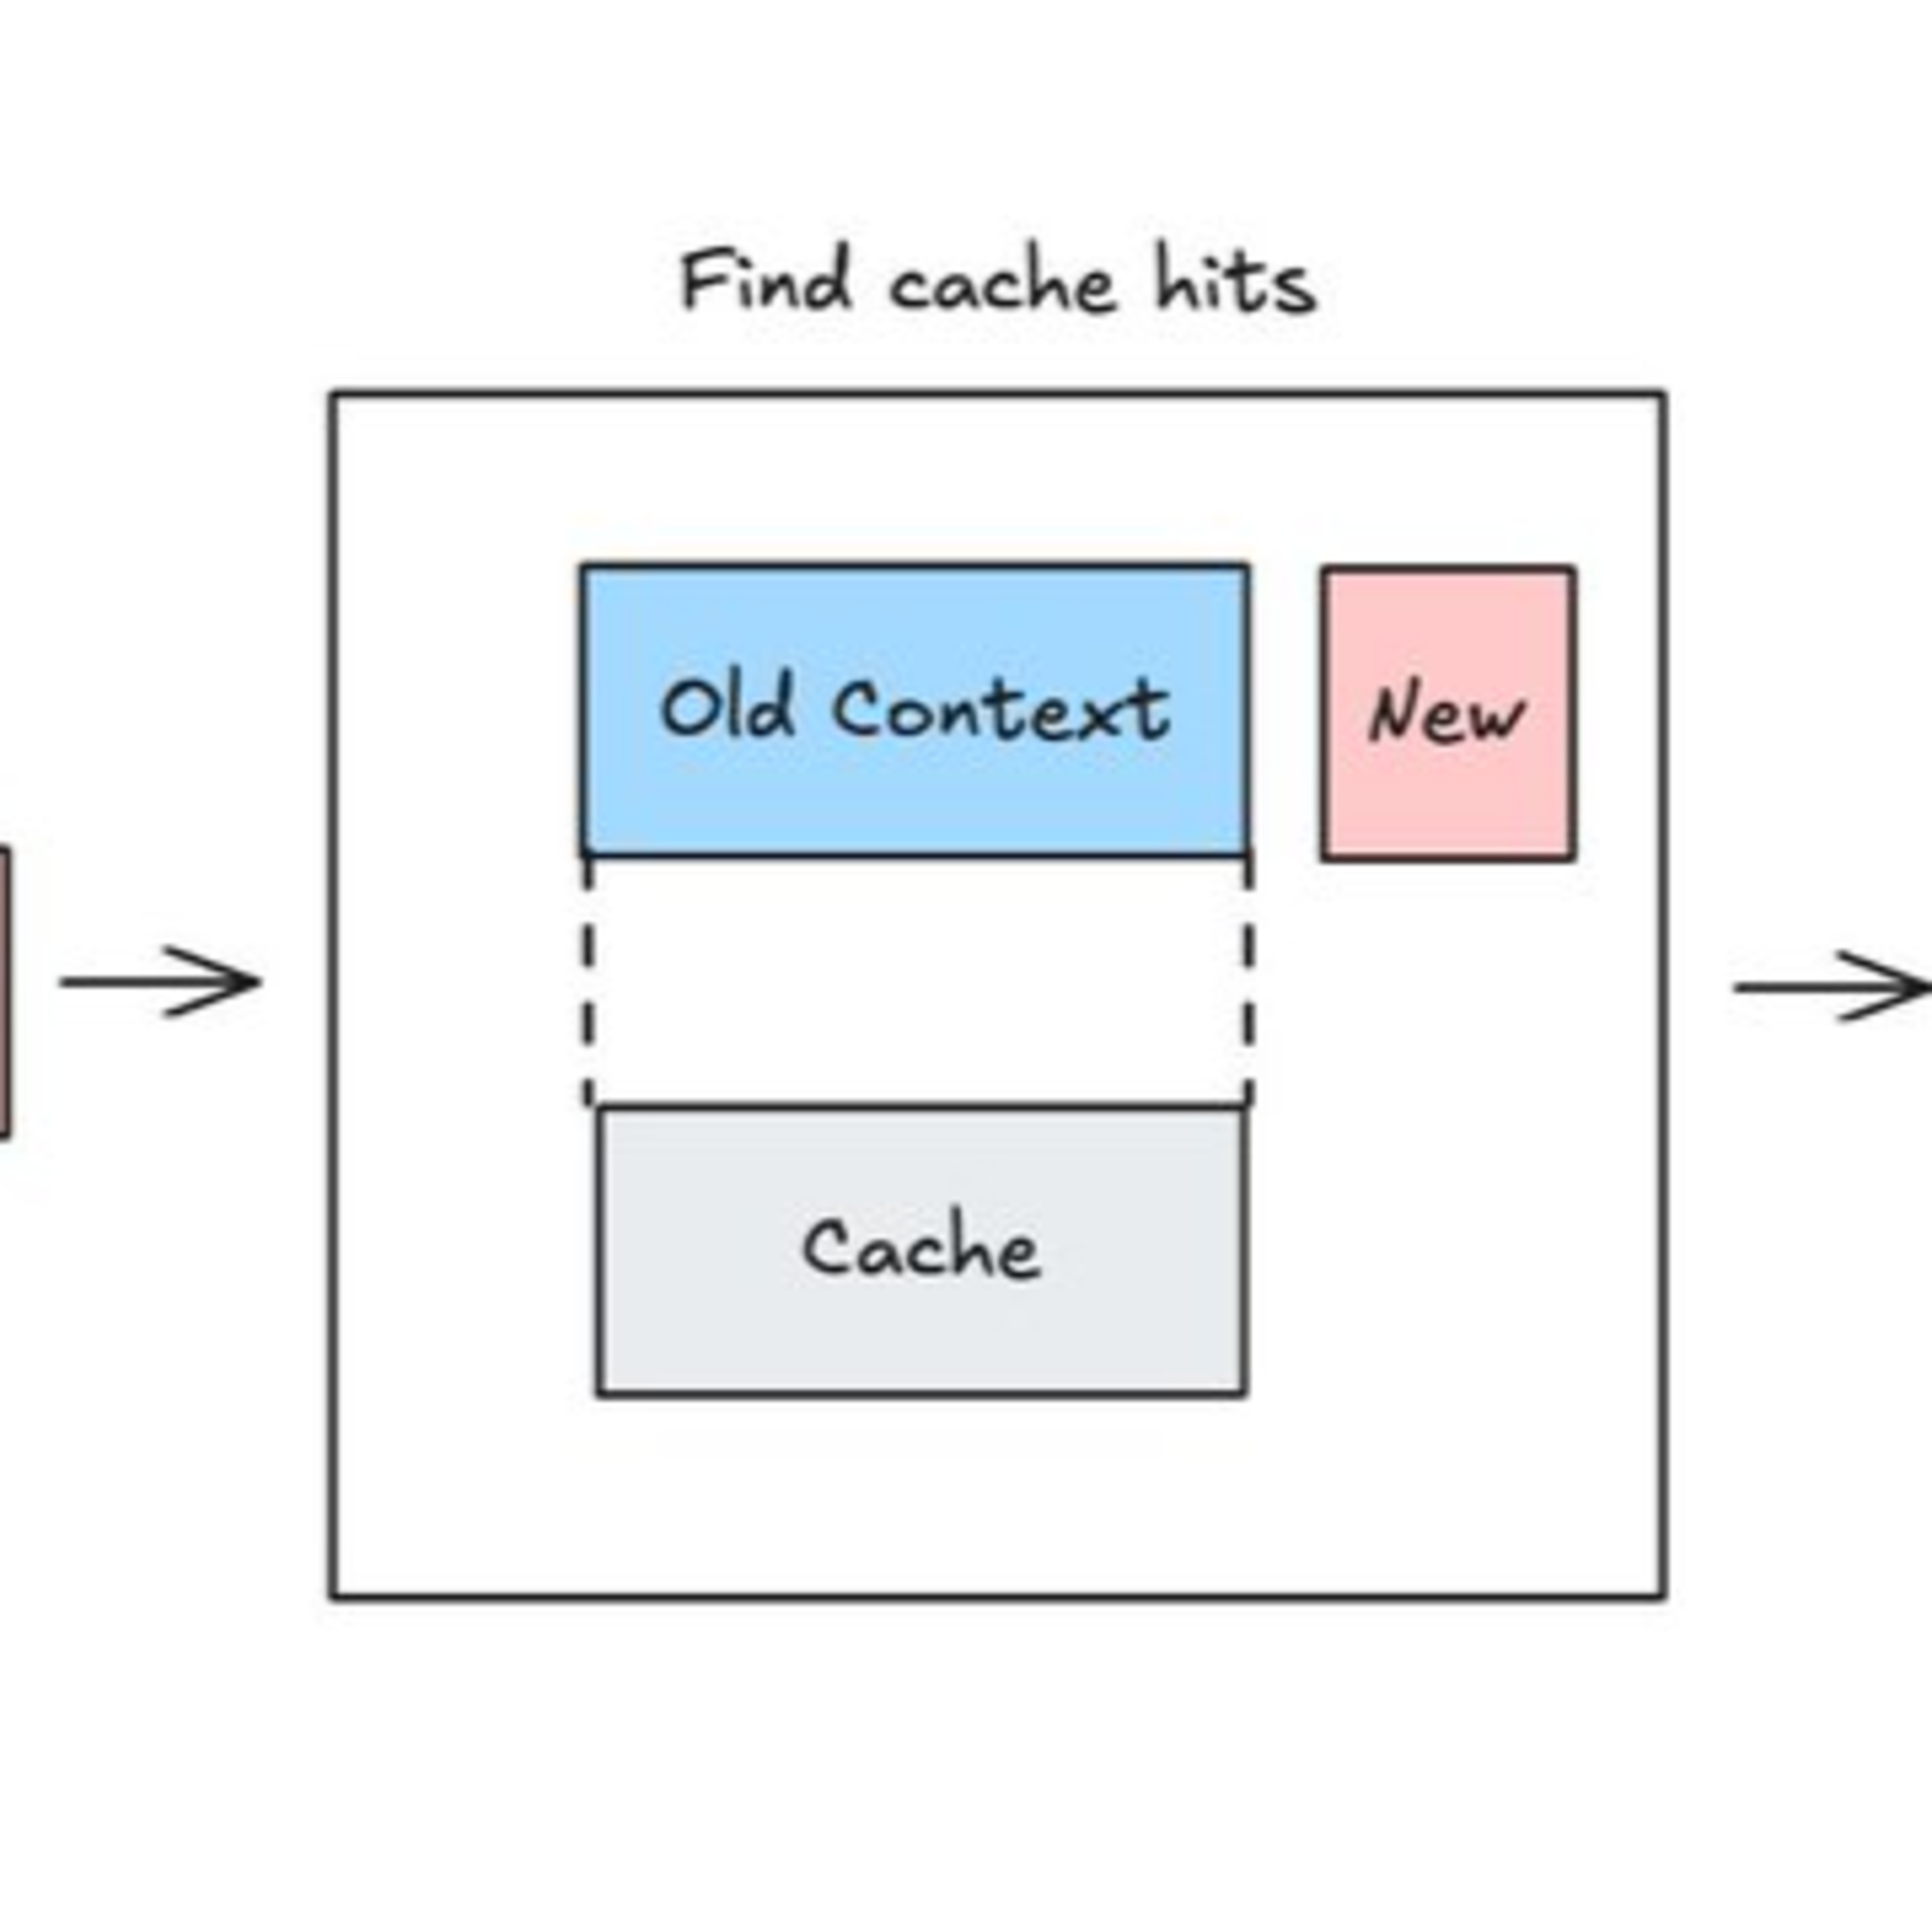
深入探讨了大语言模型推理性能的底层逻辑,重点分析了Transformer架构在实际运行中的算力与显存开销。作者通过一阶原理推导,详细解释了KV缓存(KV cache)如何通过空间换时间来避免重复计算,并探讨了显存容量对批处理大小的限制。文中对比了计算密集型与访存密集型任务的差异,揭示了硬件带宽如何成为推理速度的关键瓶颈。此外,内容涵盖了模型并行化中的通信成本,以及如何通过数学公式预测不同硬件配置下的推理延迟。作者还将理论计算值与Nvidia FasterTransformer等实际基准测试进行了校验,为优化大模型推理效率提供了实用的分析框架。https://x.com/RLanceMartin/status/2024573404888911886There are some great resources (e.g., here from @sankalp or here from @kipply) on the details of LLM inference and caching. In general, LLM inference pipelines typically use a prefill phase that processes the prompt and a decode phase that generates output tokens.The intuition behind caching is that the prefill computation can be performed once, saved (e.g., cached), and then re-used if (part of) a future prompt is identical. Inference libraries / frameworks like vLLM and SGLang use different approaches to achieve this central idea.
Embed this episode
Ready to play
Anthropic: Claude Prompt自动缓存
No transcript for this episode yet
Similar Episodes
No similar episodes found.