Ask, Don’t Judge: Binary Questions for Interpretable LLM Evaluation and Self-Improvement
from Best AI papers explained Hosted by Enoch H. Kang
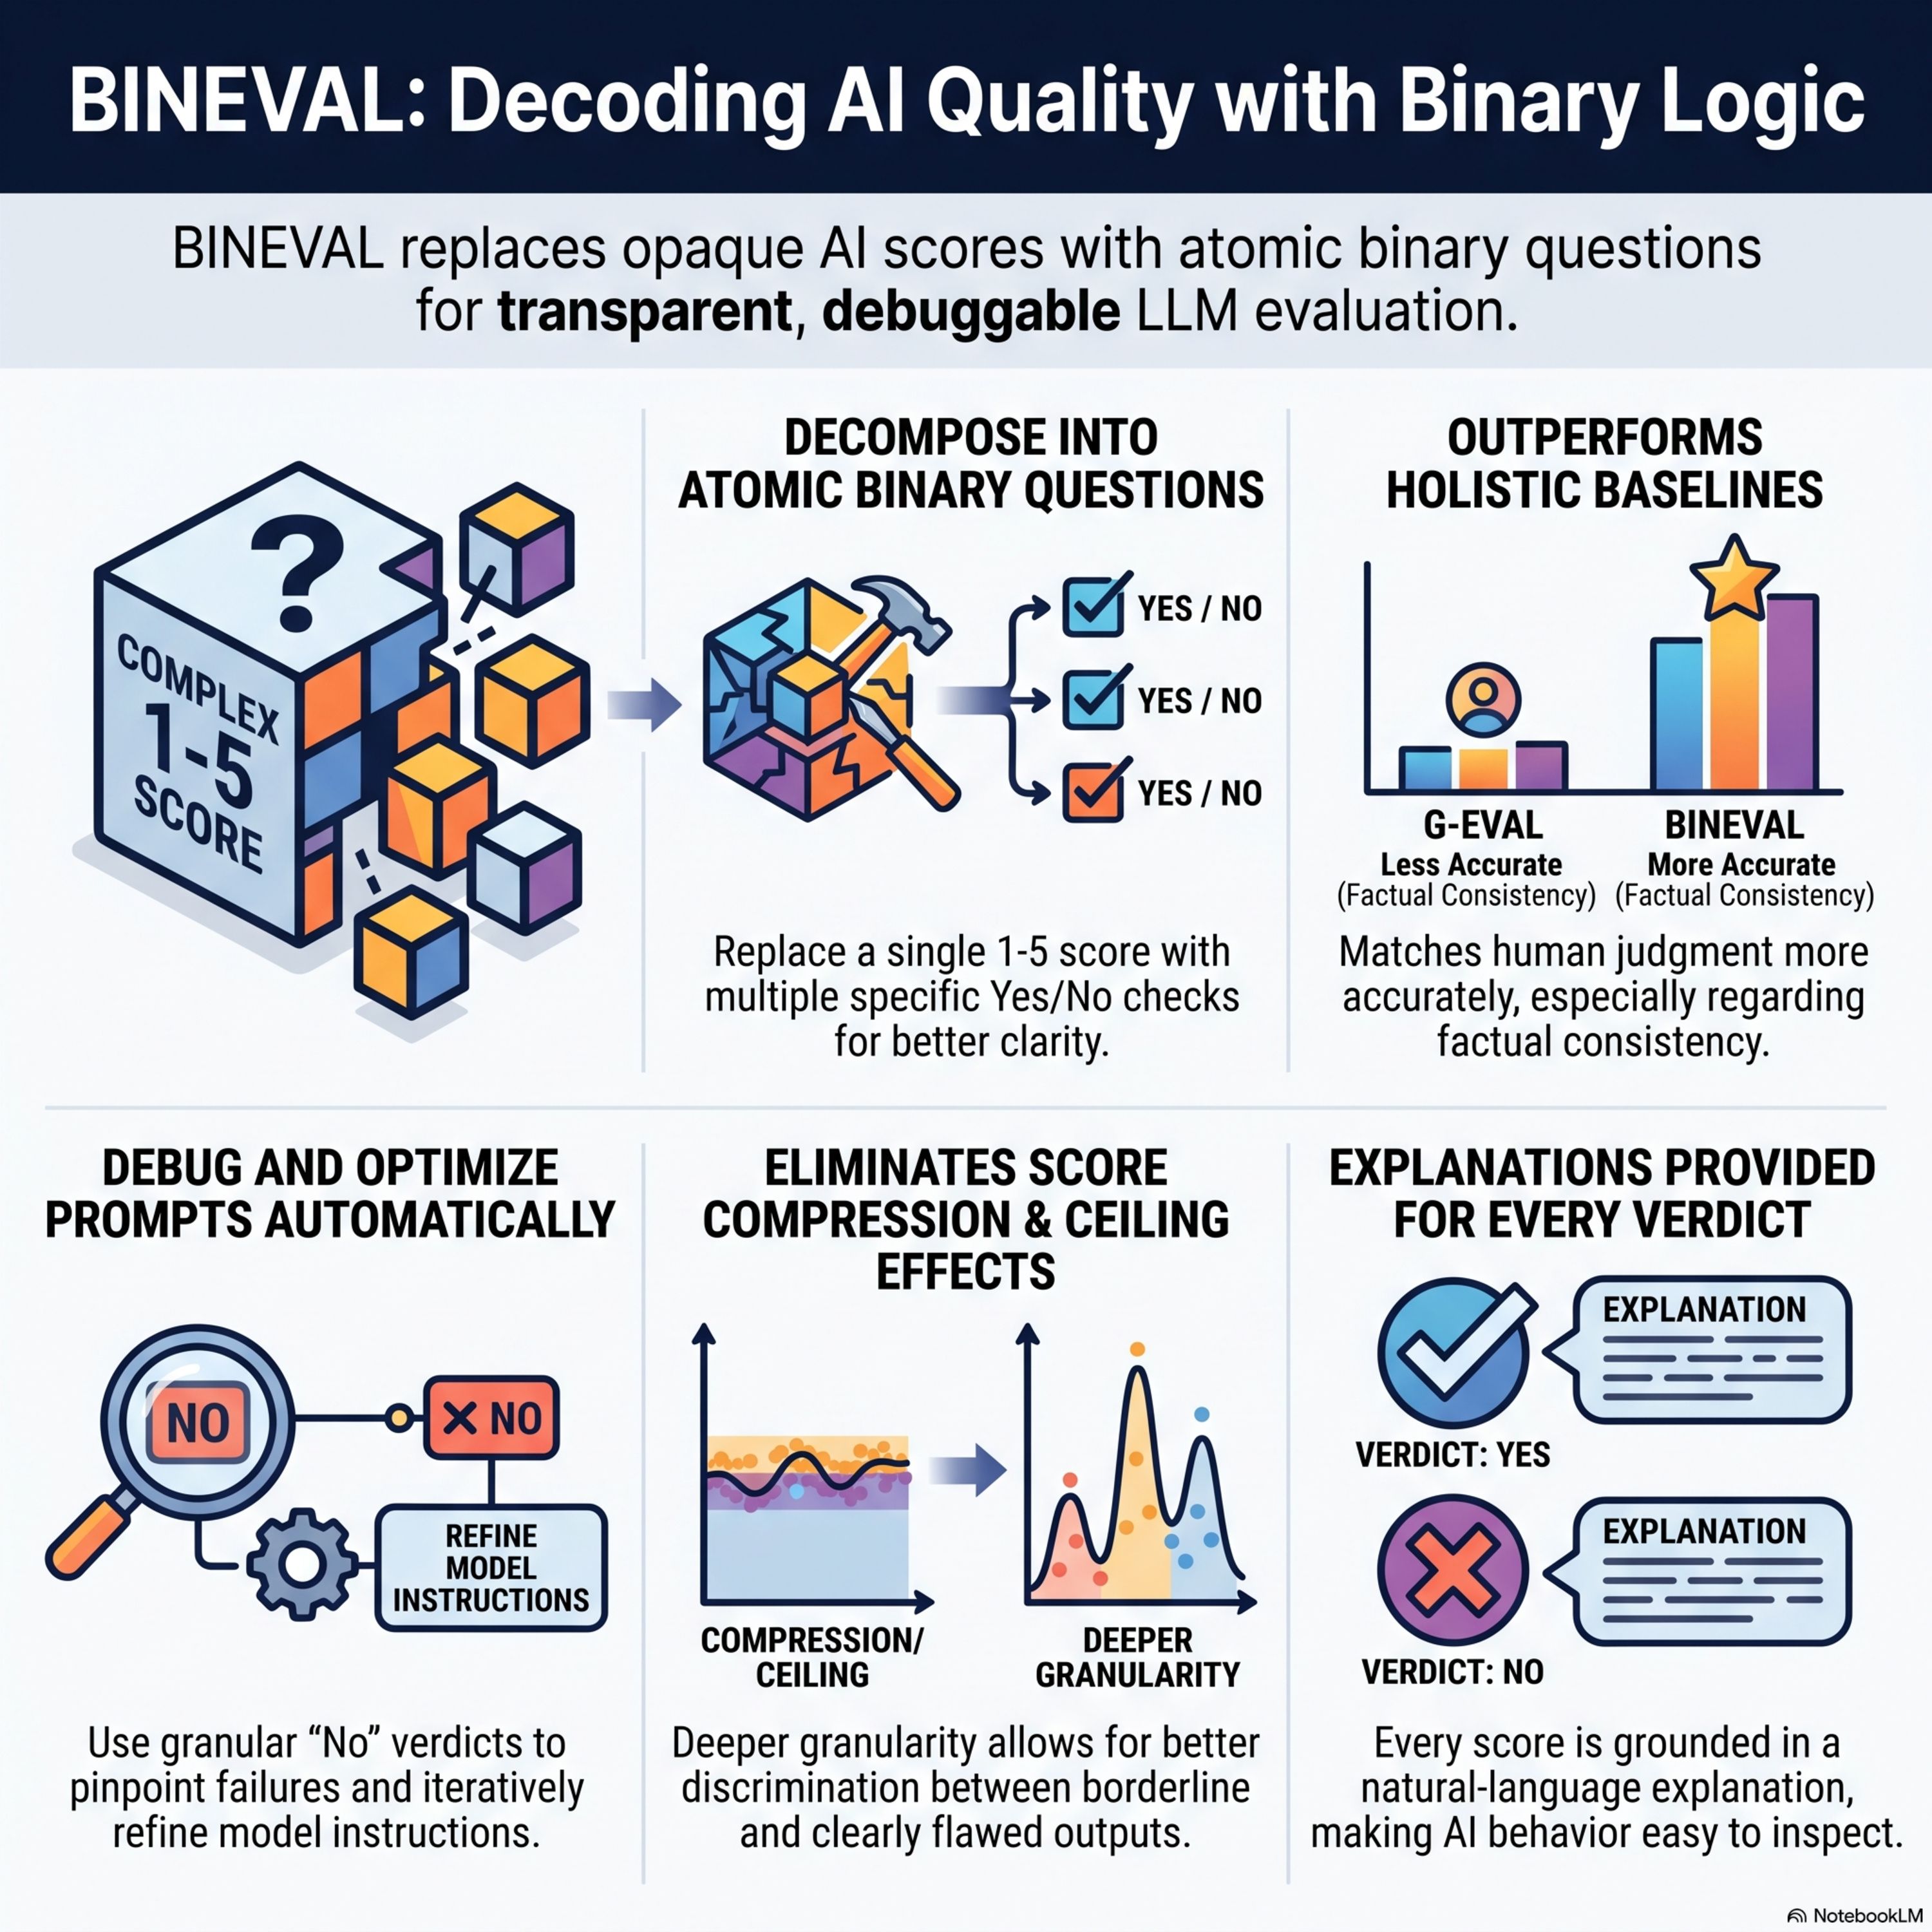
The research introduces BINEVAL, a novel evaluation framework that improves the reliability of Large Language Models (LLMs) by decomposing complex quality criteria into atomic binary questions. Unlike traditional holistic grading, which often produces opaque and inconsistent scores, this method utilizes a "decompose-then-verify" approach to generate transparent, multidimensional assessments. By aggregating simple yes/no verdicts into calibrated scores, the system achieves superior alignment with human judgment across tasks like summarization and dialogue. Beyond measurement, the framework supports an iterative optimization loop that uses question-level feedback to refine both evaluator rubrics and generation prompts. This diagnostic granularity allows developers to pinpoint specific failure modes, such as factual misattributions or formatting errors, that broader metrics typically obscure. Ultimately, BINEVAL demonstrates that breaking evaluation into checkable sub-tasks makes LLM outputs more interpretable, debuggable, and actionable for continuous model improvement.
Embed this episode
No transcript yet.