BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
from KnowledgeDB.ai Hosted by KnowledgeDB
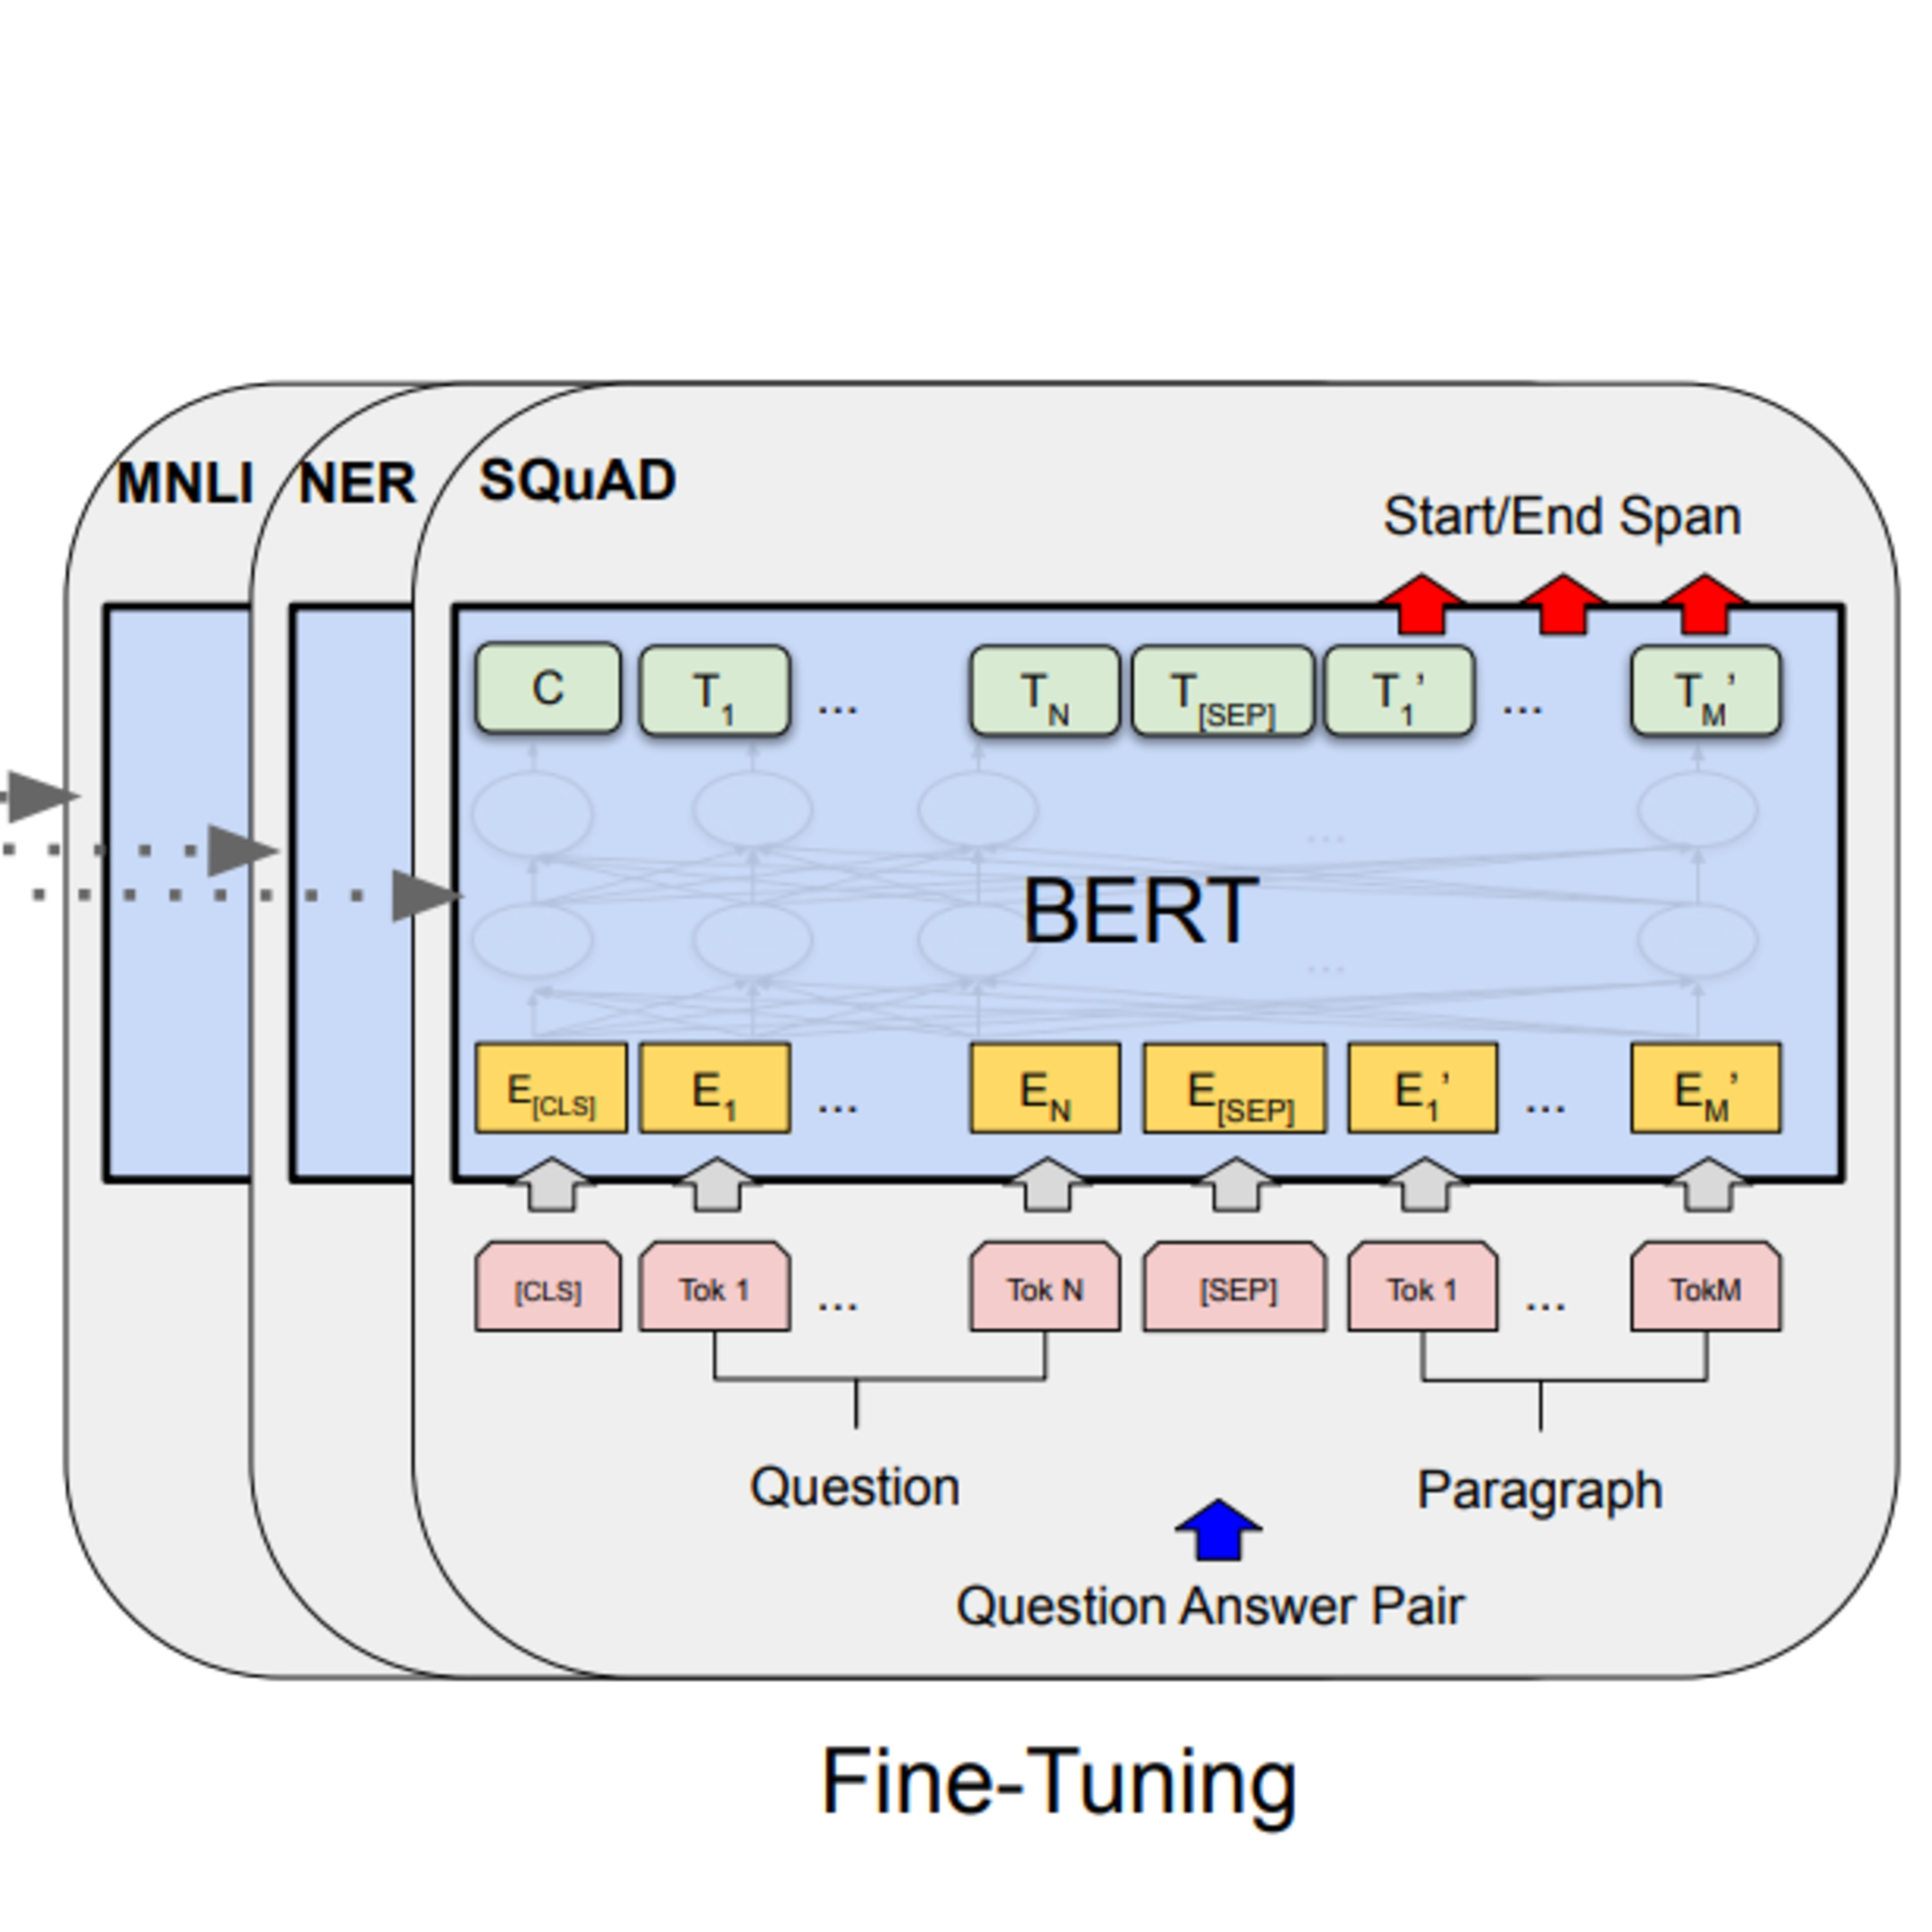
Ref: https://arxiv.org/abs/1810.04805 This research paper introduces BERT, a novel language representation model using bidirectional Transformer encoders. Unlike previous unidirectional models, BERT pre-trains deep bidirectional representations by jointly conditioning on both left and right context. This allows for state-of-the-art performance on various natural language processing tasks after fine-tuning with a single output layer. The authors present extensive experiments demonstrating BERT's superior performance and conduct ablation studies to analyze the impact of different model components and pre-training strategies. Finally, they compare the fine-tuning approach with a feature-based approach, showing BERT's effectiveness in both.
Embed this episode
No transcript yet.