Cerebras
from DecodeFM Hosted by Particle Future
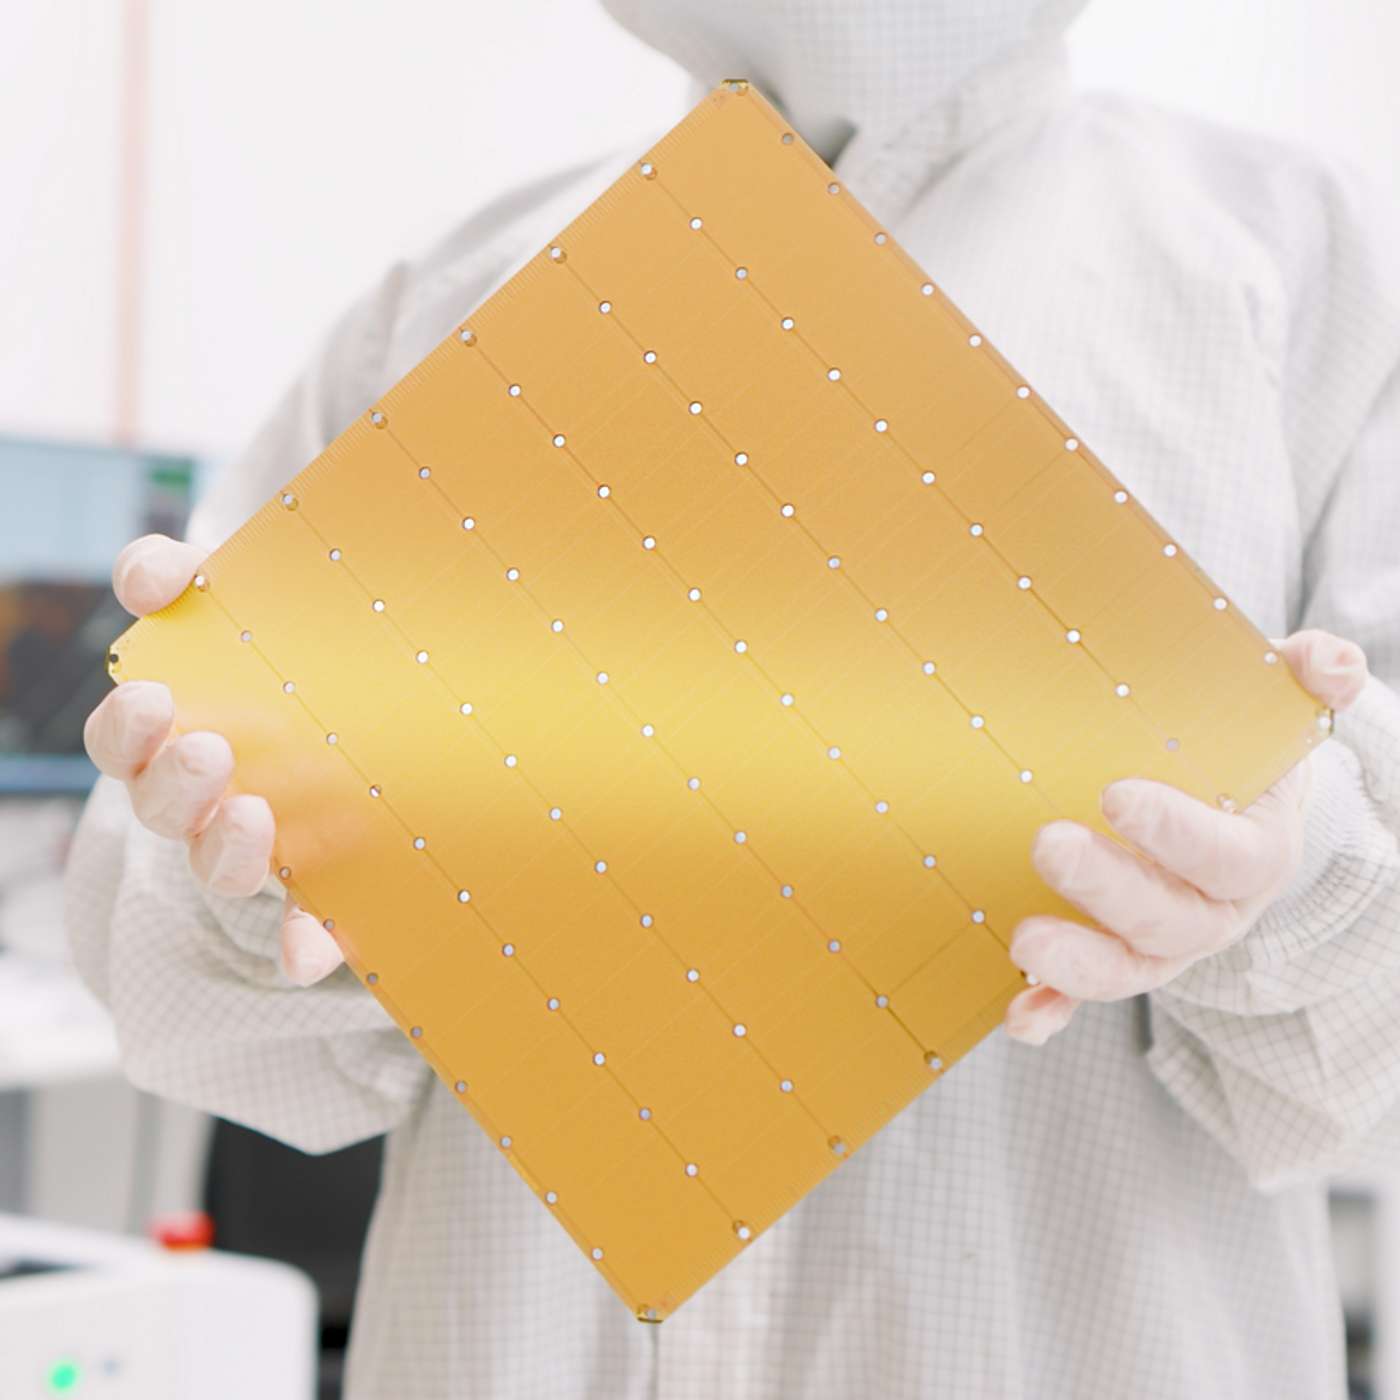
In this episode, we discuss Cerebras Systems and their Wafer-Scale Engine, currently the fastest LLM inference processor, with 7000x more memory bandwidth than nVidia H100. Together with G42, they’re also developing the Condor Galaxy, potentially the largest AI supercomputer. Is this all just hype? What are the real world use cases and why should average users care about it?
Embed this episode
No transcript yet.
Frequently asked questions
How long is this episode of DecodeFM?
This episode is 13 minutes long.
When was this DecodeFM episode published?
This episode was published on December 4, 2024.
Can I download this DecodeFM episode?
Yes. Use the download control on the episode player to save the publisher-provided media file.