CLIP: Learning Transferable Visual Models From Natural Language Supervision
from KnowledgeDB.ai Hosted by KnowledgeDB
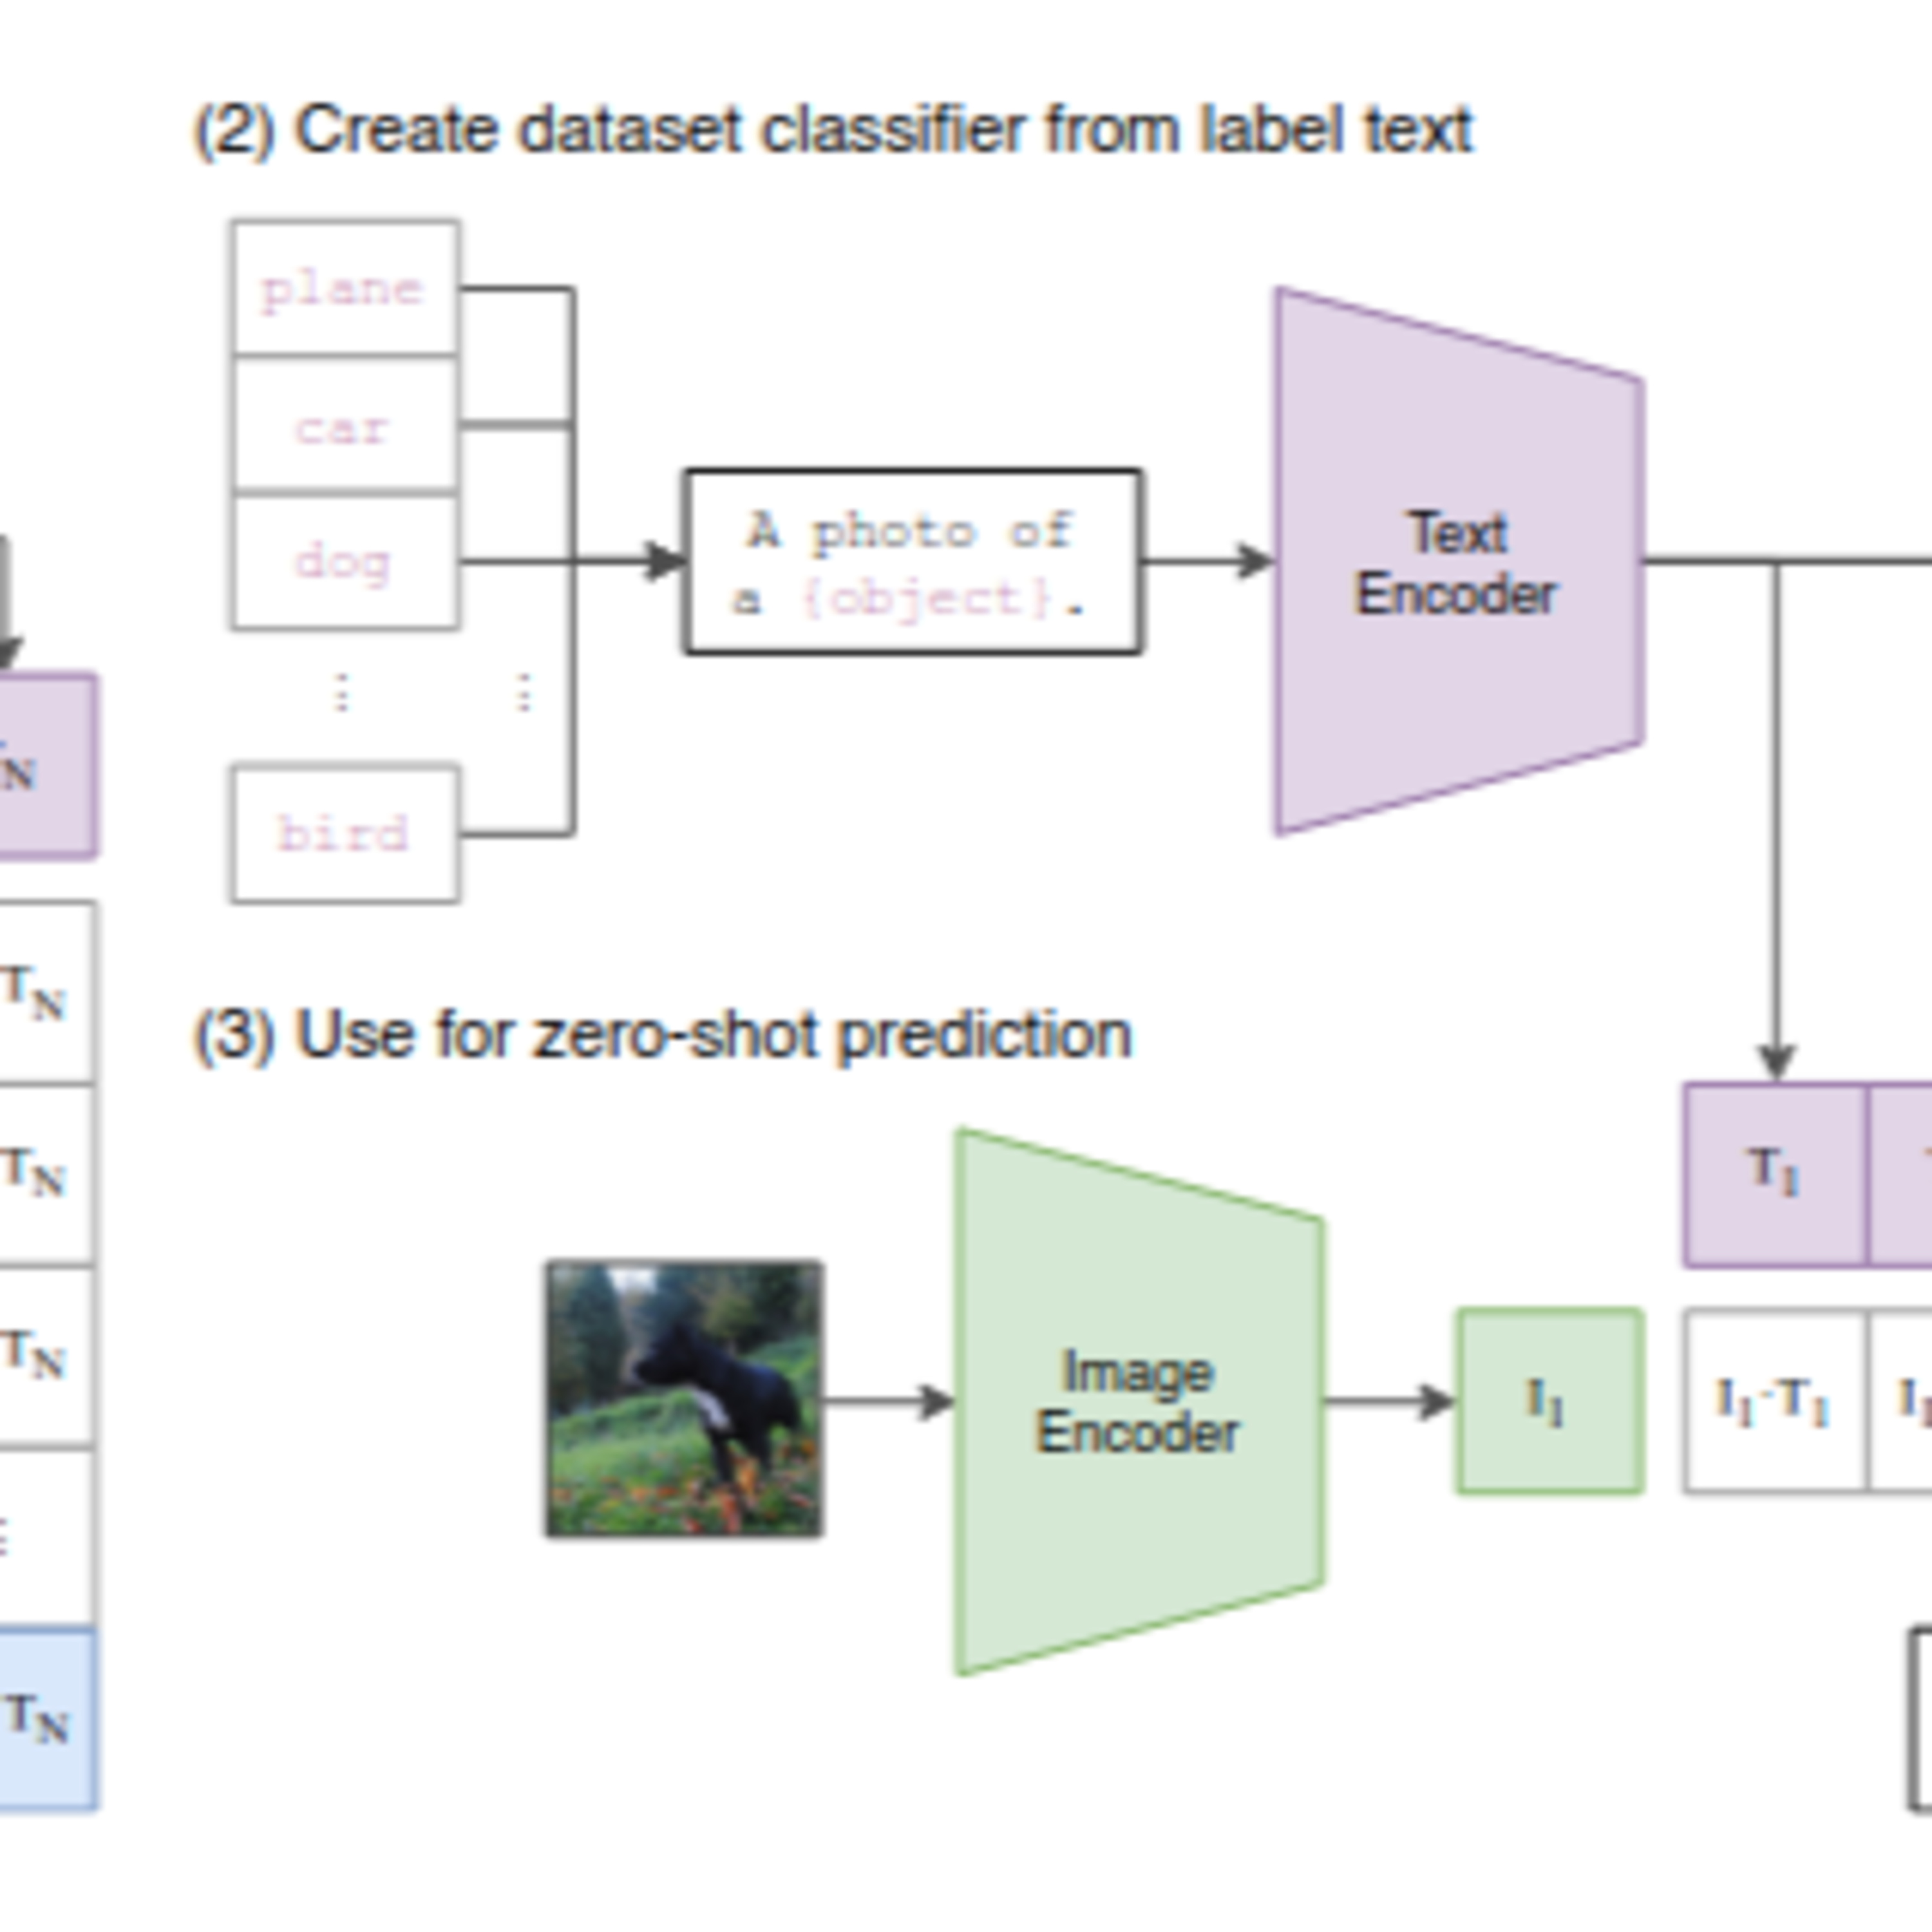
Ref: https://arxiv.org/abs/2103.00020 This research paper explores CLIP, a novel approach to image representation learning that leverages natural language supervision. CLIP's efficiency and effectiveness in zero-shot transfer learning are demonstrated through comparisons with existing models on various benchmark datasets. The study also investigates CLIP's robustness to distribution shifts and explores its potential biases and ethical implications, particularly in the context of surveillance. Furthermore, the paper analyzes data overlap concerns and the model's performance relative to human capabilities in few-shot learning. Finally, limitations of CLIP and areas for future research are discussed.
Embed this episode
No transcript yet.