
EPISODE · Jul 20, 2026 · 18 MIN
Course 40 - Web Scraping with Python | Episode 10: Navigating and Extracting Web Data with Beautiful Soup
from CyberCode Academy · host CyberCode Academy
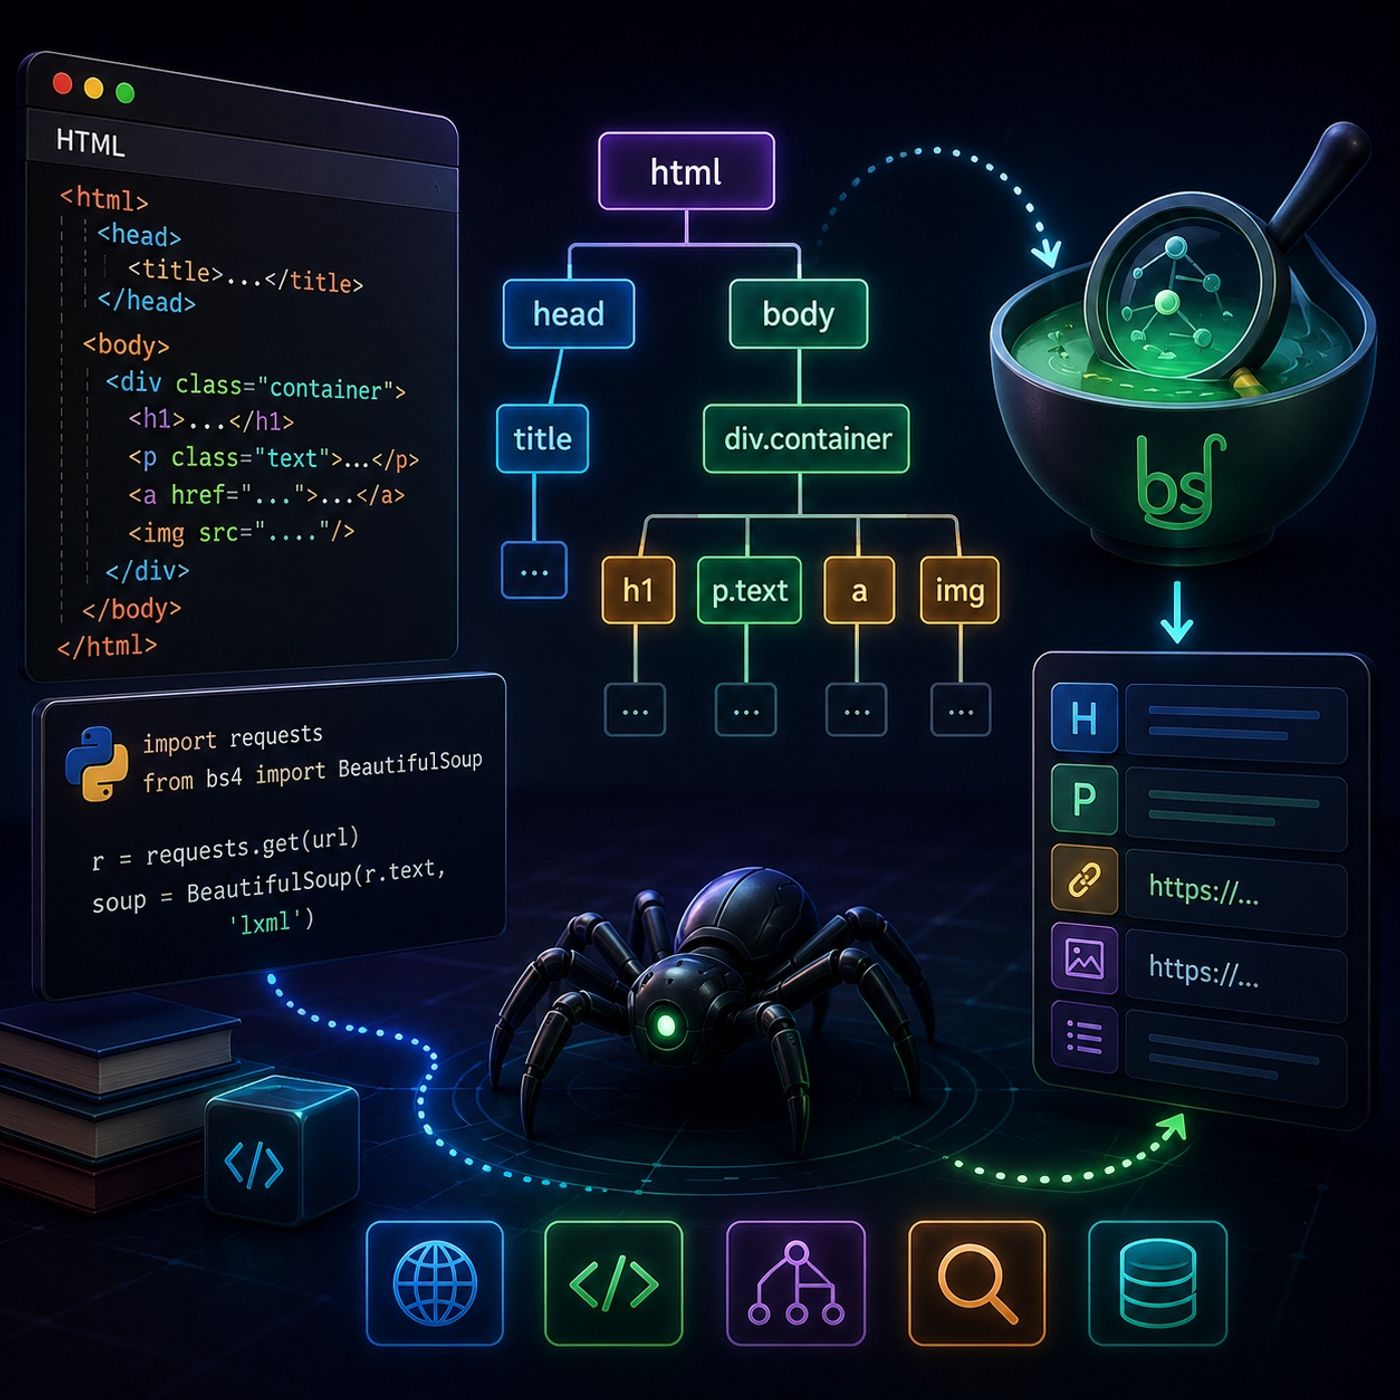
In this lesson, you’ll learn about: how HTML is structured as a tree, how to turn raw pages into navigable data using Beautiful Soup, and how to extract specific elements efficiently1. Understanding the HTML Parse Tree🔹 The Structure of a Web PageEvery web page is a hierarchical tree made of nodes:Root → Children → and Siblings → elements at the same level🔹 Key Sections → metadata (title, scripts, styles) → visible content👉 Key InsightScraping is really about navigating this tree intelligently2. Turning HTML into Data (Beautiful Soup)🔹 The Core ToolUse Beautiful SoupConverts raw HTML → structured Python objectMakes navigation simple and readable🔹 Why It’s PowerfulHandles messy HTMLSupports multiple parsersEasy to search and extract3. Choosing the Right Parser🔹 Available ParsersParserStrengthlxmlFast and efficienthtml5libHandles broken HTML🔹 When to Use EachUse lxml → performanceUse html5lib → unreliable or malformed pages👉 Pro InsightReal-world pages are often messy → parser choice matters4. From Request to Parsed Tree🔹 Workflow OverviewSend HTTP requestReceive HTMLParse with Beautiful SoupNavigate and extract🔹 Example Setupimport requests from bs4 import BeautifulSoup r = requests.get("https://example.com") soup = BeautifulSoup(r.text, "lxml") 5. Extracting Text Content🔹 Headers & Paragraphstitle = soup.h1.string paragraph = soup.p.string 👉 Use CaseBlog titlesArticle contentProduct descriptions6. Extracting Attributes (Links & Images)🔹 Accessing Attributeslink = soup.a["href"] image = soup.img["src"] 👉 What You Can ExtractURLsImage sourcesMetadata7. Working with CSS Classes🔹 Finding Elements by Classitems = soup.find_all("div", class_="product") 🔹 Important NoteClasses can be multi-valued 👉 Beautiful Soup handles this intelligently8. Navigating the Tree🔹 Moving Through Nodes.parent.children.next_sibling🔹 Examplefor child in soup.body.children: print(child) 👉 Key SkillUnderstanding relationships = better extraction9. Real Extraction Strategy🔹 Step-by-Step ThinkingInspect HTMLIdentify target elementChoose selectorExtract dataClean output10. Common Pitfalls🔹 Things to Watch Out ForMissing tagsNested complexityDynamic content (JavaScript)👉 SolutionAlways verify structure firstUse browser DevTools11. Mental ModelHTML Page = TreeBeautiful Soup = Navigator👉 You are not scraping randomlyYou are walking a structured mapFinal TakeawayMastering Beautiful Soup means mastering how the web is structured.Once you understand the tree, extraction becomes predictable, scalable, and precise—turning messy HTML into clean, usable data.You can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 10: Navigating and Extracting Web Data with Beautiful Soup
No transcript for this episode yet
Similar Episodes
No similar episodes found.