
EPISODE · Aug 6, 2026 · 22 MIN
Course 40 - Web Scraping with Python | Episode 26: Framework Overview and Core Architecture
from CyberCode Academy · host CyberCode Academy
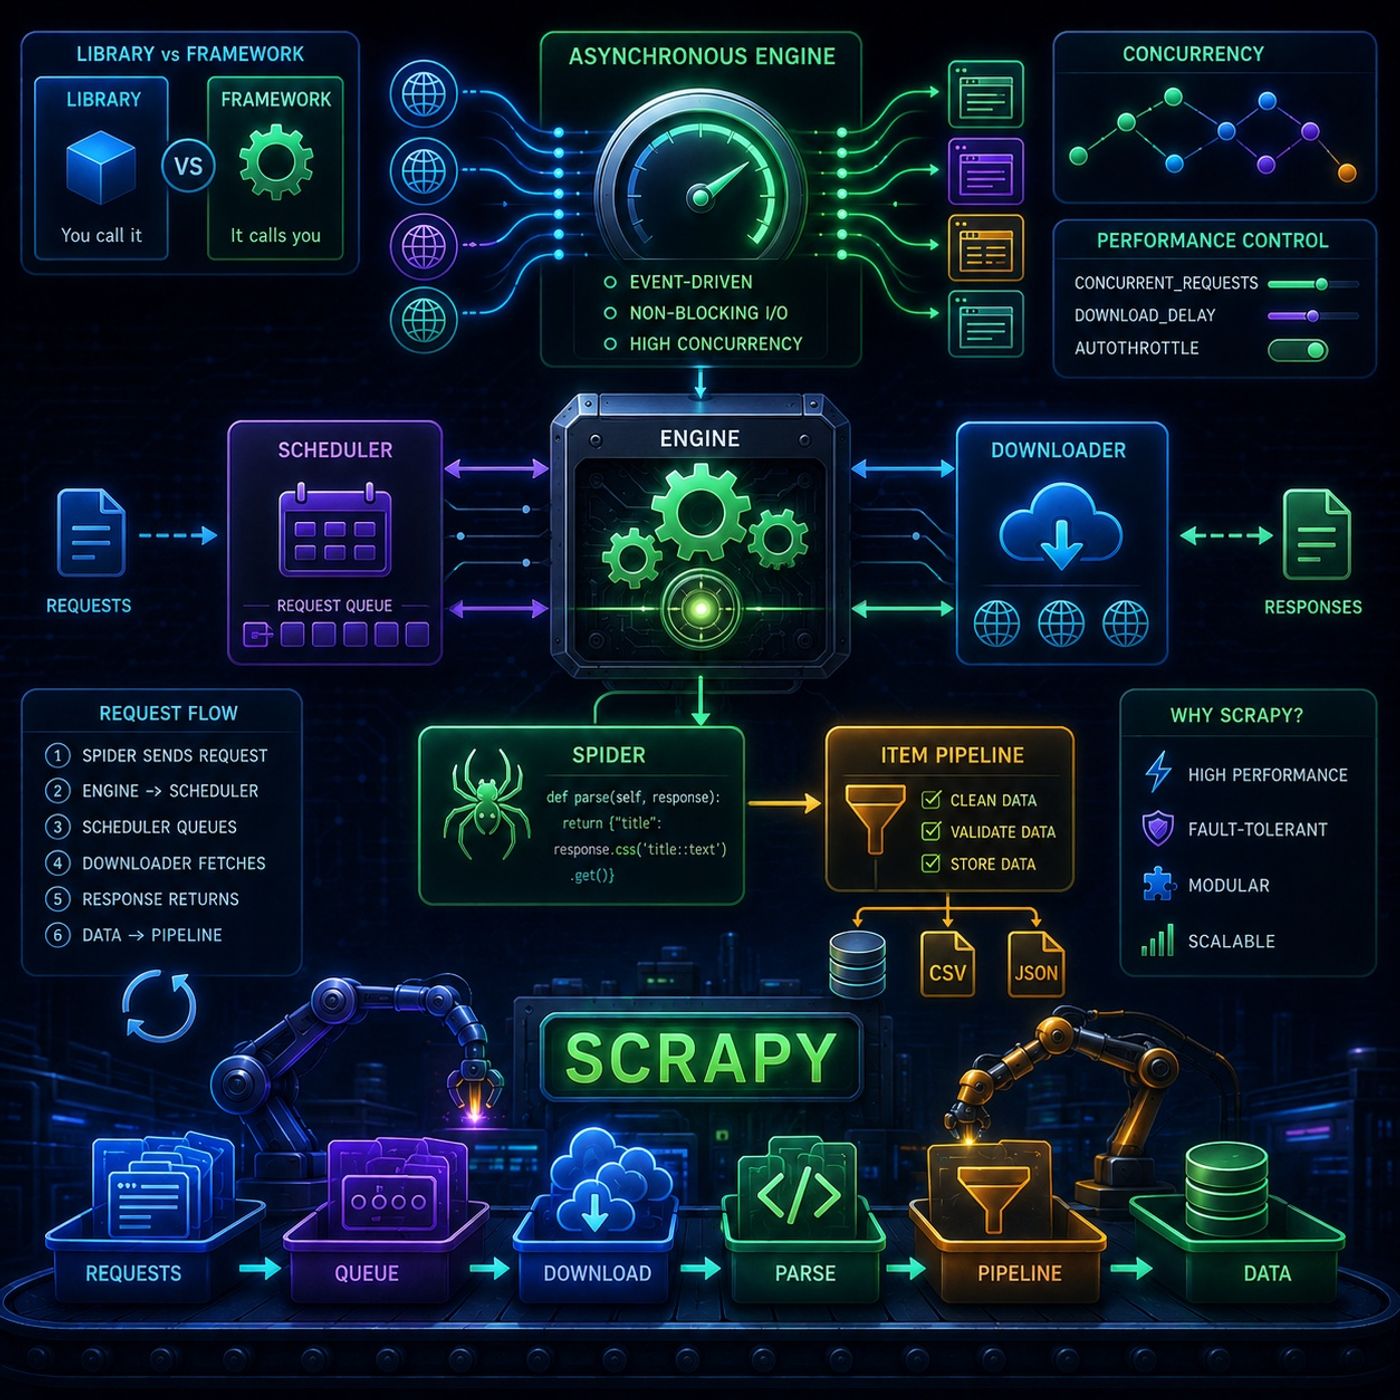
In this lesson, you’ll learn about: what makes Scrapy a framework (not just a library), how its asynchronous engine works, and how its core components cooperate to deliver fast, scalable web scraping1. Library vs Framework (Core Concept)🔹 Who Controls the Flow?🔹 Key DifferenceLibrary → you call it when neededFramework → it calls your code👉 Key InsightScrapy is a framework because it controls execution (Inversion of Control)2. Asynchronous Power (Why Scrapy is Fast)🔹 Event-Driven Architecture🔹 What Makes It PowerfulUses event-driven networkingHandles many requests simultaneouslyDoesn’t wait (non-blocking I/O)👉 Key InsightScrapy doesn’t scrape pages one-by-one—it handles many at once3. Scrapy Architecture (Big Picture)🔹 How Components Interact4. Core Components Explained🔹 1. EngineCentral controllerManages request/response flow🔹 2. SpidersYour custom logicExtract data from responsesdef parse(self, response): return {"title": response.css("title::text").get()} 🔹 3. SchedulerQueues requestsDecides what to crawl next🔹 4. DownloaderSends HTTP requestsRetrieves web pages🔹 5. Item PipelineCleans dataValidates dataSaves data (DB, CSV, etc.)👉 Key InsightEach component has one responsibility → modular & scalable5. Request Flow (Step-by-Step)Spider sends requestEngine forwards to SchedulerScheduler queues itDownloader fetches pageResponse returns to SpiderData sent to Pipeline👉 This loop continues asynchronously for thousands of requests6. Fine-Grained Control🔹 Performance Tuning🔹 Key ControlsLimit concurrent requestsControl request delaysEnable auto-throttling🔹 Example SettingsCONCURRENT_REQUESTS = 16 DOWNLOAD_DELAY = 1 AUTOTHROTTLE_ENABLED = True 👉 Key InsightSpeed without control = getting blocked7. Why Scrapy is Production-Ready⚡ High performance (async)🔄 Fault-tolerant (handles failures)🧱 Modular architecture🎯 Precise data pipelines8. Mental ModelThink of Scrapy as a factory:🏭 Engine → manager🕷 Spider → worker extracting data📦 Scheduler → task queue🌐 Downloader → fetcher🧹 Pipeline → cleaner & packagerFinal TakeawayScrapy isn’t just a tool—it’s a complete scraping system.You gain:Massive speed via asynchronous processingClean architecture for scalingFull control over performance and behavior👉 That’s why Scrapy is used for large-scale, professional-grade data extractionYou can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 26: Framework Overview and Core Architecture
No transcript for this episode yet
Similar Episodes
Jan 27, 2024 ·12m
Jan 19, 2024 ·9m
Jan 18, 2024 ·5m
Jan 14, 2024 ·6m
Jan 5, 2024 ·7m