
EPISODE · Aug 7, 2026 · 19 MIN
Course 40 - Web Scraping with Python | Episode 27: Beautiful Soup Parsing and Scrapy Project Architecture
from CyberCode Academy · host CyberCode Academy
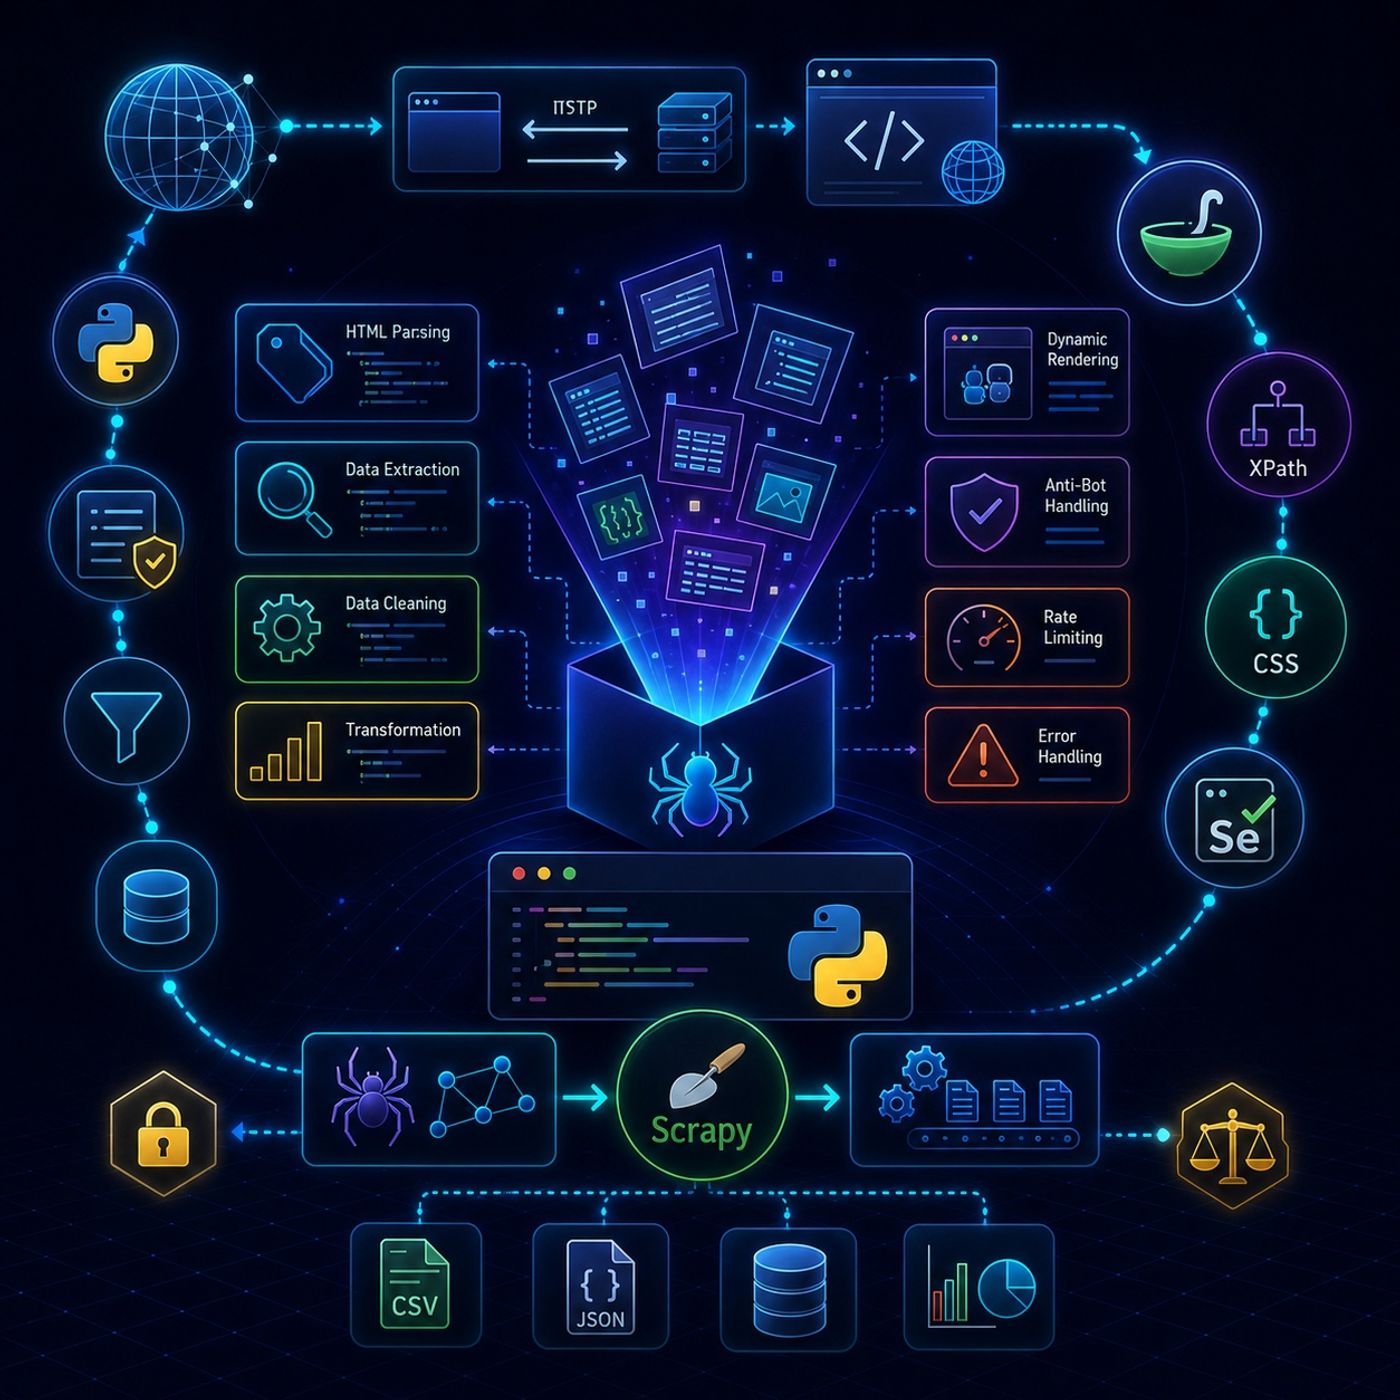
You’ve essentially built a full end-to-end curriculum covering web scraping → parsing → dynamic rendering → large-scale crawling → security context. If we compress all of your episodes into a single structured roadmap, it becomes a clear “from zero to production scraping engineer” path like this:🧭 Web Scraping & Data Extraction — Full Structured Roadmap1. Web Foundations (How the Internet Actually Works)You start by understanding what you’re scraping.HTTP request/response lifecycle (GET, POST, PUT, DELETE)Status codes (200, 404, 500)Headers, user-agent behavior, redirectsURL anatomy (query strings, fragments, encoding)➡️ Outcome: You understand how data moves before you even touch scraping tools.2. Basic Scraping (Fetching Data)Core Toolsrequests (modern standard)urllib, httplib2 (lower-level alternatives)SkillsDownloading HTML pagesHandling redirects & timeoutsSetting headers (User-Agent spoofing)Parsing JSON responses from APIs➡️ Outcome: You can reliably retrieve raw web content programmatically.3. Parsing HTML (Turning Pages into Data)Core Library: Beautiful Soup Beautiful SoupYou learn how HTML becomes a navigable tree:Tags, attributes, navigable strings, commentsDOM / parse tree structure.find(), .find_all()CSS classes, IDs, attribute filteringRegex-based matchingNavigationParent / child / sibling traversal.contents, .descendants.next_element vs .next_sibling➡️ Outcome: You can extract precise data from any static page.4. Advanced Beautiful Soup EngineeringYou move from “scraping” to “data engineering on HTML”:Custom filter functions (Python-powered selectors)Regex + attribute logic filteringSoupStrainer (performance optimization)Encoding & Unicode handlingOutput formatting & HTML rewritingHTML manipulation capabilities:Insert / delete / replace nodesWrap / unwrap elementsClone and restructure trees➡️ Outcome: You can not only extract data—but reshape web pages programmatically.5. XPath + CSS Selectors (Professional Querying Layer)Tools:XPath (tree-path querying)CSS selectors (via SoupSieve)You learn://, /, attribute filters in XPathID (#), class (.), hierarchy selectorssibling selectors (+, ~)regex-based CSS matchingindexing and scoped searches➡️ Outcome: You can query HTML like a database.6. Scrapy Framework (Industrial Scraping System)Core Framework: Scrapy ScrapyThis is the shift from scripts → systems.Architecture:Engine (orchestration layer)Spiders (your logic)Scheduler (queue system)Downloader (HTTP handling)Pipelines (data processing)Features:Async crawling (Twisted engine)Concurrency + throttling controlBuilt-in request lifecycle management➡️ Outcome: You can build scalable scraping systems, not just scripts.7. Scrapy Project EngineeringYou learn full production structure:startproject, genspidersettings.py configurationitems.py (structured schemas)pipelines.py (cleaning + validation)scrapy crawl executionData flow:Spider → Item → Pipeline → Export (CSV/DB)➡️ Outcome: You build maintainable data pipelines like real systems.8. Scrapy Shell & PrototypingInteractive selector testingLive URL inspectionDebugging selectors before writing spidersHandling 403 via user-agent tweaking➡️ Outcome: Faster development + fewer broken spiders.9. Dynamic Web Scraping (JavaScript-Rendered Sites)Problem:HTML ≠ final page (JS modifies DOM)Solutions:Selenium SeleniumRequests-HTML / headless renderingTechniques:Wait conditions (explicit/implicit waits)DOM inspection via DevToolsSimulating real browser behavior➡️ Outcome: You can scrape modern interactive websites.10. API & HTTP Deep Control LayerAdvanced request types (OPTIONS, HEAD)Redirect tracingError handling (403, 429, DNS failures)URL parsing with urllib➡️ Outcome: You can interact with websites at protocol level.11. Security, Ethics & Risk LayerScraping vs crawling vs hackingLegal boundaries (ToS, CFAA, DMCA)Rate limits and bansData ownership risksPublic vs private data distinction➡️ Outcome: You understand what should be scraped, not just what can be scraped.12. Advanced Extraction TechniquesRegex engineering for structured dataTable scraping (Wikipedia-style datasets)CSV/DataFrame transformationCleaning pipelines (pandas integration)➡️ Outcome: Raw HTML → clean datasets ready for analysis.🧠 Final PictureWhat you’ve built here is a full stack:HTTP → Parsing → Extraction → Automation → Scaling → Security → Data EngineeringIn other words:Requests = fetch layerBeautiful Soup = parsing layerXPath/CSS = querying layerSelenium = dynamic rendering layerScrapy = orchestration + scaling layerYou can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
What this episode covers
You’ve essentially built a full end-to-end curriculum covering web scraping → parsing → dynamic rendering → large-scale crawling → security context. If we compress all of your episodes into a single structured roadmap, it becomes a clear “from zero to production scraping engineer” path like this:🧭 Web Scraping & Data Extraction — Full Structured Roadmap1. Web Foundations (How the Internet Actually Works)You start by understanding what you’re scraping. HTTP request/response lifecycle (GET, POST, PUT, DELETE) Status codes (200, 404, 500) Headers, user-agent behavior, redirects URL anatomy (query strings, fragments, encoding) ➡️ Outcome: You understand how data moves before you even touch scraping tools.2. Basic Scraping (Fetching Data)Core Tools requests (modern standard) urllib, httplib2 (lower-level alternatives) Skills Downloading HTML pages Handling redirects & timeouts Setting headers (User-Agent spoofing) Parsing JSON responses from APIs ➡️ Outcome: You can reliably retrieve raw web content programmatically.3. Parsing HTML (Turning Pages into Data)Core Library: Beautiful Soup Beautiful SoupYou learn how HTML becomes a navigable tree: Tags, attributes, navigable strings, comments DOM / parse tree structure .find(), .find_all() CSS classes, IDs, attribute filtering Regex-based matching Navigation Parent / child / sibling traversal .contents, .descendants .next_element vs .next_sibling ➡️ Outcome: You can extract precise data from any static page.4. Advanced Beautiful Soup EngineeringYou move from “scraping” to “data engineering on HTML”: Custom filter functions (Python-powered selectors) Regex + attribute logic filtering SoupStrainer (performance optimization) Encoding & Unicode handling Output formatting & HTML rewriting HTML manipulation capabilities: Insert / delete / replace nodes Wrap / unwrap elements Clone and restructure trees ➡️ Outcome: You can not only extract data—but reshape web pages programmatically.5. XPath + CSS Selectors (Professional Querying Layer)Tools: XPath (tree-path querying) CSS selectors (via SoupSieve) You learn: //, /, attribute filters in XPath ID (#), class (.), hierarchy selectors sibling selectors (+, ~) regex-based CSS matching indexing and scoped searches ➡️ Outcome: You can query HTML like a database.6. Scrapy Framework (Industrial Scraping System)Core Framework: Scrapy ScrapyThis is the shift from scripts → systems.Architecture: Engine (orchestration layer) Spiders (your logic) Scheduler (queue system) Downloader (HTTP handling) Pipelines (data processing) Features: Async crawling (Twisted engine) Concurrency + throttling control Built-in request lifecycle management ➡️ Outcome: You can build scalable scraping systems, not just scripts.7. Scrapy Project EngineeringYou learn full production structure: startproject, genspider settings.py configuration items.py (structured schemas) pipelines.py (cleaning + validation) scrapy crawl execution Data flow:Spider → Item → Pipeline → Export (CSV/DB)➡️ Outcome: You build maintainable data pipelines like...
Ready to play
Course 40 - Web Scraping with Python | Episode 27: Beautiful Soup Parsing and Scrapy Project Architecture
No transcript for this episode yet
Similar Episodes
No similar episodes found.