
EPISODE · Aug 8, 2026 · 13 MIN
Course 40 - Web Scraping with Python | Episode 28: Base and Generic Crawling Classes
from CyberCode Academy · host CyberCode Academy
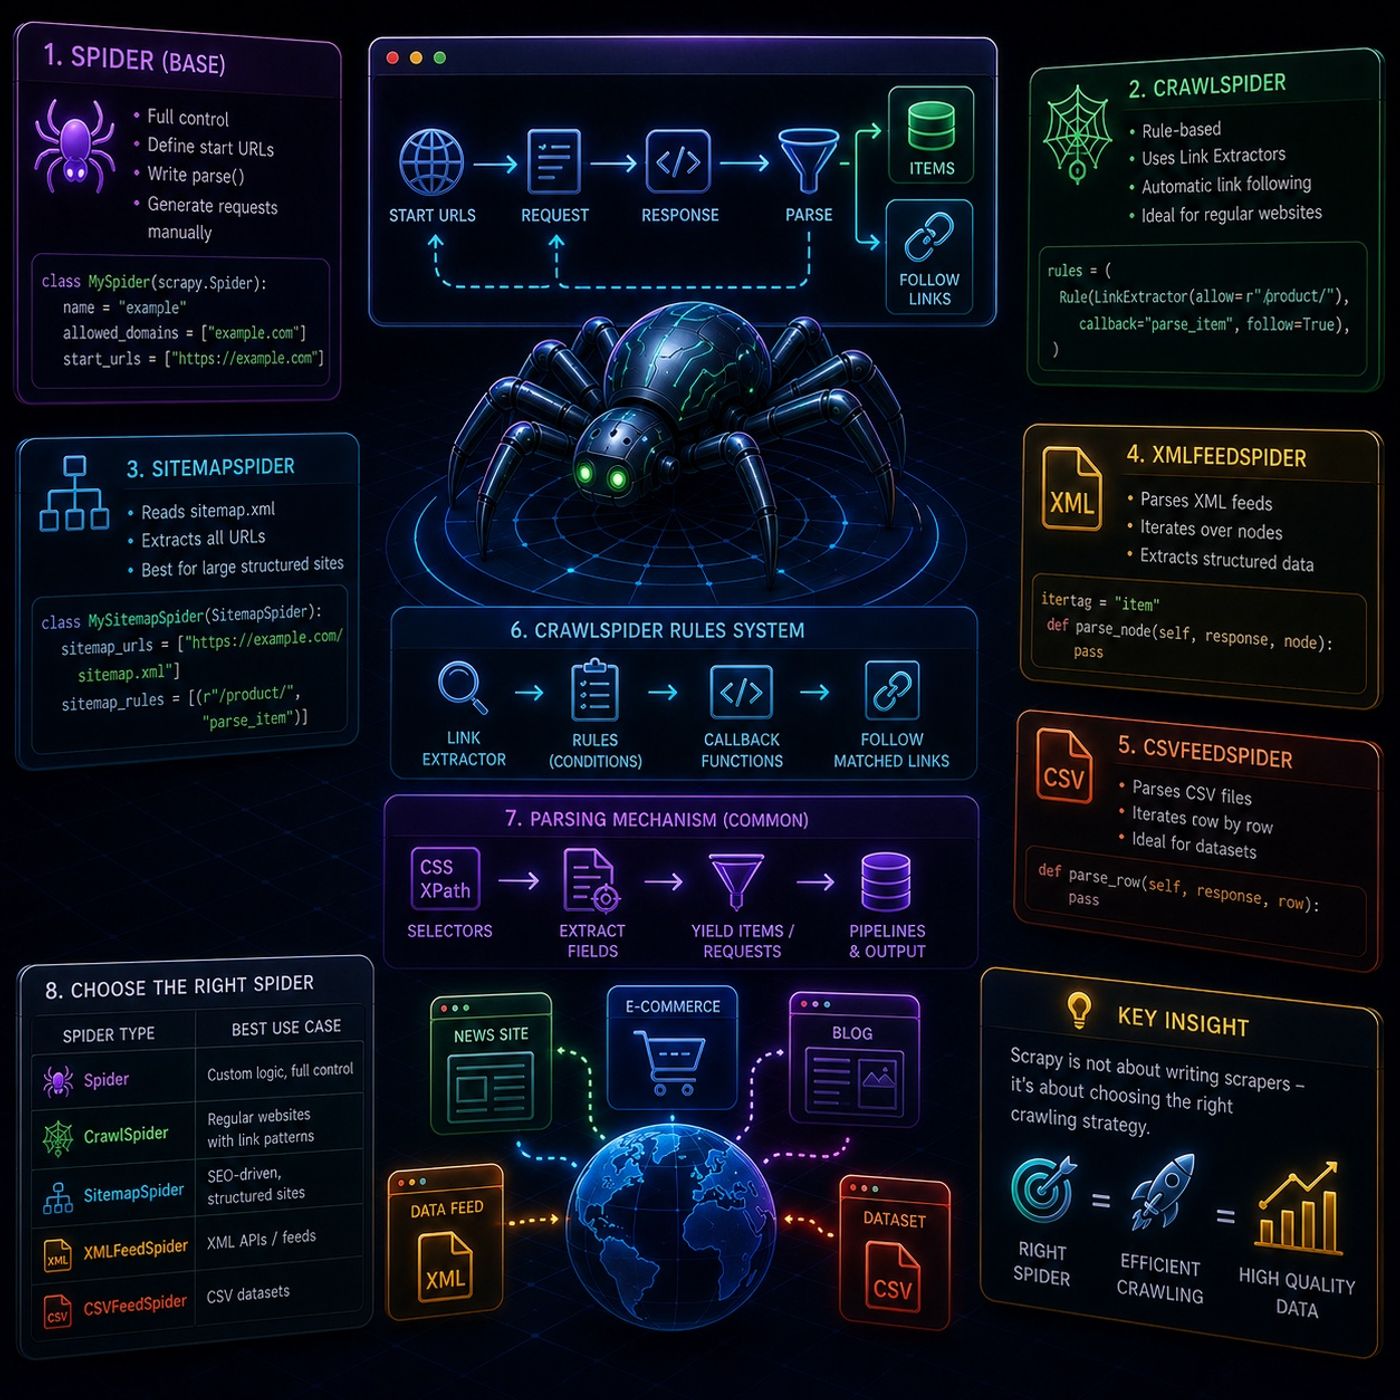
This episode is essentially about how Scrapy structures crawling logic through different spider types, and when to use each one depending on the scale and structure of the target site.Here’s the clean, structured breakdown:🕷️ Scrapy Spiders — Architecture & Types1. What a Spider Actually IsA Scrapy spider is a Python class that defines:Where to crawl (scoping)How to crawl (link following rules)What to extract (parsing logic)So every spider always answers three questions:Where do I start? → Where do I go next? → What data do I take?2. Base Class: scrapy.Spider ScrapyThis is the simplest and most flexible spider.Core structure:name → identifier for the spiderallowed_domains → restricts crawling scopestart_urls → initial entry pointsFlow:Scrapy sends requests automatically via start_requestsResponses are passed to parse()You manually extract data + generate next requestsKey idea:Full manual control over crawling logic3. CrawlSpider (Rule-Based Automation)CrawlSpiderThis is the most commonly used advanced spider.Instead of manually controlling navigation, you define rules.Core concept:Uses Link ExtractorsUses RulesAutomatically follows links that match conditionsExample behavior:“Follow all product links”“Ignore login pages”“Only crawl category pages”Why it matters:It automates link discovery instead of writing it manually.4. SitemapSpider (Structured Crawling)SitemapSpiderDesigned for websites that expose:/sitemap.xmlBehavior:Reads sitemap URLsExtracts all listed links automaticallyCrawls them without link discovery logicBest for:Large structured websitesSEO-friendly sitesE-commerce catalogs5. XMLFeedSpider & CSVFeedSpiderThese are specialized for data feeds, not HTML pages.XMLFeedSpider:Iterates over XML nodesExtracts structured fieldsCSVFeedSpider:Iterates row-by-row through CSV filesUse case:When the “website” is already a dataset feed6. CrawlSpider Rules SystemThis is the most important upgrade over base spiders.Components:Link Extractor → finds links on pagesRules → define which links to followCallback functions → process matched pagesExample logic:Follow category pagesExtract product pages onlyIgnore pagination or ads7. Parsing Mechanism (Shared Concept)Across all spiders:Parsing step always includes:Extracting structured fields (title, price, etc.)Using XPath or CSS selectorsYielding items or new requests8. Spider Selection StrategyHere’s how you choose:Spider TypeBest Use CaseSpiderCustom logic, full controlCrawlSpiderRegular websites with link patternsSitemapSpiderSEO-driven structured sitesXMLFeedSpiderXML APIs / feedsCSVFeedSpiderCSV datasets🧠 Key InsightThe real concept behind this episode is:Scrapy is not about writing scrapers — it’s about choosing the right crawling strategy.You can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 28: Base and Generic Crawling Classes
No transcript for this episode yet
Similar Episodes
No similar episodes found.