
EPISODE · Aug 9, 2026 · 19 MIN
Course 40 - Web Scraping with Python | Episode 29: From Feed and Sitemap Spiders to CrawlSpider Demos
from CyberCode Academy · host CyberCode Academy
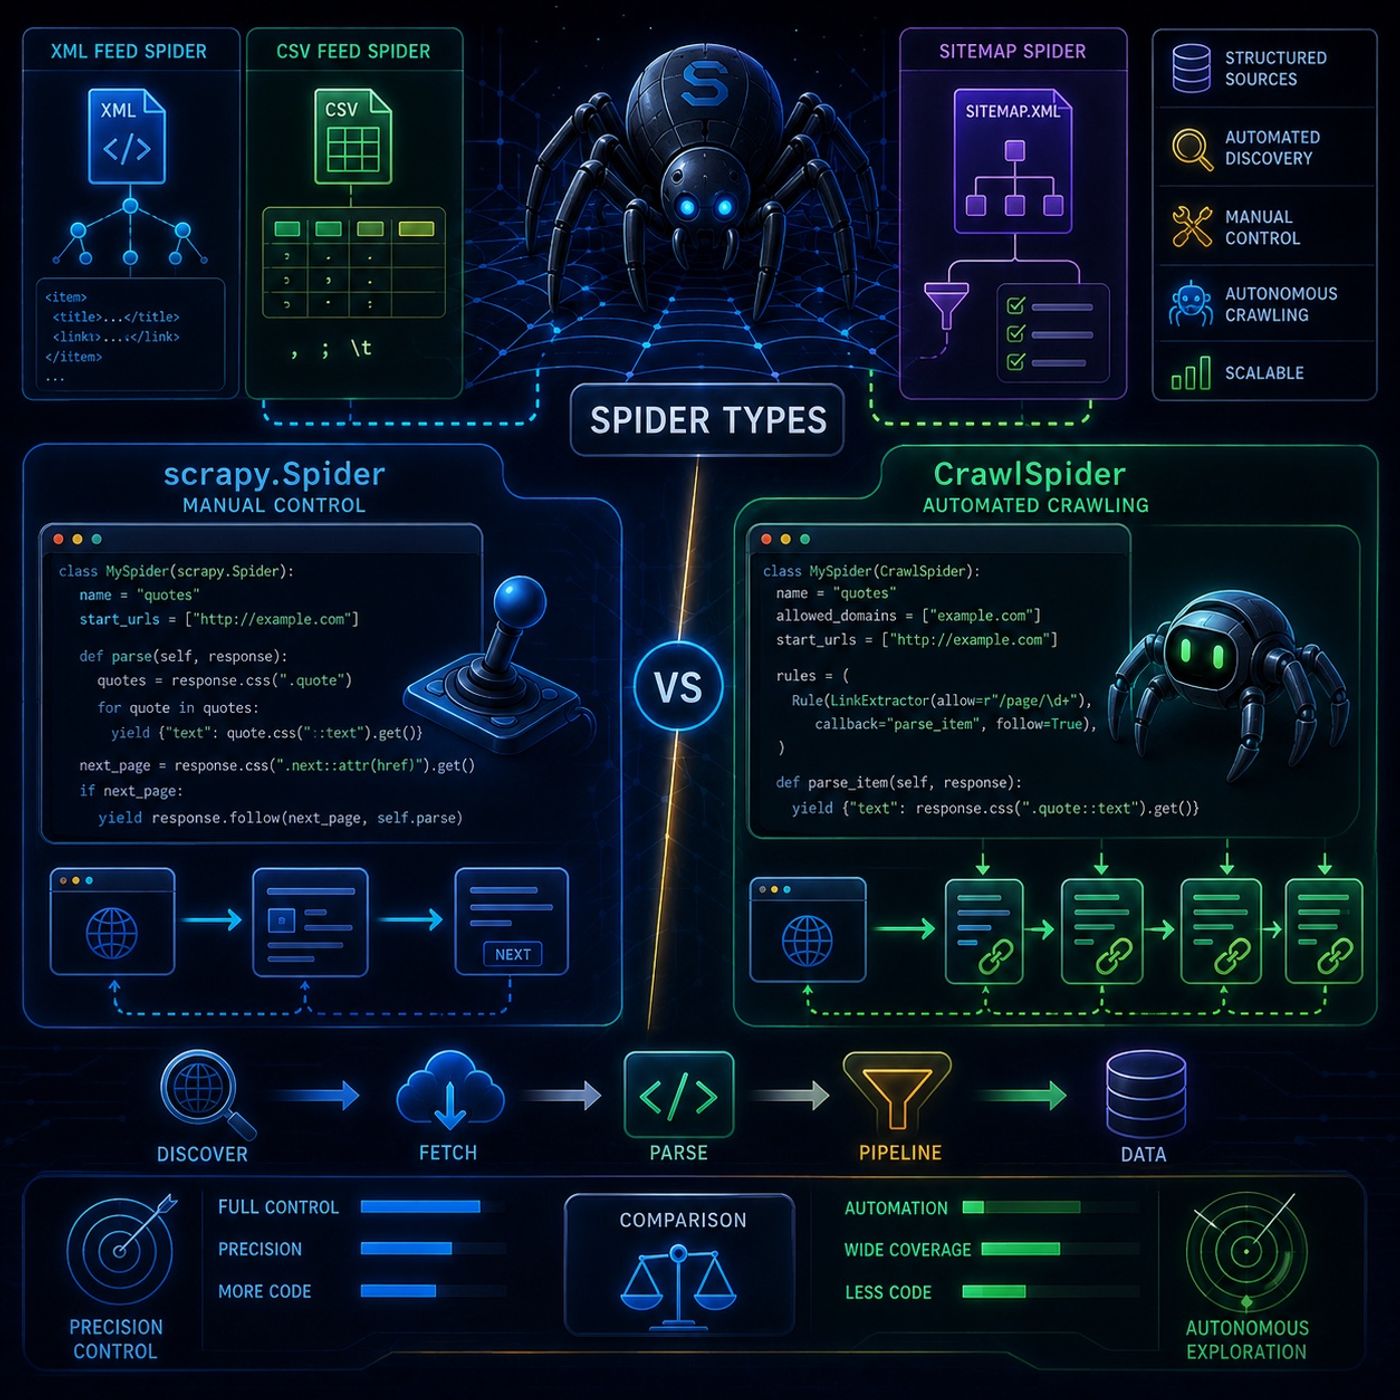
This episode is really about choosing between manual control and automated crawling logic inside Scrapy, and understanding how specialized spider classes change your level of control.Here’s the structured breakdown:🕷️ Scrapy Spider Types — Practical Comparison & Feed Spiders1. Feed-Based Spiders (Structured Data Sources)These spiders are not designed for HTML pages — they target pre-structured data formats.📄 XMLFeedSpider ScrapyPurpose:Extract structured data from XML feeds.Key concept:Works by iterating through XML nodesUses itertag to define which tag to extractUses iterator mode (itnodes) for performanceBehavior:Instead of parsing a full page, it streams through XML elements one by one.📊 CSVFeedSpider ScrapyPurpose:Scrape structured CSV files directly.Key features:Custom delimiters (, ; \t)Configurable quote charactersHeader mapping → fields become item keysBehavior:Each row becomes a structured item automatically.2. SitemapSpider (Automated URL Discovery)SitemapSpider ScrapyPurpose:Crawl websites using their sitemap instead of link discovery.How it works:Reads sitemap.xmlExtracts all URLs listedFilters URLs using:regex rulescallback mapping rulesAdvantage:No need to manually discover or follow links.⚔️ 3. scrapy.Spider vs CrawlSpider (Core Comparison)🧱 A. scrapy.Spider (Manual Control)Behavior:You define:start_urlsparse() logicpagination logic manuallyWhat you control:Every requestEvery page transitionEvery extraction stepExample characteristics:CSS selectors used explicitlyMust manually follow “next page” linksFull control over flowKey idea:You are writing the crawling engine logic yourself.🤖 B. CrawlSpider (Automated Crawling)Behavior:Uses Rules + LinkExtractorsAutomatically follows linksWhat it does for you:Finds links automaticallyFilters them using regex or CSS rulesCalls callbacks automaticallyScope:Much broader by defaultCan crawl entire domains unless restrictedKey idea:You define rules — Scrapy handles navigation.🔄 4. Real Demo Insight (Quotes Scraping Example)scrapy.Spider behavior:Manually extract dataManually handle paginationPages may finish in non-sequential order (async execution)CrawlSpider behavior:Automatically follows linksLess manual parsing logicMore scalable for large websites🧠 Core Concept of the EpisodeThe real takeaway is:scrapy.Spider = precision controlCrawlSpider = autonomous exploration📌 Mental ModelTypeStrengthWeaknessscrapy.SpiderFull controlMore codeCrawlSpiderAutomationLess fine-grained controlSitemapSpiderFast discoveryDepends on sitemapXML/CSV SpidersStructured feedsLimited flexibilityYou can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 29: From Feed and Sitemap Spiders to CrawlSpider Demos
No transcript for this episode yet
Similar Episodes
No similar episodes found.