
EPISODE · Jul 13, 2026 · 22 MIN
Course 40 - Web Scraping with Python | Episode 3: Mastering CSS, XPath, and Developer Tools
from CyberCode Academy · host CyberCode Academy
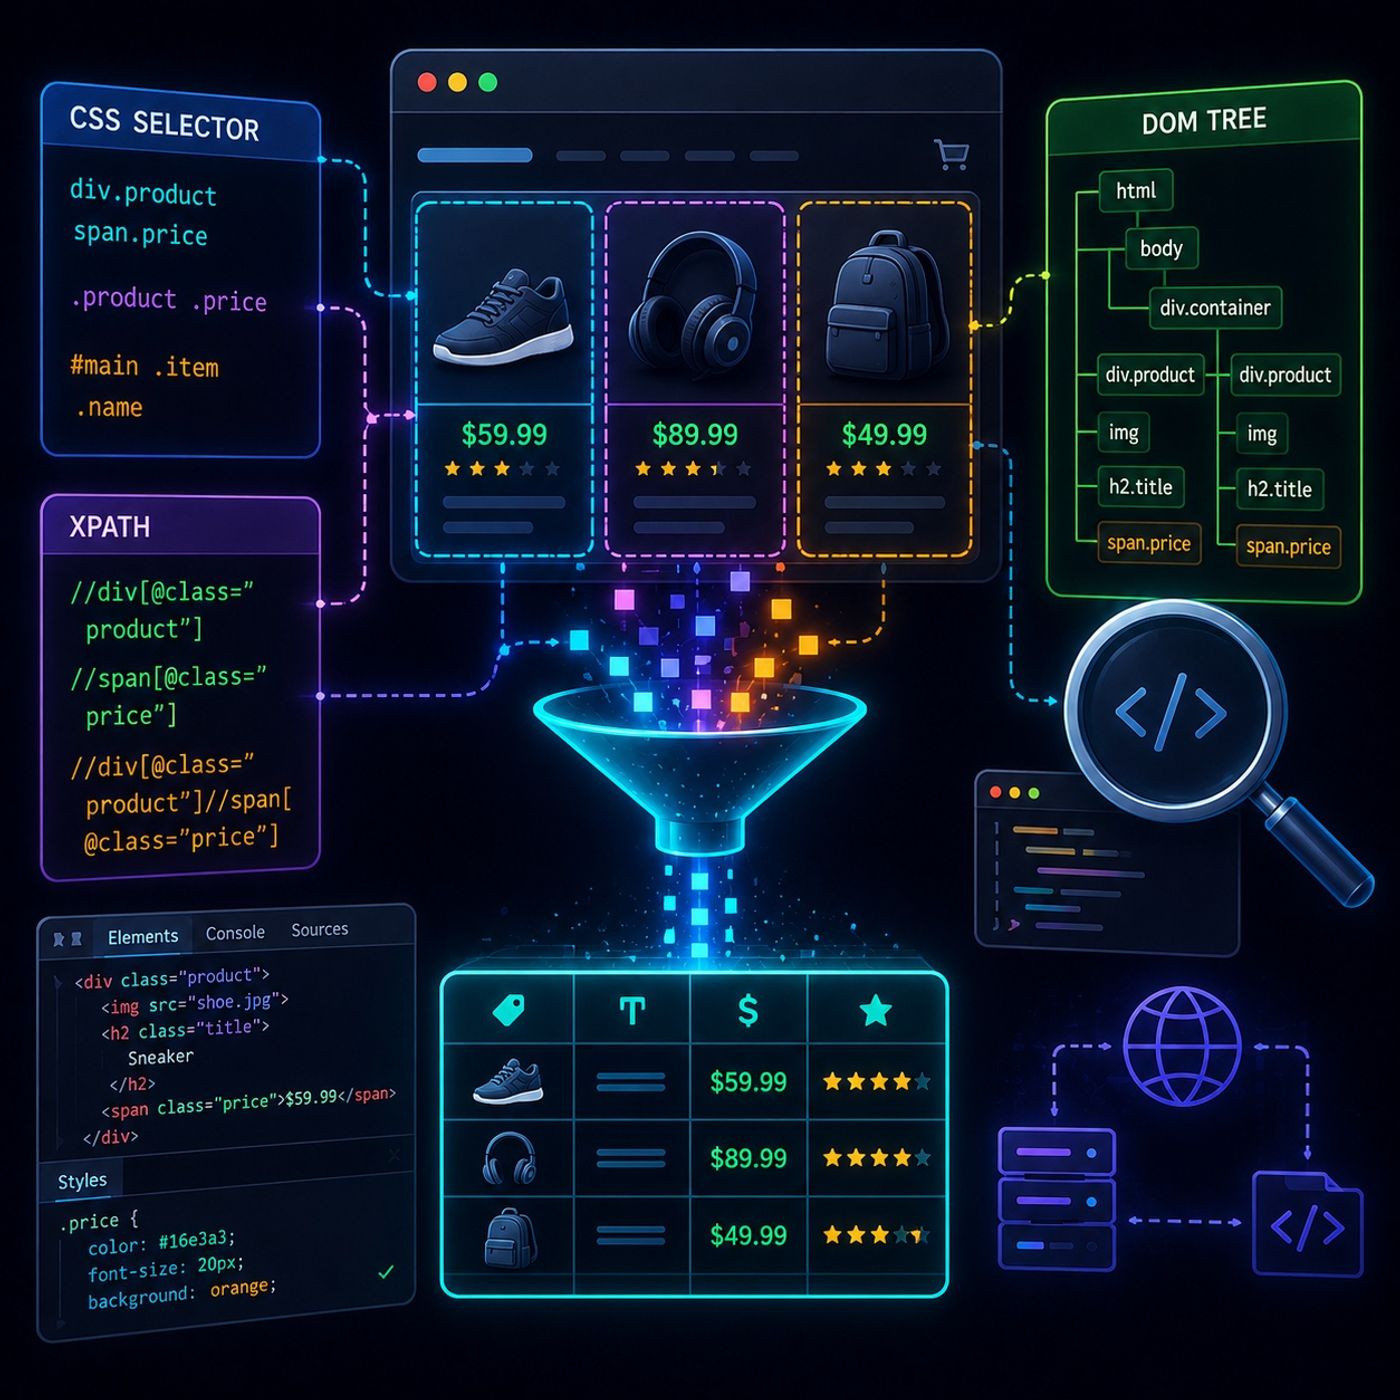
In this lesson, you’ll learn about: how to extract precise data from web pages using selectors, how CSS and XPath differ, and how to apply them effectively with real browser tools1. What is Data Extraction (“SQL for the Web”)🔹 Core IdeaData extraction is about selecting exactly what you want from a web page—just like SQL queries select rows from a database.Using tools like Beautiful Soup, you can:Target specific elementsExtract clean textAutomate structured data collection👉 Key InsightThe power is not in scraping everything—it’s in extracting only what matters2. Understanding HTML Structure🔹 The DOM Tree ConceptWeb pages are structured like a treeElements have:ParentsChildrenSiblings👉 Example: Title $10 3. CSS Selectors (Your First Tool)🔹 BasicsTag → divClass → .priceID → #main🔹 Combining Selectorssoup.select("div.product span.price") 👉 This means:Find span.priceInside div.product🔹 Why CSS is PowerfulSimple and readableFast to writeWorks directly in browsers4. XPath (Advanced Targeting)🔹 What is XPath?Use XPathTreats HTML as a navigable treeMore flexible than CSS🔹 Key Syntax//div → find anywhere/div → direct child[@class="price"] → filter by attribute🔹 Example//div[@class="product"]//span[@class="price"] 🔹 When XPath WinsComplex structuresConditional logicTraversing up/down the tree5. CSS vs XPath (Quick Comparison)FeatureCSSXPathEase of useEasyMediumPowerModerateHighReadabilityHighLowerComplex queriesLimitedStrong👉 Rule of ThumbStart with CSSSwitch to XPath when needed6. Using Chrome Developer Tools🔹 Inspecting ElementsSteps:Right-click → InspectView HTML structureTest selectors live🔹 Pro Techniques1. Visual DebuggingTemporarily change styles:background: orange; 👉 Confirms your selector targets the correct elements2. Copy Selectors AutomaticallyRight-click element → Copy →CSS SelectorXPath3. Test in Consoledocument.querySelectorAll("div.product") 7. Real-World Extraction Scenarios🔹 Example: Wikipedia TablesIdentify Loop through rowsExtract cells🔹 Example: Complex Graphs (SVG + JS)Challenges:Data not in visible HTMLRendered via JavaScriptStored inside SVG elements👉 Solution:Inspect deeplyCheck network requestsReverse-engineer data source8. Best Practices for Clean Extraction🔹 Stay OrganizedWork step-by-stepTest selectors incrementally🔹 Write Robust SelectorsAvoid:div > div > div > span Prefer:.product .price 🔹 Expect ChangeWebsites update frequentlyBuild flexible logic9. Mental ModelHTML → Selector → Extract → Clean → Structure👉 Final TakeawayMastering data extraction is less about tools and more about thinking structurally—once you understand how the web is built, you can query it with precision just like a database.You can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 3: Mastering CSS, XPath, and Developer Tools
No transcript for this episode yet
Similar Episodes
No similar episodes found.