
EPISODE · Aug 10, 2026 · 20 MIN
Course 40 - Web Scraping with Python | Episode 30: Controlling URL Paths and Processing Scraped Data
from CyberCode Academy · host CyberCode Academy
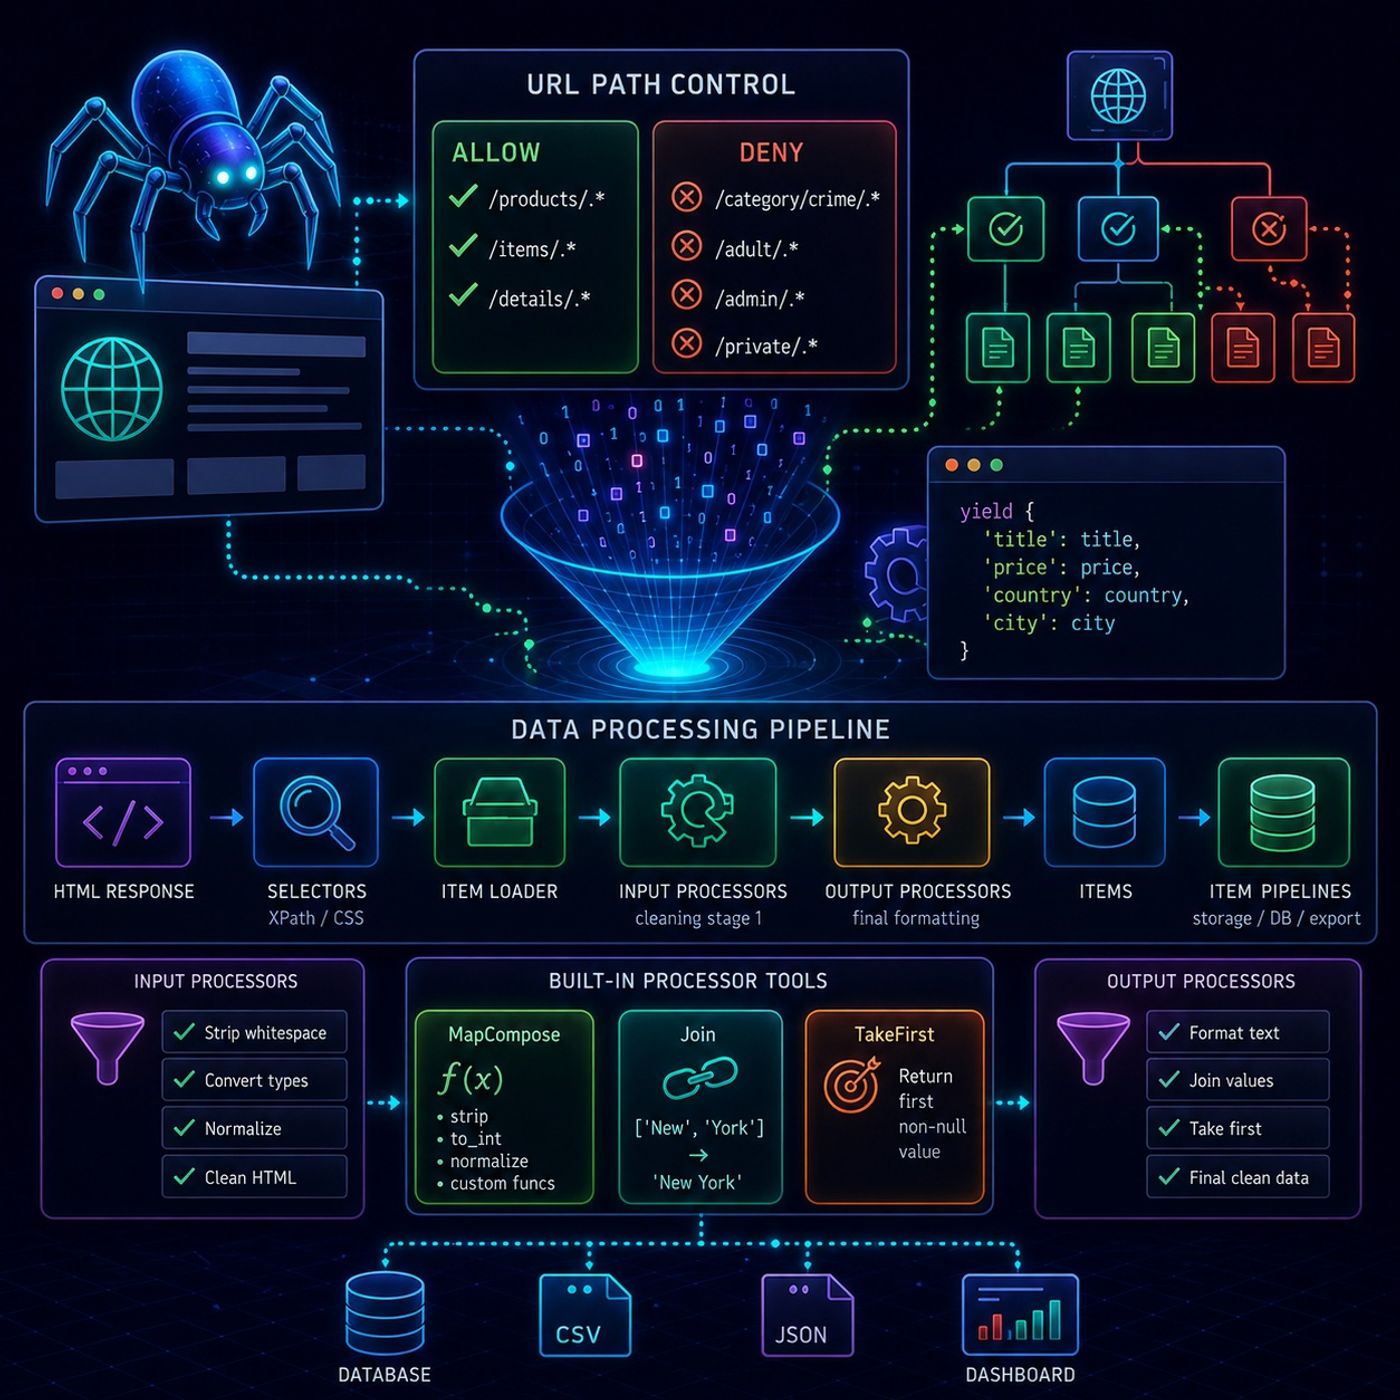
This episode is really about controlling Scrapy’s crawl scope and shaping data as it moves through the pipeline, so you’re not just collecting data—you’re actively engineering what gets collected and how it looks.🕷️ Scrapy Crawl Control & Data Processing Pipeline1. 🎯 URL Path Control (Allow / Deny Rules)In Scrapy, crawl behavior is tightly controlled using rule-based filtering, often inside spiders like CrawlSpider.🔹 Allow rulesDefine what URLs the spider is allowed to followTypically based on regex patternsUsed to target specific sections of a site (e.g., product pages)🔹 Deny rulesExplicitly block unwanted pathsUseful for excluding:irrelevant categoriesadmin pagesunwanted content typesExample use cases:Allow: /products/.*Deny: /category/crime/.*, /adult/.*Key idea:You are shaping the crawler’s “attention span” using URL patterns.⚙️ 2. Data Processing Pipeline (Item Loaders)Once Scrapy extracts raw HTML data, it passes through a structured transformation system.This is where Item Loaders + Processors come in.🔄 Input vs Output Processors📥 Input ProcessorsRun immediately after extractionClean or normalize raw scraped valuesExample: stripping whitespace, converting formats📤 Output ProcessorsRun after all values are collectedProduce final cleaned field value🧠 3. Built-in Processor ToolsScrapy provides reusable functions to transform scraped data efficiently:🔹 MapComposeApplies functions to every item in a list.Example use:strip spacesconvert strings to integersnormalize URLs👉 Think of it as:“run this function on every extracted piece of data”🔹 JoinCombines multiple values into a single string.Example:["New", "York"] → "New York" Used when:HTML splits text into multiple nodesYou want a single clean field🔹 TakeFirstReturns:the first non-null value from a listUseful because:Scrapy often returns multiple matchesYou usually only want one final value🔗 4. Full Data Flow (Important Concept)This is the critical architecture idea in the episode:HTML Response ↓ Selectors (XPath / CSS) ↓ Item Loader ↓ Input Processors (cleaning stage 1) ↓ Output Processors (final formatting) ↓ Items ↓ Item Pipelines (storage / DB / export) 🧠 Core Insight of the EpisodeThe key idea is:Scrapy is not just scraping data — it is a data transformation pipeline systemYou don’t just extract data…You control how messy web data becomes structured business intelligence.📌 Mental ModelComponentPurposeAllow / Deny rulesControl crawl scopeInput ProcessorsClean raw extractionOutput ProcessorsFinal formattingMapComposeTransform listsJoinMerge textTakeFirstReduce noiseYou can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 30: Controlling URL Paths and Processing Scraped Data
No transcript for this episode yet
Similar Episodes
No similar episodes found.