
EPISODE · Aug 11, 2026 · 23 MIN
Course 40 - Web Scraping with Python | Episode 31: From Item Loaders to Pipelines
from CyberCode Academy · host CyberCode Academy
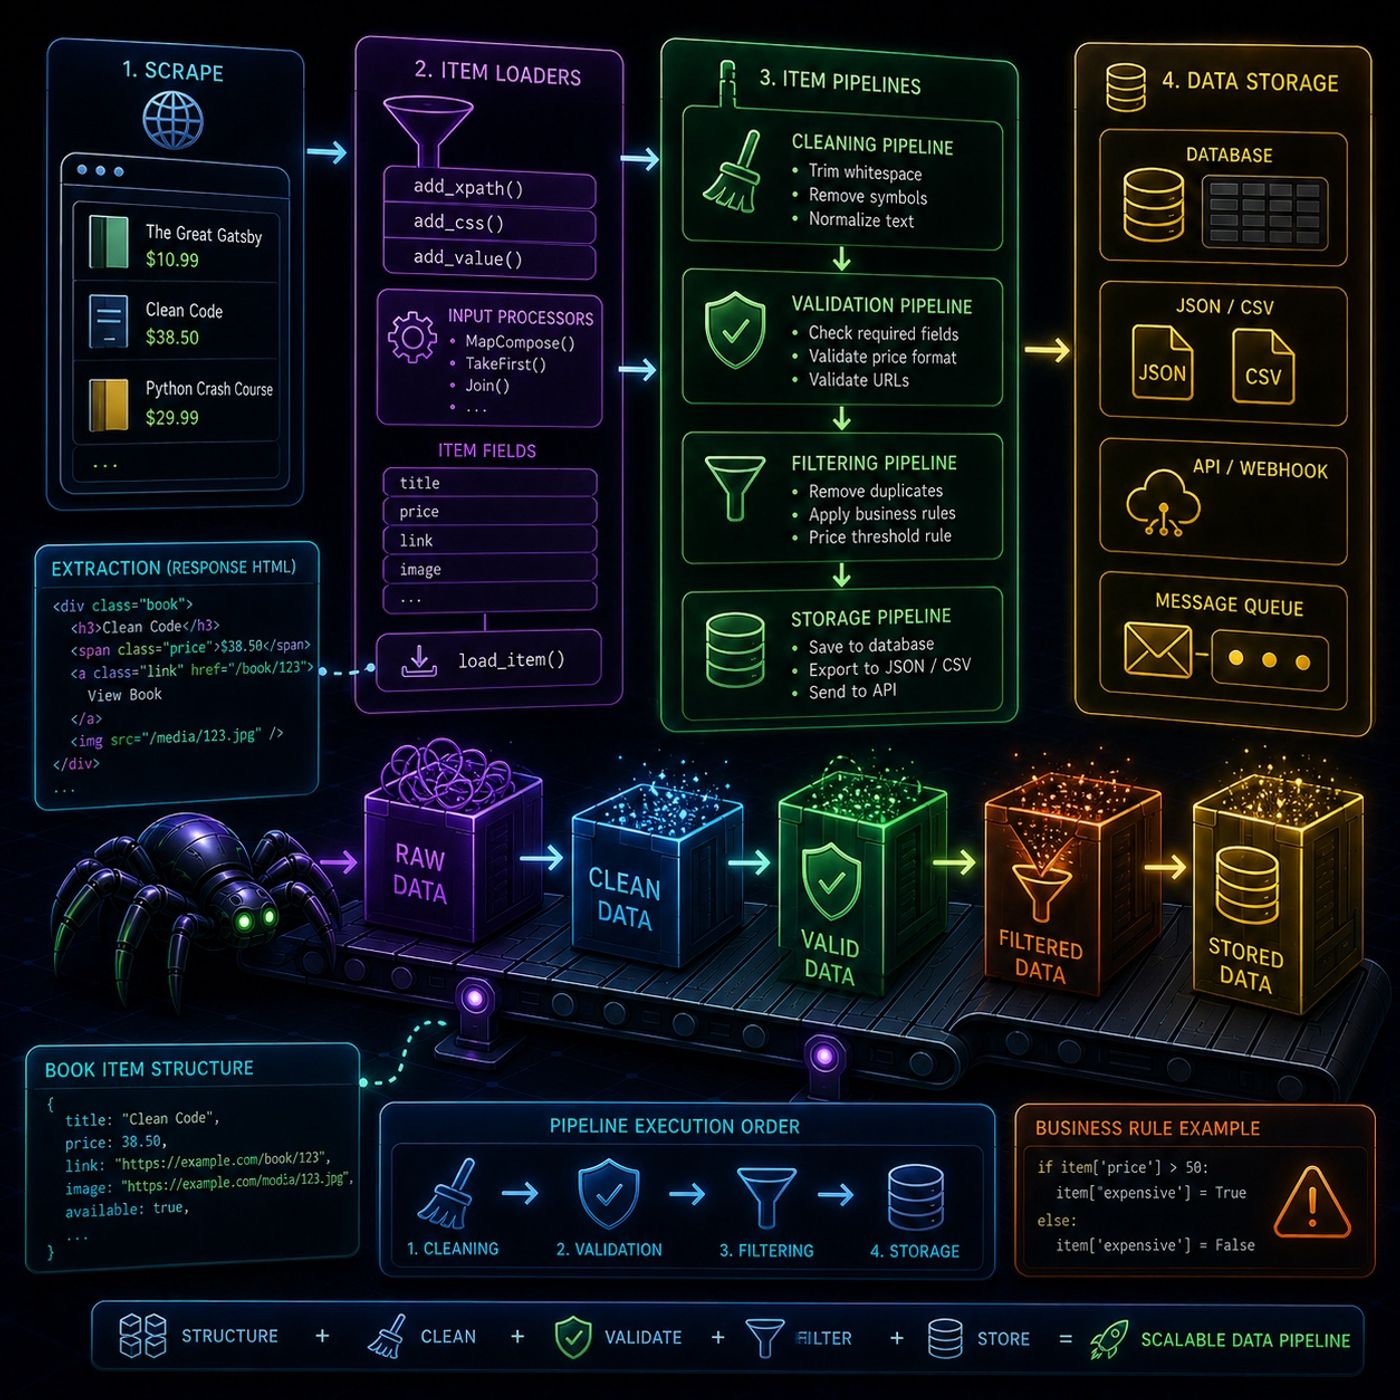
This episode is essentially about turning Scrapy from “just a scraper” into a full data processing system, where extraction, cleaning, validation, and storage are all structured and automated.🕷️ Scrapy Data Population & Processing Pipeline1. 📦 Item Loaders (Structured Data Population)Item Loaders are the layer between raw scraped HTML and structured Scrapy Items.Instead of manually assigning fields, you feed data through controlled methods:🔹 Core methodsadd_xpath()add_css()add_value()These methods:collect raw extracted valuespass them through processors automaticallybuild a clean final item via load_item()💡 Why this mattersInstead of:messy manual parsingscattered cleaning logicYou get:A single controlled pipeline for building structured objects🔄 Item Loader FlowResponse HTML ↓ add_xpath / add_css / add_value ↓ Input Processors (cleaning + normalization) ↓ Item Fields (structured data) ↓ load_item() ⚙️ 2. Item Pipelines (Post-Extraction Processing Layer)Item Pipelines operate after scraping, acting like a processing conveyor belt.Each pipeline class can:modify datavalidate datareject invalid itemsstore data🔹 Common Pipeline Responsibilities🧹 Data Cleaningremove unwanted charactersnormalize formatsfix inconsistent values✅ Validationcheck price formatsvalidate emails or URLsensure required fields exist🚫 Filteringdrop invalid or unwanted itemsblock duplicatesfilter based on business rules💾 Storagesave to databaseexport to JSON / CSVpush into APIs📚 3. Practical Example: Book Scraping SystemThe episode demonstrates a real workflow using a book website.🔹 Data Transformation ExampleMapCompose usageUsed to transform raw fields like:image URLs → full valid URLsbook links → normalized linkstext cleanup (whitespace, symbols)🔹 Custom Pipeline LogicExample rule:“Flag or drop books where price > threshold”So the pipeline can:mark expensive booksexclude them entirelyor route them differently🔹 Pipeline OrderingScrapy allows multiple pipelines:You define execution order in settings:Item Pipeline Order: 1. Cleaning Pipeline 2. Validation Pipeline 3. Filtering Pipeline 4. Storage Pipeline This ensures:Data always flows in a predictable transformation sequence🧠 Key Concept of the EpisodeThe main idea is:Scrapy is not a scraper — it is a data engineering pipeline frameworkYou are not just collecting data, you are:structuring it (Item Loaders)refining it (Processors)validating it (Pipelines)and storing it (Final output layer)🧩 Mental ModelLayerPurposeItem LoadersBuild structured itemsProcessorsClean + normalize fieldsPipelinesValidate + transform + storeSettingsControl execution order🚀 Big Picture InsightThis episode shows the shift from:❌ “scrape → print data”to:✅ “scrape → structure → clean → validate → store → scale”You can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 31: From Item Loaders to Pipelines
No transcript for this episode yet
Similar Episodes
No similar episodes found.