
EPISODE · Aug 15, 2026 · 20 MIN
Course 40 - Web Scraping with Python | Episode 35: Locating Dynamic Elements with Selenium and Python
from CyberCode Academy · host CyberCode Academy
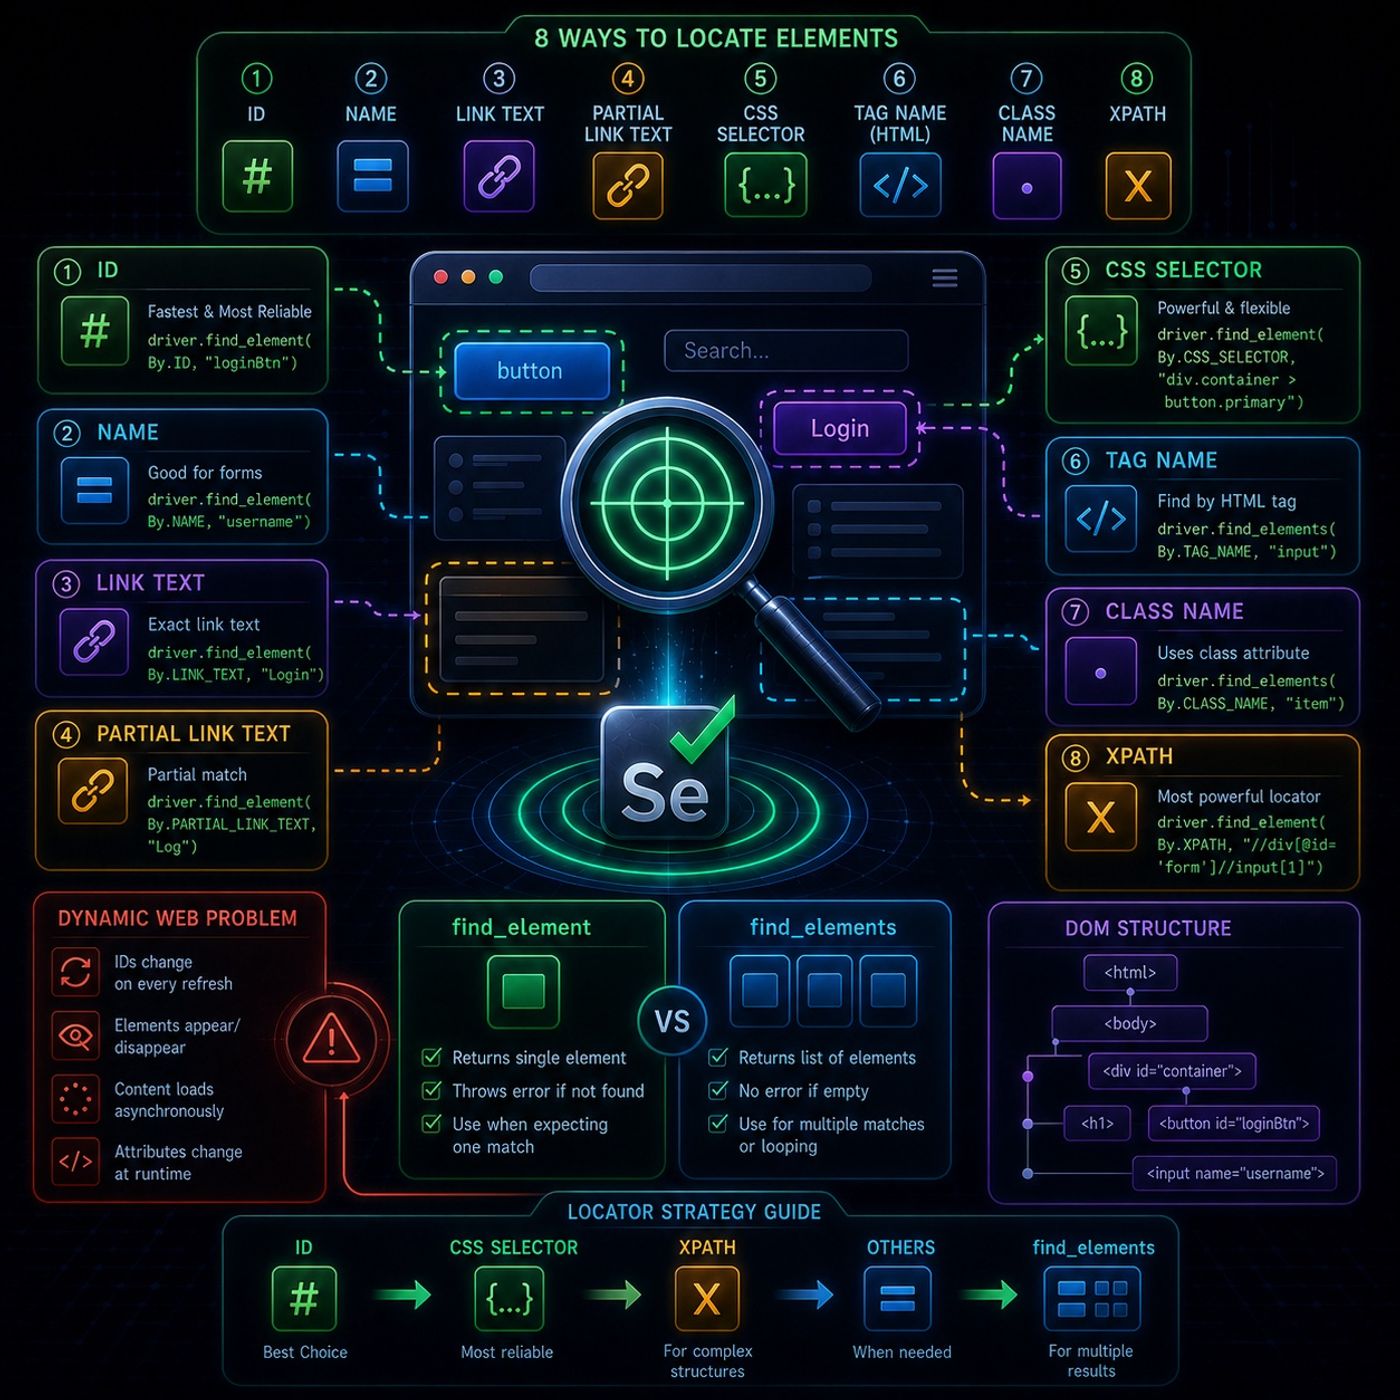
This module is basically about the core skill in Selenium automation: reliably finding the right element on a page that keeps changing.🧩 What “locating elements” really meansIn Selenium, everything you interact with is a web element, such as:buttonsinput fieldslinksimageshidden UI components used by JavaScriptModern web apps are often dynamic, meaning:IDs change on every refreshclasses are generated randomlyelements appear/disappear after AJAX callsSo the real challenge is not clicking elements — it’s finding them consistently.⚠️ The Dynamic Web ProblemUnlike static HTML pages, modern JavaScript-heavy sites:regenerate DOM elements constantlyload content asynchronouslymodify attributes at runtimeThat’s why a locator that works once may fail on the next page load.🔍 The 8 Ways to Locate ElementsSelenium gives multiple strategies. Each has a different “strength level”.1. 🆔 ID (Best option)Fastest and most reliableMust be uniqueBreaks only if developers change structure2. 🏷️ NameWorks when ID is missingCommon in forms3. 🔗 Link TextMatches full hyperlink textExample: “Login”Partial Link TextMatches part of a linkMore flexible but less precise4. 🎯 CSS SelectorsVery powerful and widely usedUses patterns like:classeshierarchyattributesExample idea:“div.container button.primary”5. 🧱 Tag NameFinds elements like , , Usually returns many results6. 🎨 Class NameUses CSS class attributeRisk: many elements share same class7. 🧭 XPath (Most powerful)Can navigate DOM like a treeWorks even when structure is messyKey advantage:supports relative pathscan search based on text, attributes, hierarchy⚙️ Two Core Retrieval Methods🔹 find_elementreturns single elementthrows error if not foundbest when you expect exactly one match🔹 find_elementsreturns list of elementssafe (no exception if empty)you can loop or index results🧠 Practical InsightThe real decision rule is:Use ID firstIf not available → CSS SelectorIf structure is complex → XPathIf multiple results → find_elements⚡ Key TakeawayThis module is really teaching one idea:Selenium automation fails not because of actions, but because of bad element selection strategiesSo robust scraping depends on:choosing stable attributesavoiding fragile selectorshandling dynamic DOM changesYou can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 35: Locating Dynamic Elements with Selenium and Python
No transcript for this episode yet
Similar Episodes
No similar episodes found.