
EPISODE · Aug 18, 2026 · 20 MIN
Course 40 - Web Scraping with Python | Episode 38: Scraping Dynamic Premier League Stats and News with Selenium and BeautifulSoup
from CyberCode Academy · host CyberCode Academy
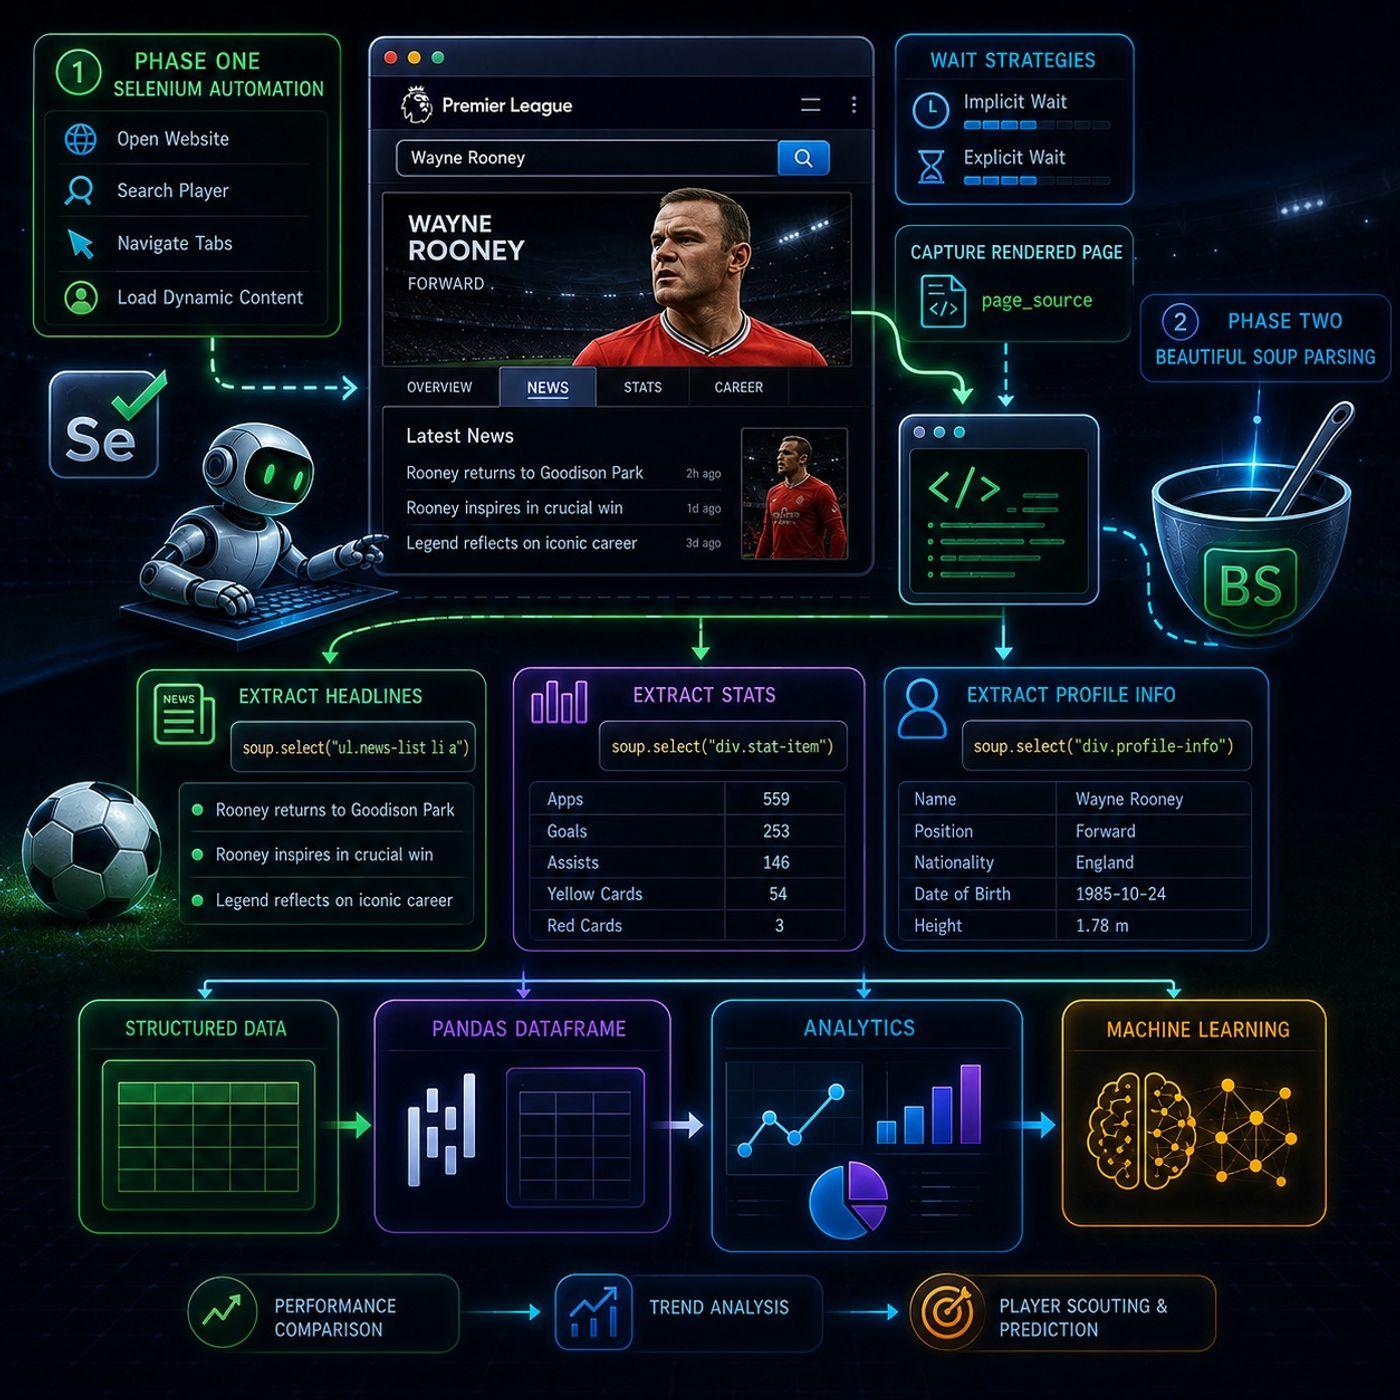
This episode is a practical end-to-end example of the Selenium + Beautiful Soup hybrid scraping pattern, applied to a real sports data use case (Premier League player pages).⚽ Goal of the ProjectScrape structured data about Wayne Rooney from a dynamic football website, including:News headlinesCareer statisticsPlayer profile informationThis is a classic case where:Content is JavaScript-rendered (dynamic)Page structure changes after interactionStatic scraping alone would fail🧭 1. Phase One — Selenium (Browser Automation)Selenium is used here as a real user simulator.What it does:Opens the Premier League websiteNavigates to the player sectionUses search to find Wayne RooneyClicks through profile tabs (news, stats, etc.)Why Selenium is required:Because the site:Loads content dynamically via JavaScriptRequires user interaction (clicks, navigation)Doesn’t expose all data in initial HTML⏳ Critical Concept: WaitsThe episode emphasizes two types of synchronization:🔹 Implicit WaitGlobal delay applied to all element searchesSelenium keeps retrying until element appears🔹 Explicit WaitWaits for specific conditions:element becomes clickableelement is visibleDOM finishes loading👉 This is essential because dynamic pages load unpredictably.📥 2. Capture the Final Rendered PageAfter navigation:Selenium grabs the final DOM using page_sourceAt this point:You have the fully rendered browser state, including JavaScript-generated content.🧪 3. Phase Two — Beautiful Soup (Fast Parsing)Now Selenium steps out, and Beautiful Soup takes over.Why switch tools?Because:Selenium is slow for repeated extractionBeautiful Soup works on local HTML memoryParsing becomes significantly faster🧠 Extraction ProcessOnce HTML is passed into BS4:📰 Headlines extractionLocate or structured containersExtract text cleanly from tags📊 Stats extractionTarget stat containersRead:labels from attributesnumeric values from text nodes🔄 Key Design InsightThis architecture is:Selenium = navigation engineBeautiful Soup = data extraction engineThey are not competing tools — they are complementary.📌 Why this approach scalesThe episode highlights a key idea:Player-agnostic designOnce built, the same script can:scrape any player profilereuse the same selectorsscale across hundreds of pages🚀 Extension Path (Important)The workflow naturally evolves into:1. Data structuringConvert scraped data into tables using Pandas2. AnalyticsCompare players statisticallyTrack performance over time3. ML applicationsperformance predictionsentiment analysis on news articlesscouting models🧠 Core TakeawayThis is a real production scraping pattern:Selenium → reach the data (dynamic navigation)page_source → freeze the stateBeautiful Soup → extract efficientlyPandas/ML → analyze downstreamYou can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 38: Scraping Dynamic Premier League Stats and News with Selenium and BeautifulSoup
No transcript for this episode yet
Similar Episodes
No similar episodes found.