
EPISODE · Aug 19, 2026 · 23 MIN
Course 40 - Web Scraping with Python | Episode 39: Overcoming Challenges and Optimizing Performance
from CyberCode Academy · host CyberCode Academy
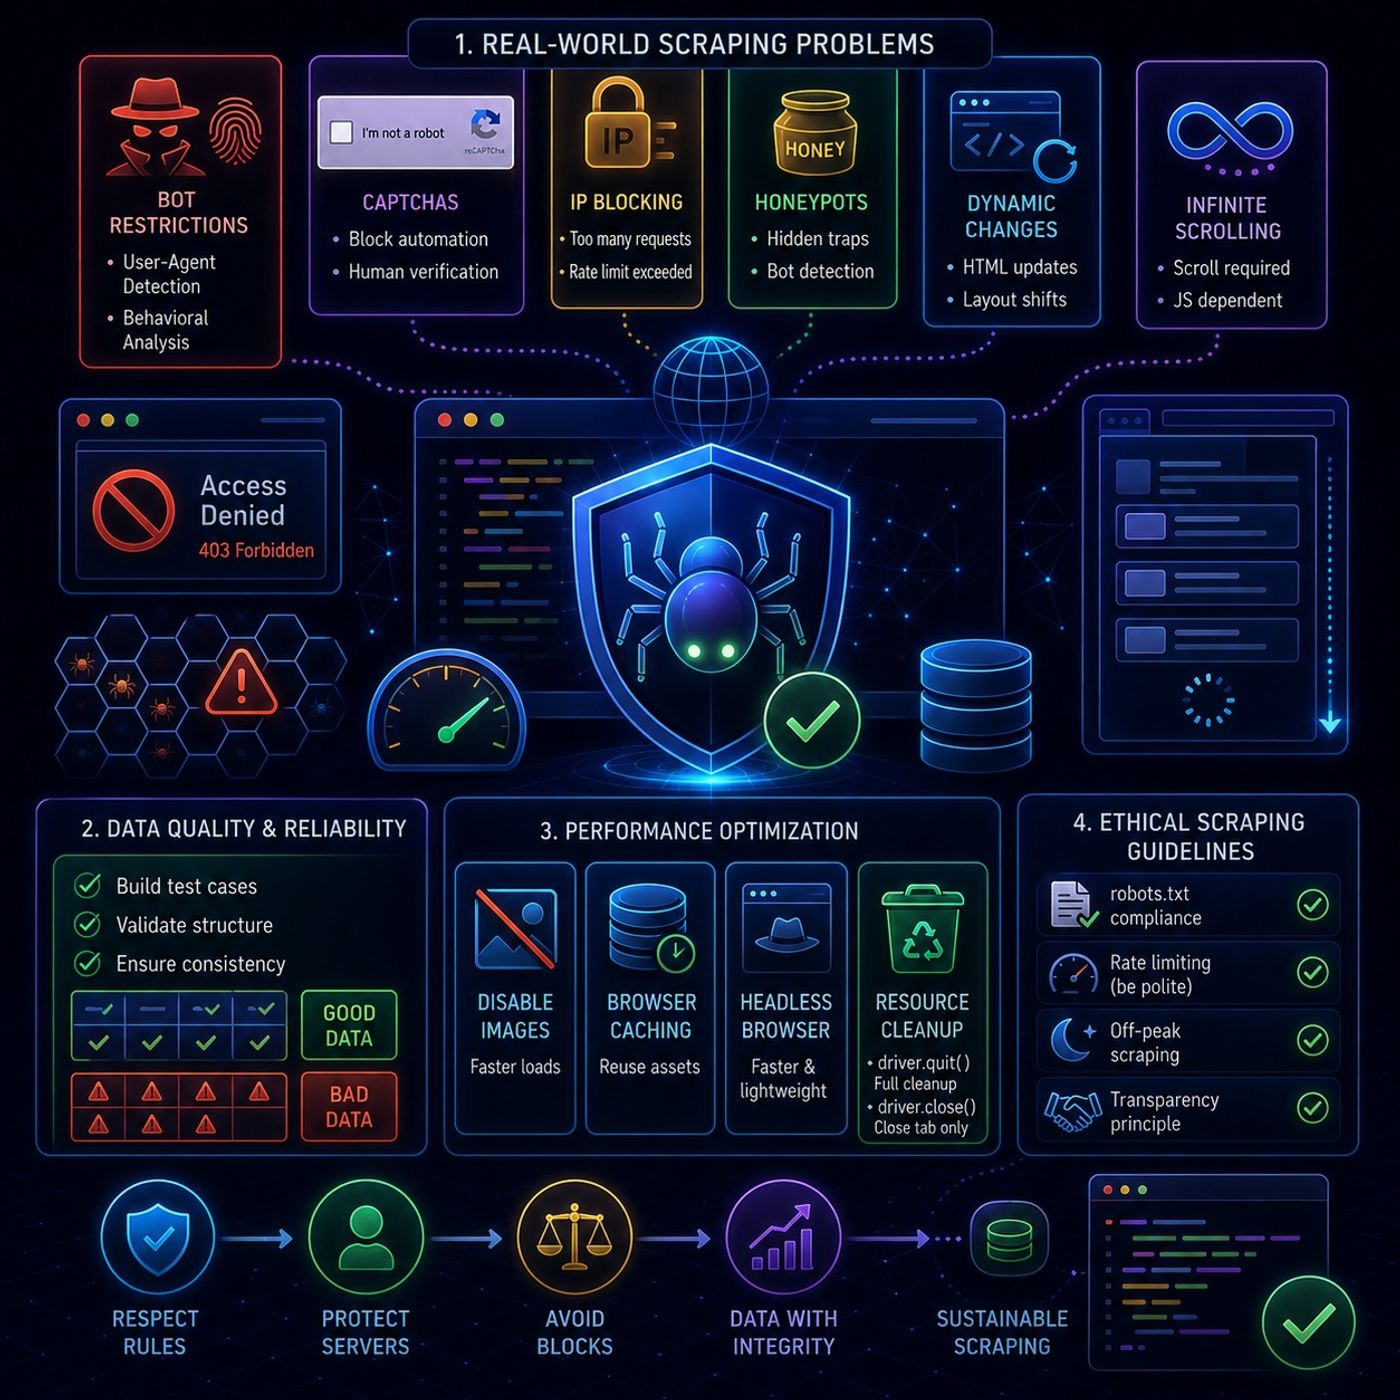
This module is essentially the “real world survival guide” for web scraping — it moves away from pure tooling and focuses on what actually breaks scrapers in production and how to behave responsibly while scraping at scale.🚧 1. Real-World Scraping ProblemsModern websites actively defend themselves against automation, so scraping is rarely “just code and go”.🚫 Bot RestrictionsWebsites may block automated traffic using:User-agent detection (recognizing Selenium / bots)Behavioral analysis (click speed, navigation patterns)🧩 CAPTCHAsA major anti-bot mechanism:Designed to distinguish humans from automationOften blocks login pages, search pages, or high-value data🌐 IP BlockingIf you:send too many requestsscrape too fastignore rate limitsThen servers may:temporarily block your IPpermanently blacklist it🕳️ HoneypotsHidden traps inside websites:invisible linksfake endpointsnon-visible HTML elements👉 If your bot clicks them, it gets flagged instantly.🔄 Dynamic Structure ChangesWebsites constantly evolve:HTML layouts changeclass names get renamedelements move or get removedThis causes:Scrapers to break without warning♾️ Infinite ScrollingInstead of pages, content loads as you scroll:requires scroll automationrequires dynamic request handlingoften tied to JavaScript APIs🧪 2. Data Quality & ReliabilityScraping is not just about collecting data — it’s about ensuring it’s usable later.Recommended practice:build test cases for scraped outputvalidate structure before savingensure consistency across runsWhy?Because bad scraped data can:corrupt datasetsbreak ML pipelinesproduce misleading analytics⚡ 3. Performance Optimization TechniquesThe module introduces practical speed improvements:🖼️ Disable Imagesprevents browser from loading heavy assetsdrastically reduces page load time💾 Browser Cachingreuse previously loaded assetsavoids redundant downloads🧠 Headless BrowsersRun Chrome without UI:faster executionlower memory usageideal for automation servers🧹 Proper Resource CleanupImportant rule:driver.quit() → closes everything (safe cleanup)driver.close() → closes only current tab👉 Not quitting properly can leak memory and processes.⚖️ 4. Ethical Scraping GuidelinesThis is the most important conceptual layer.📄 robots.txt compliancedefines what bots are allowed to accessignoring it can violate site rules or laws🧠 Rate limiting (be a “polite bot”)avoid rapid-fire requestsprevent server overload🕒 Off-peak scrapingrun jobs during low traffic hoursreduces impact on real users🎭 Transparency principleA “good bot” should:not disguise malicious intentnot impersonate real usersbehave predictably and responsibly🧠 Core Philosophy of the ModuleScraping is not just a technical task — it’s a system interaction problem with ethical constraintsSo you need three layers:Technical robustness (avoid breaks)Performance efficiency (don’t waste resources)Ethical compliance (don’t abuse systems)🔥 Final TakeawayModern scraping isn’t about “how to extract data” anymore.It’s about:how to extract data without breaking systems, getting blocked, or violating rulesYou can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 39: Overcoming Challenges and Optimizing Performance
No transcript for this episode yet
Similar Episodes
No similar episodes found.