
EPISODE · Jul 15, 2026 · 23 MIN
Course 40 - Web Scraping with Python | Episode 5: From Environment Setup to Pandas DataFrames
from CyberCode Academy · host CyberCode Academy
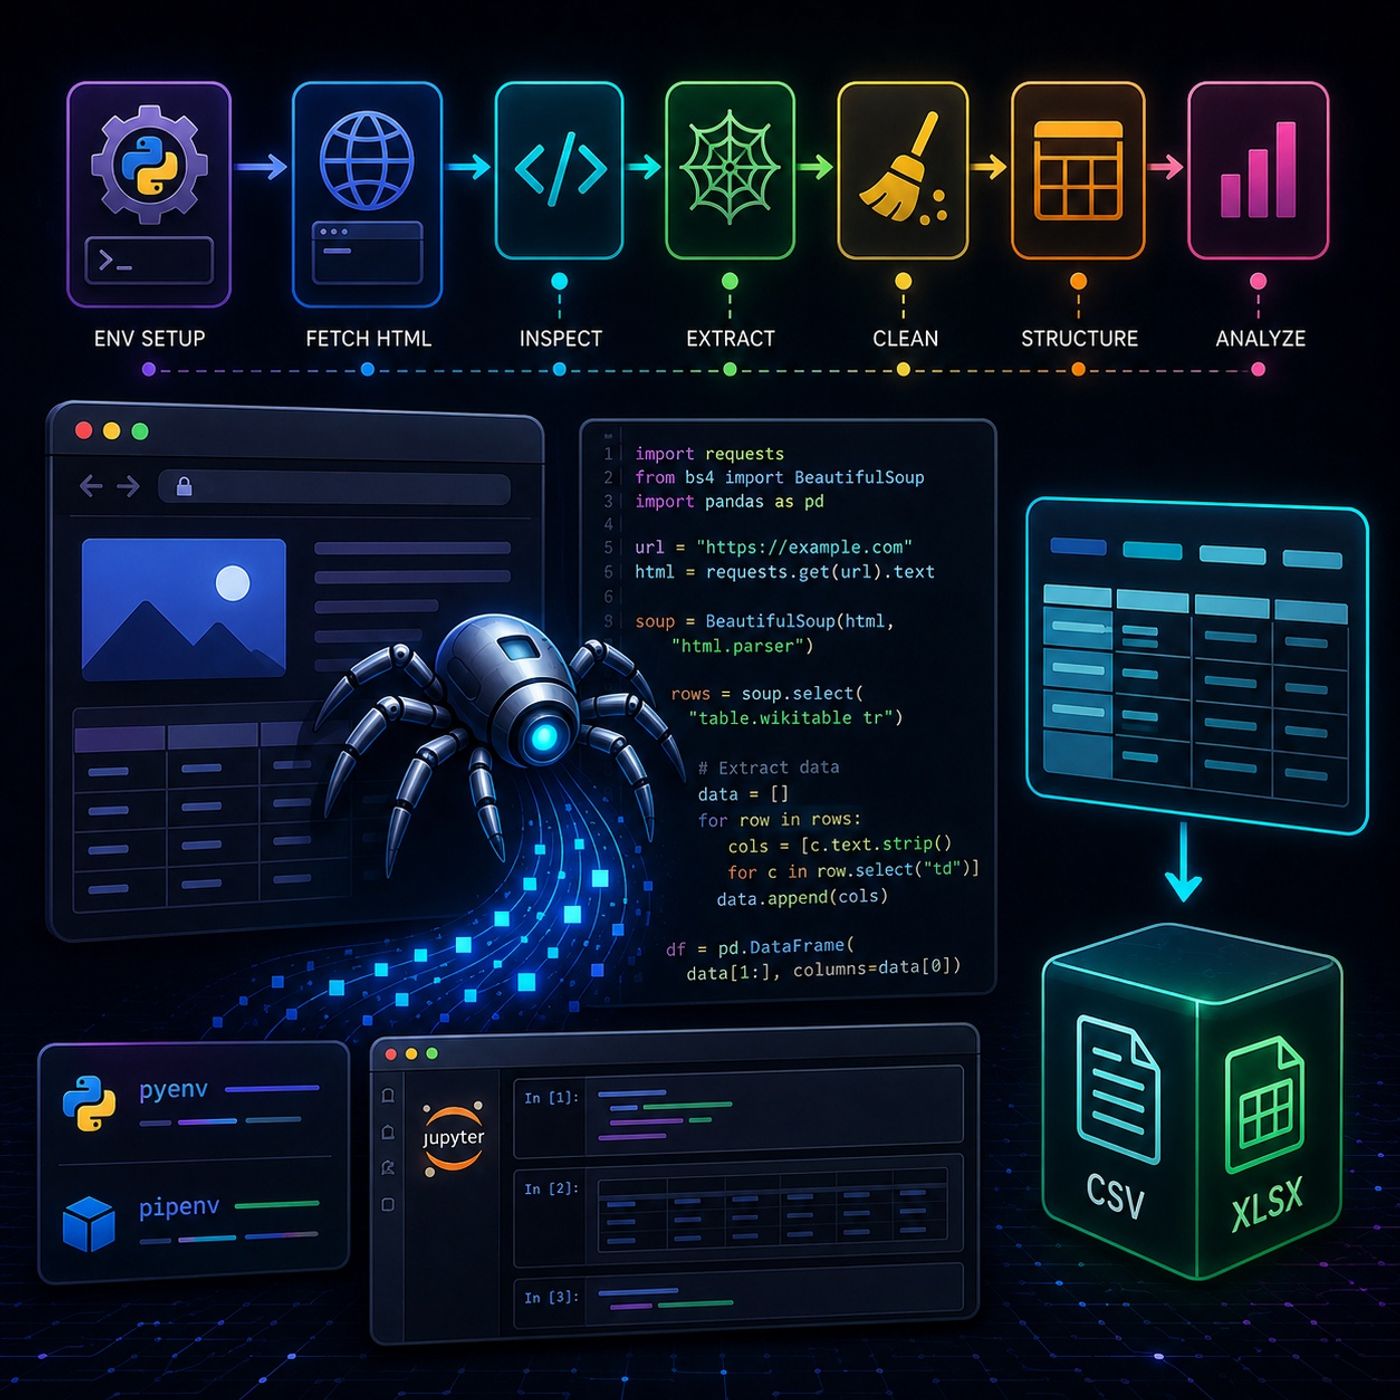
In this lesson, you’ll learn about: setting up a professional Python scraping environment, extracting web data step-by-step, and transforming raw HTML into structured datasets1. Setting Up Your Development Environment🔹 Python Version ManagementUse pyenvInstall and switch between Python versions بسهولةAvoid compatibility issues across projects🔹 Virtual Environments & DependenciesUse pipenvCreate isolated environmentsManage dependencies like:requestsBeautifulSoup4pandas👉 Key InsightClean environment = fewer bugs + reproducible projects🔹 Interactive DevelopmentUse JupyterLabRun code in cells step-by-stepInspect outputs instantlyExplore files and HTML visually2. Downloading & Inspecting Web Content🔹 Fetching HTML PagesUse Requestsimport requests url = "https://example.com" response = requests.get(url) html = response.text 🔹 Why Save Locally?Work offlineAvoid repeated requestsDebug faster🔹 Inspecting the PageUse:JupyterLab HTML viewerBrowser DevTools (Elements tab)👉 Goal:Locate the exact HTML structure of your target data (e.g., tables, divs)3. Extracting Data with BeautifulSoup🔹 Parsing HTMLUse BeautifulSoupfrom bs4 import BeautifulSoup soup = BeautifulSoup(html, "html.parser") 🔹 Using CSS Selectorstable = soup.select("table.wikitable")[0] rows = table.select("tr") 👉 This allows precise targeting of elements4. Cleaning the Data🔹 Fix Column NamesRemove whitespaceReplace spaces with _clean_header = header.text.strip().replace(" ", "_") 🔹 Remove Unwanted Patterns (Regex)Use Regular Expressionimport re clean_text = re.sub(r"\[.*?\]", "", raw_text) 👉 Removes things like:[1], [citation needed]5. Structuring the Data🔹 Build a “List of Lists”data = [] for row in rows: cols = [col.text.strip() for col in row.select("td")] data.append(cols) 👉 Structure becomes:[ ["Name", "Age", "City"], ["John", "25", "NY"], ] 6. Creating a DataFrame🔹 Use PandasUse pandasimport pandas as pd df = pd.DataFrame(data[1:], columns=data[0]) 🔹 Why DataFrames MatterEasy filteringData analysisExport to CSV/Excel7. Full Workflow (Big Picture)Setup environment (pyenv + pipenv)Fetch HTML (Requests)Inspect structure (DevTools / Jupyter)Extract data (BeautifulSoup)Clean data (Regex + string ops)Structure data (lists)Analyze (Pandas DataFrame)Mental ModelRaw HTML → Parsed DOM → Extracted Elements → Clean Data → Structured Dataset → Analysis👉 Final TakeawayA successful scraping project is not just about extraction—it’s about building a clean, repeatable pipeline that turns messy web content into usable data.You can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 5: From Environment Setup to Pandas DataFrames
No transcript for this episode yet
Similar Episodes
No similar episodes found.