
EPISODE · Jul 19, 2026 · 21 MIN
Course 40 - Web Scraping with Python | Episode 9: Navigating Requests, Redirects, and Timeouts
from CyberCode Academy · host CyberCode Academy
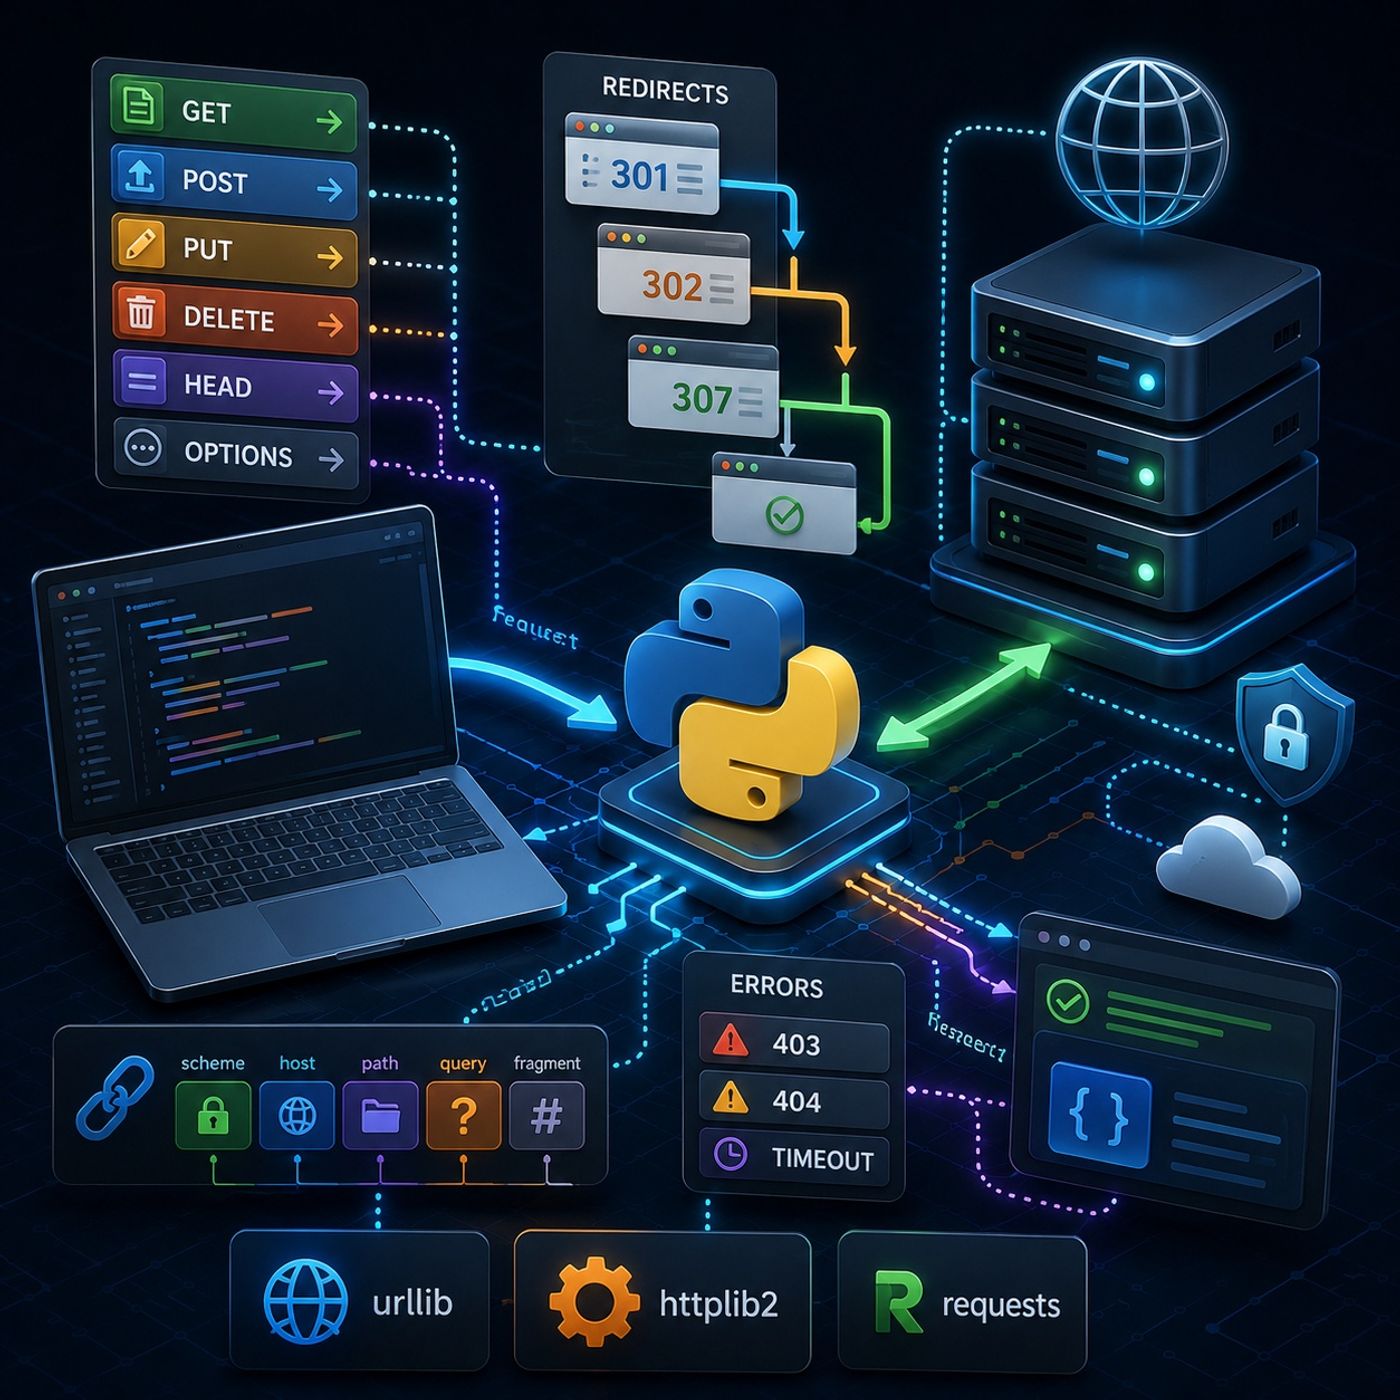
In this lesson, you’ll learn about: how to handle HTTP requests in Python, compare different libraries, manage redirects and errors, and use modern tools like Requests effectively1. The Big Picture: Talking to the Web🔹 What You’re Really DoingWhen working with HTTP in Python, you're:Sending requestsReceiving responsesHandling edge cases (errors, redirects, timeouts)👉 This is the foundation of:Web scrapingAPI integrationAutomation2. HTTP Methods Beyond the Basics🔹 Core Methods RecapMethodPurposeGETRetrieve dataPOSTSend dataPUTUpdate (idempotent)DELETERemove🔹 Advanced MethodsMethodUse CaseHEADGet headers only (no body)OPTIONSDiscover server capabilities👉 Pro InsightHEAD is great for checking if a resource exists without downloading itOPTIONS helps when working with APIs and permissions3. Redirect Handling (Critical in Real-World Scraping)🔹 What is a Redirect?A redirect happens when:Server tells you → “Go to another URL”🔹 Types of RedirectsSafe RedirectsGET, HEADAutomatically followedUnsafe RedirectsPOST, PUTMay require confirmation🔹 Why It MattersPrevent infinite loopsTrack where data actually comes fromDebug login flows or APIs4. URL Anatomy (Using urllib)🔹 Breaking Down a URLExample:https://example.com/products?id=10#reviews PartMeaningSchemehttpsLocationexample.comPath/productsQueryid=10Fragmentreviews🔹 Tool for ThisUse urllibfrom urllib.parse import urlparse parsed = urlparse("https://example.com/products?id=10") print(parsed.scheme, parsed.netloc) 👉 Why It’s ImportantHelps build clean scrapersUseful for filtering and routing URLs5. Error Handling (Making Your Code Bulletproof)🔹 Common ErrorsErrorMeaning403Forbidden (blocked)404Not foundTimeoutServer too slow🔹 Best Practiceimport requests try: r = requests.get("https://example.com", timeout=5) r.raise_for_status() except requests.exceptions.RequestException as e: print("Error:", e) 👉 Key InsightGood scrapers don’t just work…they fail gracefully6. Comparing Python HTTP Libraries🔹 The Three Main Tools1. Low-Level ControlUse httplib2Fine-grained controlMore verbose2. Built-in OptionUse urllibNo installationمتوسط التعقيد3. Modern Standard ⭐Use RequestsClean syntaxDeveloper-friendlyالأكثر استخدامًا7. Why Requests is the Go-To Tool🔹 Key FeaturesAutomatic POST encodingEasy JSON parsingBuilt-in timeout support🔹 Example: GET Requestimport requests r = requests.get("https://api.example.com/data", timeout=5) data = r.json() print(data) 🔹 Example: POST Requestpayload = {"username": "test", "password": "1234"} r = requests.post("https://api.example.com/login", data=payload) print(r.status_code) 👉 Why Developers Love ItLess codeMore readabilityHandles complexity internally8. Redirect Tracking in Requestsr = requests.get("http://example.com") print(r.url) # Final URL print(r.history) # Redirect chain 👉 Use CaseDetect hidden redirectsAnalyze tracking URLs9. Timeouts (Avoid Hanging Programs)🔹 The ProblemWithout timeout:Your script may freeze forever🔹 The Solutionrequests.get("https://example.com", timeout=3) 👉 Always set a timeout in production10. Mental ModelHTTP Request Handling =Send → Wait → Handle → RecoverFinal TakeawayMastering HTTP in Python isn’t about memorizing libraries—it’s about understanding how to control communication with servers.Once you combine:Proper method usageSmart redirect handlingStrong error managementAnd the power of Requests👉 You move from basic scripts to production-level data systems.You can listen and download our episodes for free on more than 10 different platforms:https://linktr.ee/cybercode_academy
Embed this episode
Ready to play
Course 40 - Web Scraping with Python | Episode 9: Navigating Requests, Redirects, and Timeouts
No transcript for this episode yet
Similar Episodes
No similar episodes found.