
EPISODE · Jun 11, 2026 · 18 MIN
Critical Batch Size for LLM Policy Optimization
from Best AI papers explained · host Enoch H. Kang
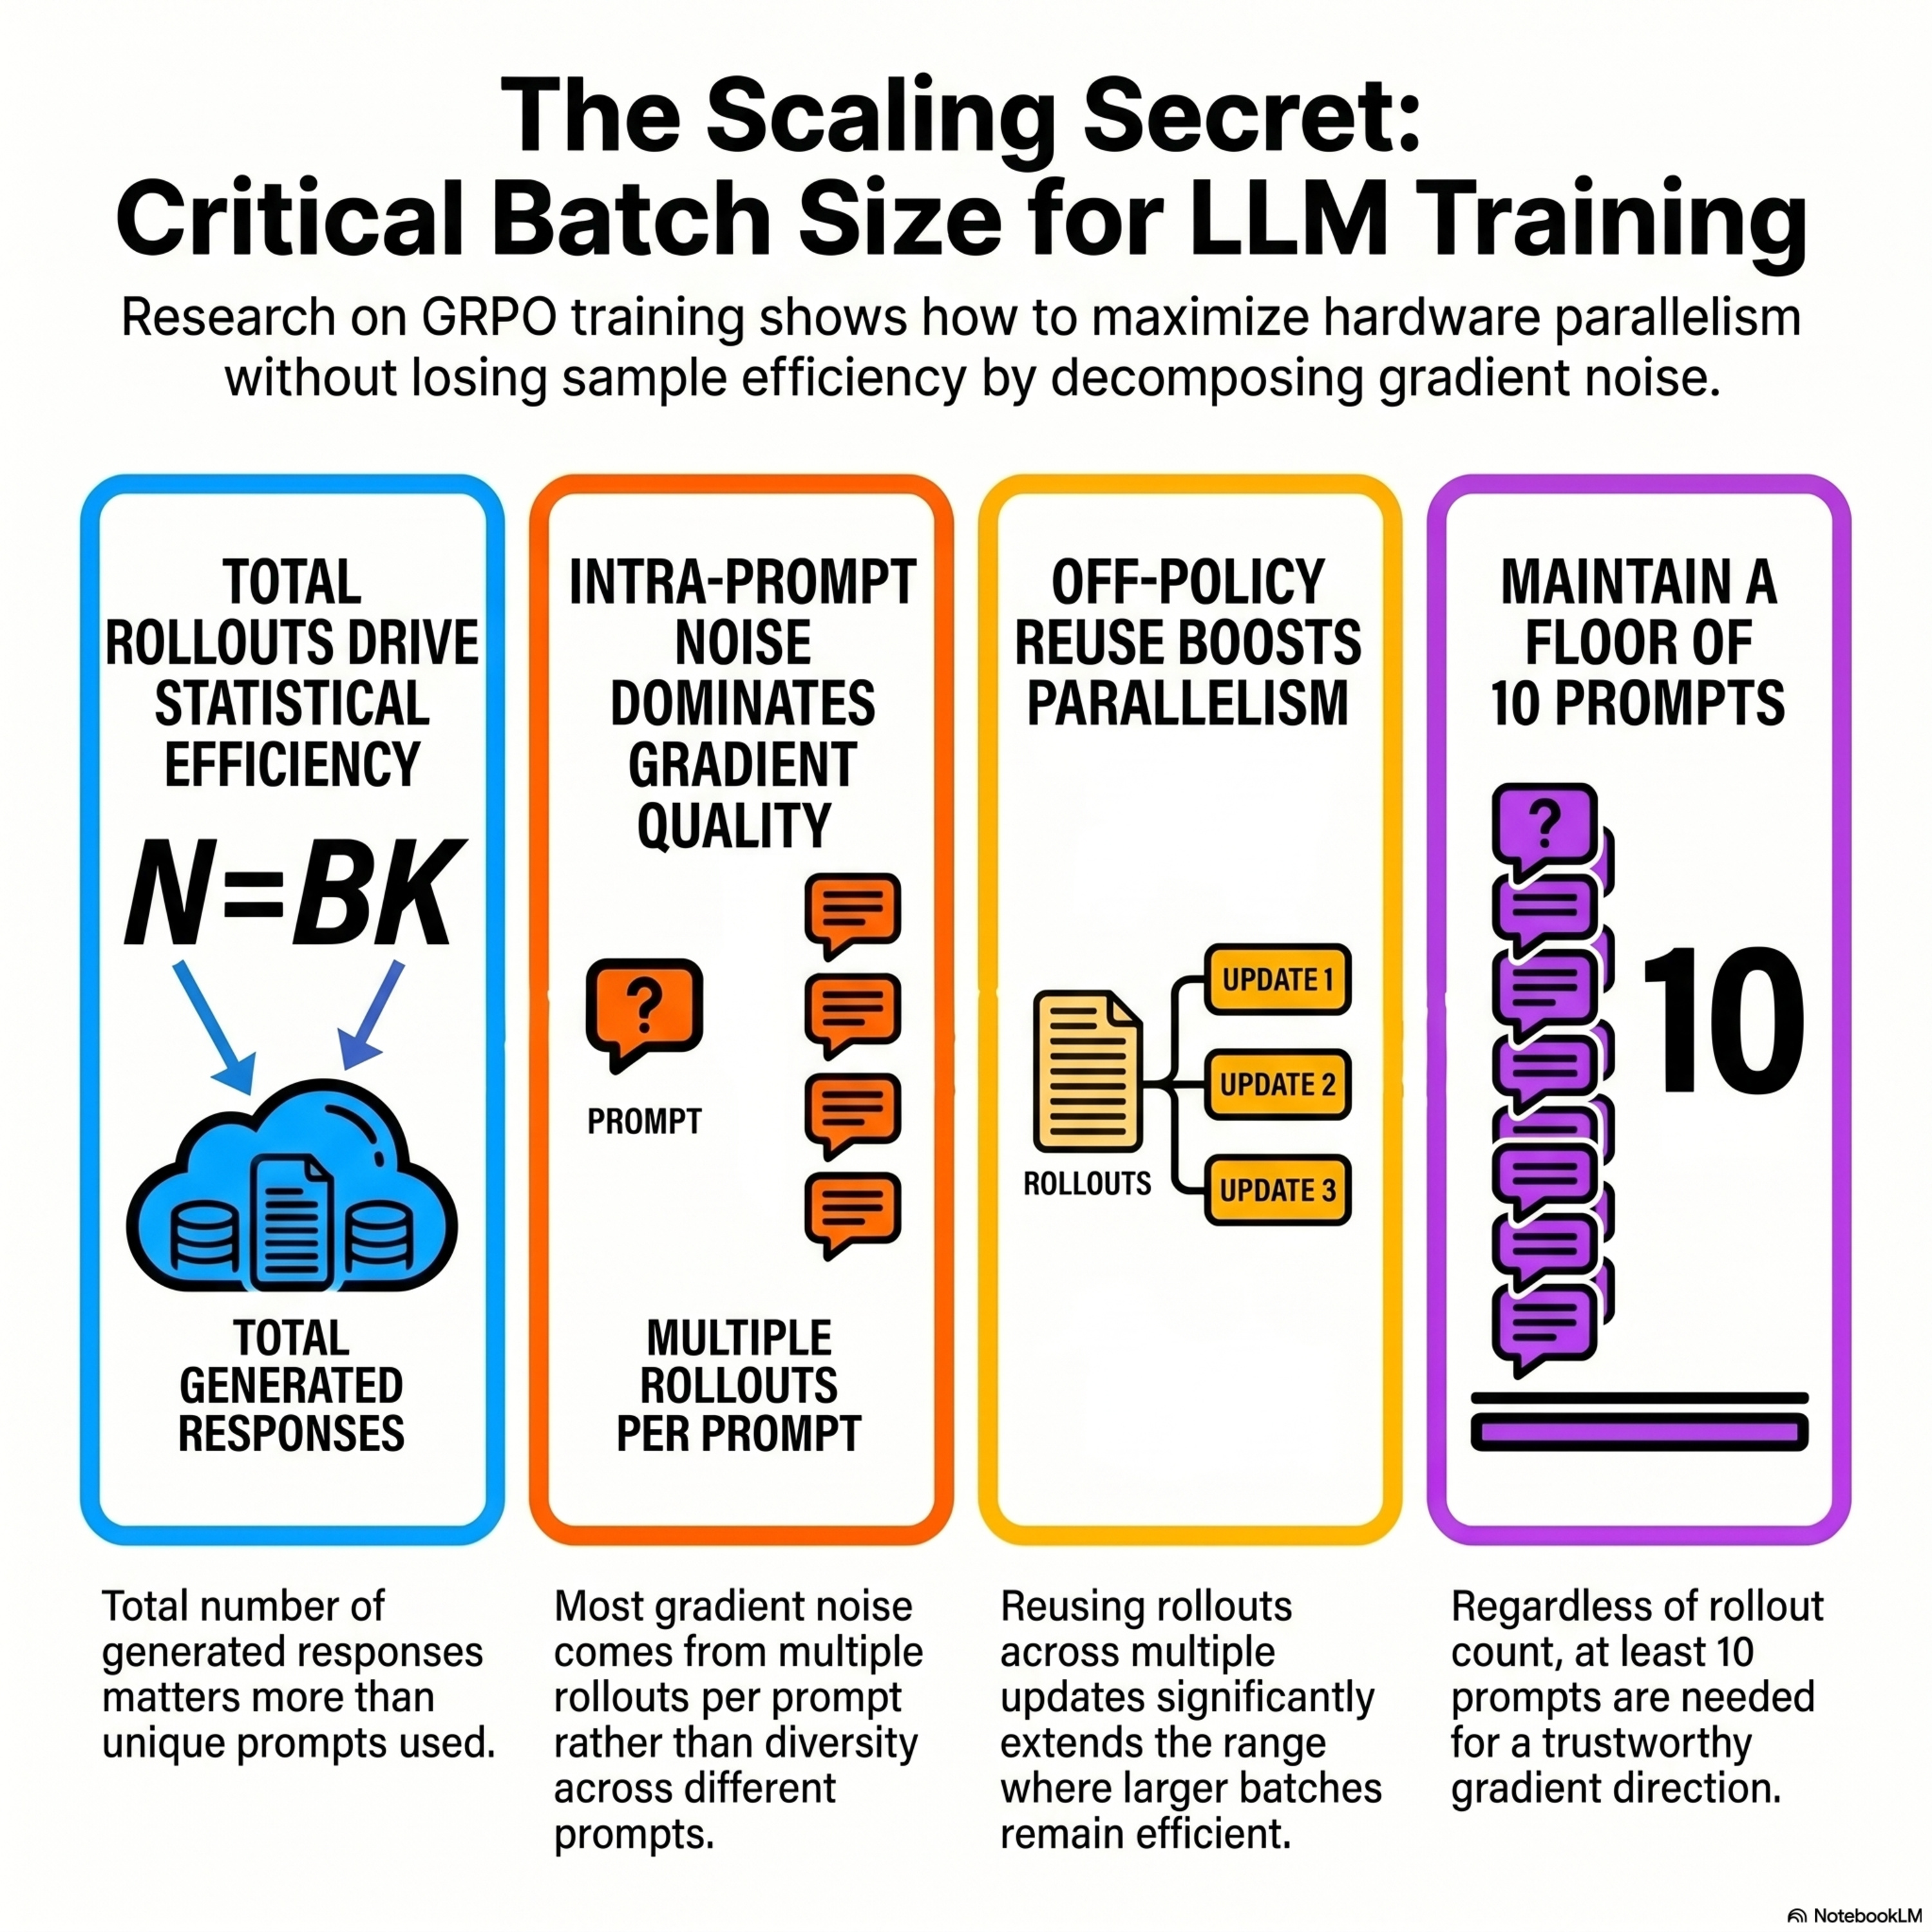
This paper investigates the critical batch size (CBS) for Large Language Model (LLM) policy optimization, specifically focusing on the GRPO algorithm. The researchers break down gradient noise into inter-prompt and intra-prompt components to determine the point where increasing data parallelism yields diminishing returns. Their findings reveal that on-policy training is primarily limited by noise within individual prompts, meaning the total rollout count is the most important factor for efficiency. In contrast, off-policy rollout reuse significantly expands the critical batch size, allowing for much greater computational parallelism. By modeling how policy drift inflates gradient noise, the study provides a theoretical and empirical framework for optimizing training efficiency in verifiable reinforcement learning. These results offer practical guidance for allocating hardware resources during the post-training phase of model development.
Embed this episode
Ready to play
Critical Batch Size for LLM Policy Optimization
No transcript for this episode yet
Similar Episodes
No similar episodes found.