Curriculum Learning-Guided Progressive Distillation in Large Language Models
from Best AI papers explained Hosted by Enoch H. Kang
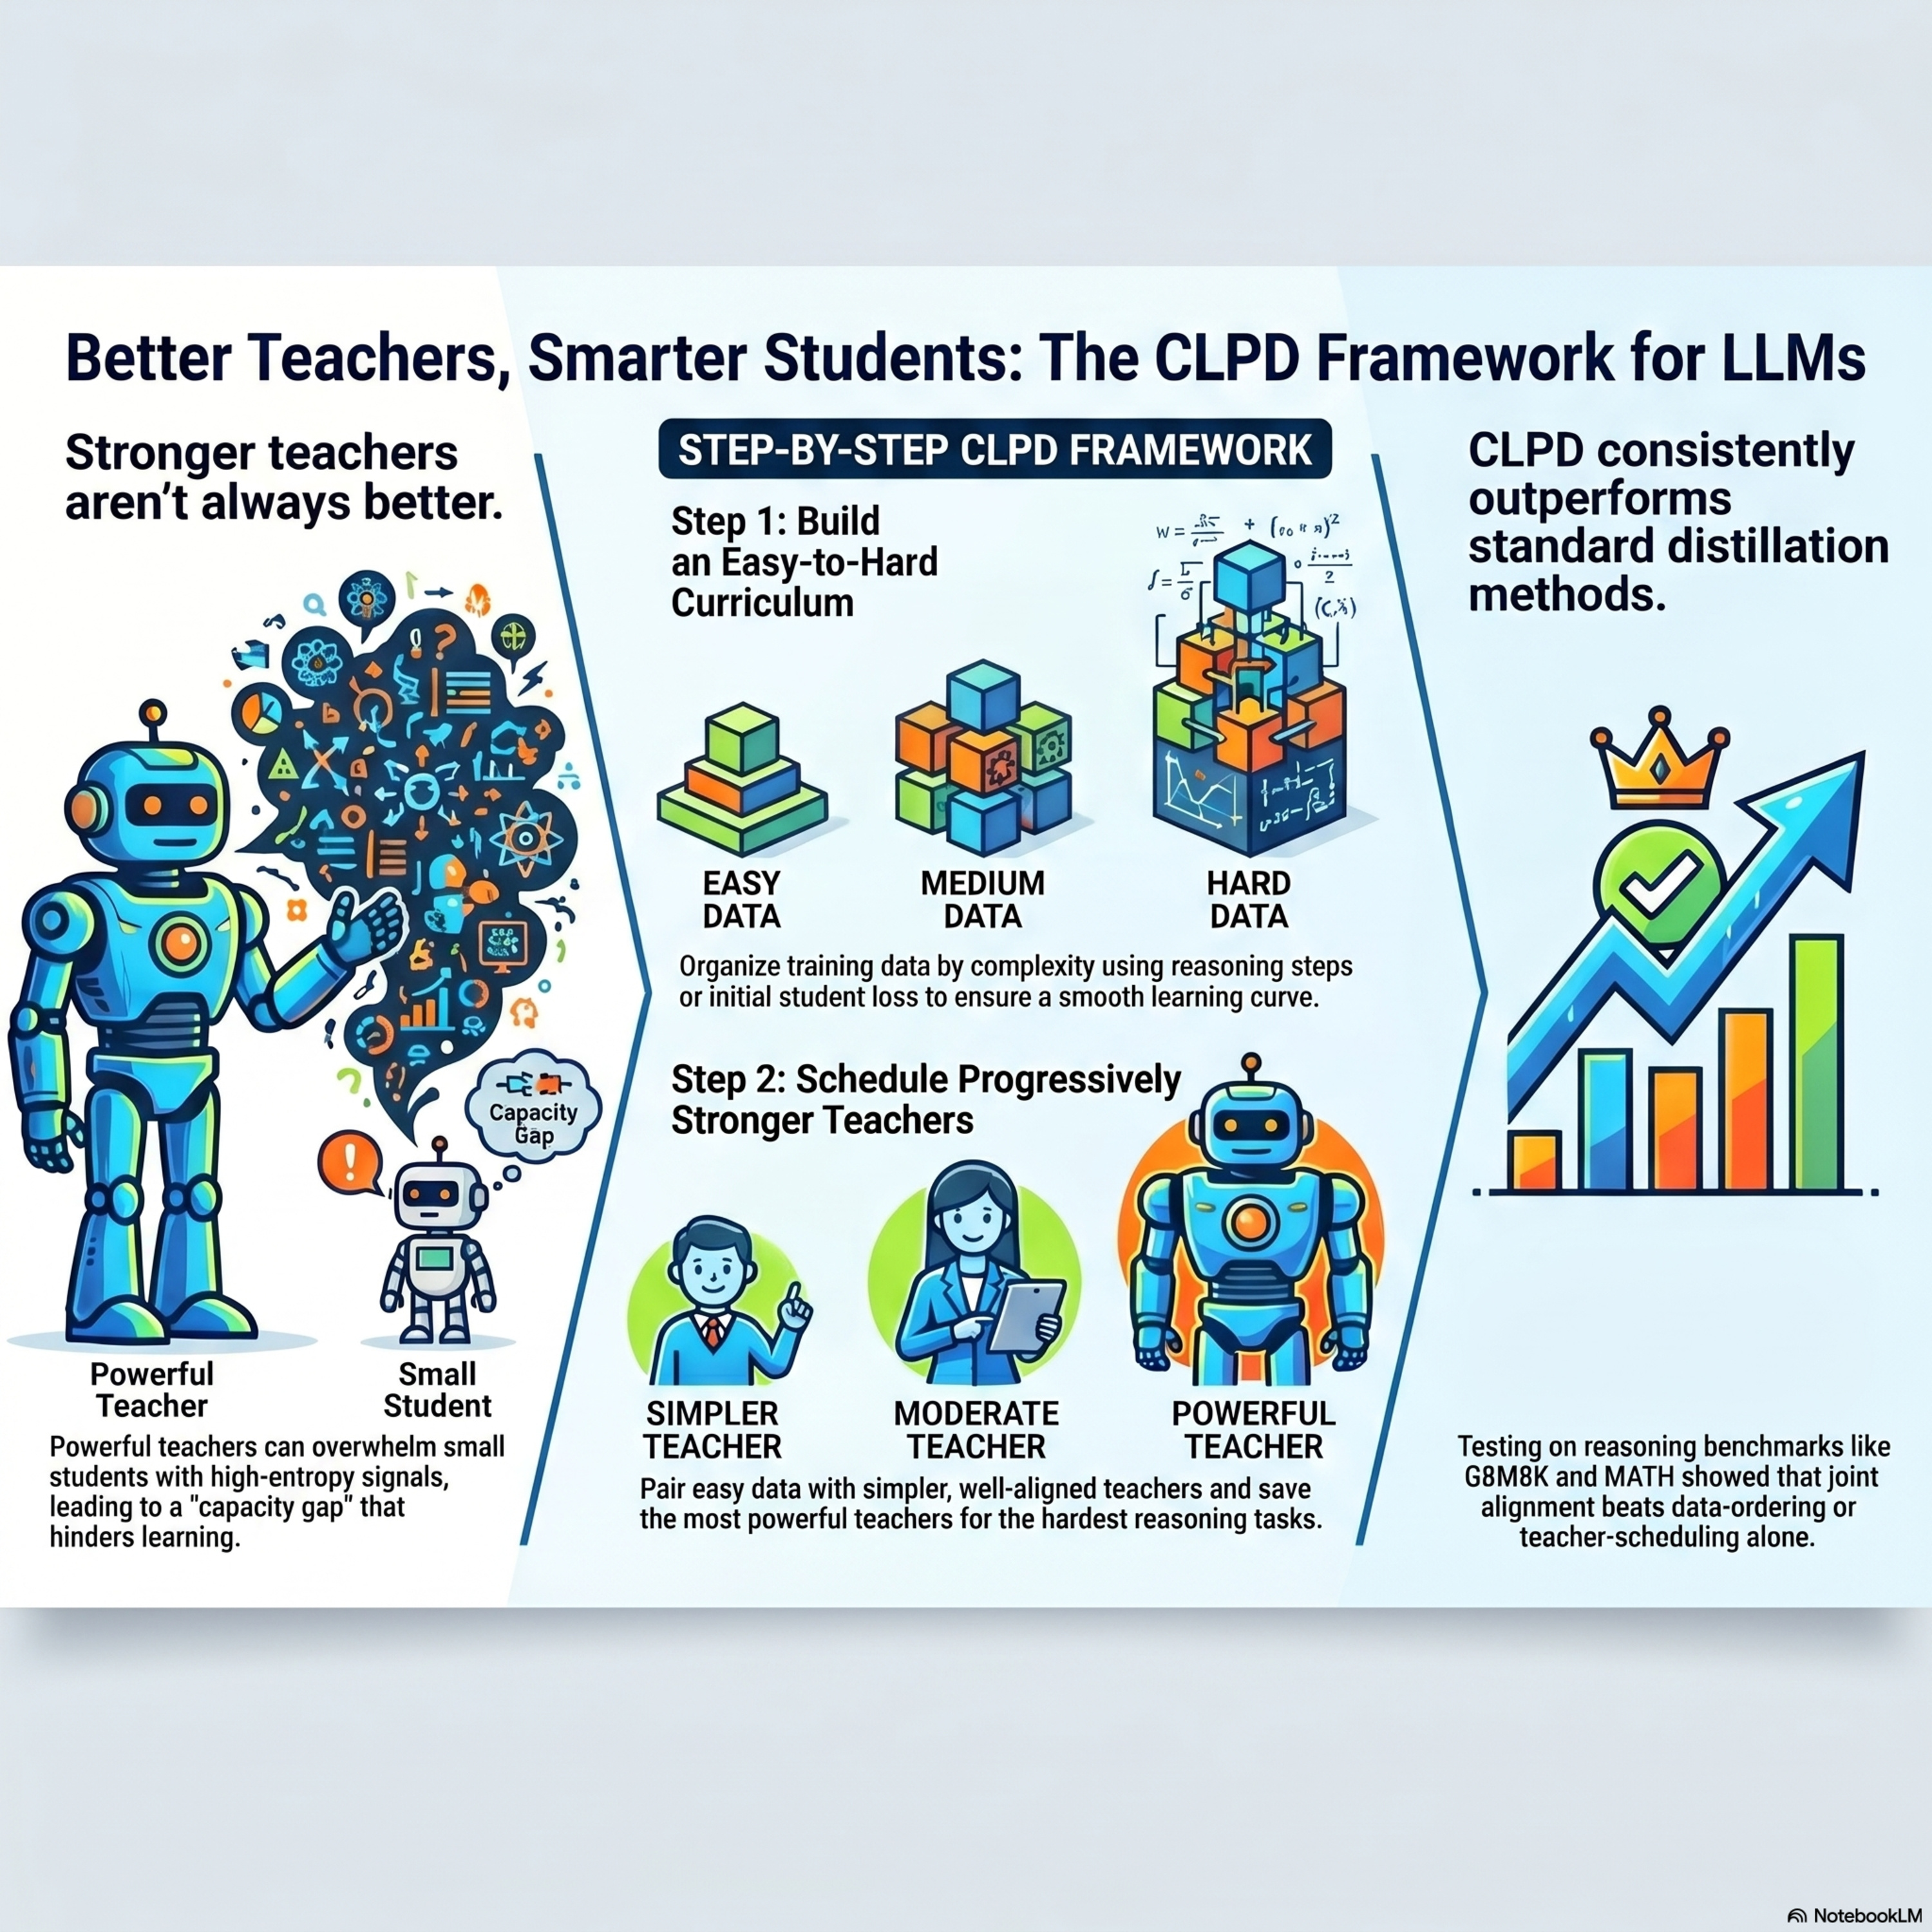
This paper introduces Curriculum Learning-Guided Progressive Distillation (CLPD), a novel framework designed to enhance the reasoning capabilities of small language models. The authors argue that traditional knowledge distillation fails when a significant capacity gap exists between a powerful teacher and a smaller student. To resolve this, CLPD simultaneously organizes training data from easy to hard while progressively increasing the strength of the teacher models used for supervision. This dual alignment ensures that students master fundamental logic through simpler instructions before attempting complex reasoning guided by high-capacity teachers. Empirical tests on mathematical and commonsense reasoning benchmarks show that this unified approach consistently outperforms methods that only use data ordering or teacher scheduling in isolation. Ultimately, the research demonstrates that effective knowledge transfer requires balancing teacher competence with the student's current learning stage.
Embed this episode
No transcript yet.