【第259期】Agentic Reward Modeling
from Seventy3
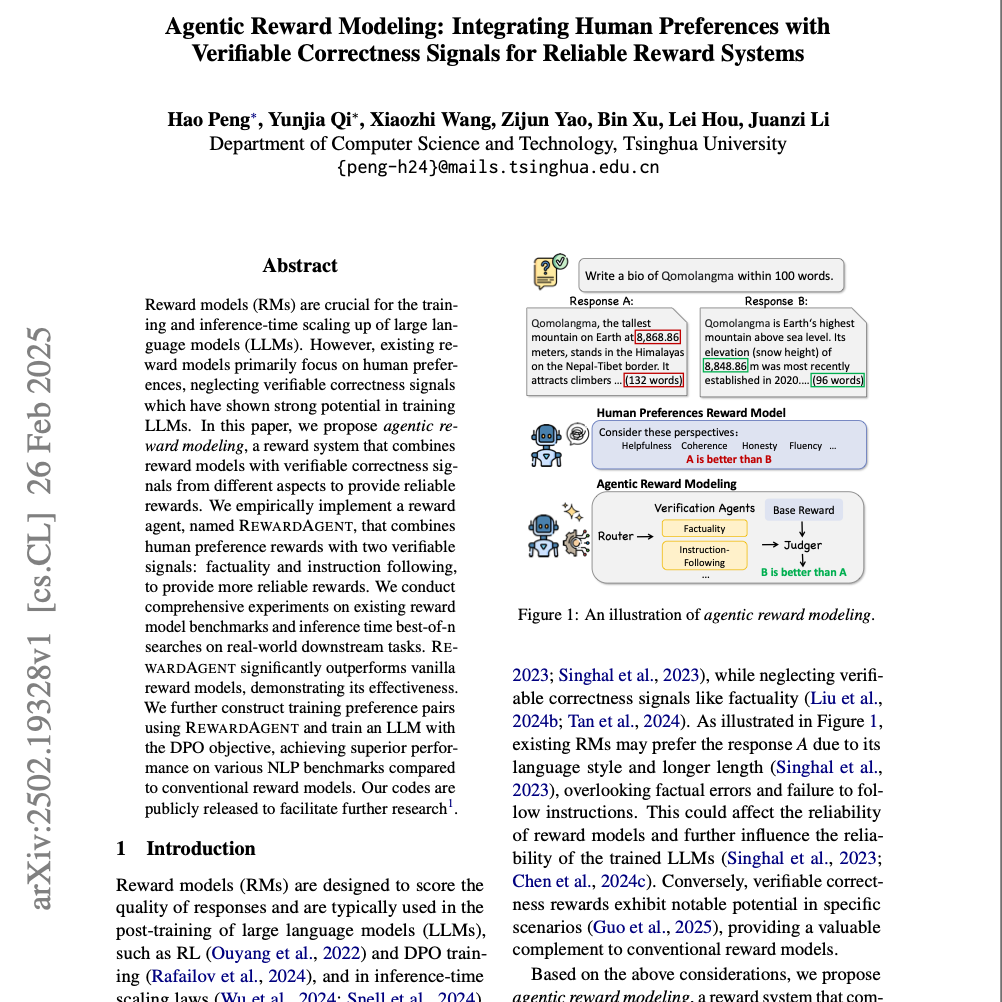
Seventy3:借助NotebookLM的能力进行论文解读,专注人工智能、大模型、机器人算法方向,让大家跟着AI一起进步。 今天的主题是: Agentic Reward Modeling: Integrating Human Preferences with Verifiable Correctness Signals for Reliable Reward Systems Summary 这项研究提出了“代理奖励建模”,一种结合了传统基于人类偏好奖励模型和可验证正确性信号的新型奖励系统。研究人员实现了一个名为 REWARDAGENT 的奖励代理,它集成了对事实性和指令遵循的可验证信号,以提供更可靠的奖励。通过在现有奖励模型基准、推理时最佳搜索以及构建训练偏好对方面的实验,结果表明 REWARDAGENT 显著优于仅依赖人类偏好的奖励模型。该框架通过纳入多维正确性信号来增强可靠性,并允许灵活集成不同的验证代理。 REWARDAGENT 的有效性在下游任务中得到了验证,并显示出其在提高语言模型性能方面的潜力,尤其是在需要事实准确性和严格遵循指令的场景中。这项工作鼓励进一步探索其他可验证的正确性信号,以开发更可靠的奖励系统,用于大型语言模型的开发和对齐。 原文链接:https://arxiv.org/abs/2502.19328 前往小宇宙评论区与主播互动
Embed this episode
No transcript yet.