
EPISODE · Oct 3, 2025 · 17 MIN
【第369期】大模型调优秘籍:半在线学习如何实现性能与效率双赢?
from Seventy3
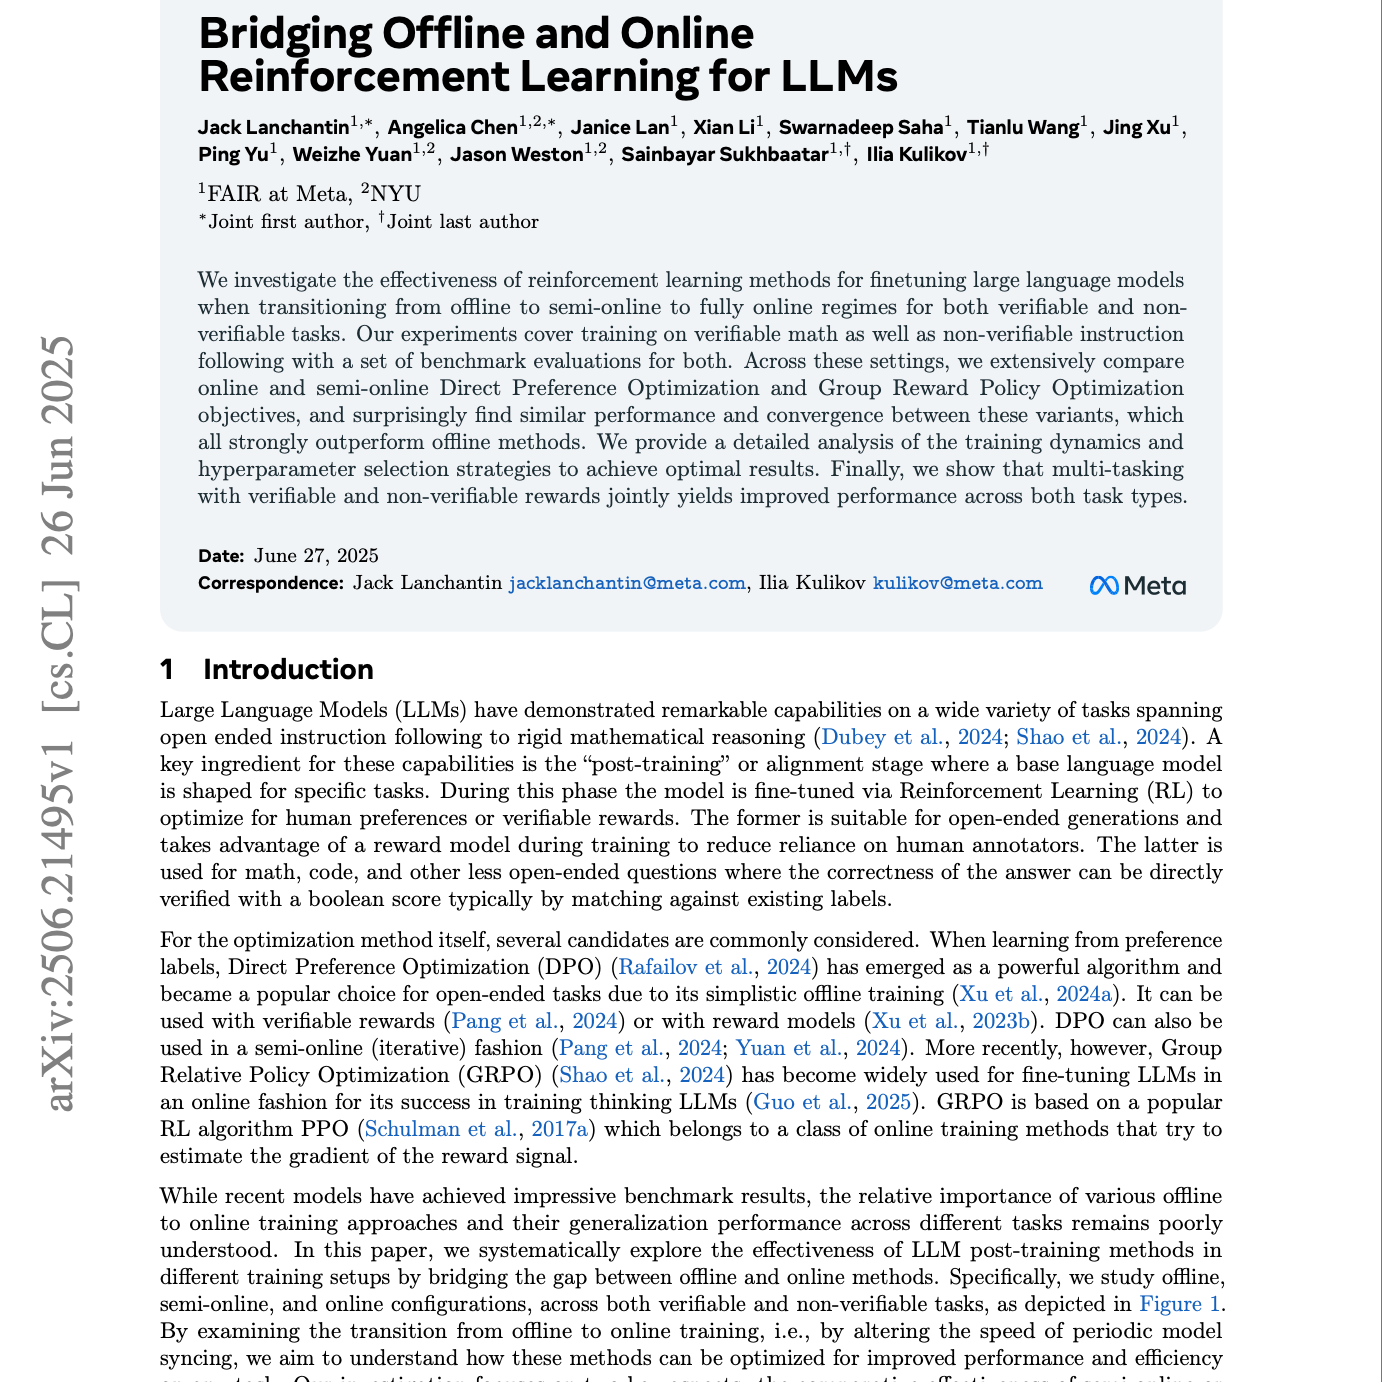
Seventy3:借助NotebookLM的能力进行论文解读,专注人工智能、大模型、机器人算法方向,让大家跟着AI一起进步。今天的主题是:Bridging Offline and Online Reinforcement Learning for LLMsSummary该来源对大型语言模型(LLMs)的强化学习微调方法进行了系统性研究,比较了离线、半在线和完全在线三种训练范式。研究探讨了直接偏好优化(DPO)和组相对策略优化(GRPO)这两种流行的优化目标在可验证(如数学)和不可验证(如指令遵循)任务上的有效性。出人意料的是,研究发现半在线和完全在线方法的表现相似,且都显著优于离线方法,这表明不一定需要完全在线的强化学习。此外,作者还展示了联合使用可验证和不可验证奖励进行多任务训练可以提升模型在两类任务上的整体性能。原文链接:https://arxiv.org/abs/2506.21495前往小宇宙评论区与主播互动
Embed this episode
Ready to play
【第369期】大模型调优秘籍:半在线学习如何实现性能与效率双赢?
0:00
17:16
1×
No transcript for this episode yet
Similar Episodes
No similar episodes found.
Similar Podcasts
No similar podcasts found.
Frequently Asked Questions
How long is this episode of Seventy3?
This episode is 17 minutes long.
When was this Seventy3 episode published?
This episode was published on October 3, 2025.
Can I download this Seventy3 episode?
Yes. Use the download control on the episode player to save the publisher-provided media file.
URL copied to clipboard!