
EPISODE · Feb 6, 2026 · 12 MIN
【第495期】Self-play SWE-RL:基于自我博弈的软件工程智能体强化学习
from Seventy3
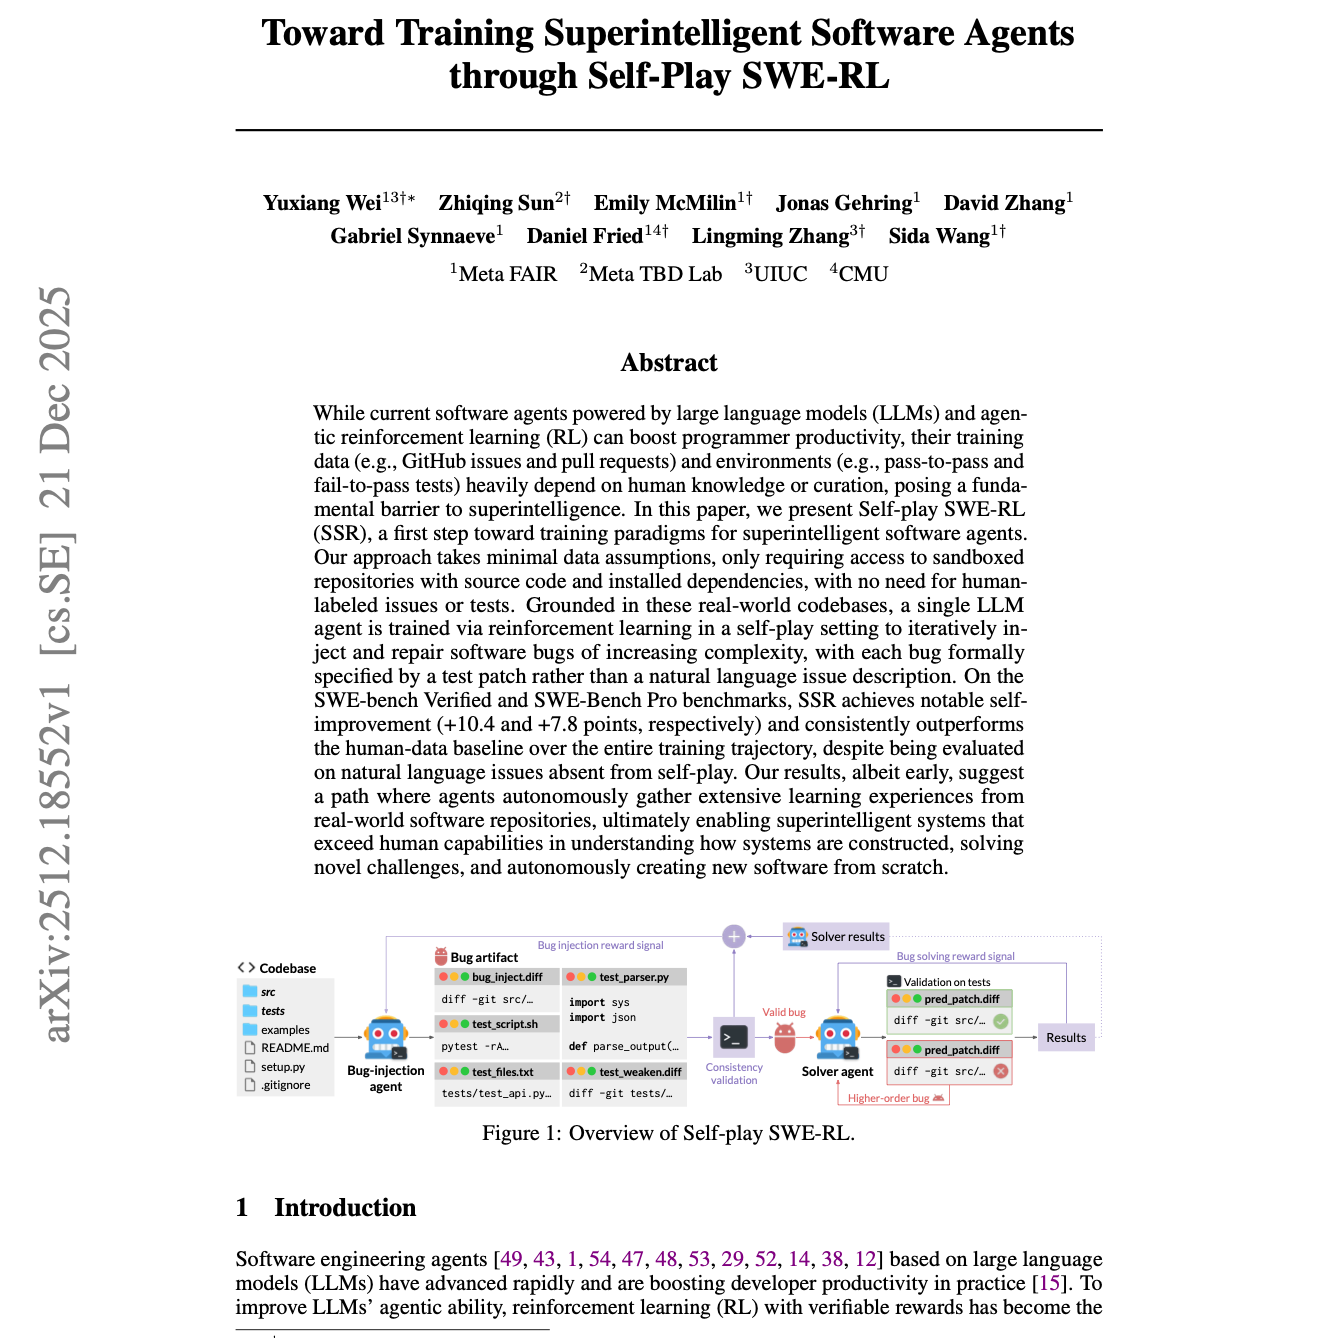
Seventy3:借助NotebookLM的能力进行论文解读,专注人工智能、大模型、机器人算法、crypto方向,让大家跟着AI一起进步。今天的主题是:Toward Training Superintelligent Software Agents through Self-Play SWE-RLSummary尽管当前基于大语言模型(LLMs)和智能体强化学习(agentic RL)的软件智能体能够提升程序员的生产力,但它们的训练数据(如 GitHub Issues 与 Pull Requests)和环境(如 pass-to-pass 与 fail-to-pass 测试)高度依赖人工知识或人工维护,这构成了迈向超级智能的根本障碍。本文提出 Self-play SWE-RL(SSR),作为面向超级智能软件智能体训练范式的第一步。该方法对数据几乎没有假设,仅需要访问带有源代码和已安装依赖的沙箱仓库,无需人工标注的 Issues 或测试用例。基于这些真实代码库,我们在**自我对弈(self-play)的设置下,通过强化学习训练单智能体 LLM,迭代地注入并修复日益复杂的软件缺陷,每个缺陷由测试补丁(test patch)**形式的正式规范定义,而非自然语言描述的 Issue。在 SWE-Bench Verified 与 SWE-Bench Pro 基准上,SSR 展现出显著的自我提升(分别为 +10.4 和 +7.8 分),并在整个训练过程中始终超越依赖人工数据的基线,即便评测使用的是自我对弈中未见的自然语言 Issues。尽管仍处于早期阶段,这些结果表明了一条可行路径:智能体能够自主从真实软件仓库中获取大量学习经验,从而最终实现超越人类能力的系统,包括理解系统构建方式、解决新颖挑战,以及自主从零创建新软件。原文链接:https://arxiv.org/abs/2512.18552前往小宇宙评论区与主播互动
Embed this episode
Ready to play
【第495期】Self-play SWE-RL:基于自我博弈的软件工程智能体强化学习
No transcript for this episode yet
Similar Episodes
No similar episodes found.
Similar Podcasts
No similar podcasts found.