
EPISODE · Jul 10, 2026 · 19 MIN
【第649期】编译智能体:将工作流写入大模型权重
from Seventy3
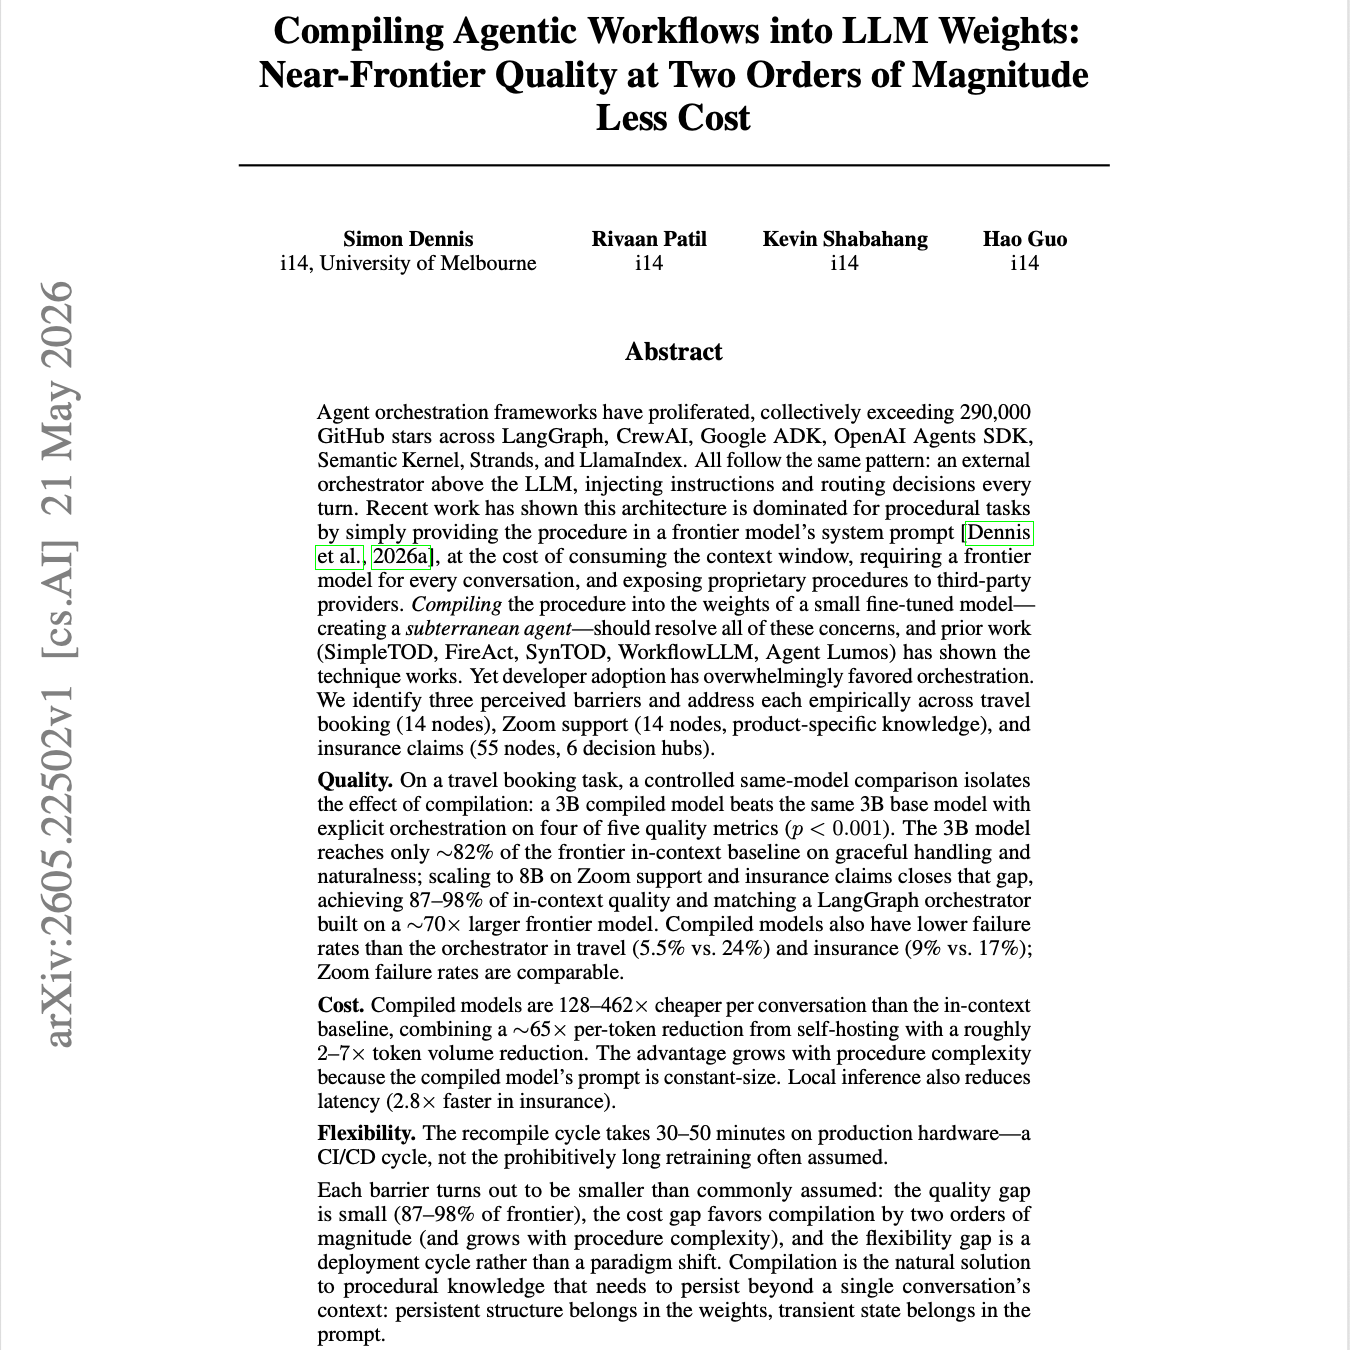
Seventy3:借助NotebookLM的能力进行论文解读,专注人工智能、大模型、机器人算法、crypto方向,让大家跟着AI一起进步。如果你想要解读自己的论文,获得更多曝光度。请联系小助手微信:seventy3_podcast 加群。合作邮箱:zhiwudazhanjiangshi#gmail.com今天的主题是:Compiling Agentic Workflows into LLM Weights: Near-Frontier Quality at Two Orders of Magnitude Less CostSummary智能体编排框架在近年来大量涌现,LangGraph、CrewAI、Google ADK、OpenAI Agents SDK、Semantic Kernel、Strands 和 LlamaIndex 等框架在 GitHub 上累计获得的星标(stars)已突破 290,000 个。所有这些框架都遵循同一种模式:在 LLM 之上设立一个外部编排器,在每一步(turn)中注入指令并做出路由决策。近期的研究表明,对于程序化任务而言,这种架构的性能会被一种更简单的方法所压倒:即直接将操作程序写入尖端模型(frontier model)的系统提示词中 [Dennis et al., 2026a];但这需要付出代价——它会消耗上下文窗口、每次对话都需要调用尖端模型,并且会将专有操作程序暴露给第三方供应商。将程序编译到经过微调的小型模型的权重中——从而创建一个“隐形智能体”(subterranean agent)——应该能解决所有这些问题,且先前的研究(SimpleTOD、FireAct、SynTOD、WorkflowLLM、Agent Lumos)已经证实了该技术的可行性。然而,开发者的采纳态度却压倒性地偏向于编排框架。我们识别出了三个普遍认知的障碍,并通过在机票酒店预订(14 个节点)、Zoom 技术支持(14 个节点,包含特定产品知识)以及保险理赔(55 个节点,6 个决策中心)三个场景中的实证研究,对它们逐一进行了解决。原文链接:https://arxiv.org/abs/2605.22502前往小宇宙评论区与主播互动
Embed this episode
Ready to play
【第649期】编译智能体:将工作流写入大模型权重
No transcript for this episode yet
Similar Episodes
No similar episodes found.
Similar Podcasts
No similar podcasts found.