【第77期】VisVM:Vision Value Model
from Seventy3
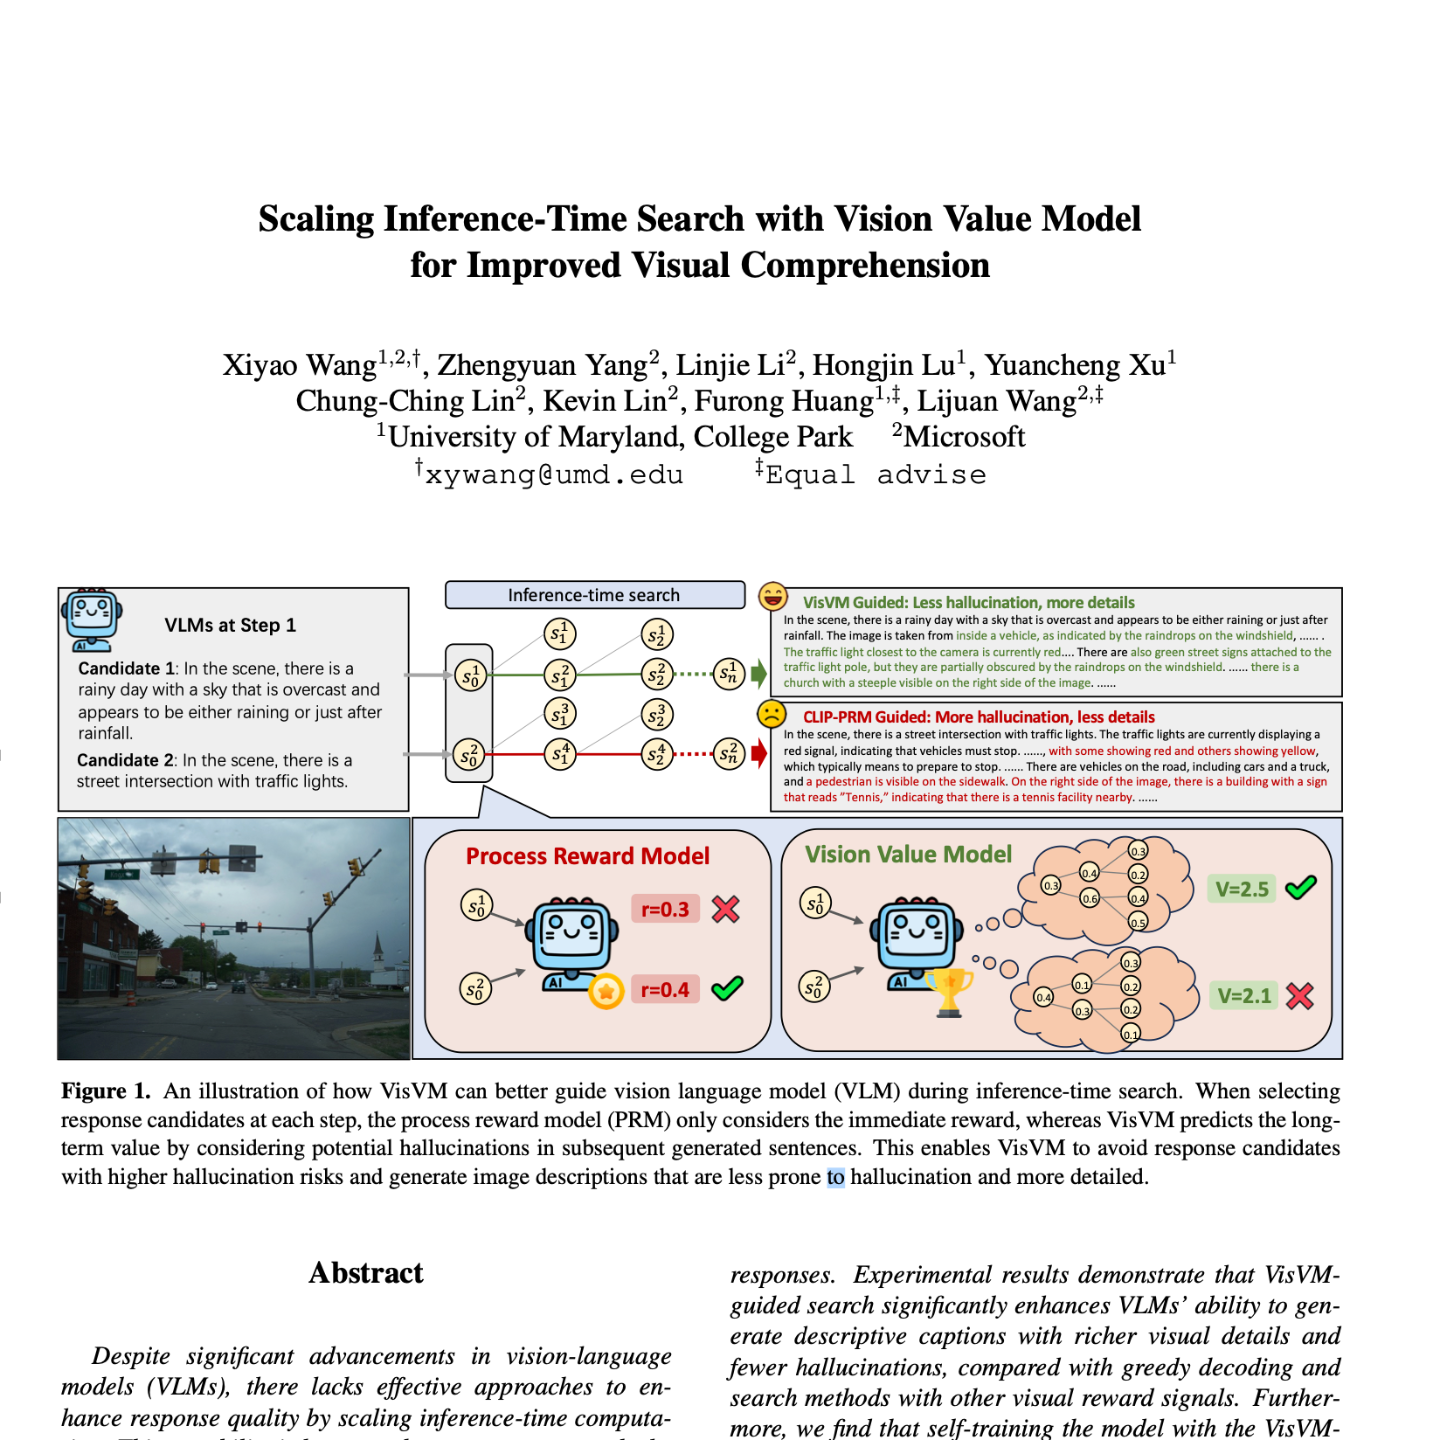
Seventy3: 用NotebookLM将论文生成播客,让大家跟着AI一起进步。 今天的主题是: Scaling Inference-Time Search with Vision Value Model for Improved Visual Comprehension Summary This research paper introduces the Vision Value Model (VisVM), a novel approach to improve the visual comprehension of vision-language models (VLMs). VisVM guides inference-time search in VLMs by predicting the long-term value of generated sentences, reducing hallucinations and increasing detail in image descriptions. Experiments demonstrate that VisVM-guided search outperforms other methods, and that using VisVM-generated captions for self-training further enhances VLM performance across multiple benchmarks. The researchers conclude that VisVM offers a promising path toward creating self-improving VLMs. The model and code are publicly available. 原文链接:https://arxiv.org/abs/2412.03704 前往小宇宙评论区与主播互动
Embed this episode
No transcript yet.