
EPISODE · Oct 8, 2026 · 23 MIN
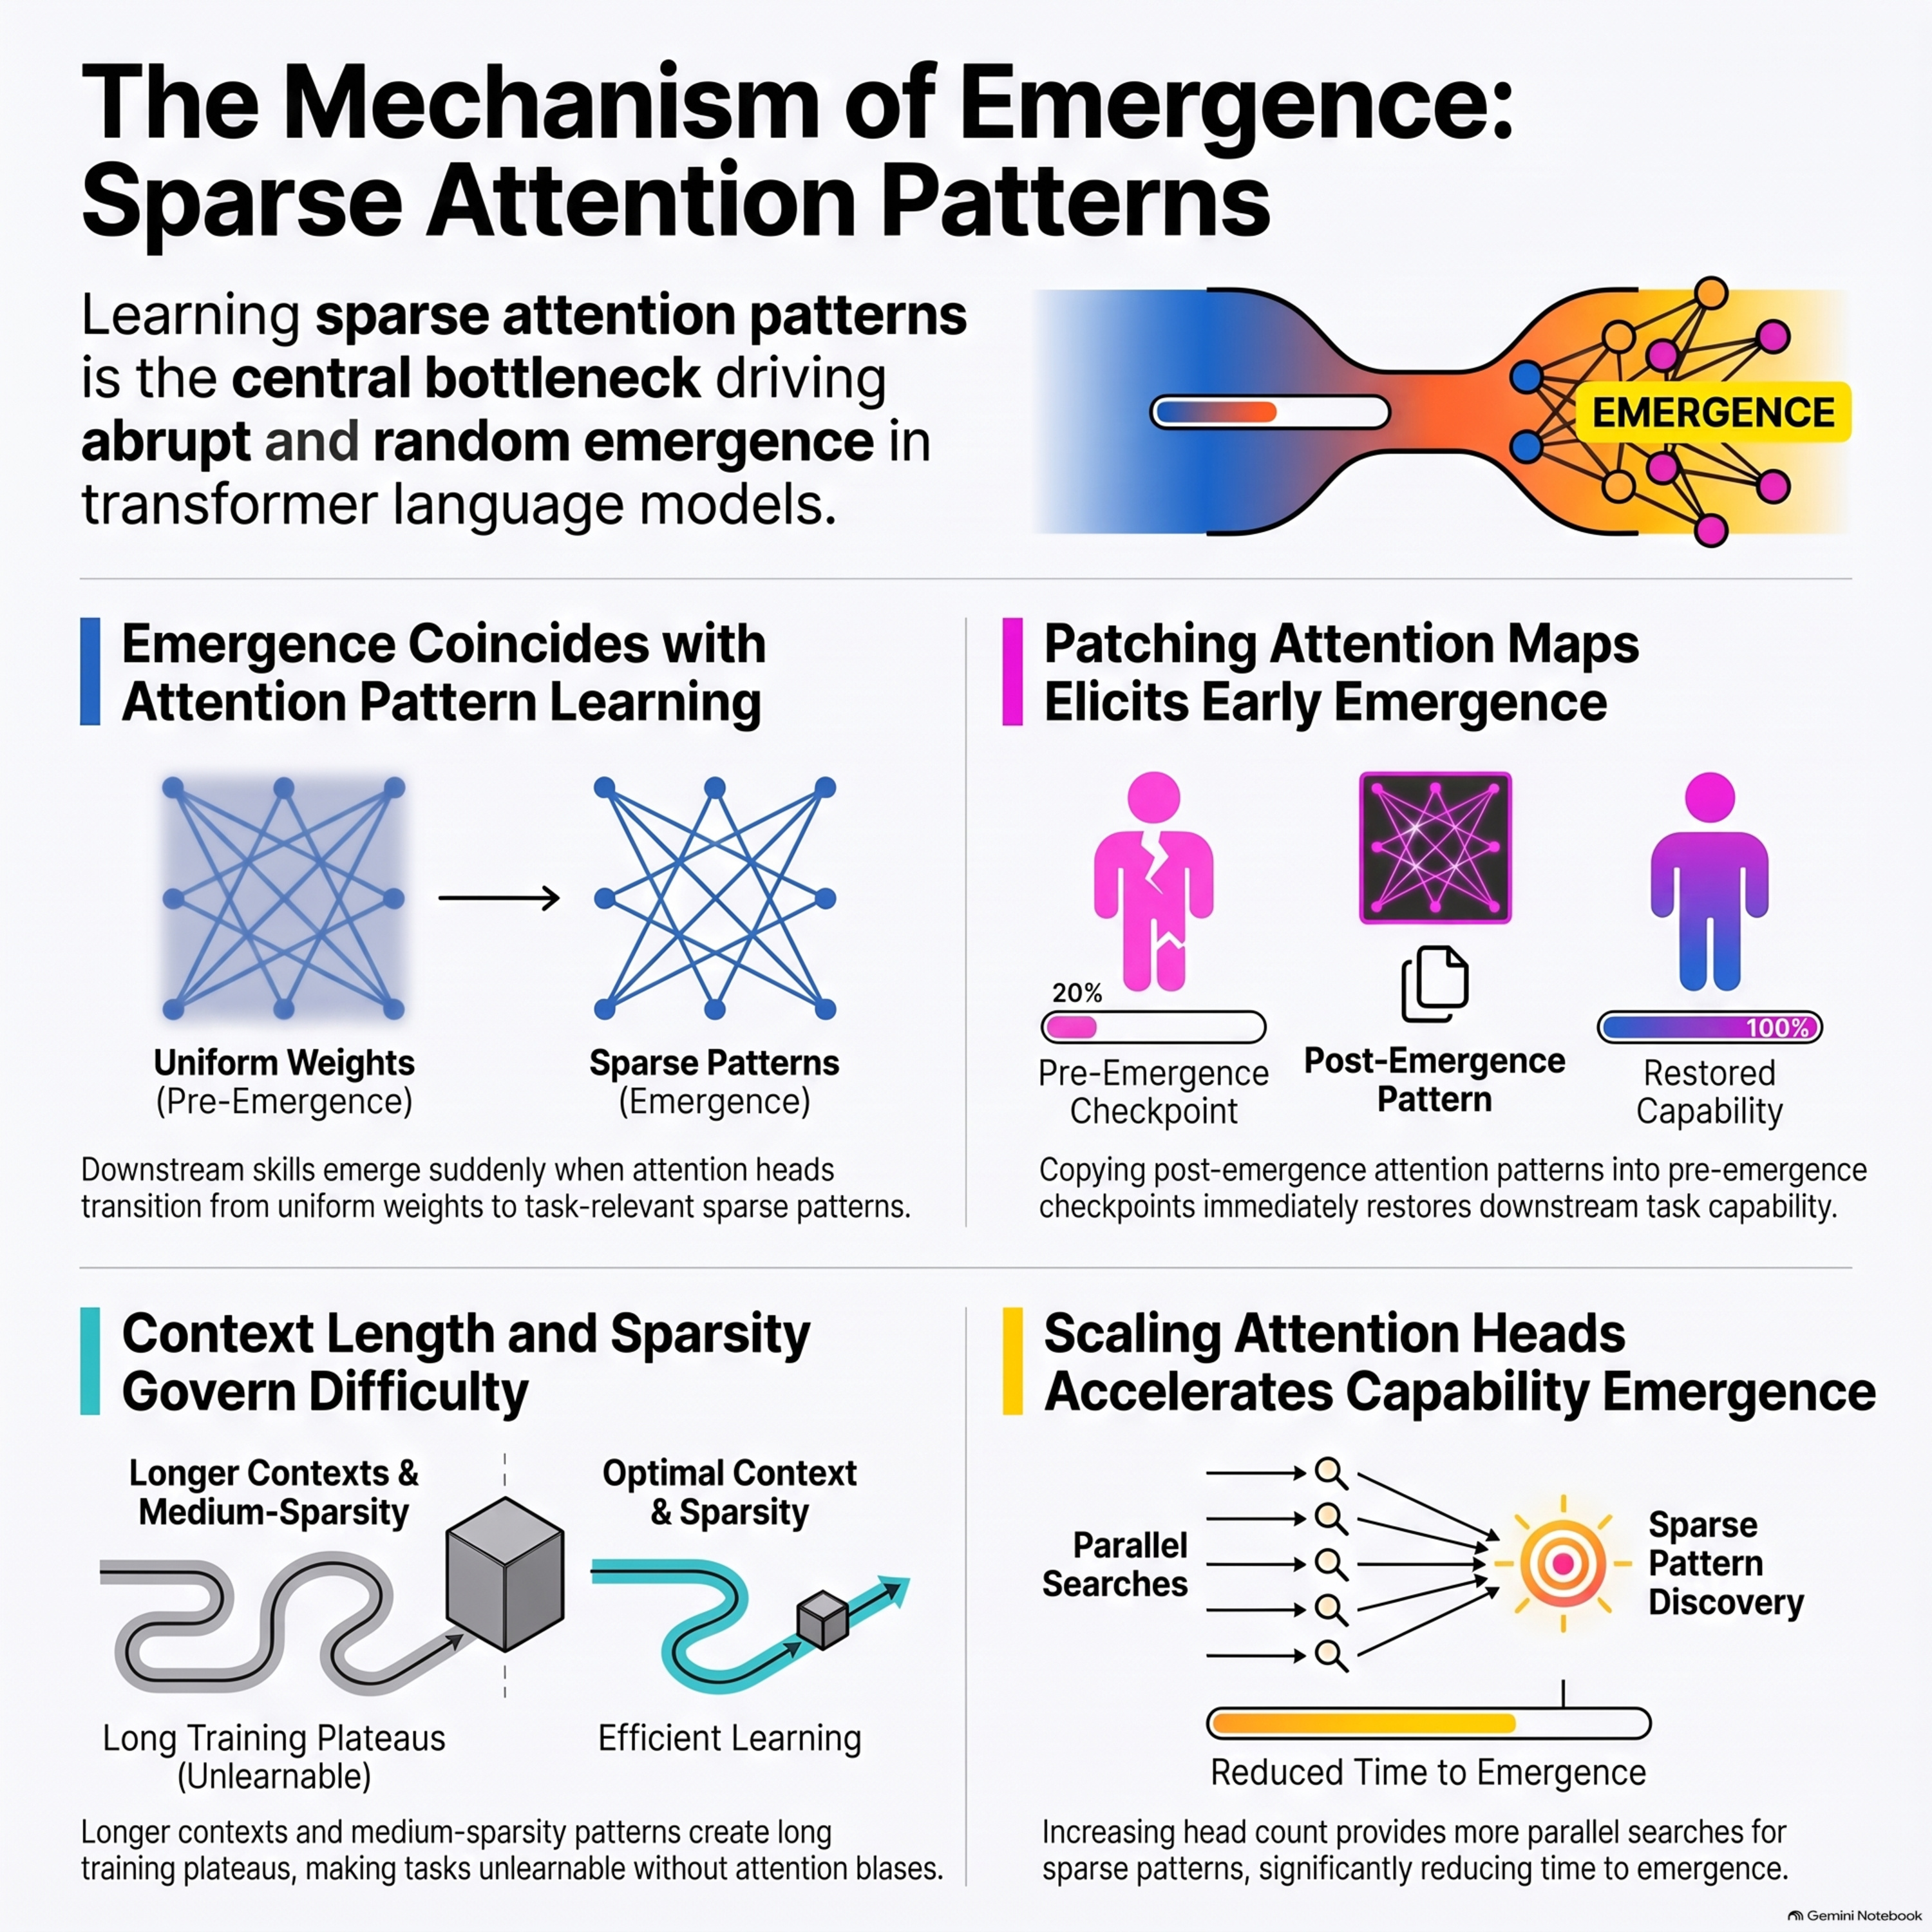
Emergent Capabilities Arise Randomly from Learning Sparse Attention Patterns
from Best AI papers explained · host Enoch H. Kang
This paper investigates why transformer language models display sudden, emergent capabilities during training by analyzing how they learn attention patterns. Through experiments on both real language models and synthetic tasks like linear maps and cellular automata, the authors demonstrate that acquiring downstream skills correlates with the abrupt mastery of sparse attention mechanisms. Furthermore, the study reveals that larger models overcome this learning bottleneck earlier because they acquire these essential attention maps more efficiently. The research also shows that activation patching can artificially trigger these capabilities at earlier training checkpoints, highlighting the crucial role that attention heads play in model performance.
Embed this episode
Ready to play
Emergent Capabilities Arise Randomly from Learning Sparse Attention Patterns
No transcript for this episode yet
Similar Episodes
No similar episodes found.