End-to-End Test-Time Training for Long Context
from Best AI papers explained Hosted by Enoch H. Kang
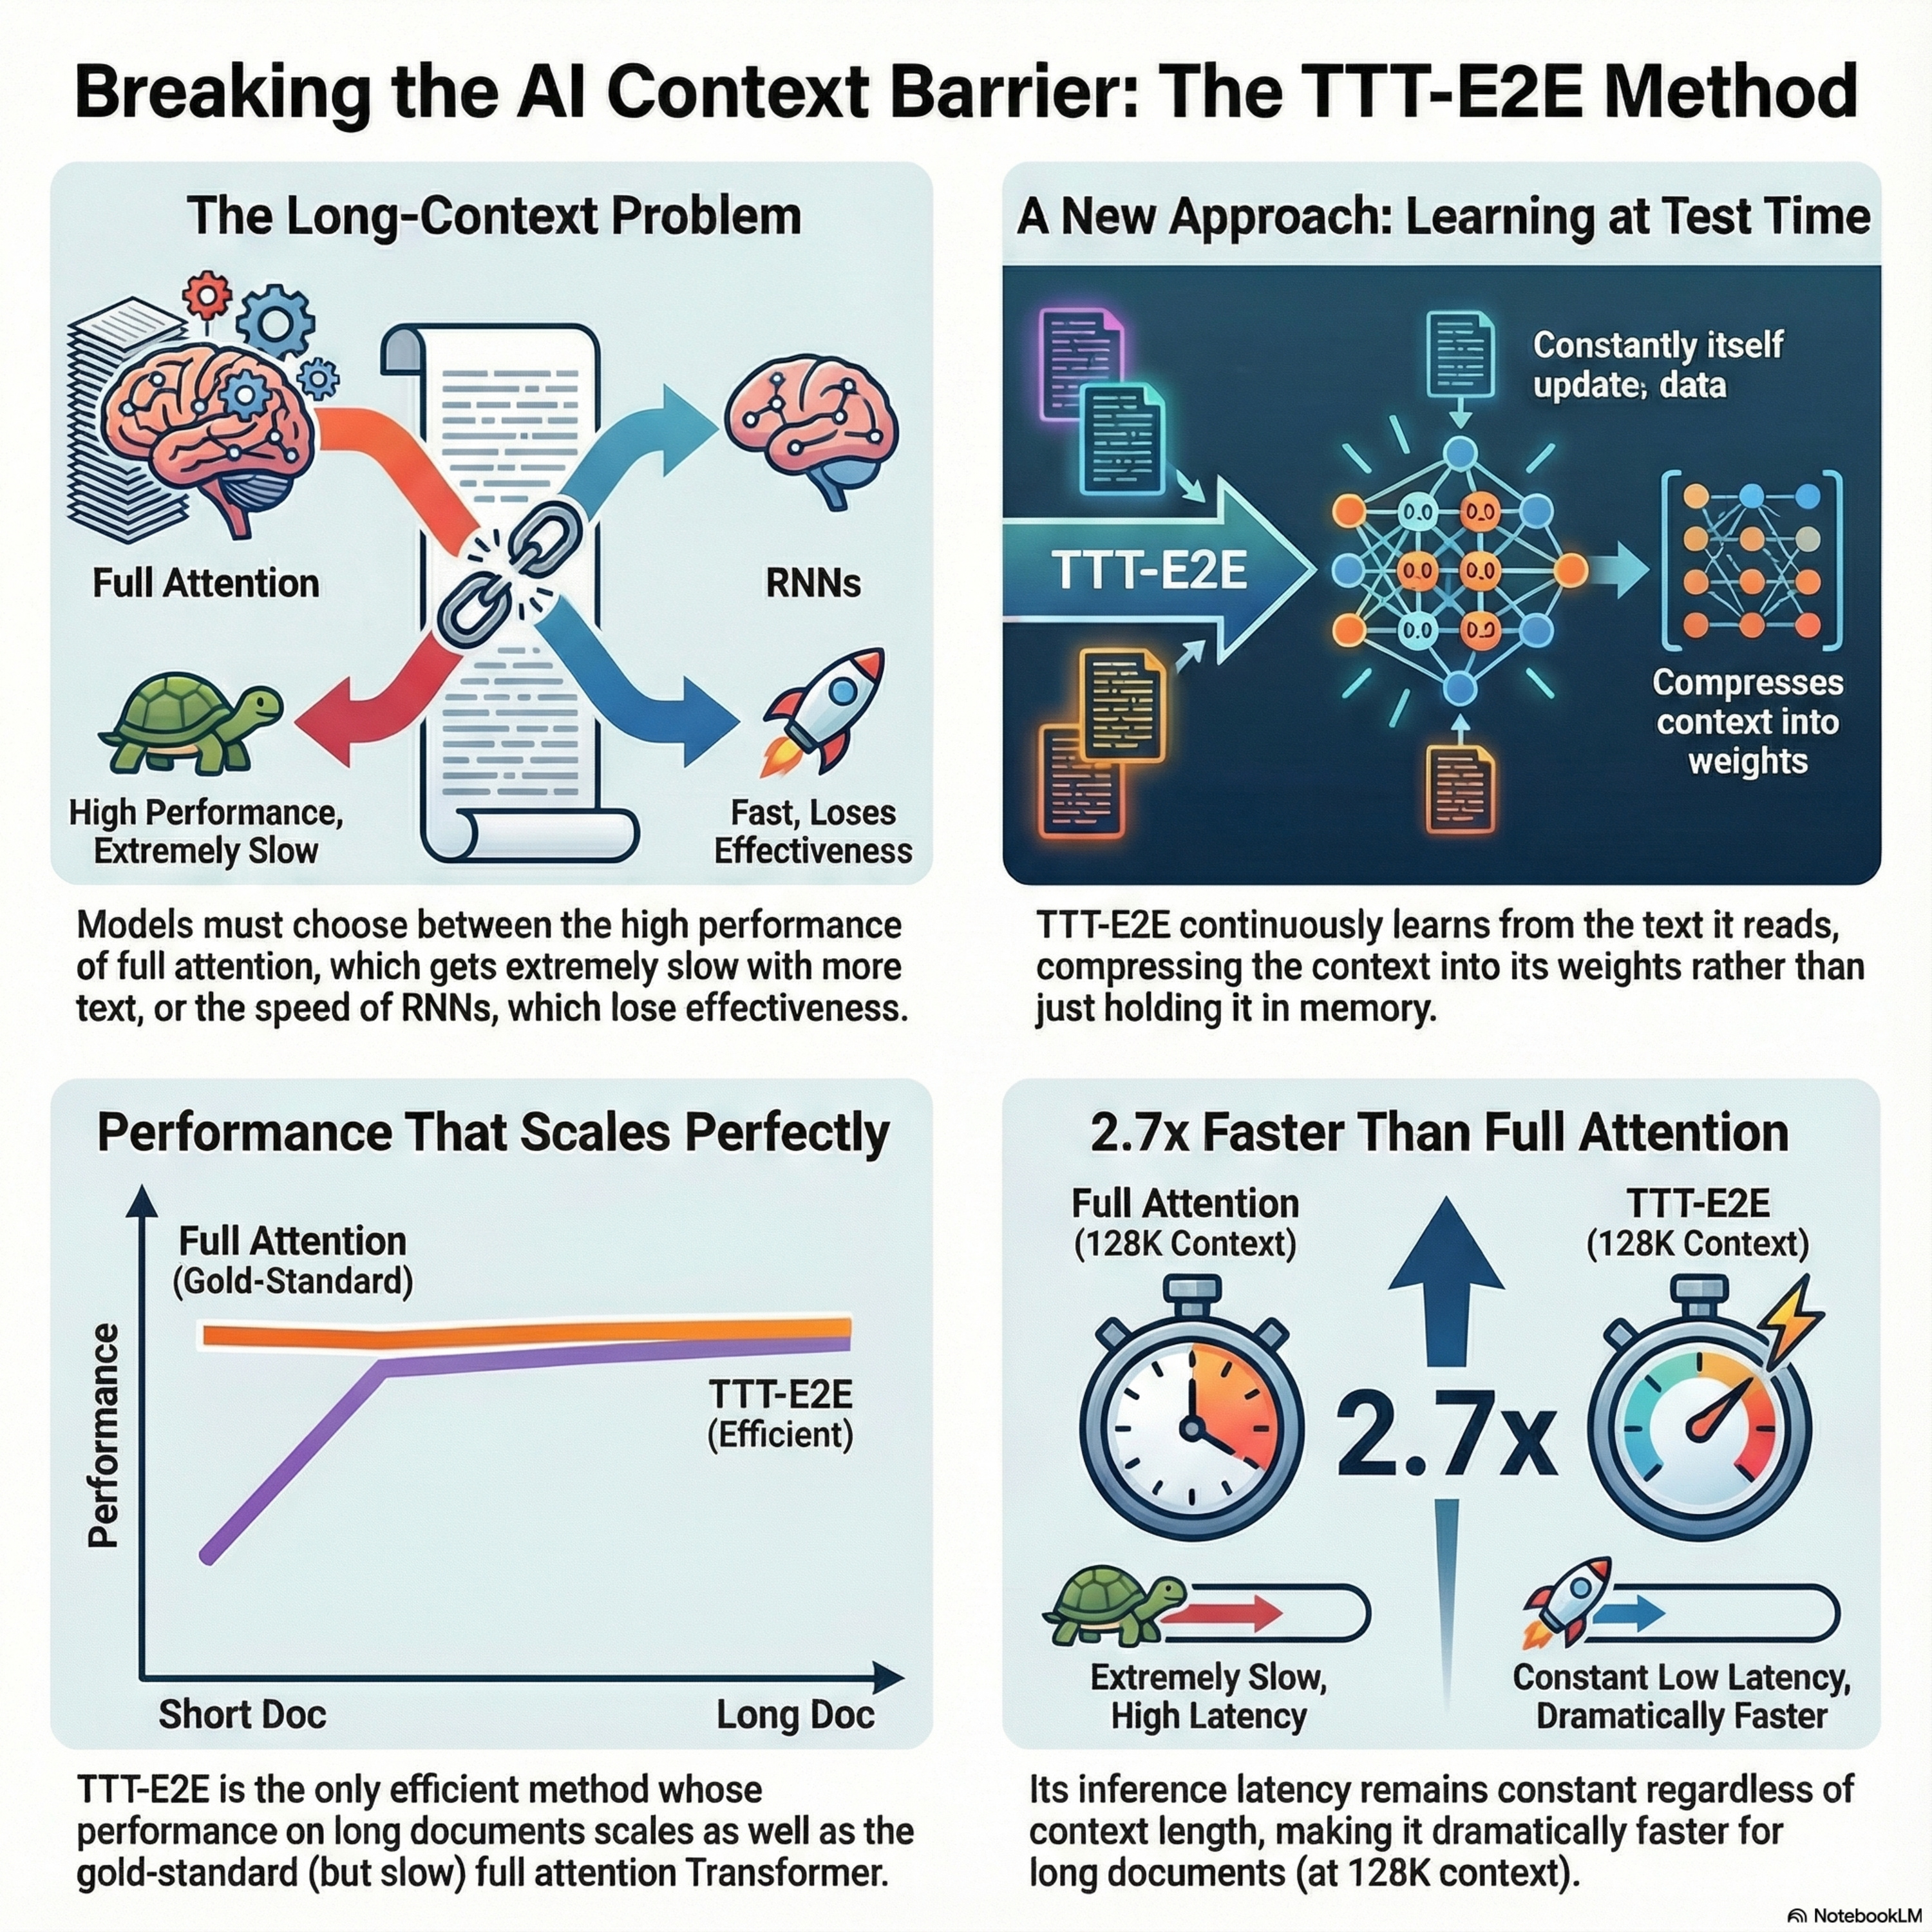
This research introduces TTT-E2E, a novel method for long-context language modeling that treats the task as a continual learning challenge rather than an architectural redesign. Unlike standard Transformers that struggle with the high computational cost of processing vast amounts of data, this model **compresses context into its weights** by learning at test time via next-token prediction. By integrating **meta-learning during training**, the system is optimized to initialize effectively for these **test-time updates**, ensuring the model improves as it reads more information. The authors demonstrate that while traditional RNNs and hybrid models lose effectiveness in very long contexts, **TTT-E2E scales performance** similarly to full-attention Transformers while maintaining the **constant inference speed** of an RNN. Ultimately, the method achieves significant efficiency gains, running **2.7 times faster** than standard models at a 128K context length while achieving superior language modeling accuracy.
Embed this episode
No transcript yet.