
EPISODE · Jun 8, 2026 · 30 MIN
Ep.09. The Sound of Thought
from Latent State · host Shengbin Cui
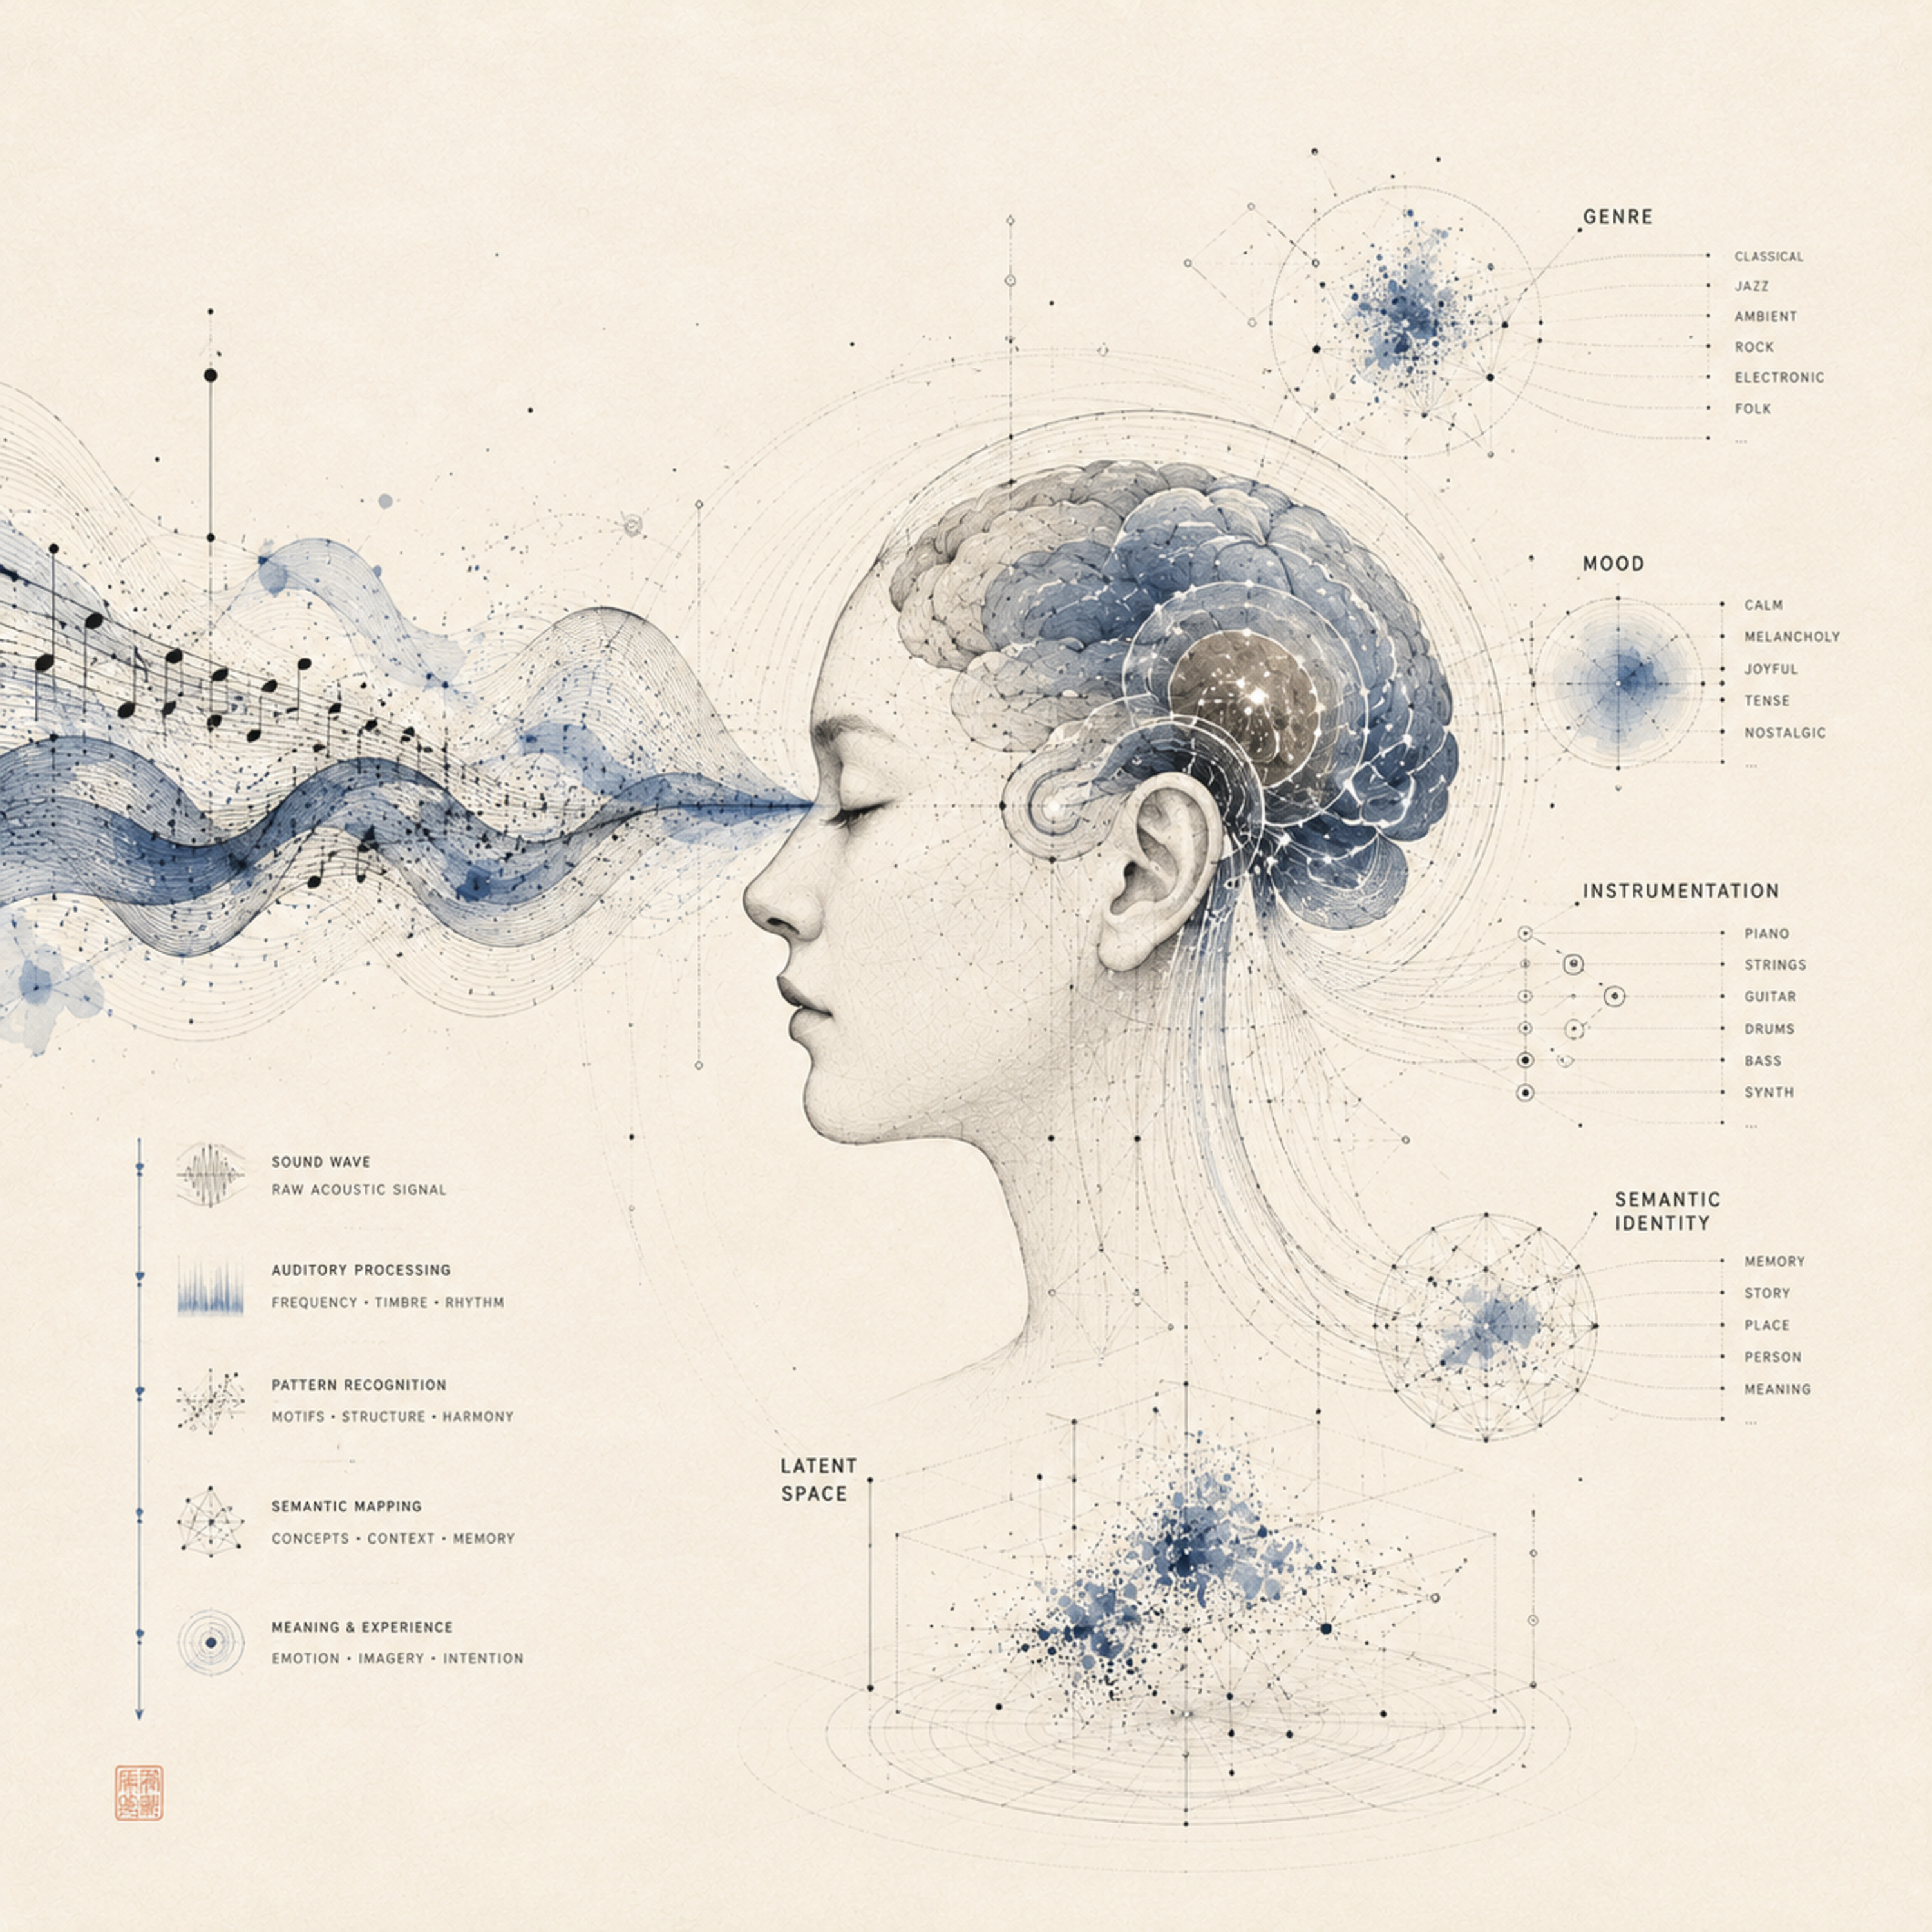
PaperDenk, T. I., Takagi, Y., Matsuyama, T., Agostinelli, A., Nakai, T., Frank, C., & Nishimoto, S. Text-to-music generation models capture musical semantic representations in the human brain. Nature Communications.One-sentence summaryA NeuroAI study shows that music-generation models can help reveal how the human auditory cortex represents musical meaning, linking music, language, and brain activity through shared semantic structure.Key ideasThe study used fMRI while participants listened to short music clips.The researchers predicted high-level music embeddings from brain activity.MusicLM generated new music from those predicted embeddings.The reconstructions preserved genre, mood, and instrumentation better than fine timing.Human raters matched reconstructed music to original music roughly three out of four times.Beats per minute were not recovered well.Music-derived and text-derived representations predicted overlapping auditory-cortex regions.The results suggest musical semantics are centered on auditory cortices, but not exclusive to them.The study shows functional correspondence, not mechanistic equivalence.Important cautionThis is not “AI reads music from the brain” in a literal sense.The method does not reconstruct the exact song or the full musical experience. It reconstructs high-level musical semantics: the kind of music, not the precise temporal unfolding.
Embed this episode
Ready to play
Ep.09. The Sound of Thought
No transcript for this episode yet
Similar Episodes
No similar episodes found.
Similar Podcasts
No similar podcasts found.