Fast KV Compaction via Attention Matching
from Best AI papers explained Hosted by Enoch H. Kang
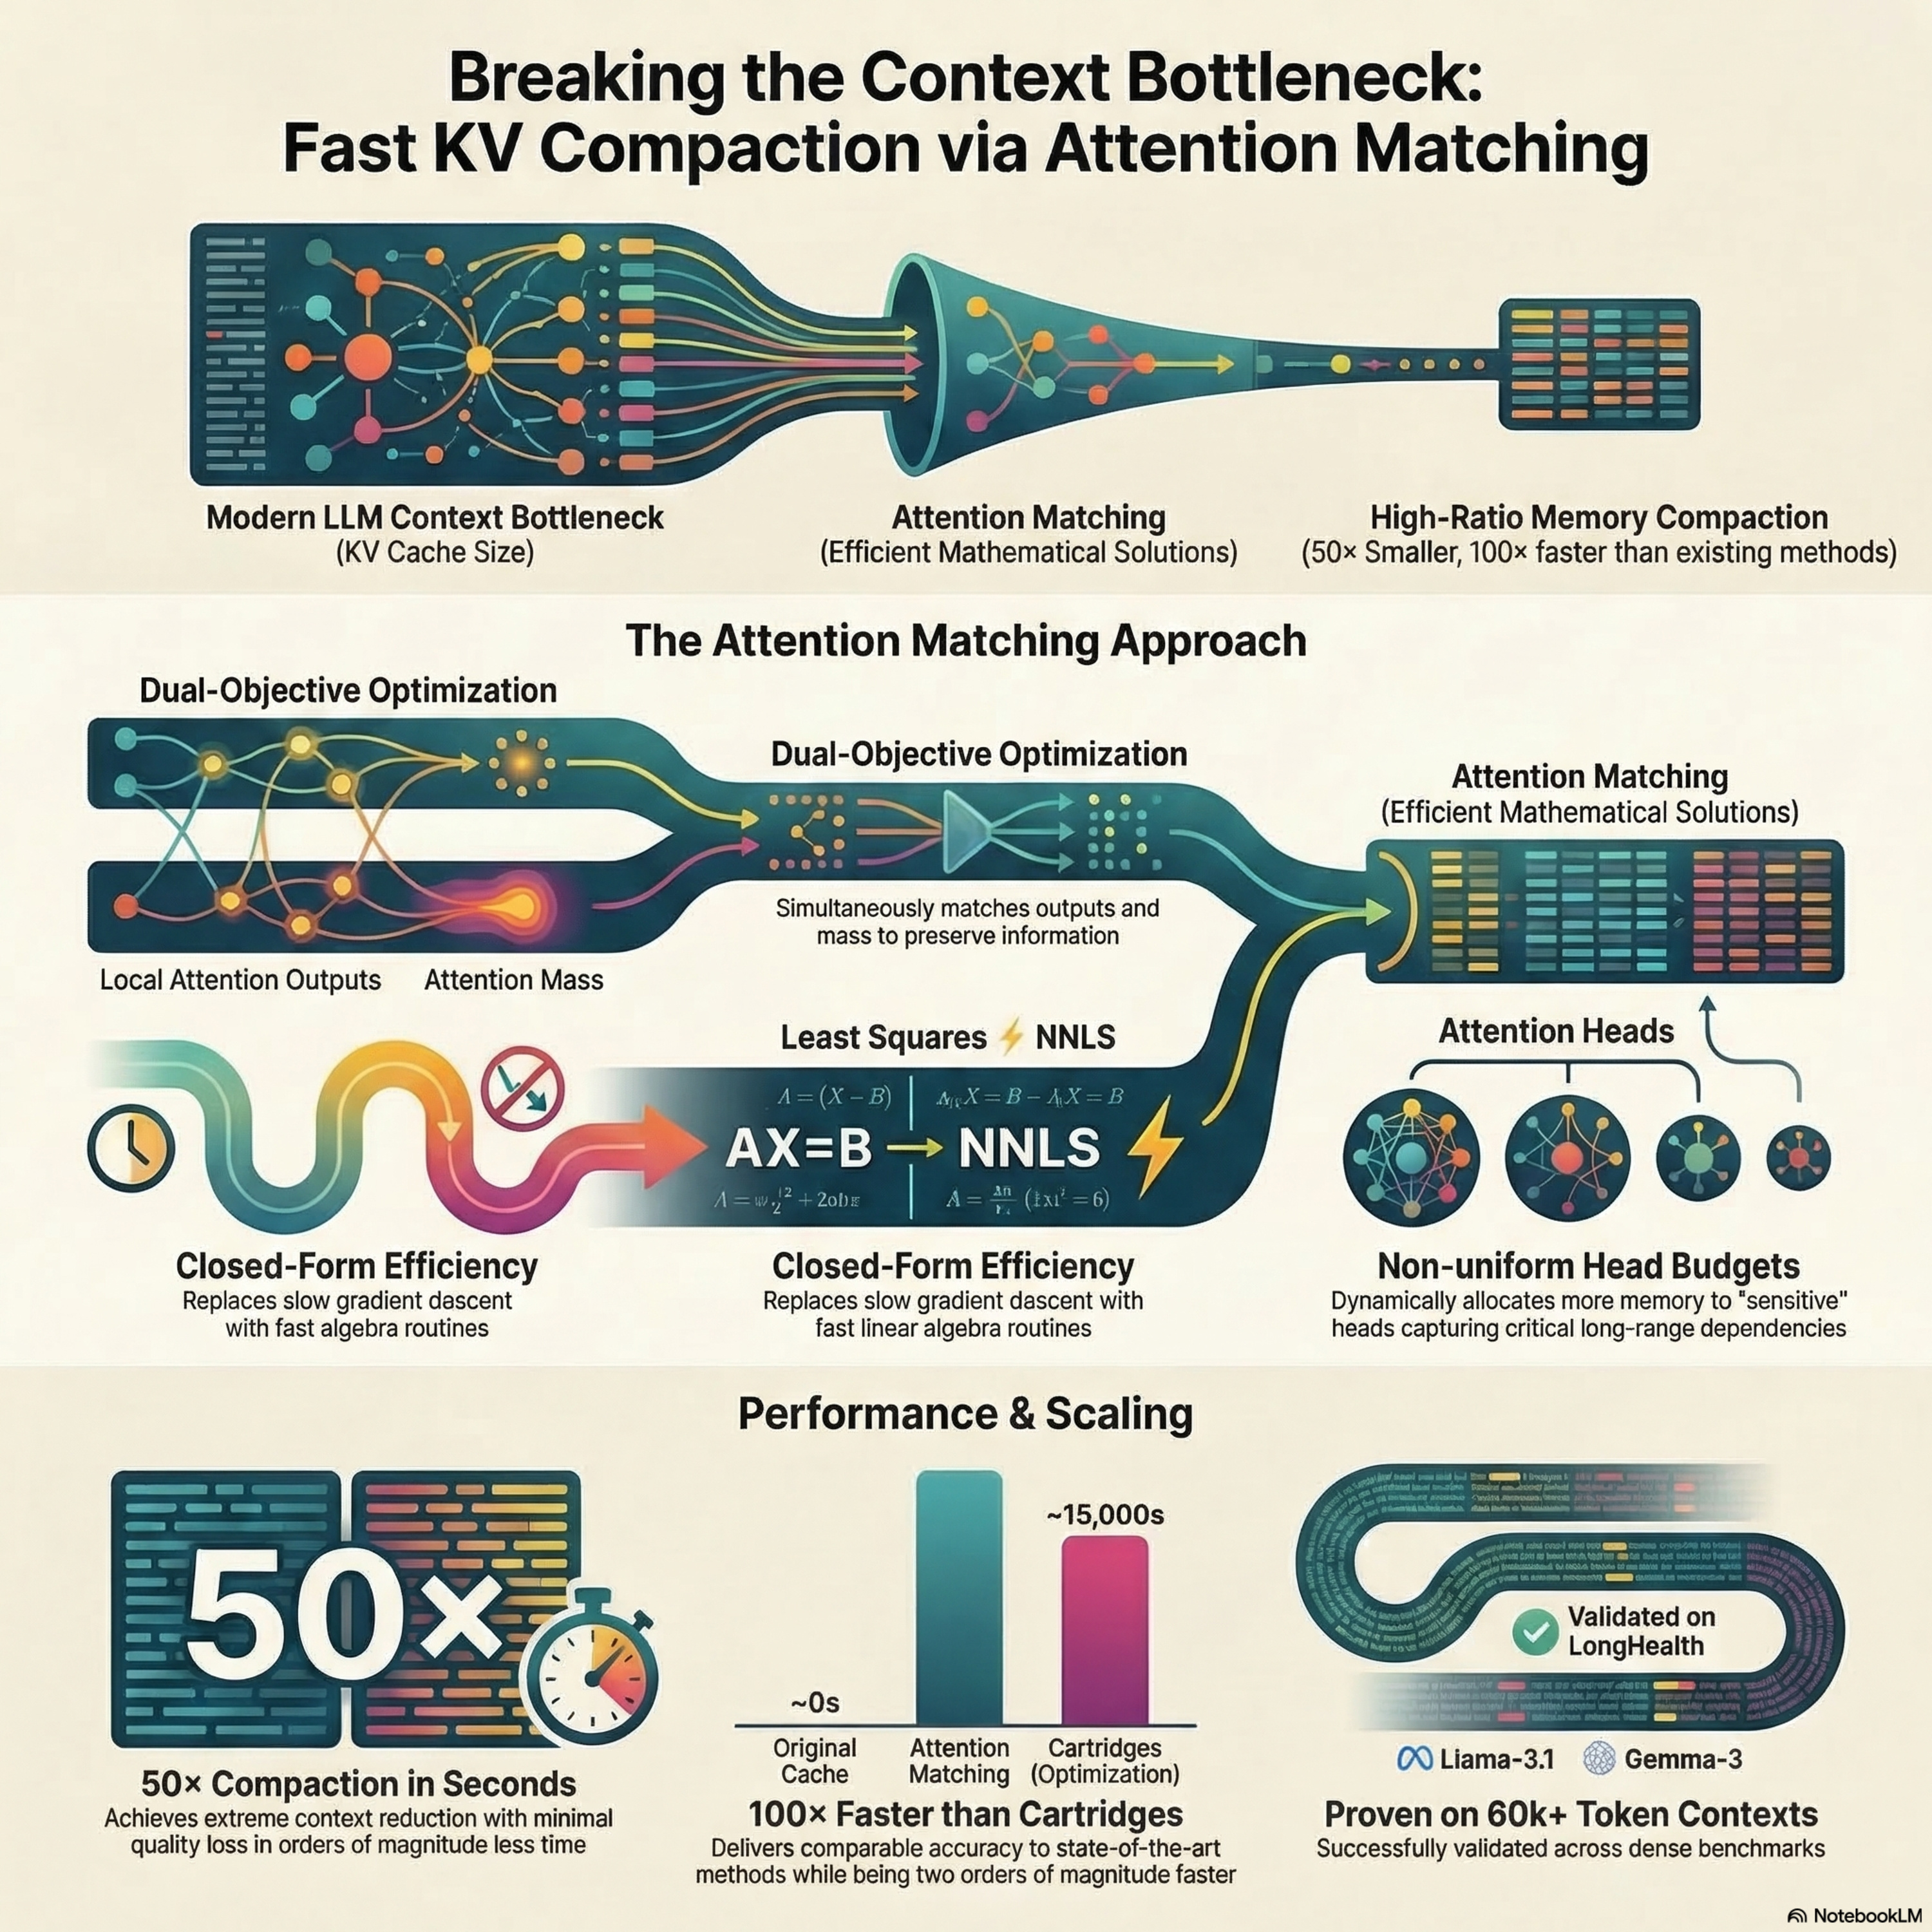
This paper introduces Attention Matching (AM), a novel framework for fast and efficient key-value (KV) cache compaction in long-context language models. As models process longer sequences, the memory required for the KV cache becomes a major bottleneck, often necessitating lossy strategies like summarization or token eviction. The researchers propose optimizing compact keys and values to reproduce the original model's attention outputs and attention mass across every layer. This method achieves up to 50× compaction in seconds, significantly outperforming traditional token-dropping baselines and matching the quality of expensive gradient-based optimization. By incorporating nonuniform head budgets and scalar attention biases, AM maintains high downstream accuracy on complex reasoning tasks while remaining compatible with existing inference engines. Their findings suggest that latent-space compaction is a powerful primitive for managing the memory demands of modern generative AI.
Embed this episode
No transcript yet.