
EPISODE · Dec 13, 2024 · 12 MIN
FLAVA: A Foundational Language And Vision Alignment Model
from KnowledgeDB.ai · host KnowledgeDB
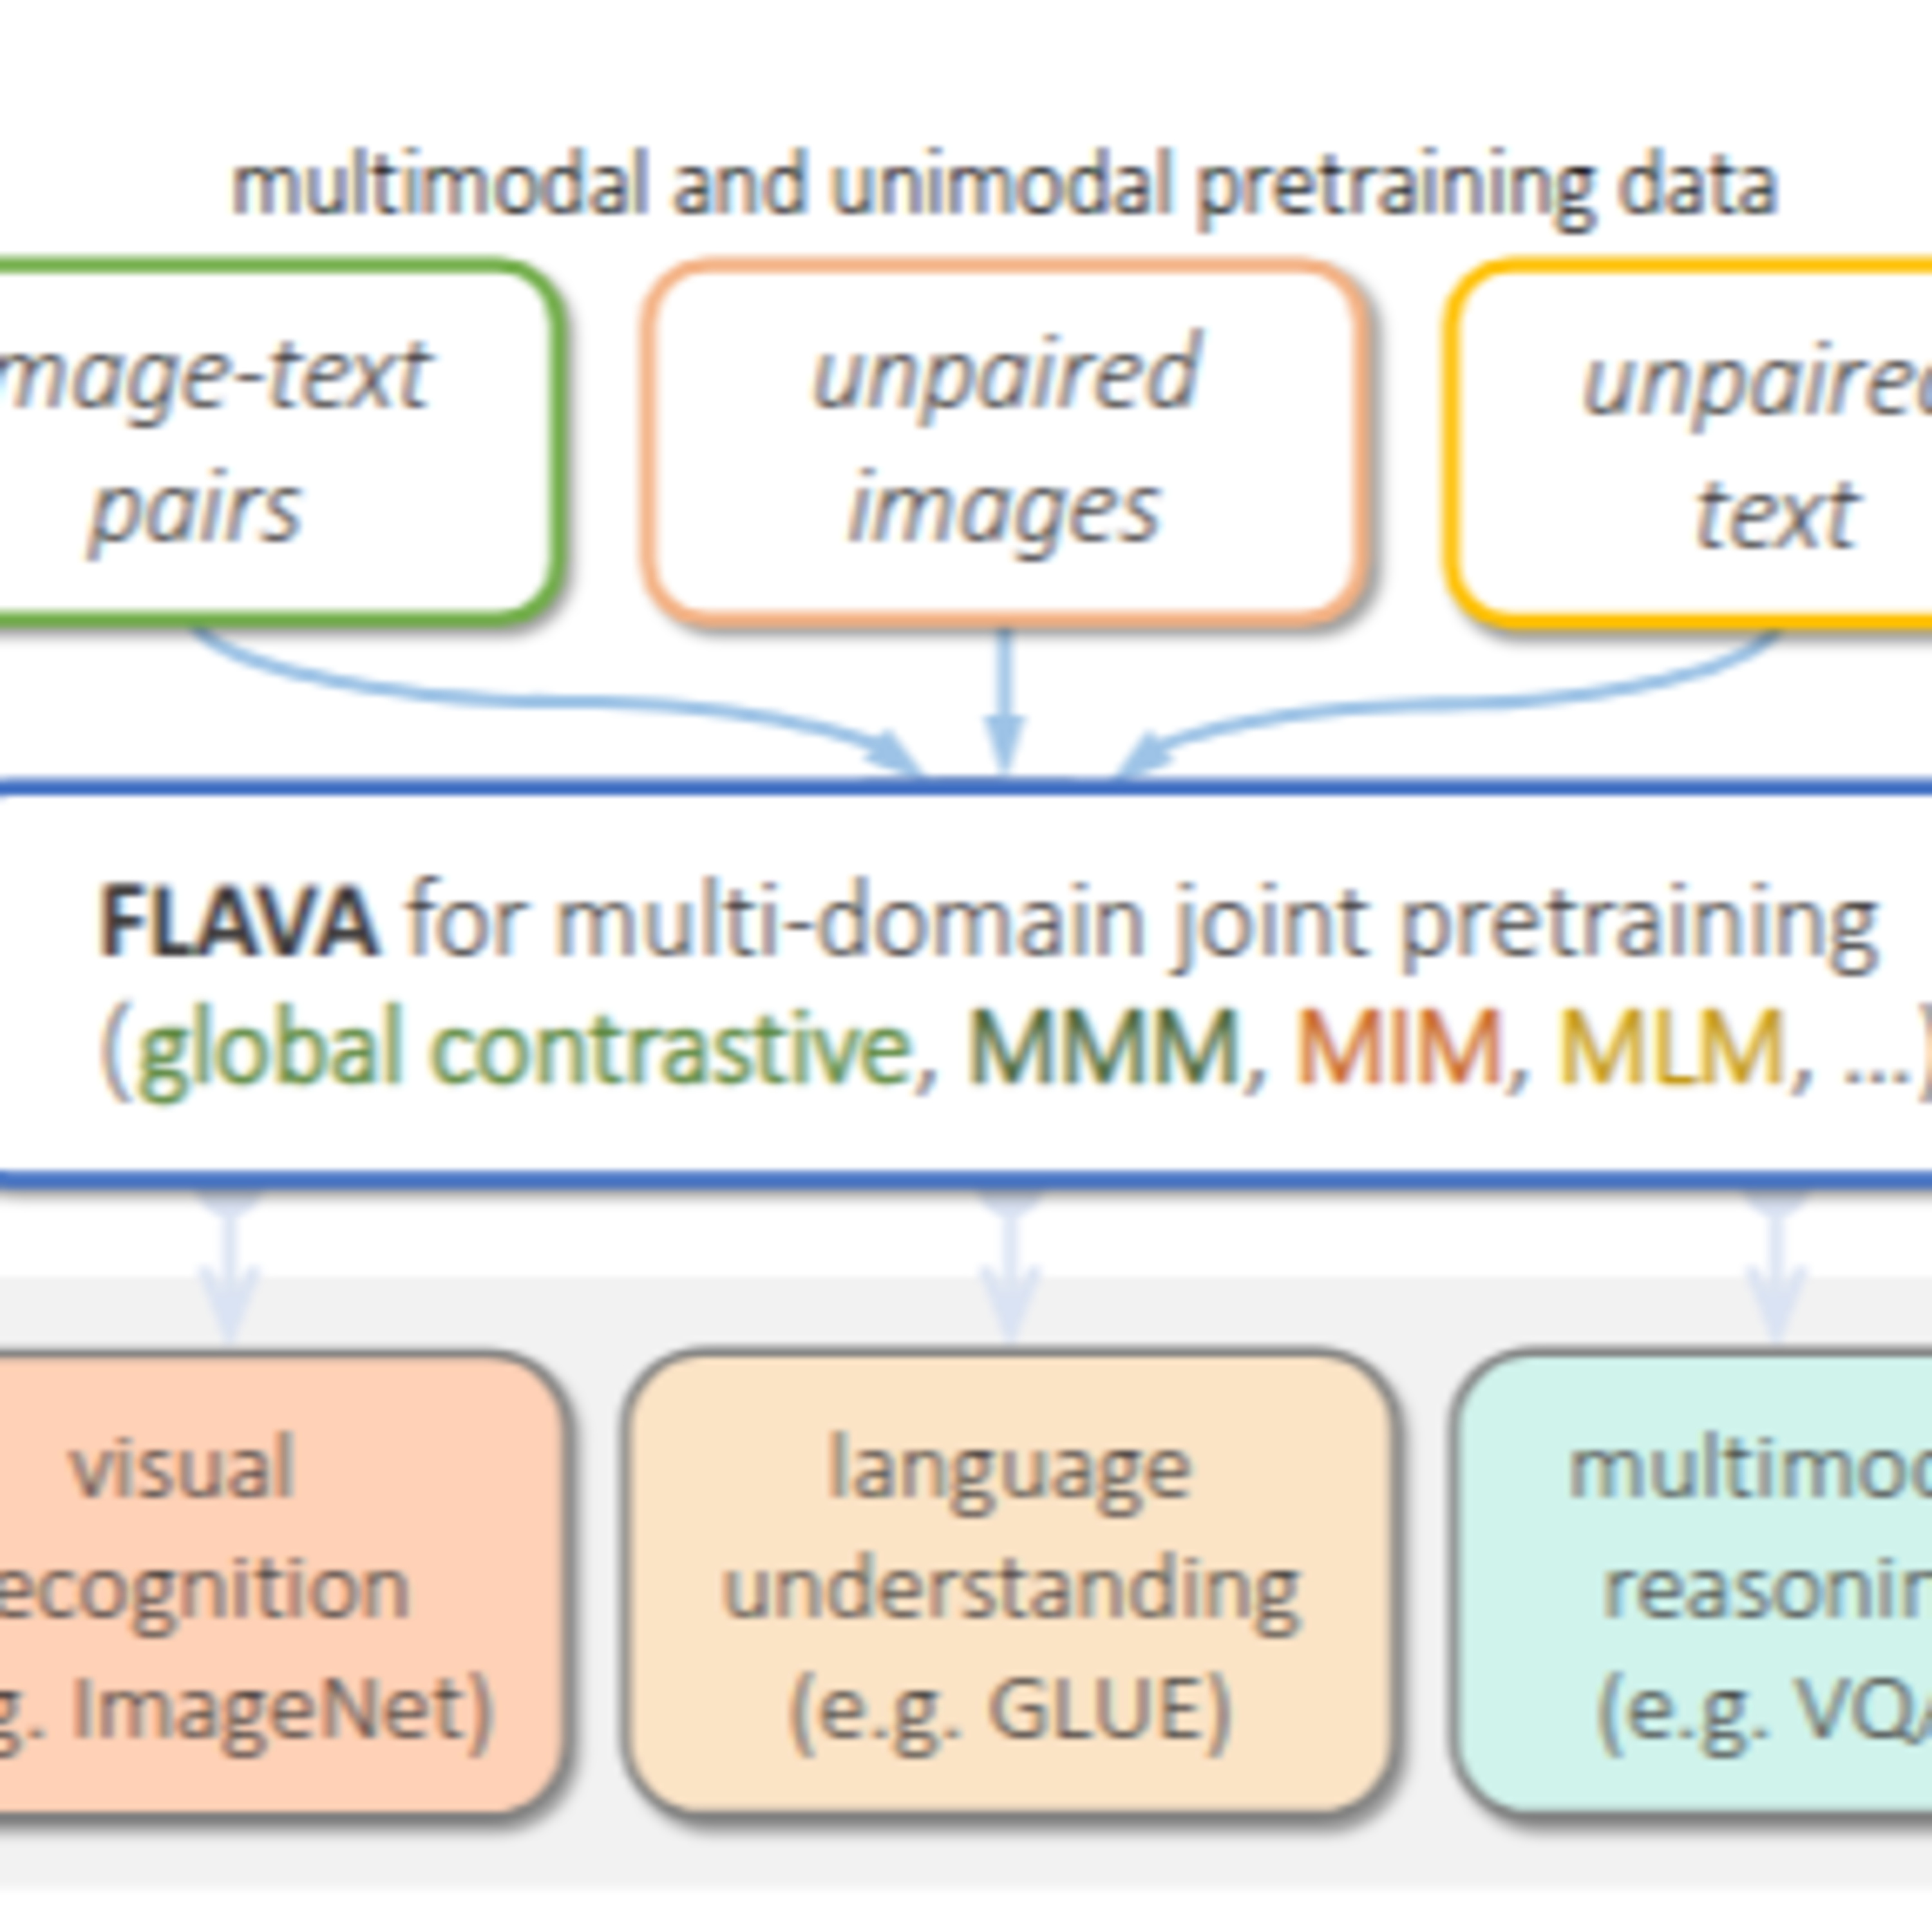
Ref: https://arxiv.org/abs/2112.04482 The document introduces FLAVA, a foundational vision and language model that excels in vision, language, and multimodal tasks. Unlike previous models often focusing on specific modalities or employing either contrastive or multi-modal approaches but not both, FLAVA uses a unified transformer architecture and a novel pretraining scheme. This scheme leverages both unimodal (images and text) and multimodal (image-text pairs) data, achieving impressive performance across 35 tasks despite using significantly less data than comparable models. The authors' open-source approach promotes reproducibility and future research. FLAVA's architecture incorporates both dual and fusion encoder designs, further enhancing its versatility and capabilities.
Embed this episode
Ready to play
FLAVA: A Foundational Language And Vision Alignment Model
No transcript for this episode yet
Similar Episodes
No similar episodes found.