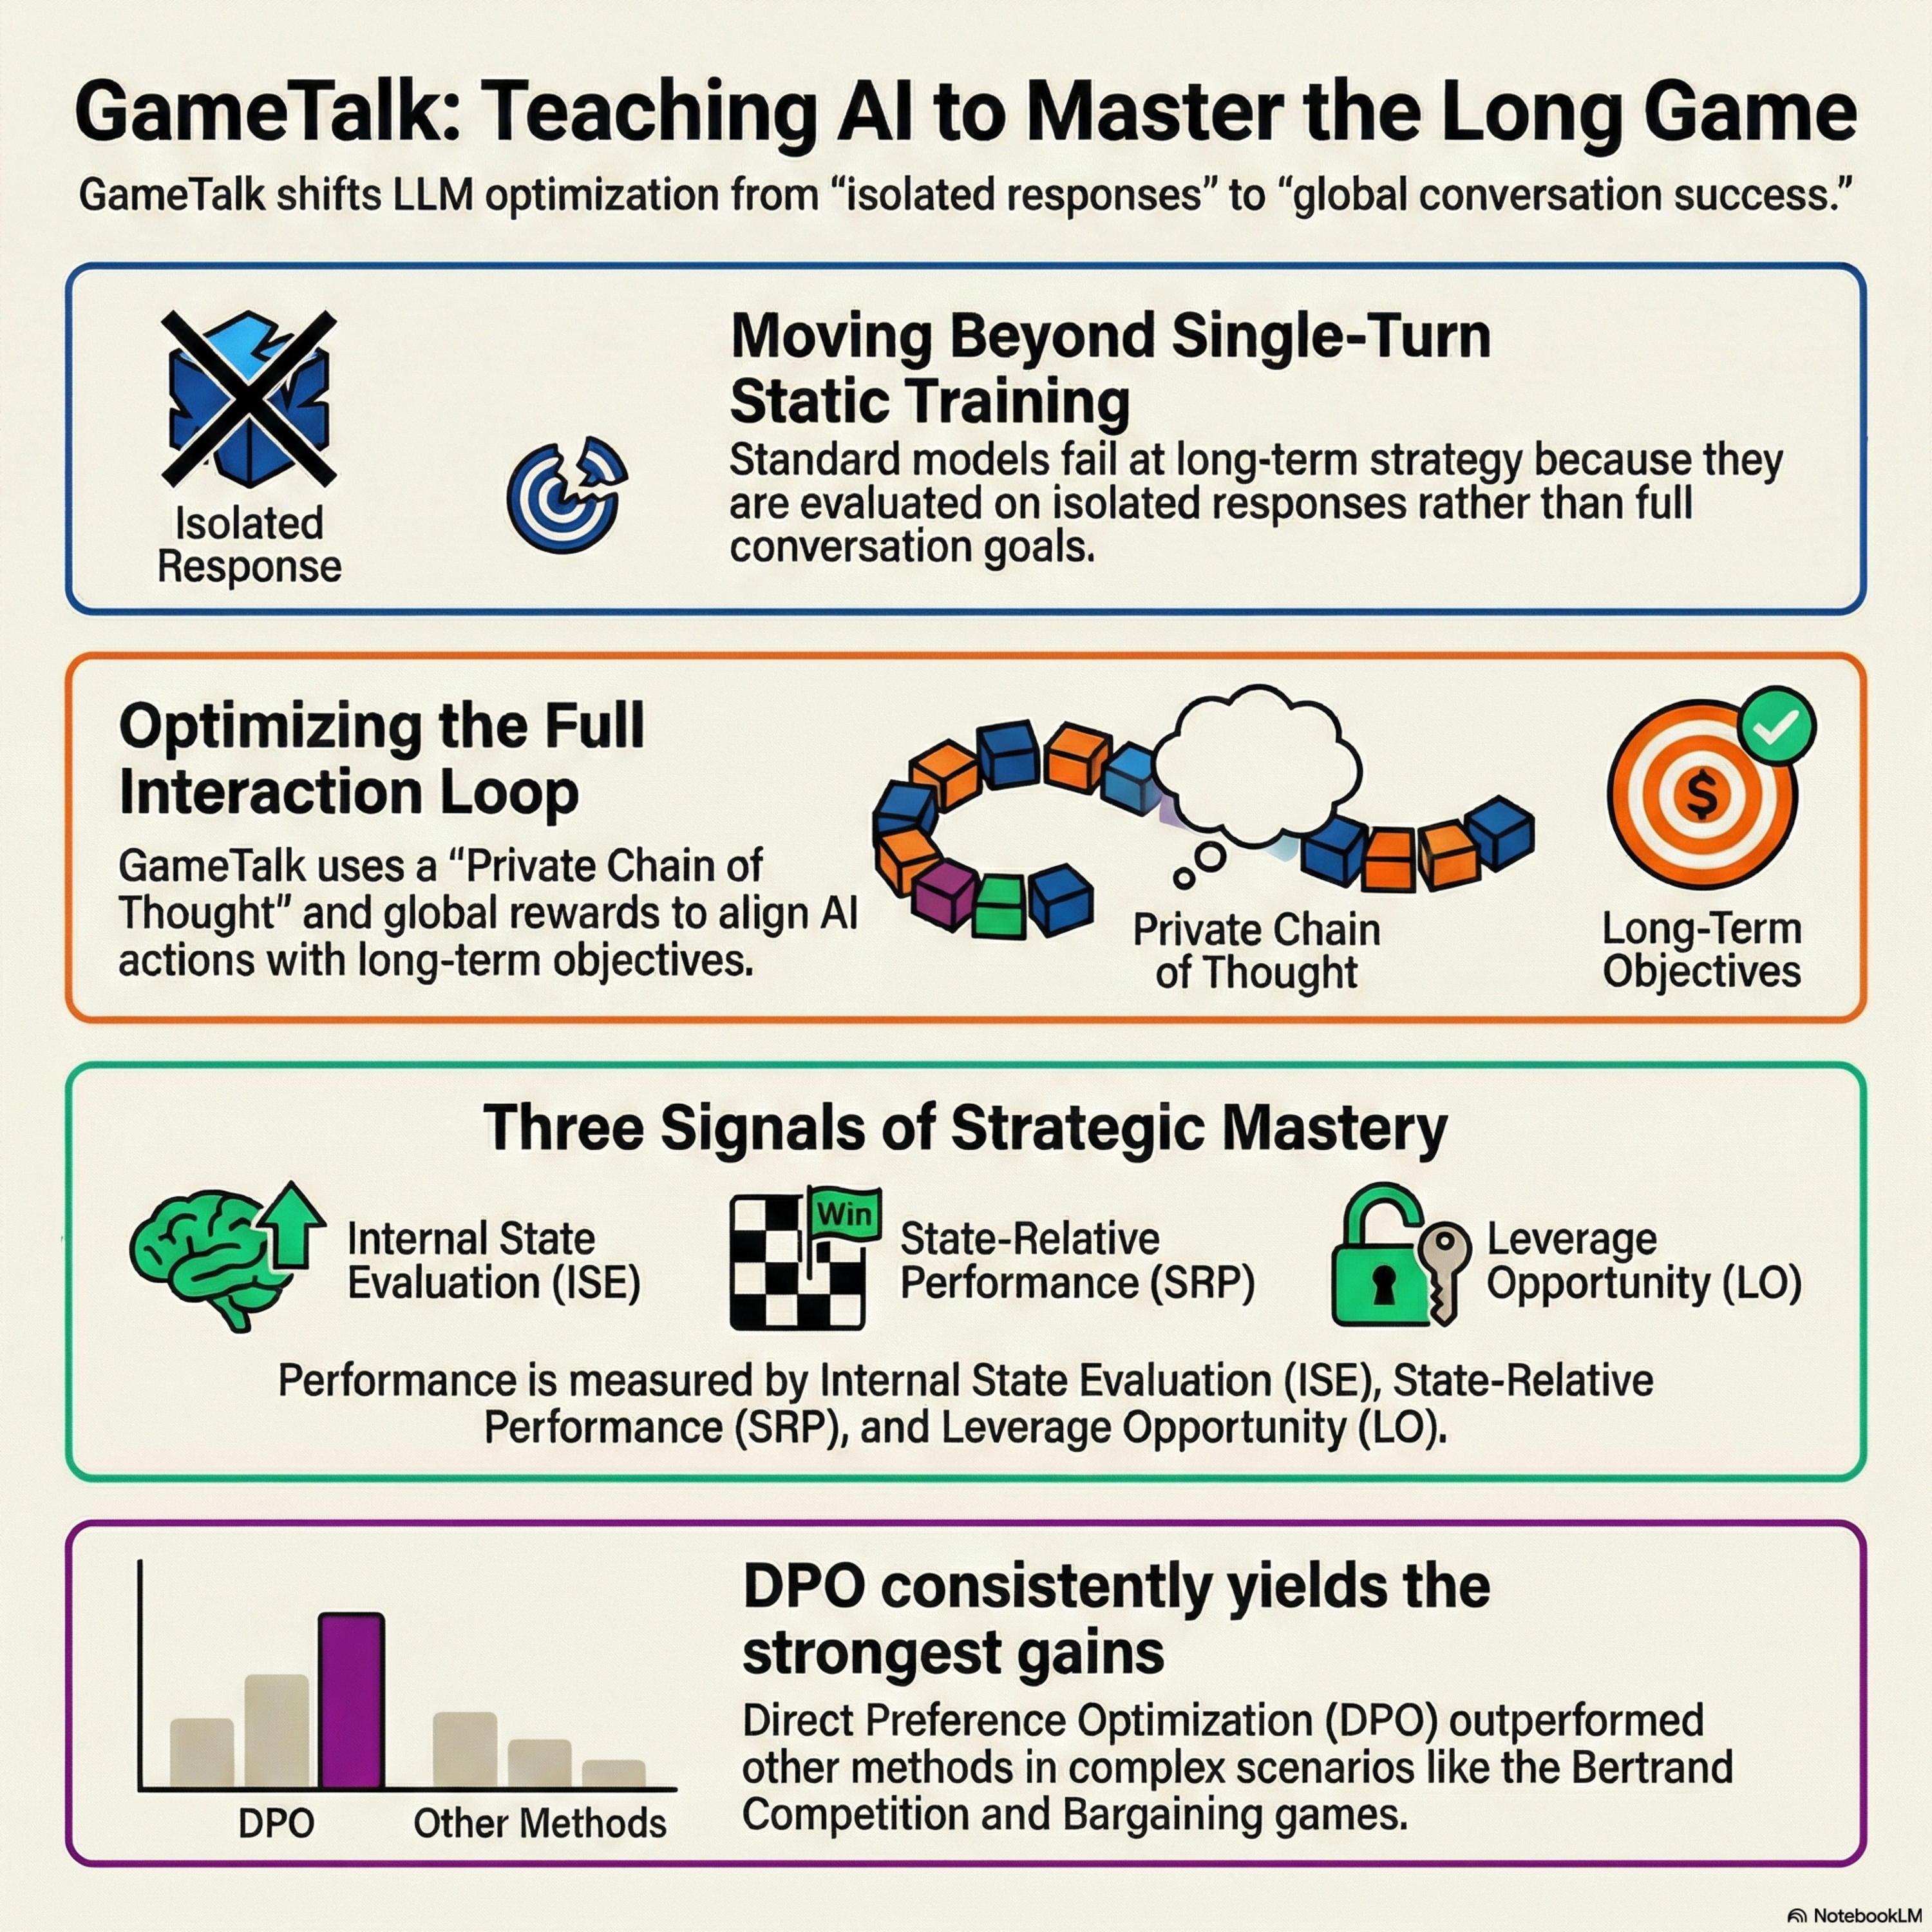
GameTalk: Training LLMs for Strategic Multi-Turn Conversation
from Best AI papers explained Hosted by Enoch H. Kang
This paper introduces **GameTalk**, a novel framework designed to train large language models (LLMs) for **strategic, multi-turn conversations**. While standard LLM training typically focuses on static, single-turn tasks, this research optimizes models to achieve **long-term goals** through complex interactions like negotiation and coordination. The authors adapt advanced fine-tuning methods—specifically **DPO, GRPO, and STaR**—to incorporate rewards based on the outcome of entire dialogues across various game environments. To diagnose and improve performance, the study utilizes three behavioral signals: **Internal State Evaluation**, **State-Relative Performance**, and **Leverage Opportunity**. Experimental results across games like Rock-Paper-Scissors and bargaining scenarios demonstrate that **DPO** is particularly effective at teaching models to use language as a persuasive tool. Ultimately, the framework shifts the focus of AI development toward **dynamic, goal-oriented reasoning** in interactive settings.
Embed this episode
No transcript yet.