Harness RL is Meta-Learning: Training to Self-Improve at Test Time
from Best AI papers explained Hosted by Enoch H. Kang
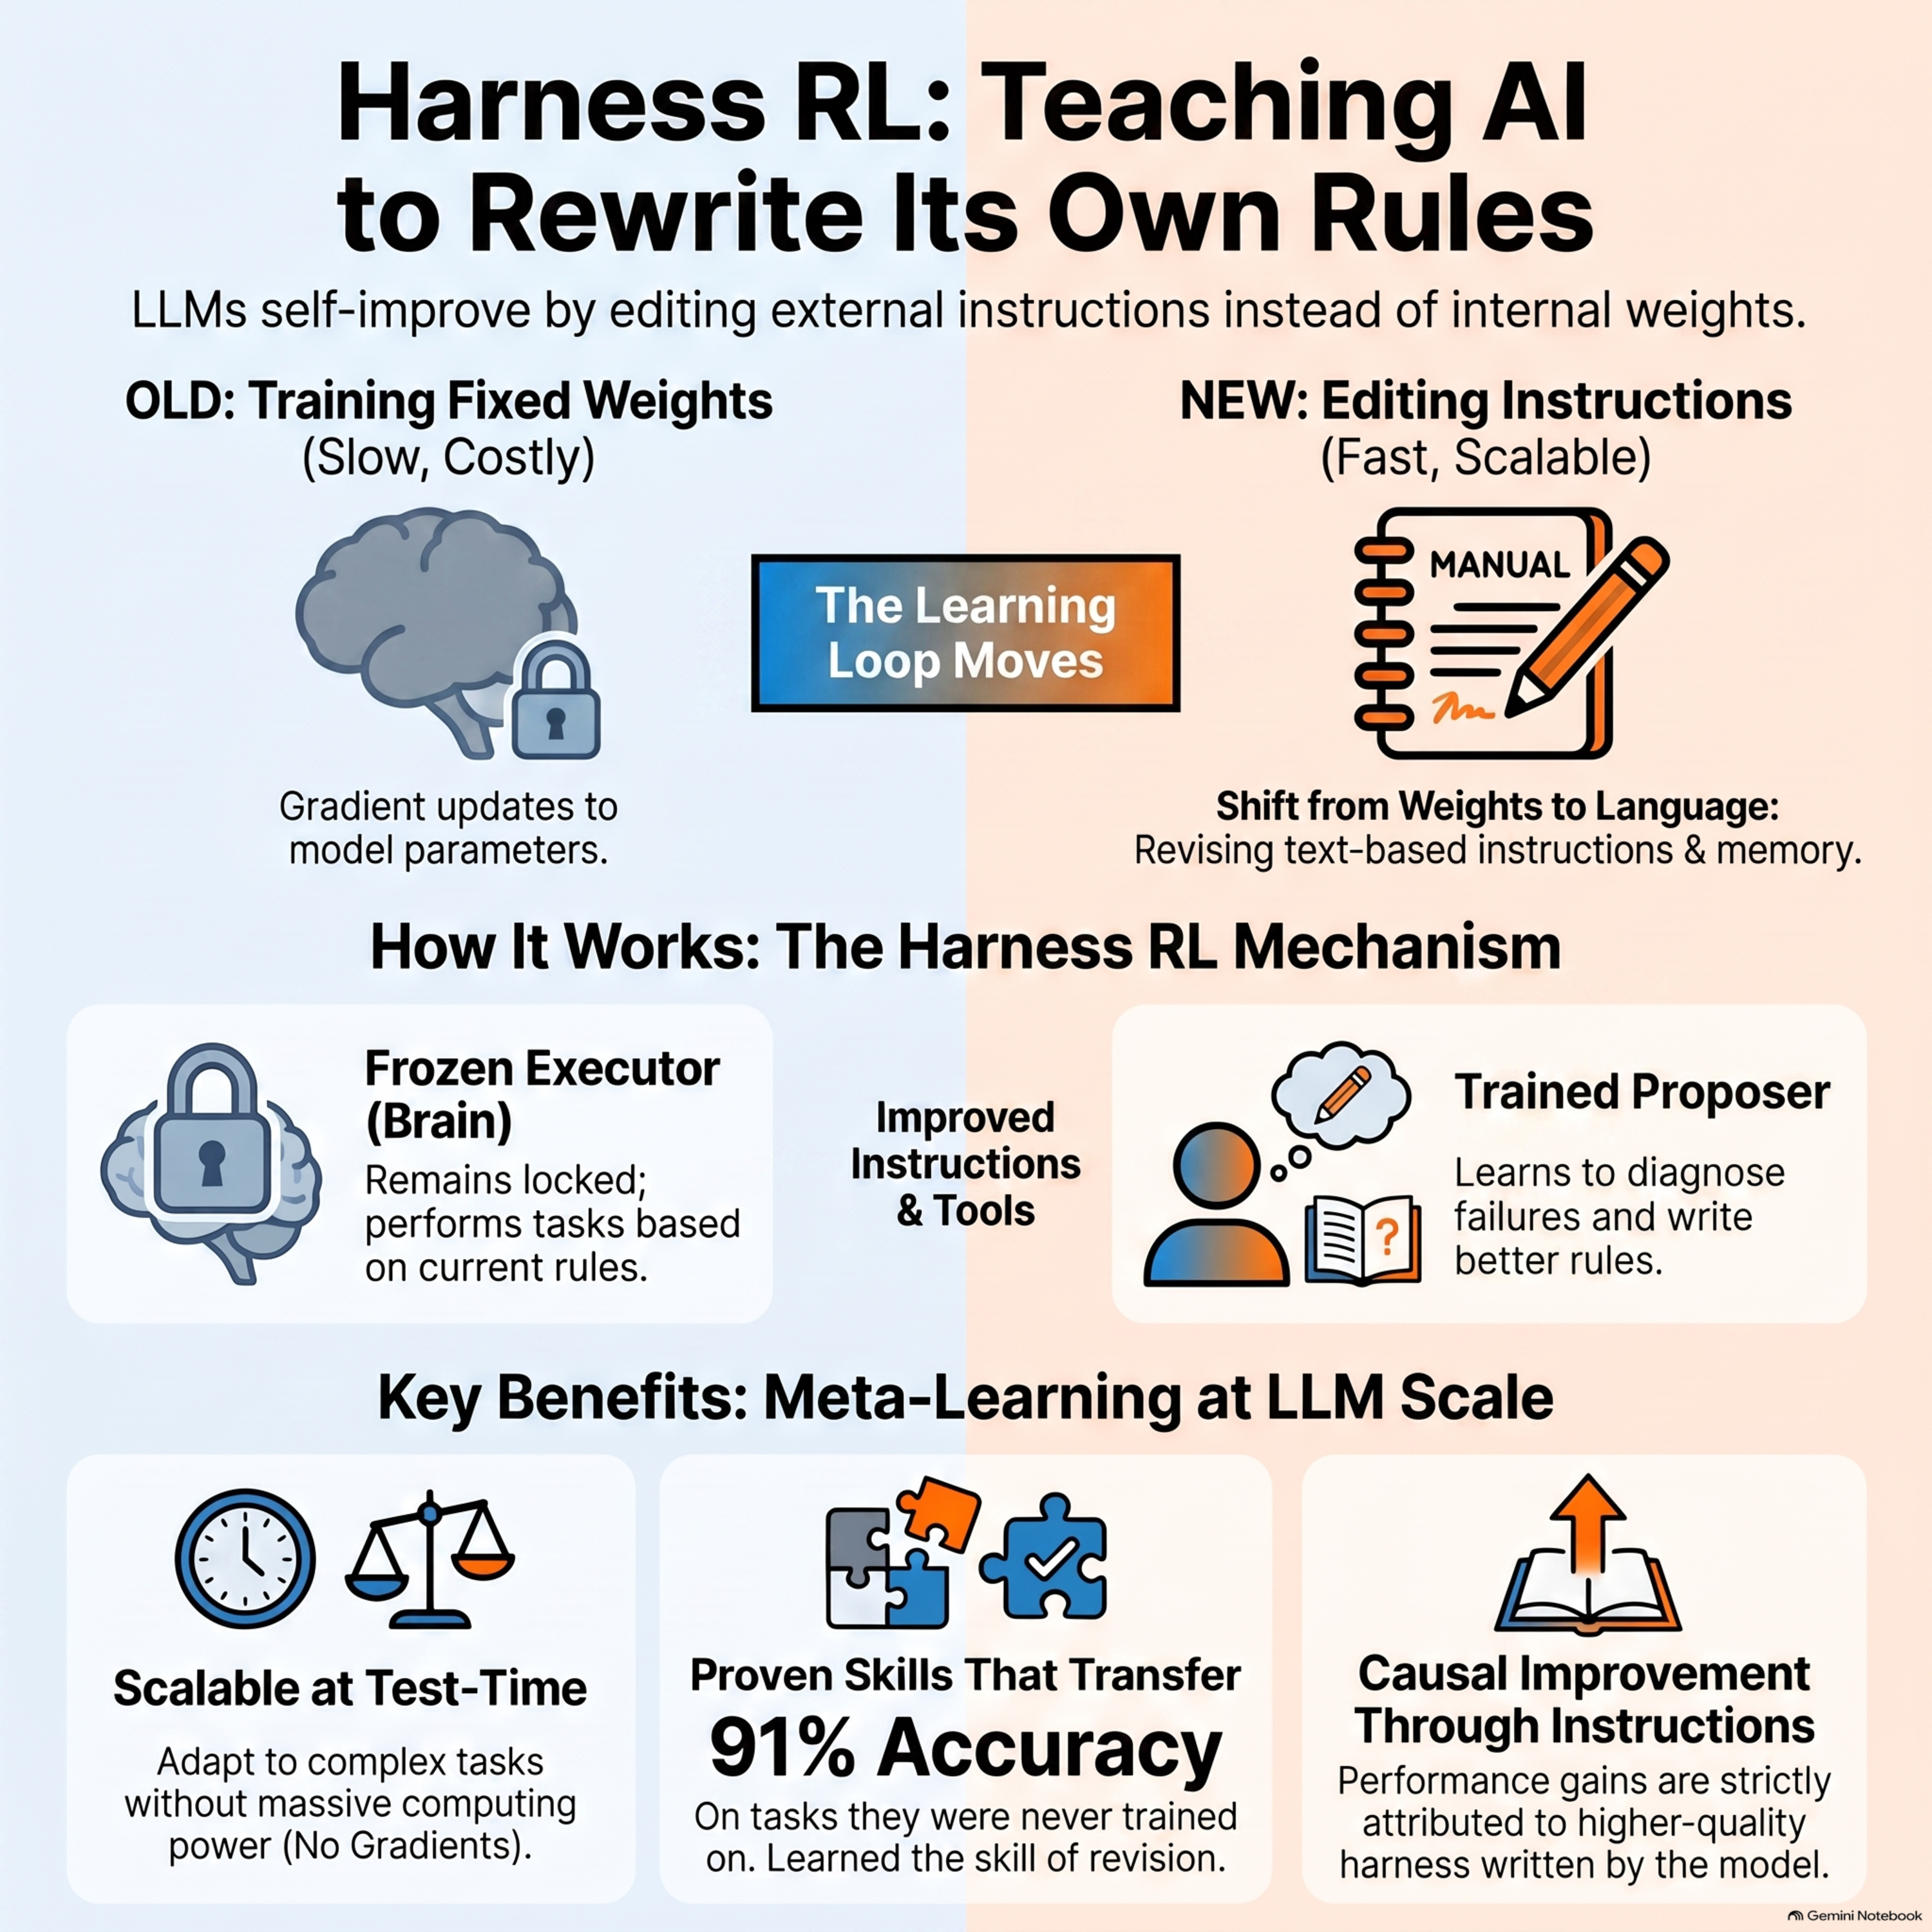
This paper introduces harness RL, a novel meta-learning framework designed to enable large language models to self-improve during test-time adaptation. Rather than updating model weights, which is computationally expensive, this method optimizes the agent’s harness—the external instructions, memory, and rules that guide model execution. By training a proposer model to revise this harness while keeping the executor model frozen, the system learns a transferable self-improvement operator. This approach reduces complex meta-learning to a standard reinforcement learning objective because the adaptation process requires no gradients. Experimental results across reasoning and coding tasks demonstrate that the trained proposer generalizes to unseen problems and maintains performance across longer revision horizons. Ultimately, the authors show that harness RL successfully isolates and improves the model's capacity for meta-self-improvement.
Embed this episode
No transcript yet.