In-Context Algorithm Emulation in Fixed-Weight Transformers
from Best AI papers explained Hosted by Enoch H. Kang
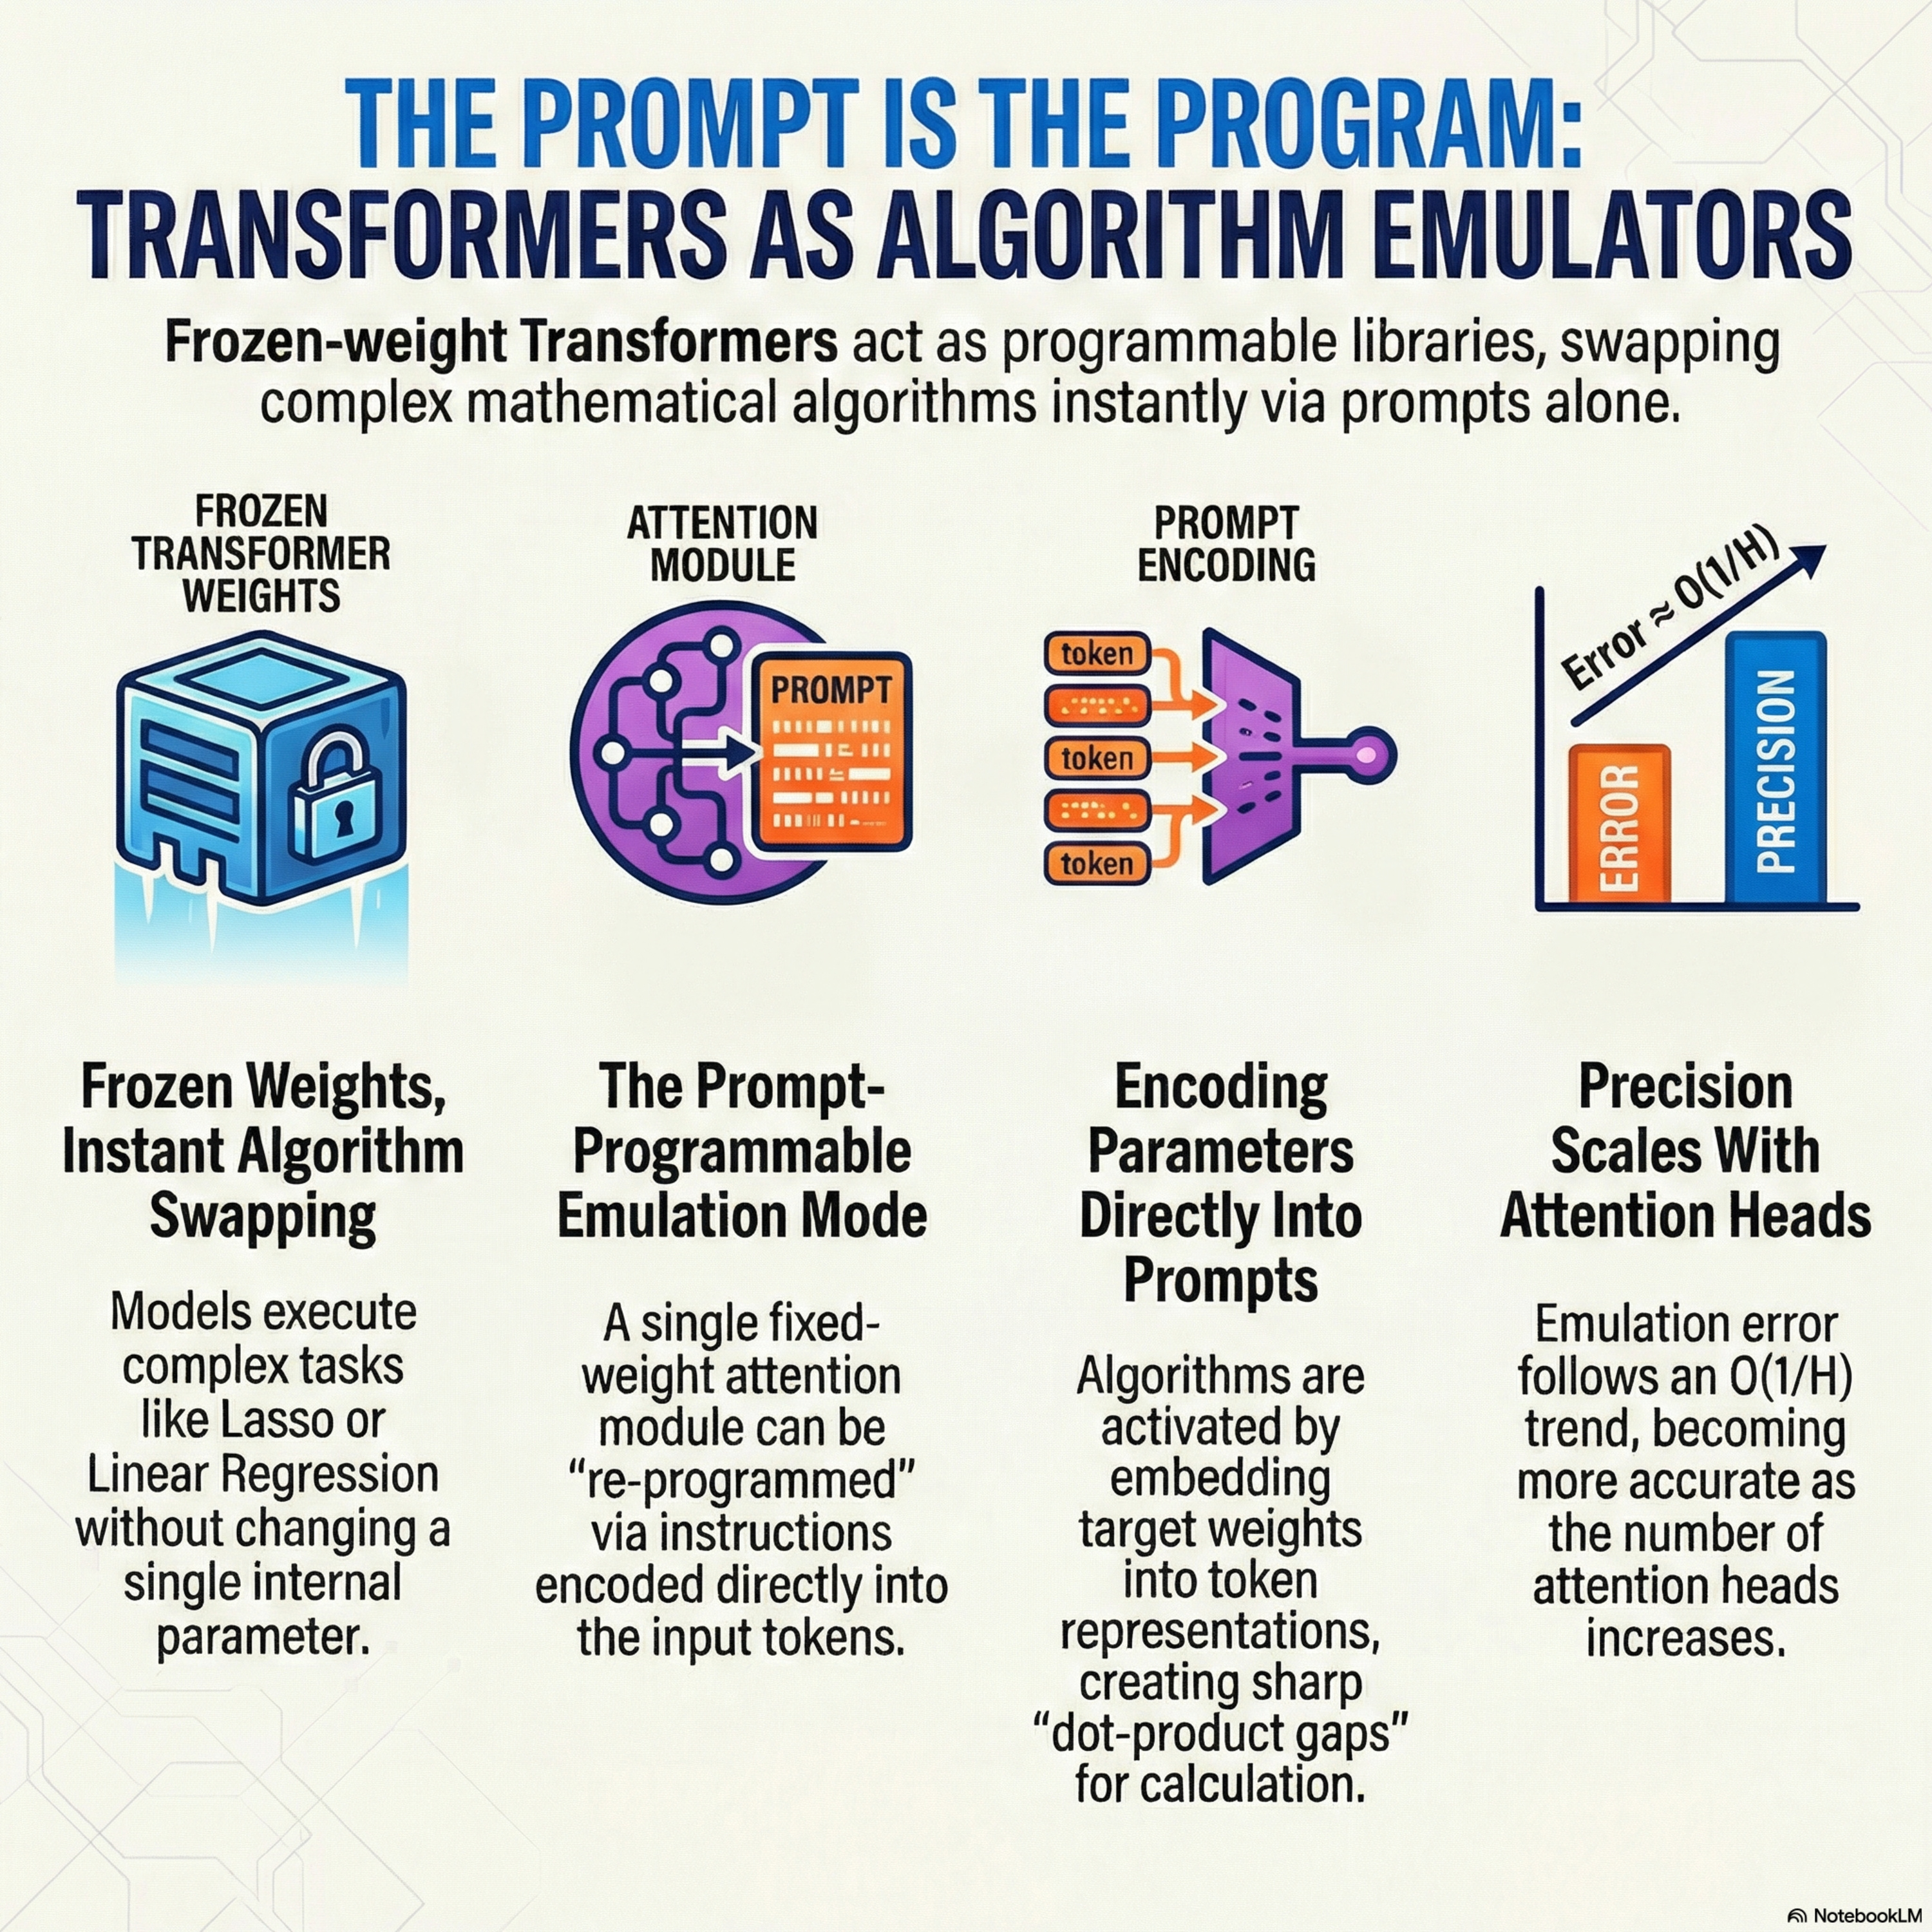
This research demonstrates that fixed-weight Transformers can function as versatile algorithm emulators by simply modifying the input prompt. The authors prove that a minimal attention architecture can execute a wide variety of machine learning tasks, such as gradient descent and linear regression, without updating its internal parameters. They distinguish between task-specific emulation, where a dedicated module performs one routine, and a more powerful prompt-programmable mode where a single module hosts a library of different algorithms. This capability is achieved by encoding algorithmic instructions and parameters directly into the prompt's tokens, allowing the model to swap routines on the fly. Mathematical proofs and experiments confirm that softmax attention alone is sufficient to achieve this algorithmic universality. Ultimately, the study provides a theoretical foundation for understanding how foundation models like GPT can adapt to complex new tasks through context alone.
Embed this episode
No transcript yet.