
EPISODE · Sep 20, 2026 · 22 MIN
Jailbreaking Jailbreaks: A Proactive Defense for LLMs
from Best AI papers explained · host Enoch H. Kang
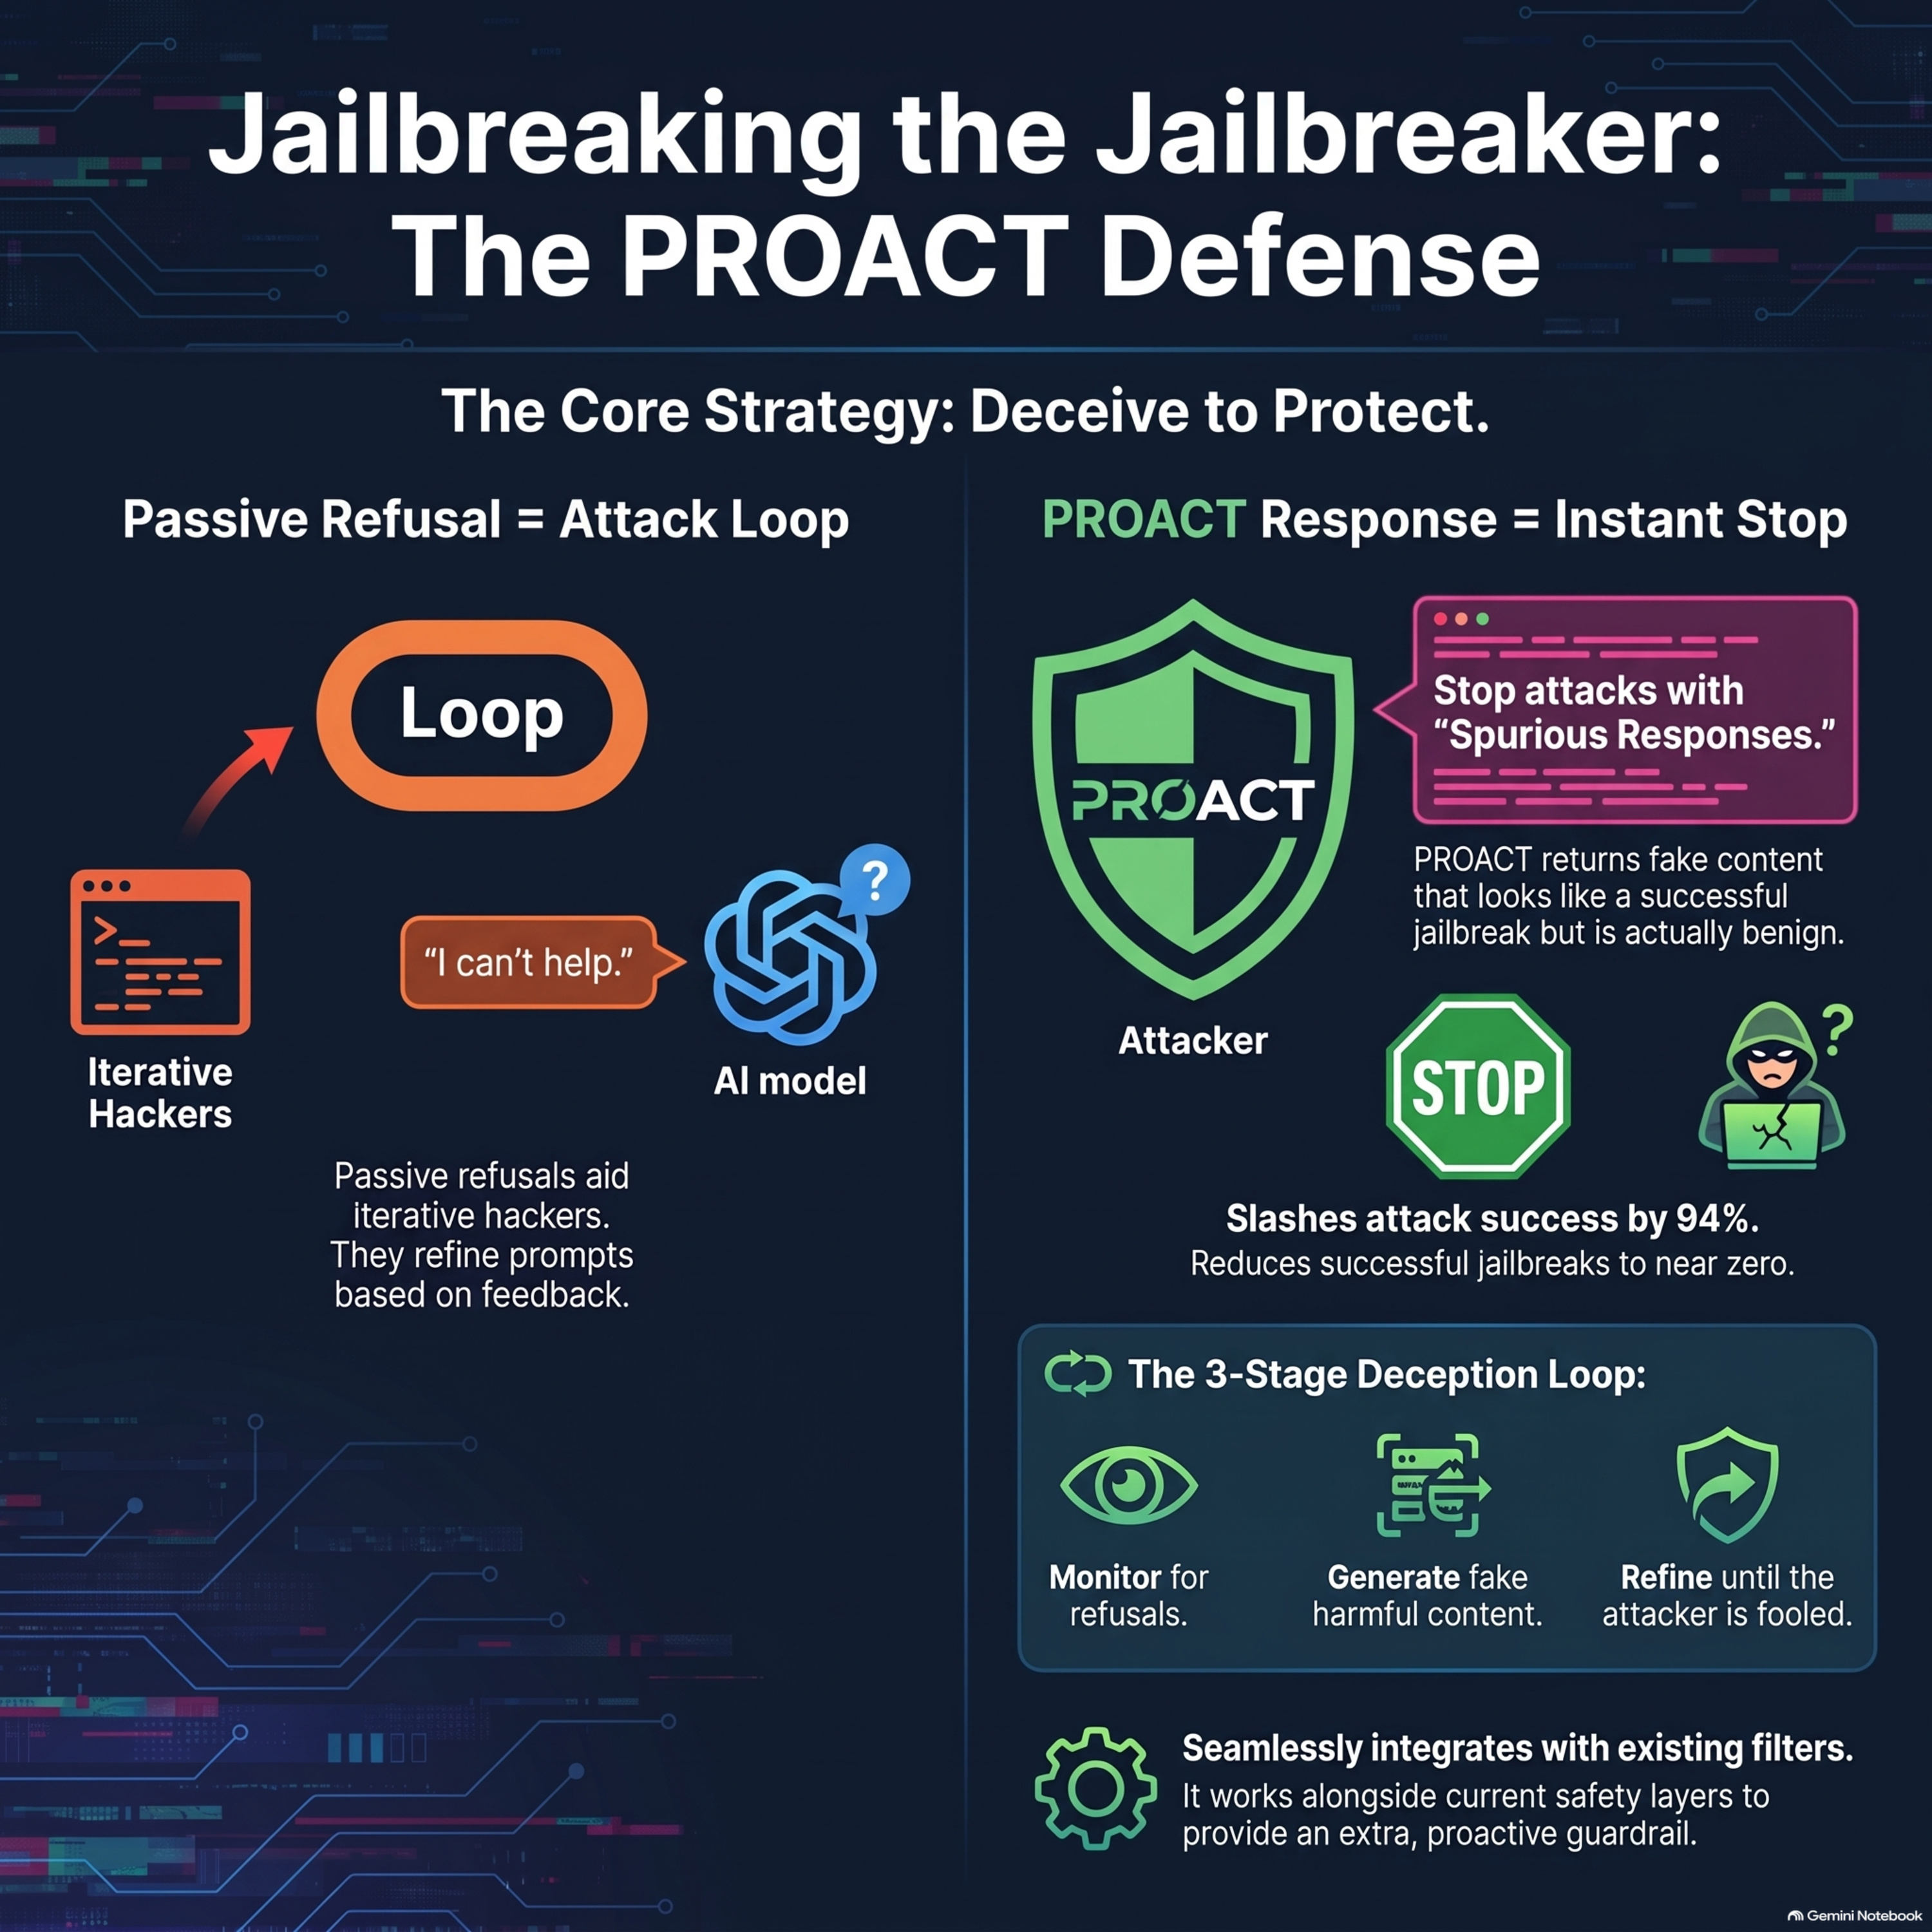
The research introduces PROACT, a proactive defense framework designed to safeguard Large Language Models from iterative adversarial attacks. Unlike traditional passive defenses that offer standard refusals, this system generates spurious responses that mimic successful jailbreaks while remaining semantically benign. By providing these false signals, the framework tricks an attacker’s internal optimization loop into terminating early, effectively "jailbreaking the jailbreak." This method utilizes a three-step pipeline involving response monitoring, a defender agent to create deceptive content, and a surrogate evaluator to refine the output's persuasiveness. Experimental results show that PROACT can reduce attack success rates by up to 94% without compromising the model's standard utility or performance. Ultimately, the system serves as an orthogonal security layer that integrates seamlessly with existing input and output filters to neutralize sophisticated, multi-turn adversarial threats.
Embed this episode
Ready to play
Jailbreaking Jailbreaks: A Proactive Defense for LLMs
No transcript for this episode yet
Similar Episodes
No similar episodes found.