
EPISODE · Sep 7, 2026 · 22 MIN
Next-Latent Prediction Transformers Learn Compact World Models
from Best AI papers explained · host Enoch H. Kang
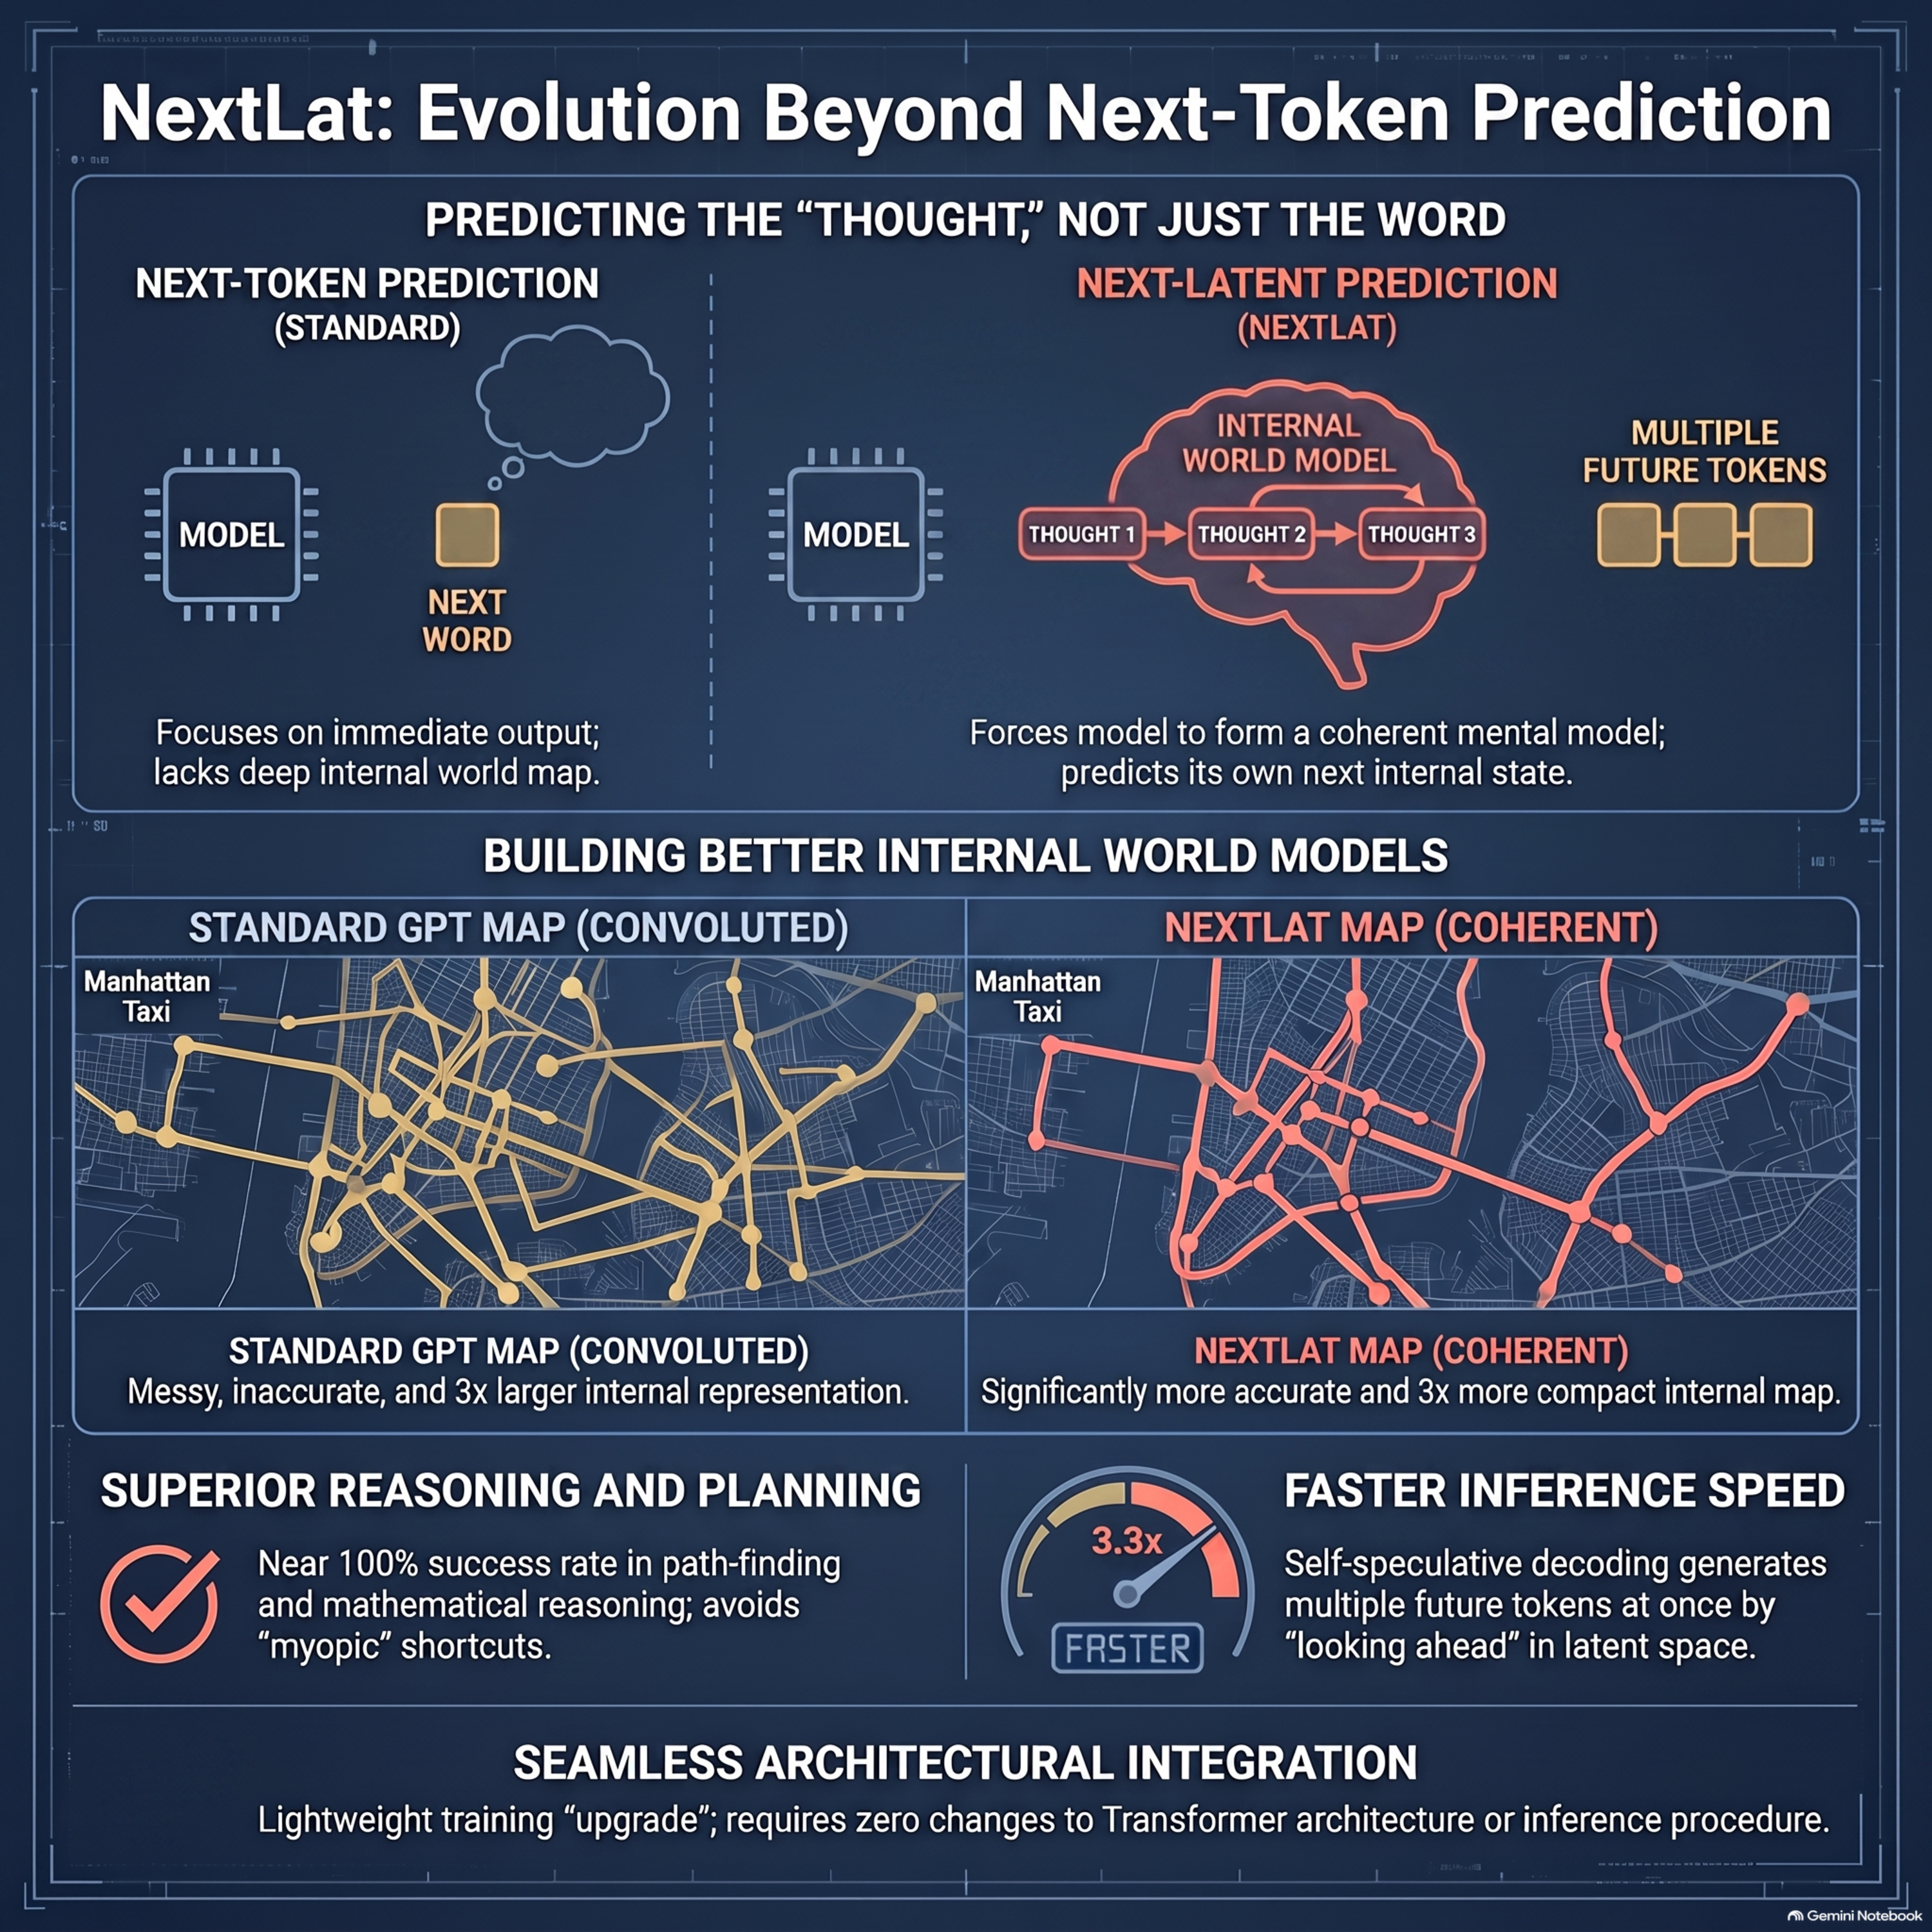
This paper introduces Next-Latent Prediction (NextLat), a novel training framework designed to help Transformer models learn more compact and generalizable internal world models. Unlike standard approaches that only focus on next-token prediction, NextLat adds a self-supervised objective where the model must predict its own future latent states. This method encourages the formation of belief states, which are efficient summaries of past information that improve the model’s ability to reason, plan, and generalize. Theoretically, this injects a recurrent inductive bias into the architecture without sacrificing the parallel training efficiency or speed of the original Transformer. Empirically, NextLat demonstrates superior performance in world modeling and long-horizon reasoning compared to traditional baselines. Furthermore, the learned latent dynamics enable variable-length self-speculative decoding, which can accelerate inference speeds by over three times.
Embed this episode
Ready to play
Next-Latent Prediction Transformers Learn Compact World Models
No transcript for this episode yet
Similar Episodes
No similar episodes found.