Parallel Token Generation for Language Models
from Best AI papers explained Hosted by Enoch H. Kang
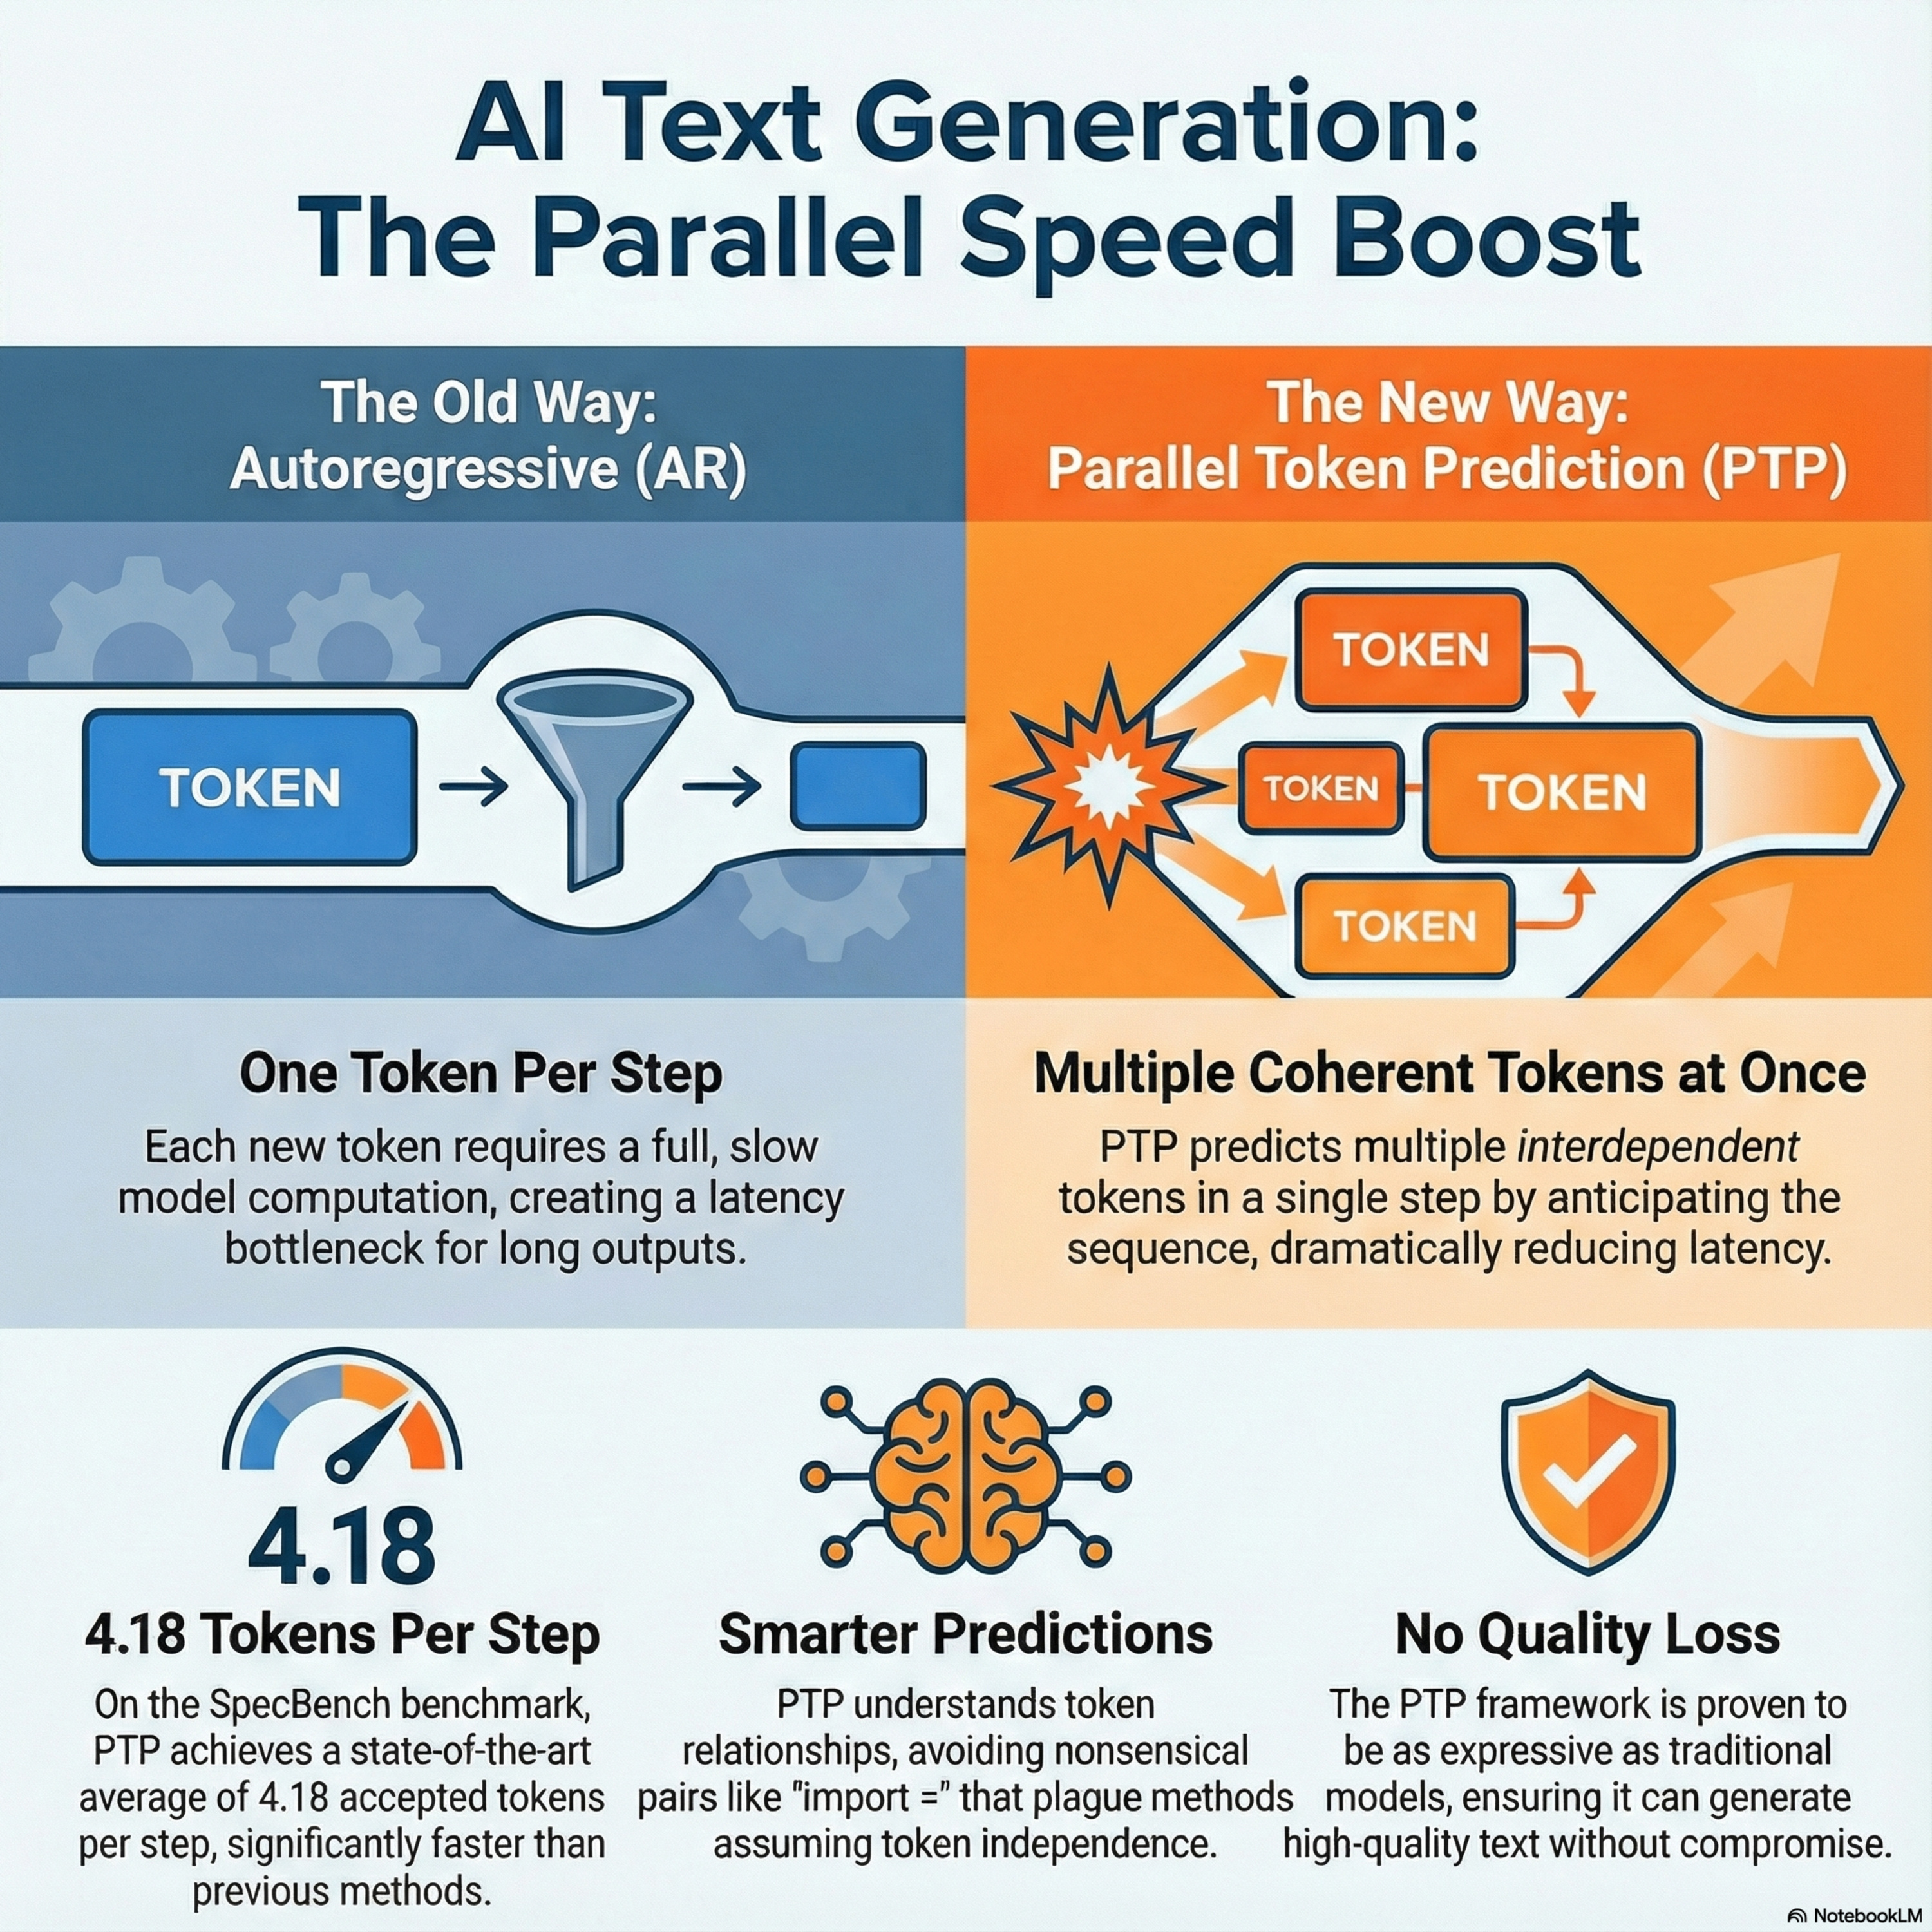
This research introduces **Parallel Token Prediction (PTP)**, a novel framework designed to accelerate language model inference by generating multiple tokens simultaneously in a single forward pass. Standard models suffer from a **sequential bottleneck**, but PTP overcomes this by incorporating auxiliary random variables directly into the model's inputs to coordinate interdependent predictions. The authors provide mathematical proof that this method is as **expressively powerful** as traditional autoregressive models while avoiding the incoherent outputs common in other parallel systems. Experimental results demonstrate that PTP achieves **state-of-the-art decoding speeds** across diverse tasks, including coding and natural language conversation. By reducing latency without sacrificing accuracy, the framework offers a scalable path toward more **efficient and responsive** artificial intelligence applications.
Embed this episode
No transcript yet.