
EPISODE · Dec 9, 2024 · 17 MIN
Reformer: The Efficient Transformer
from KnowledgeDB.ai · host KnowledgeDB
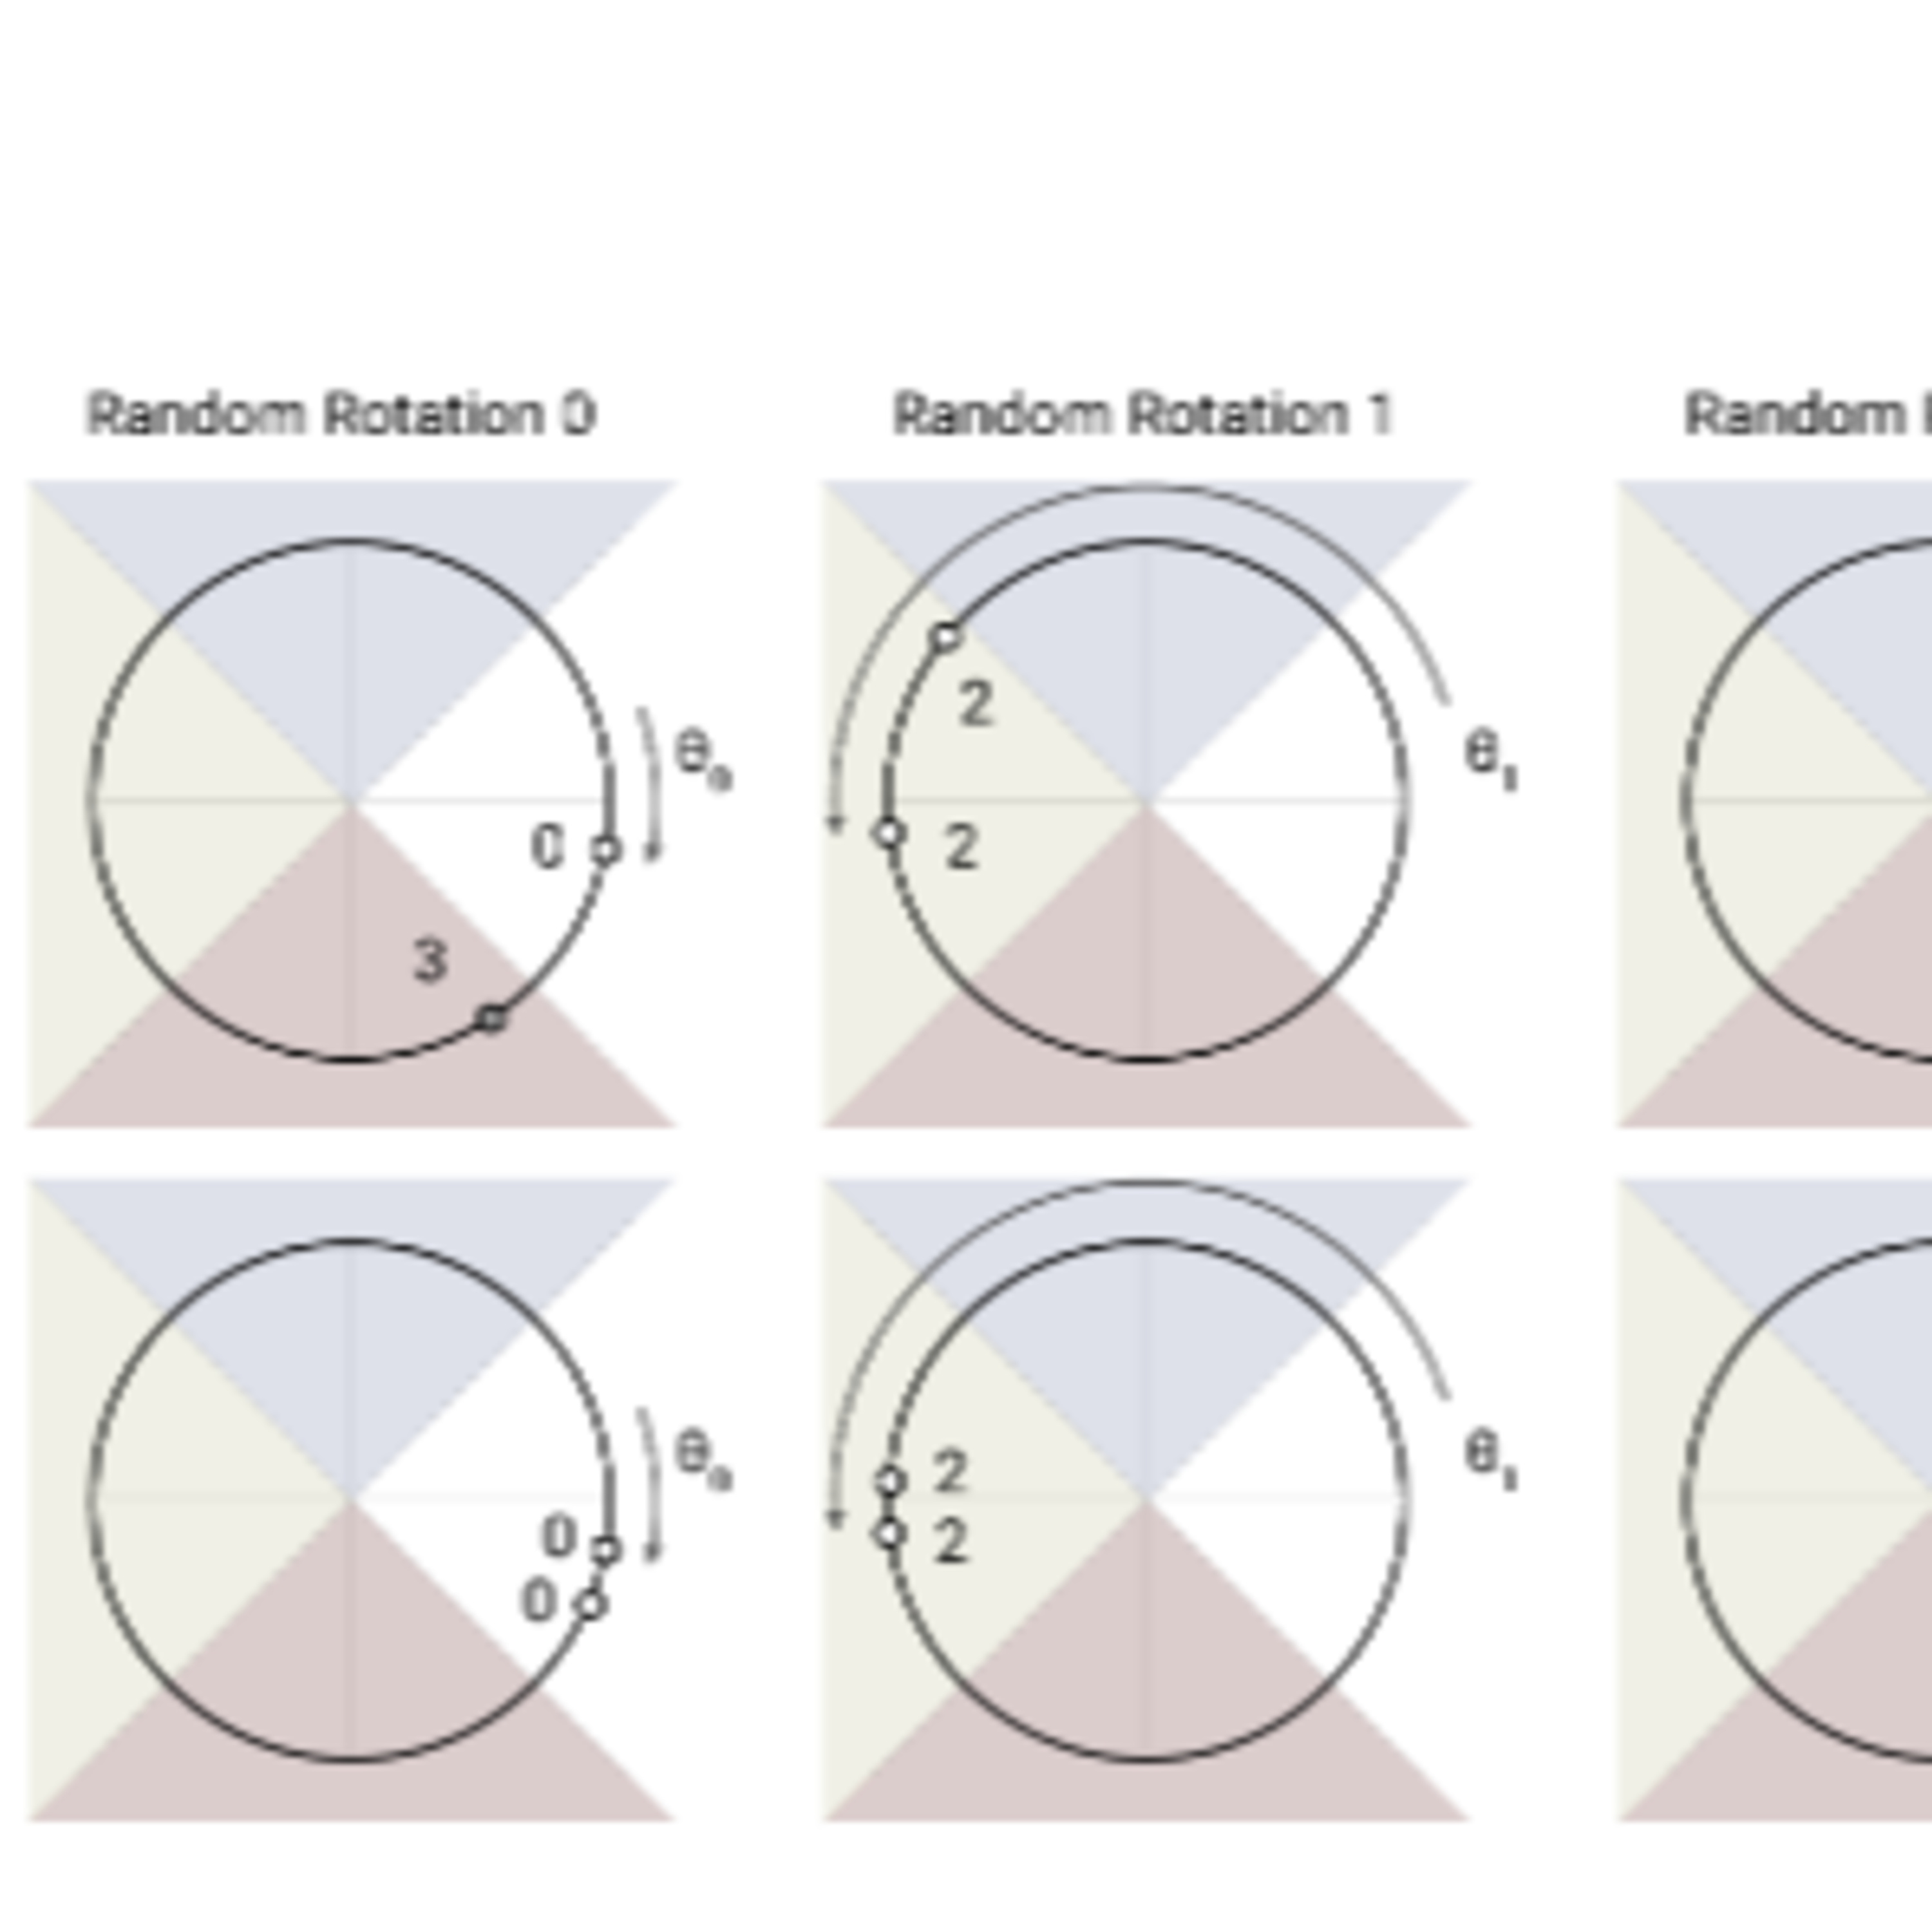
Ref: https://arxiv.org/abs/2001.04451 The paper introduces the Reformer, a more efficient Transformer model. It achieves this through three key improvements: replacing dot-product attention with locality-sensitive hashing for faster computation on long sequences, utilizing reversible residual layers to reduce memory consumption by storing activations only once, and employing a chunking mechanism to further optimize memory usage in feed-forward layers. The Reformer maintains performance comparable to standard Transformers while significantly improving speed and memory efficiency, especially when processing lengthy sequences. Experimental results across text and image generation tasks demonstrate its superior performance.
Embed this episode
Ready to play
Reformer: The Efficient Transformer
No transcript for this episode yet
Similar Episodes
No similar episodes found.