Representation-Based Exploration for Language Models: from test-time to post-training
from Best AI papers explained Hosted by Enoch H. Kang
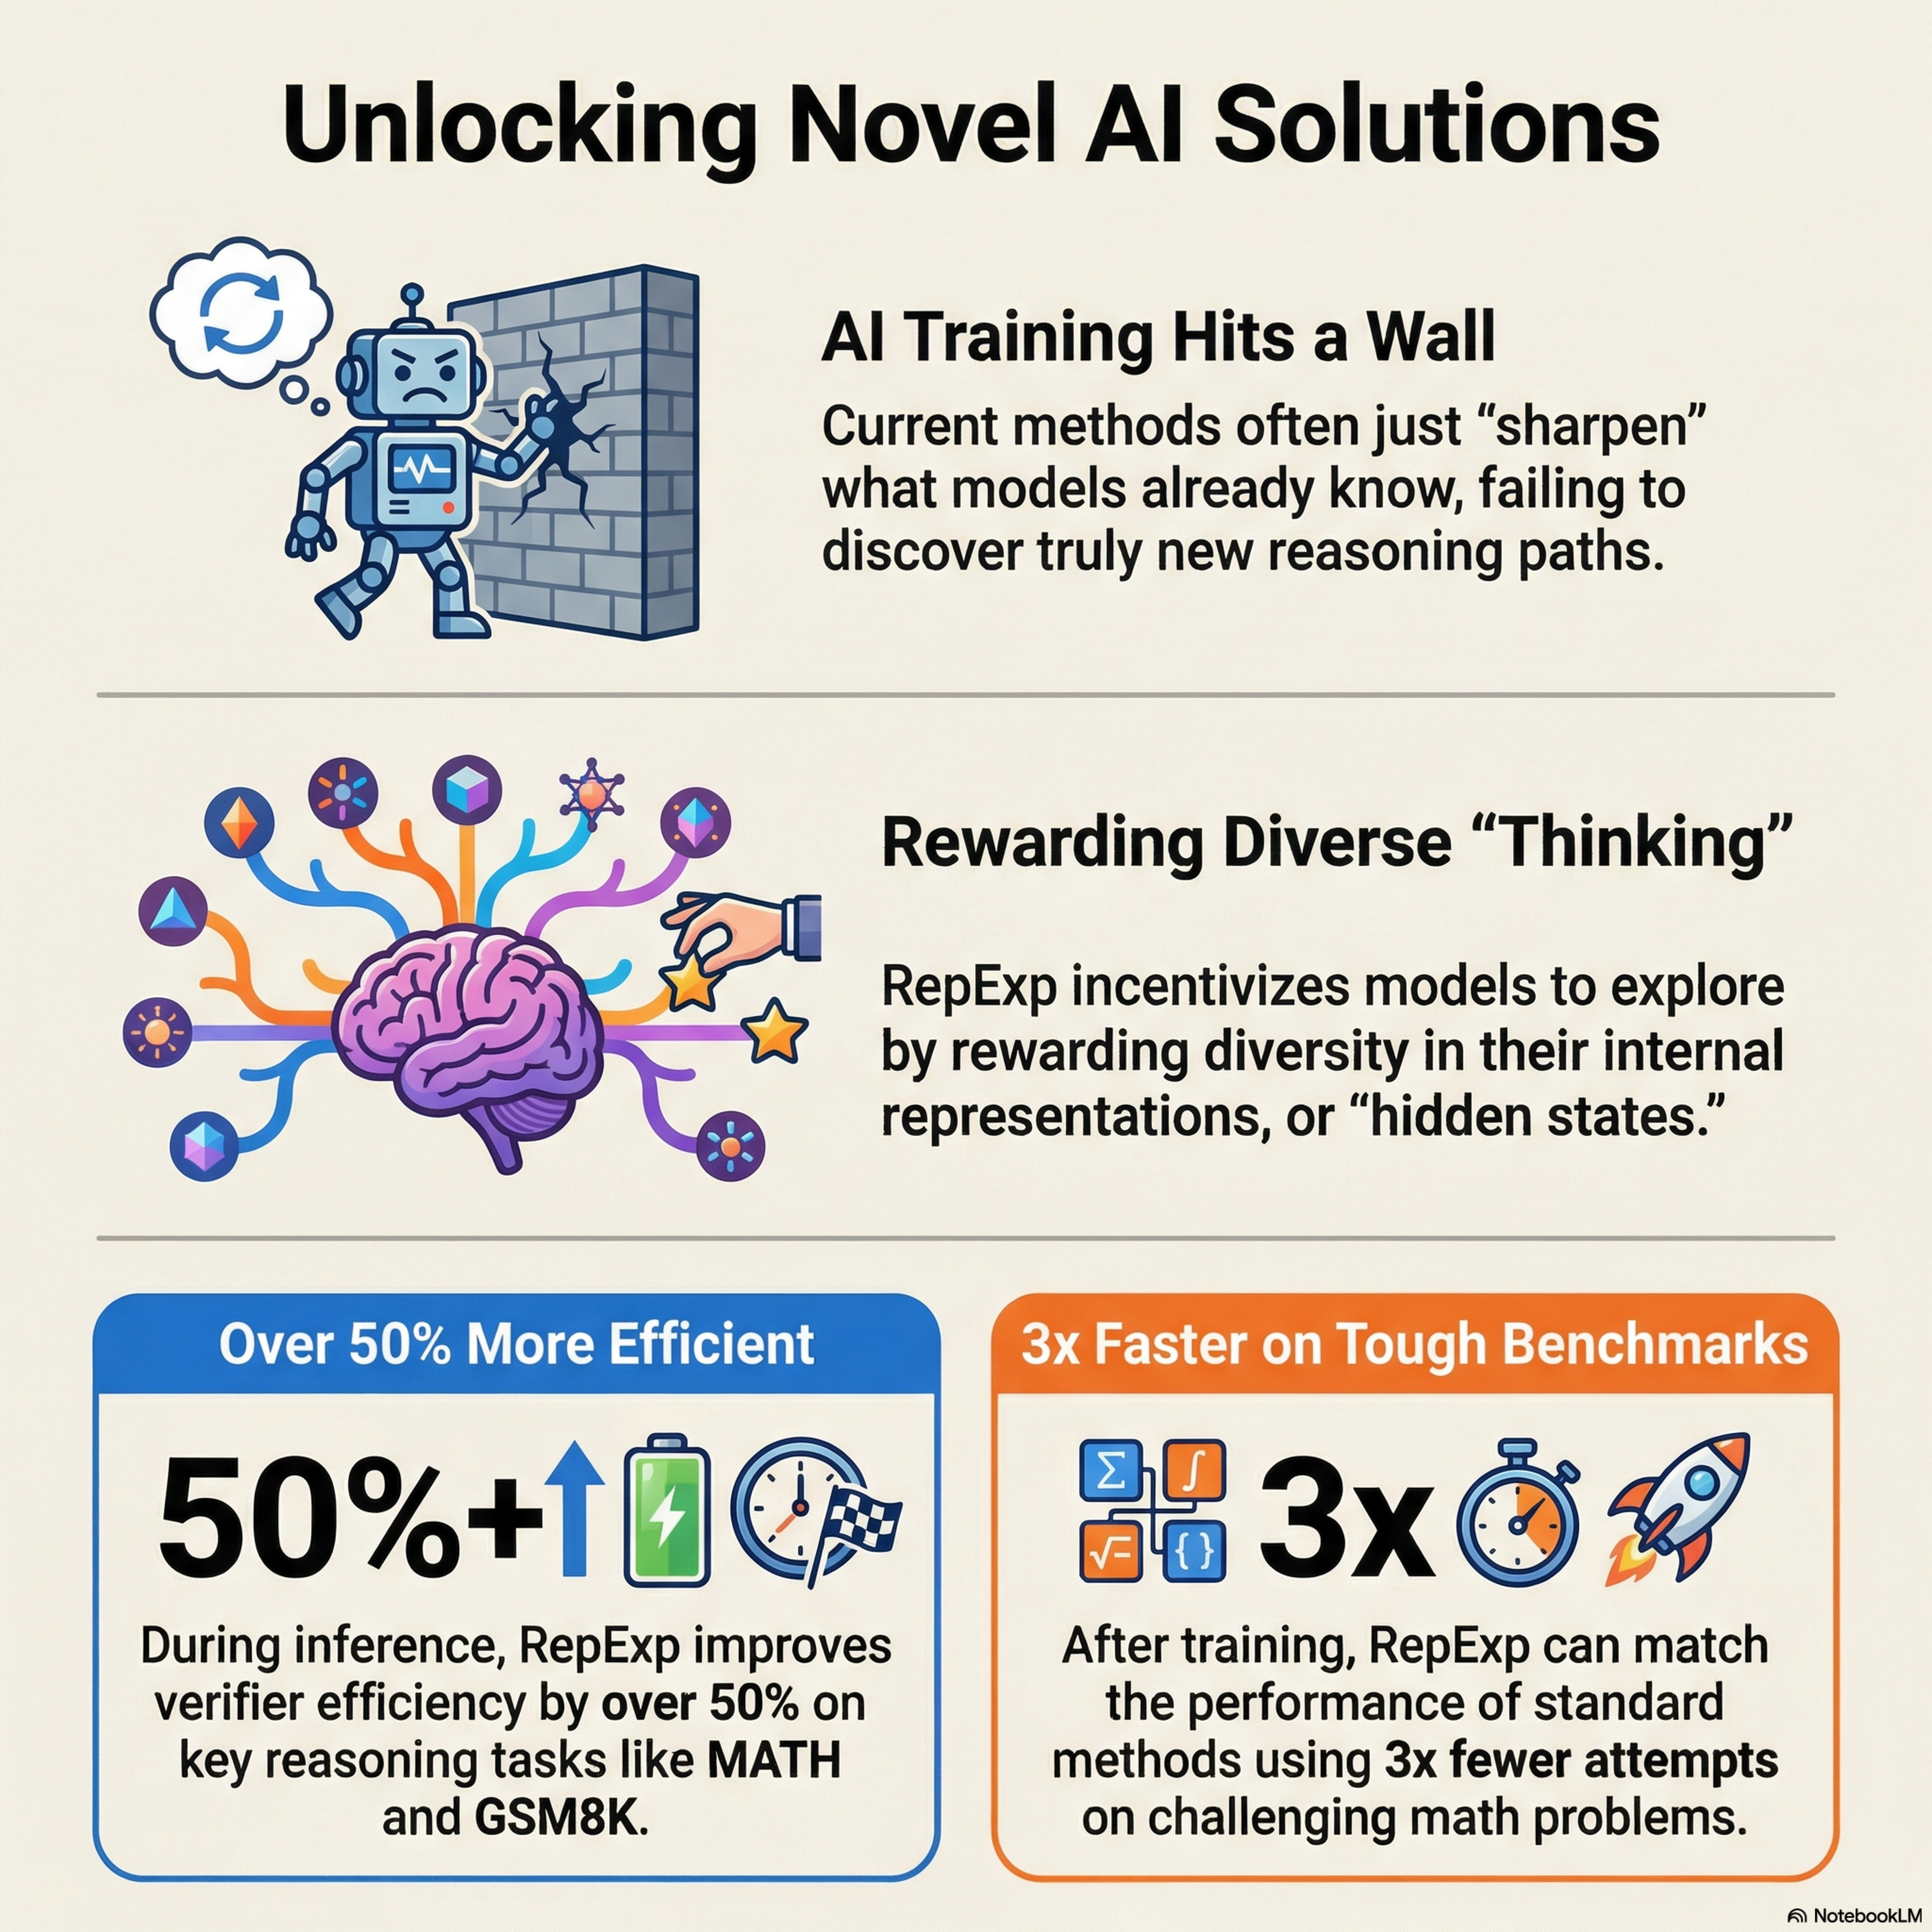
This paper introduces representation-based exploration, a method designed to help language models discover novel behaviors rather than just refining existing ones through reinforcement learning. The researchers propose using elliptical bonuses derived from a model's internal hidden states to explicitly reward diversity and novelty during both inference and training. Their experiments demonstrate that this approach significantly improves verifier efficiency and pass@k rates across complex reasoning and coding tasks. Notably, the technique mitigates the common problem of "diversity collapse," where standard reinforcement learning causes a model’s responses to become repetitive. By integrating these bonuses into the GRPO post-training pipeline, the authors show that models can achieve superior performance with fewer samples. Ultimately, the work suggests that leveraging a model's own internal knowledge is a practical and effective way to advance its autonomous reasoning capabilities.
Embed this episode
No transcript yet.