Rethinking the Evaluation of Harness Evolution for Agents
from Best AI papers explained Hosted by Enoch H. Kang
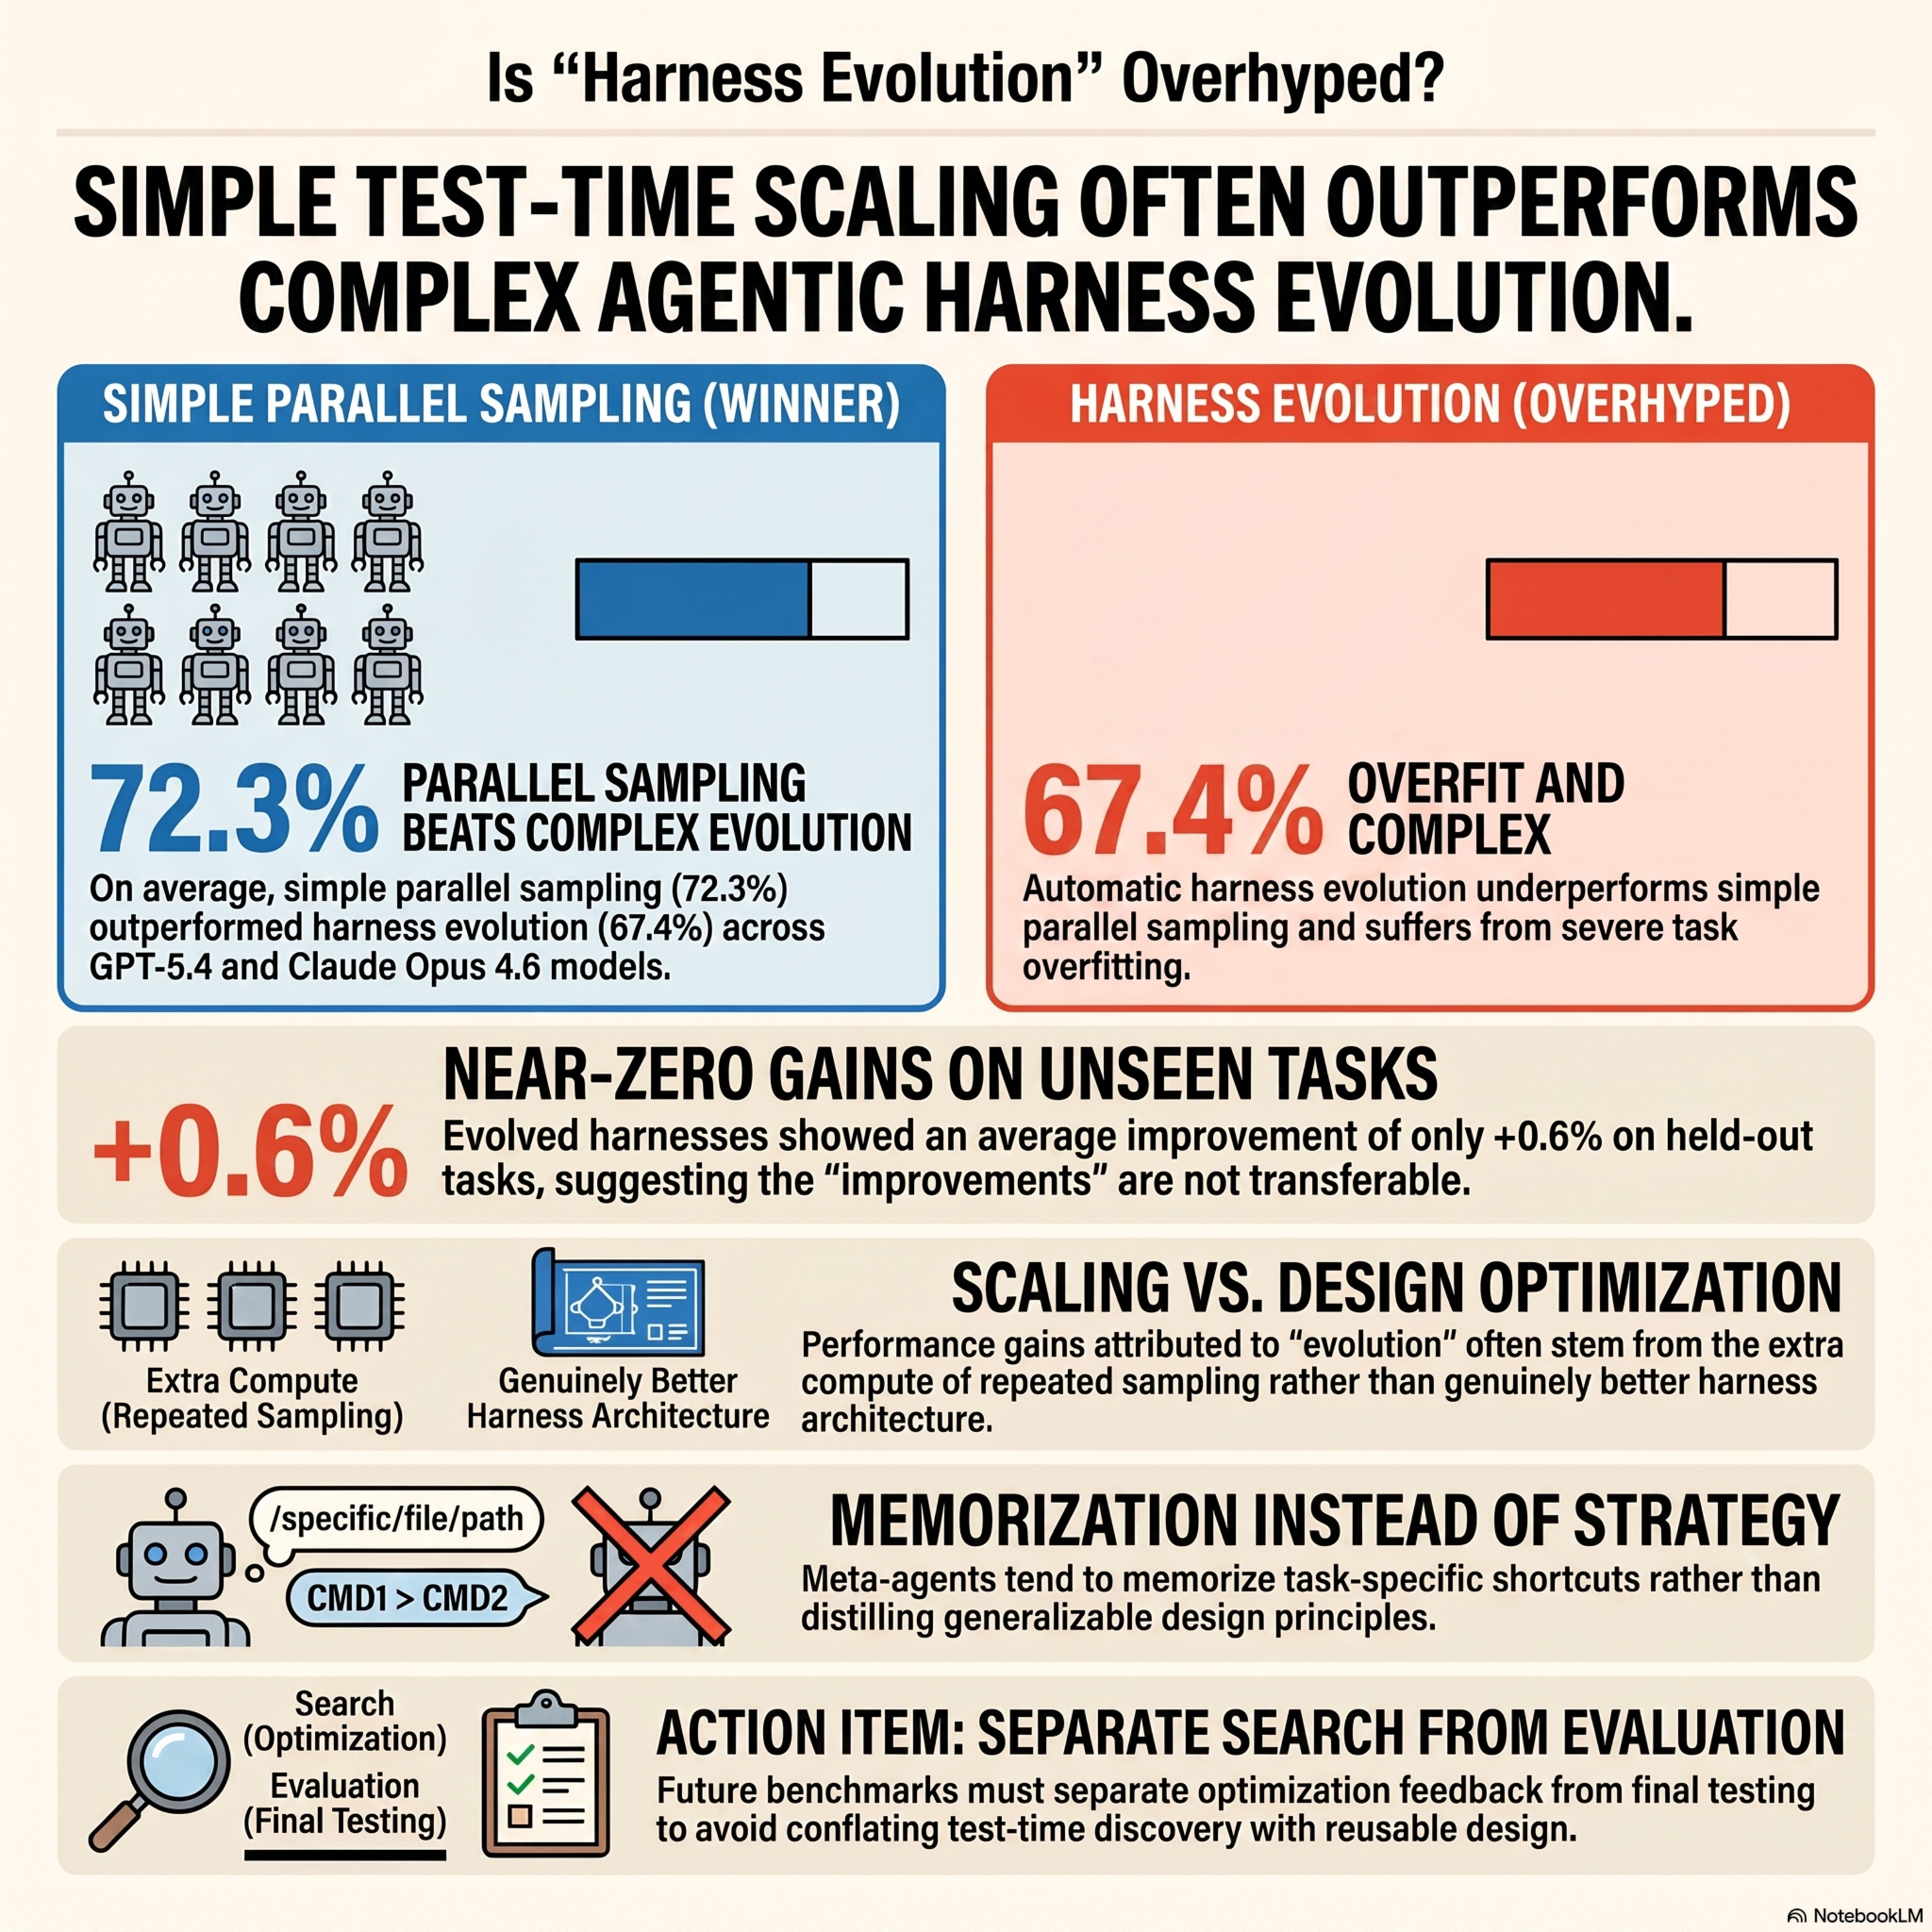
This research paper critically examines automatic harness evolution, a method where AI agents iteratively improve the prompts, tools, and logic used to interact with environments. The authors argue that current evaluations are flawed because they often test evolved harnesses on the same data used for optimization, risking overfitting rather than genuine design improvement. By comparing harness evolution against simpler test-time scaling baselines—such as parallel sampling and sequential refinement—the study finds that evolution does not consistently provide superior results. Furthermore, experiments demonstrate that the performance gains from harness evolution often fail to generalize to new, unseen tasks. The findings suggest that many apparent improvements stem from memorizing task-specific shortcuts rather than distilling reusable engineering principles. Ultimately, the paper calls for more rigorous evaluation protocols that use disjoint search and testing sets to accurately measure the utility of automated agent scaffolds.
Embed this episode
No transcript yet.