RL Token: Bootstrapping Online RL with Vision-Language-Action Models
from Best AI papers explained Hosted by Enoch H. Kang
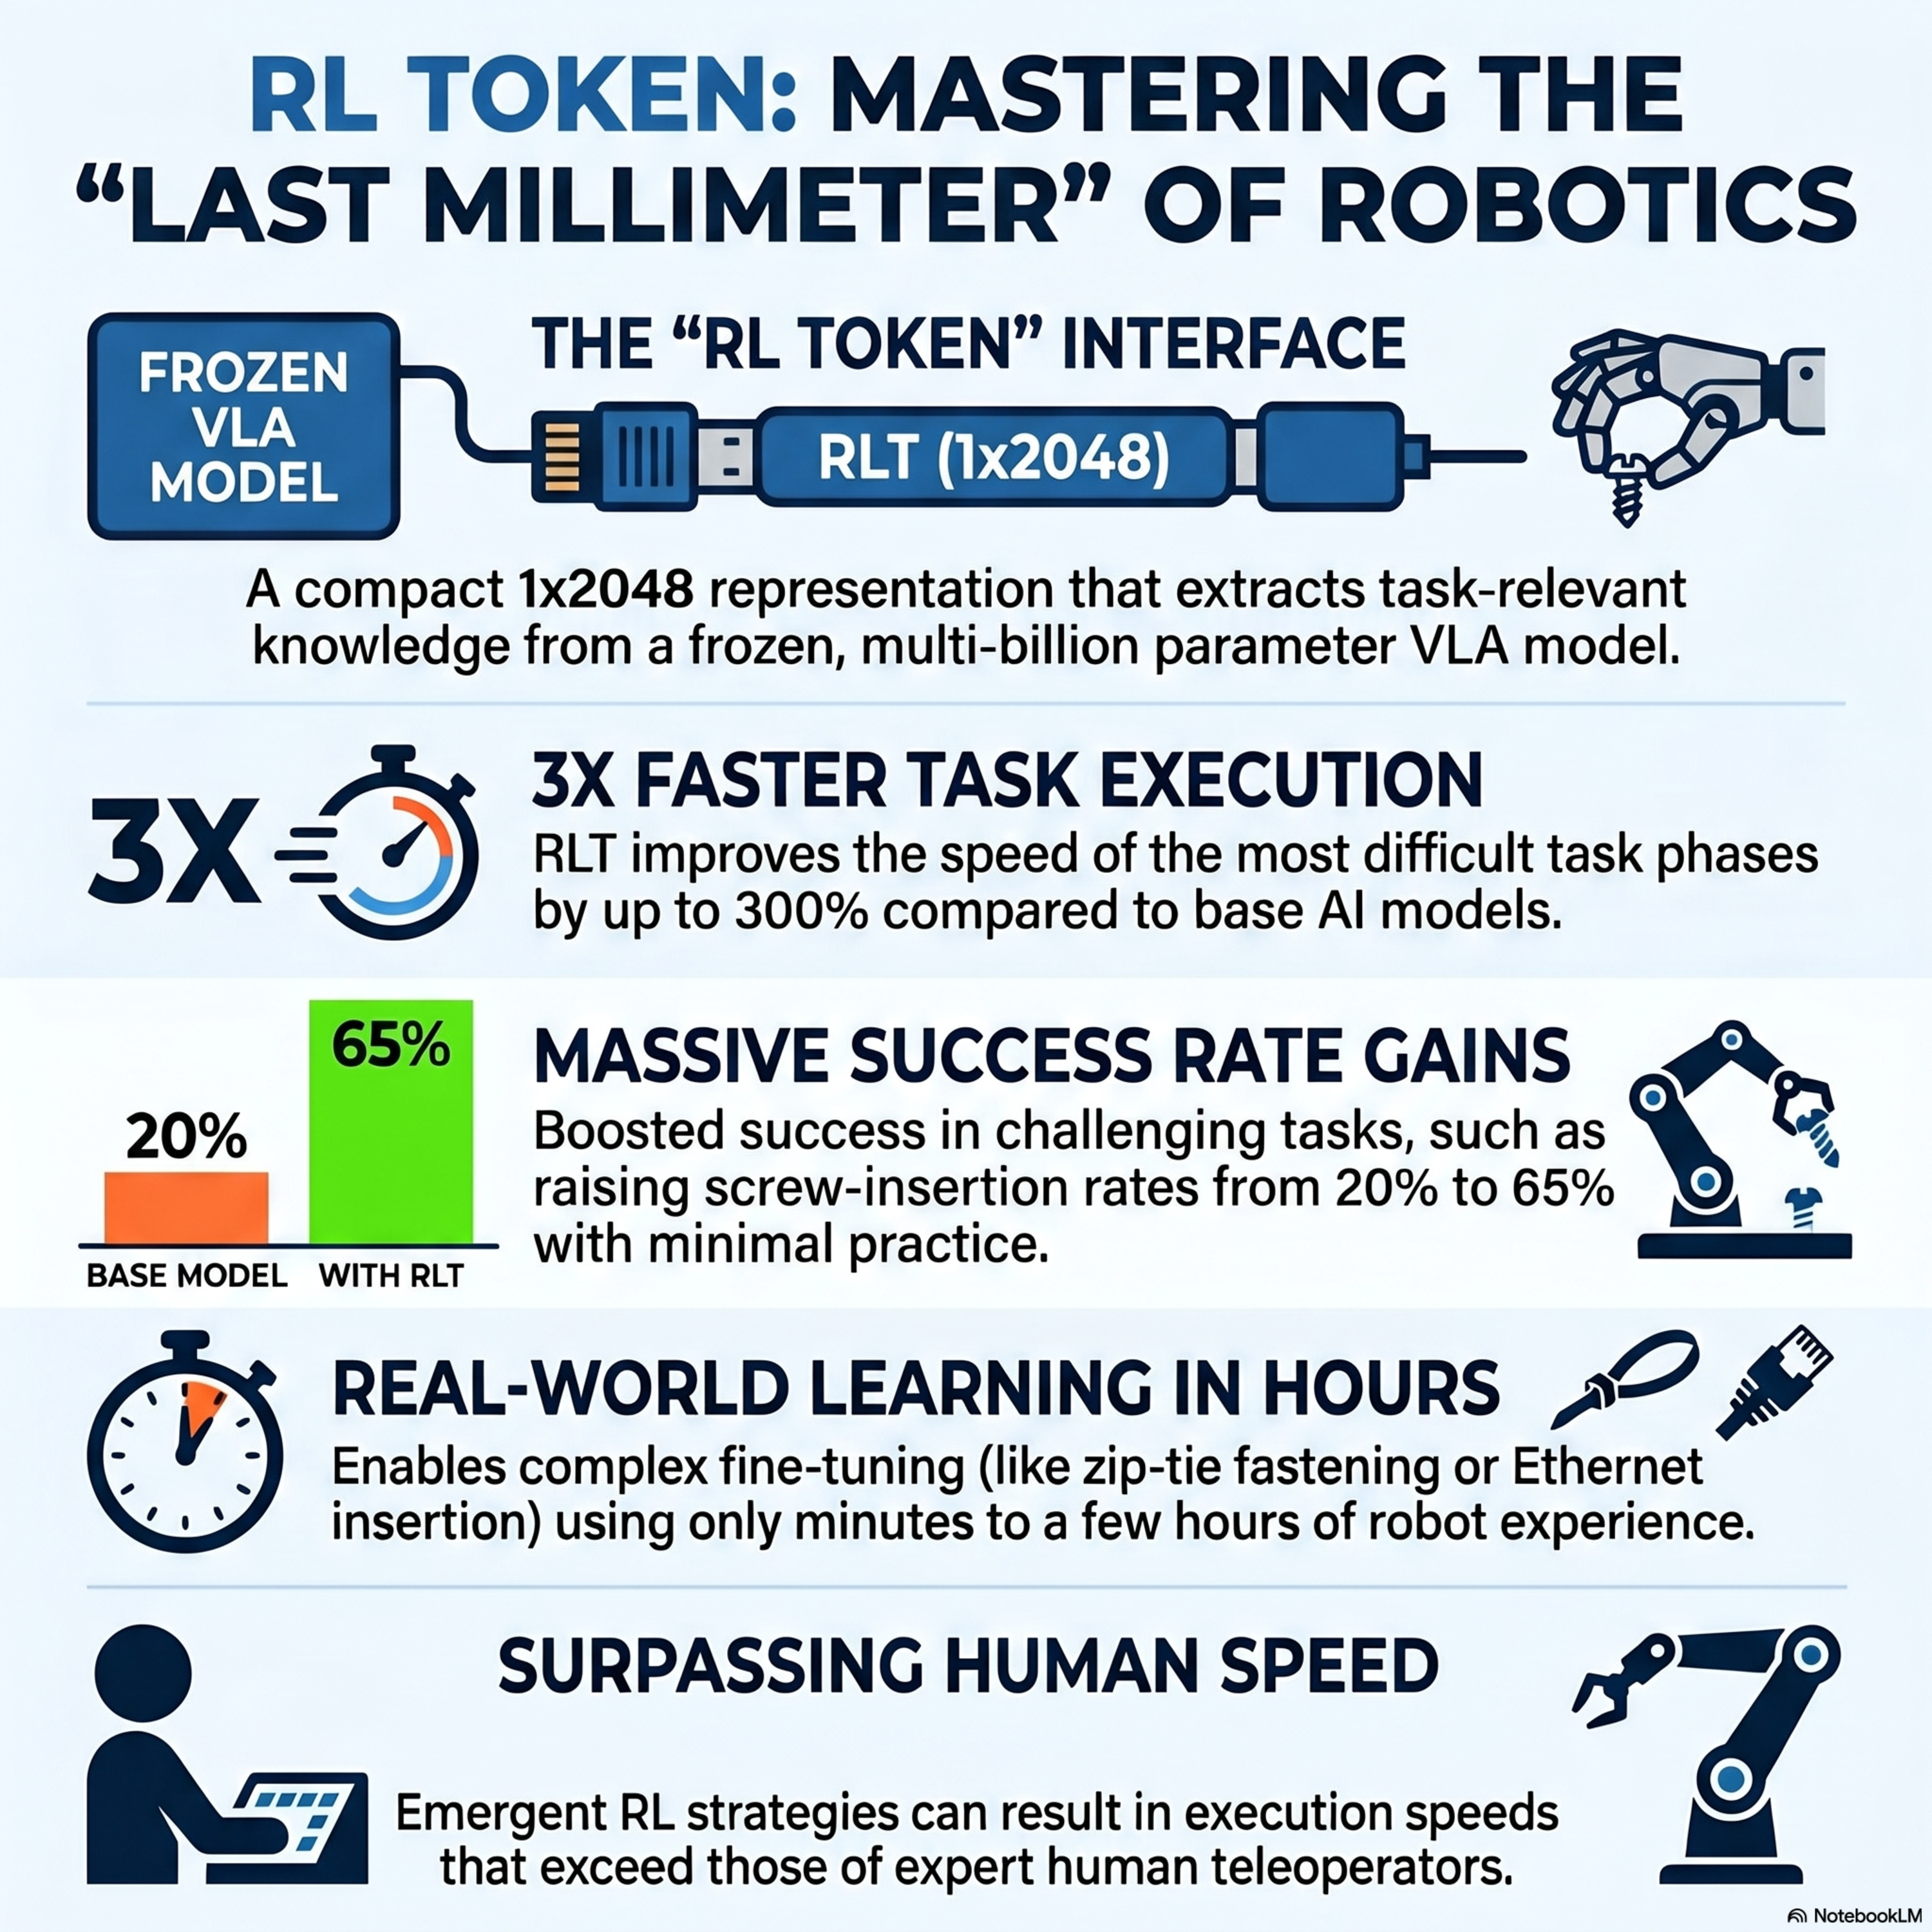
Researchers have introduced RLT, a lightweight method designed to enhance the precision and speed of vision-language-action (VLA) models through efficient online reinforcement learning. The system adapts large, pretrained VLAs by exposing an "RL token," a compressed representation that allows a small actor-critic network to refine robot movements without retraining the entire billion-parameter model. By focusing on the "critical phase" of complex maneuvers, RLT enables robots to master tasks requiring sub-millimeter precision, such as installing screws or fastening zip ties, in just a few hours. Experimental results demonstrate that this approach significantly increases success rates and execution speed, sometimes even surpassing the efficiency of expert human teleoperation. Ultimately, RLT bridges the gap between generalist model intelligence and the specialized accuracy needed for demanding real-world robot manipulation.
Embed this episode
No transcript yet.