Scaling Laws for Neural Language Models
from KnowledgeDB.ai Hosted by KnowledgeDB
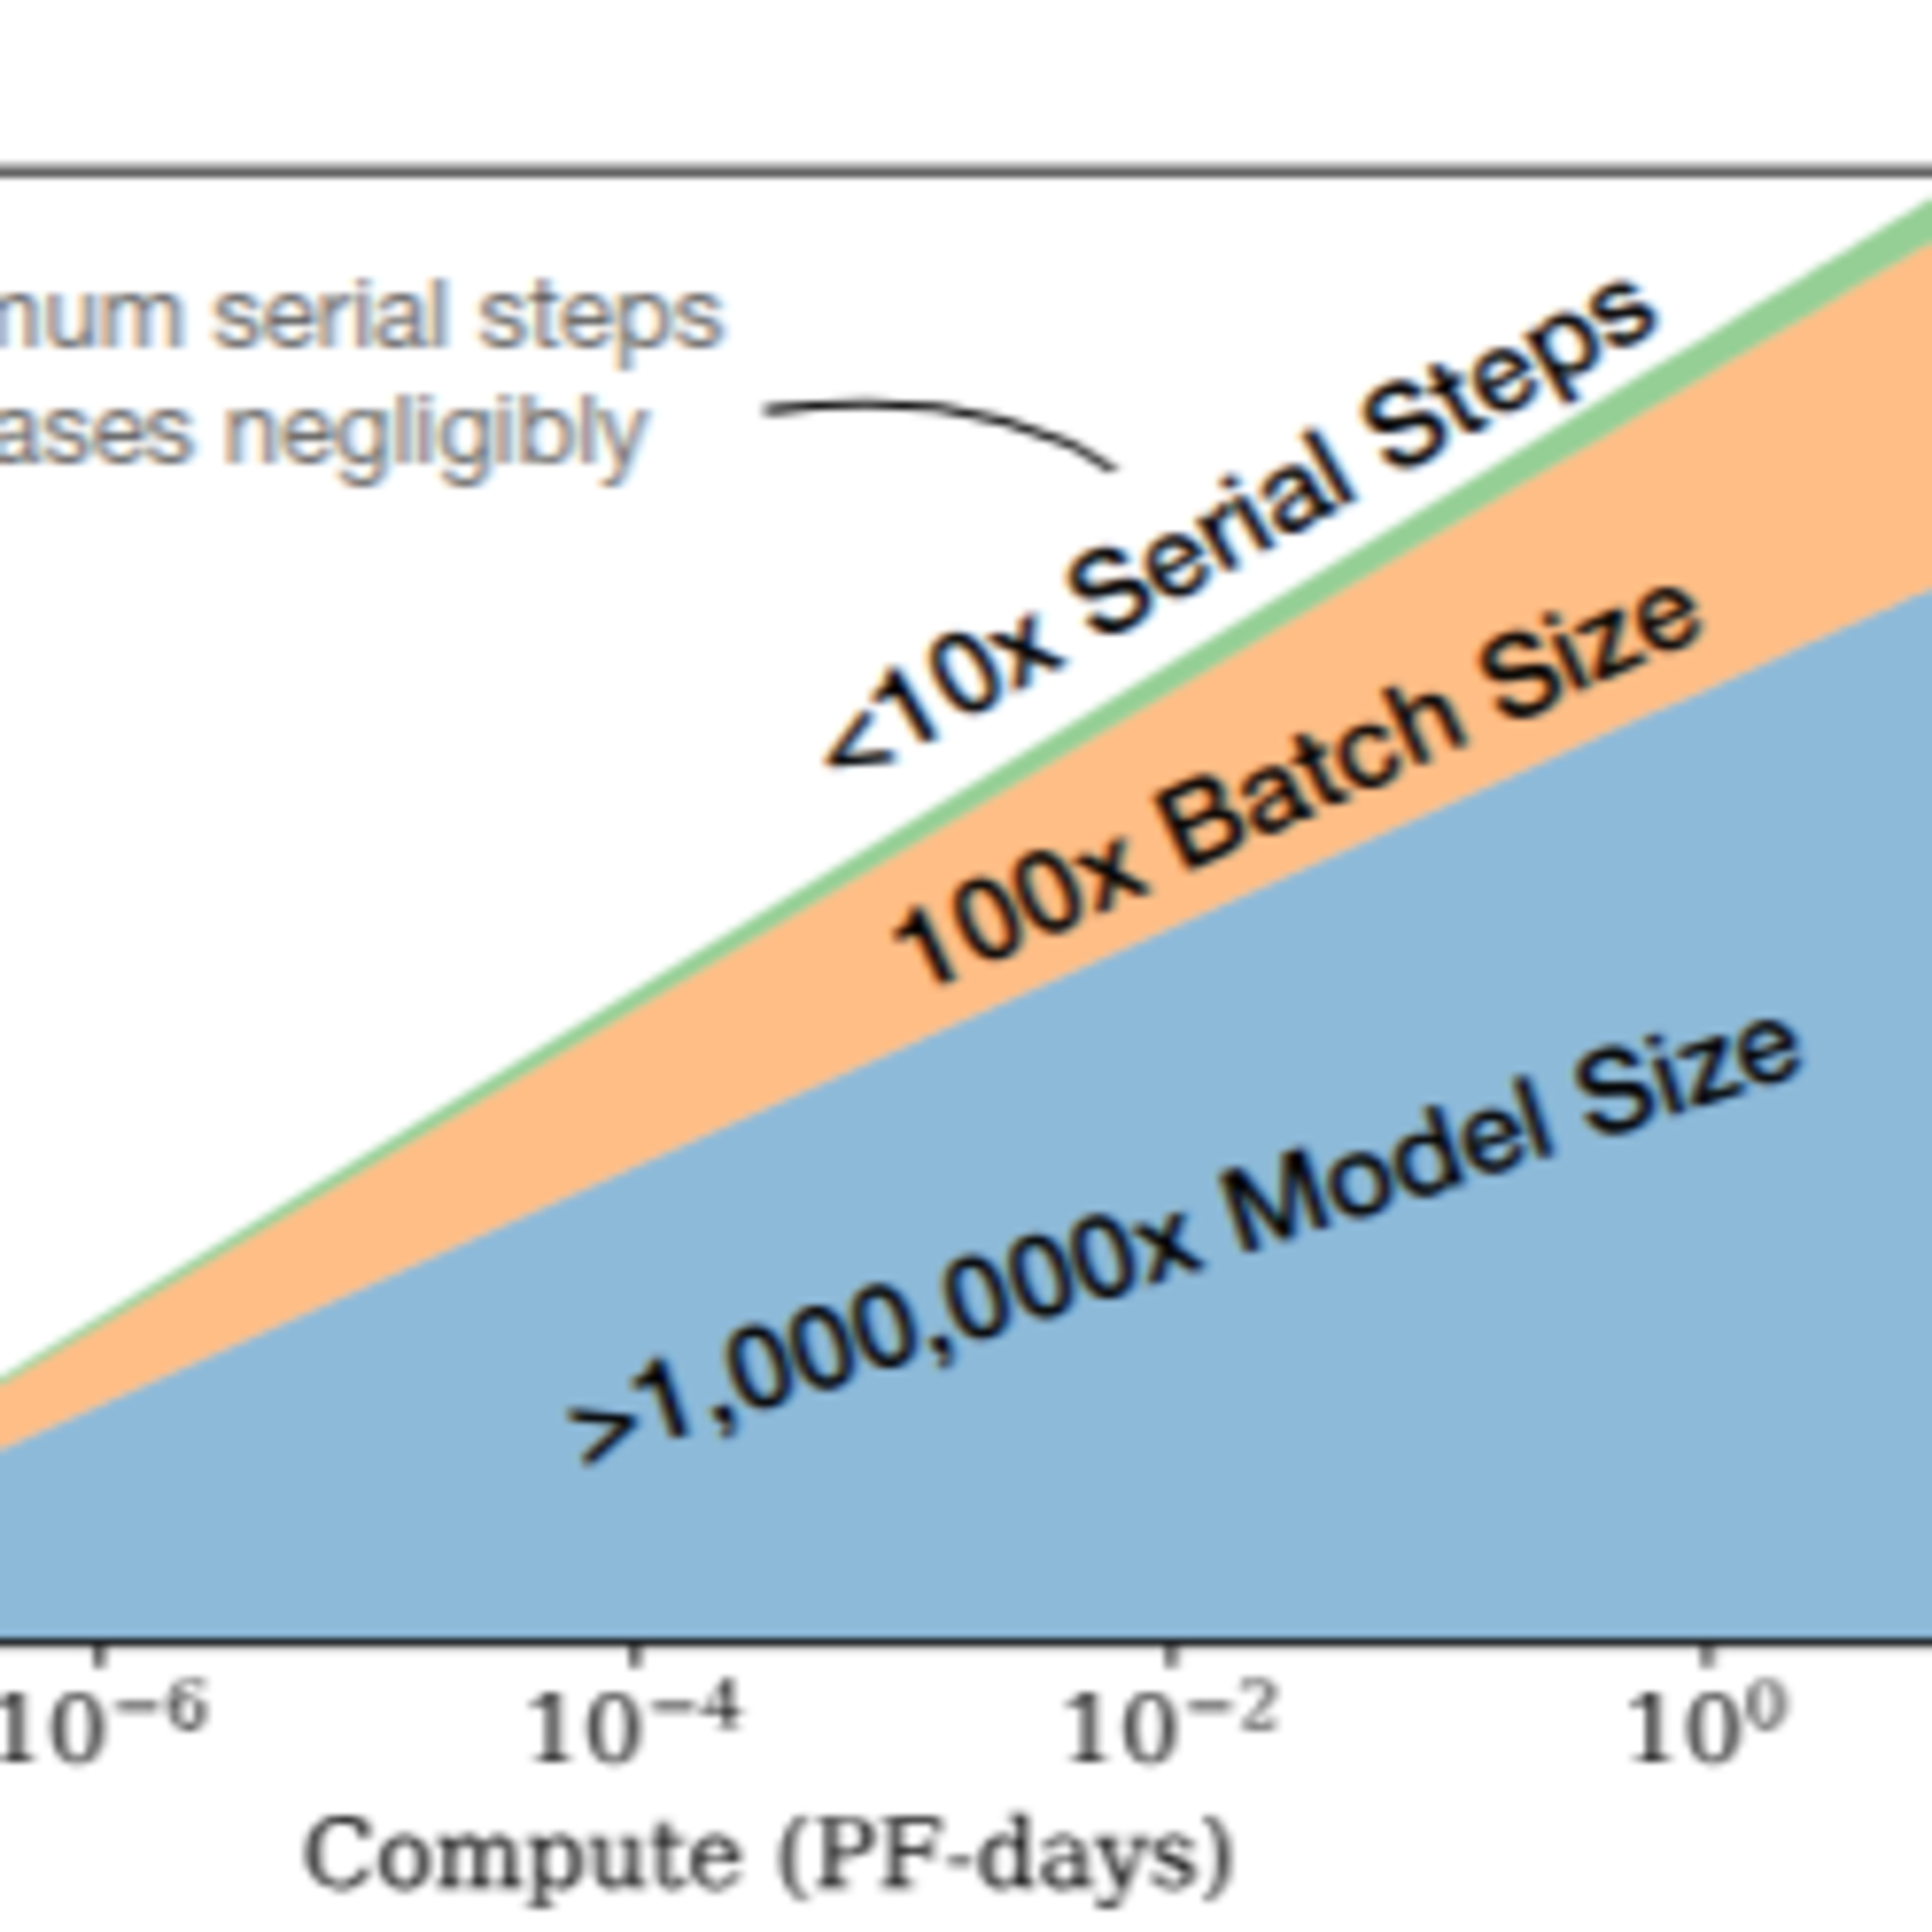
Ref: https://arxiv.org/abs/2001.08361 This research paper empirically investigates scaling laws for Transformer-based language models. The authors find that performance improves predictably with increases in model size, dataset size, and training compute, following power-law relationships across several orders of magnitude. Other architectural details have minimal impact. Optimally efficient training involves using very large models with relatively less data and stopping before convergence. The study also explores overfitting and provides equations to predict performance and optimal resource allocation.
Embed this episode
No transcript yet.