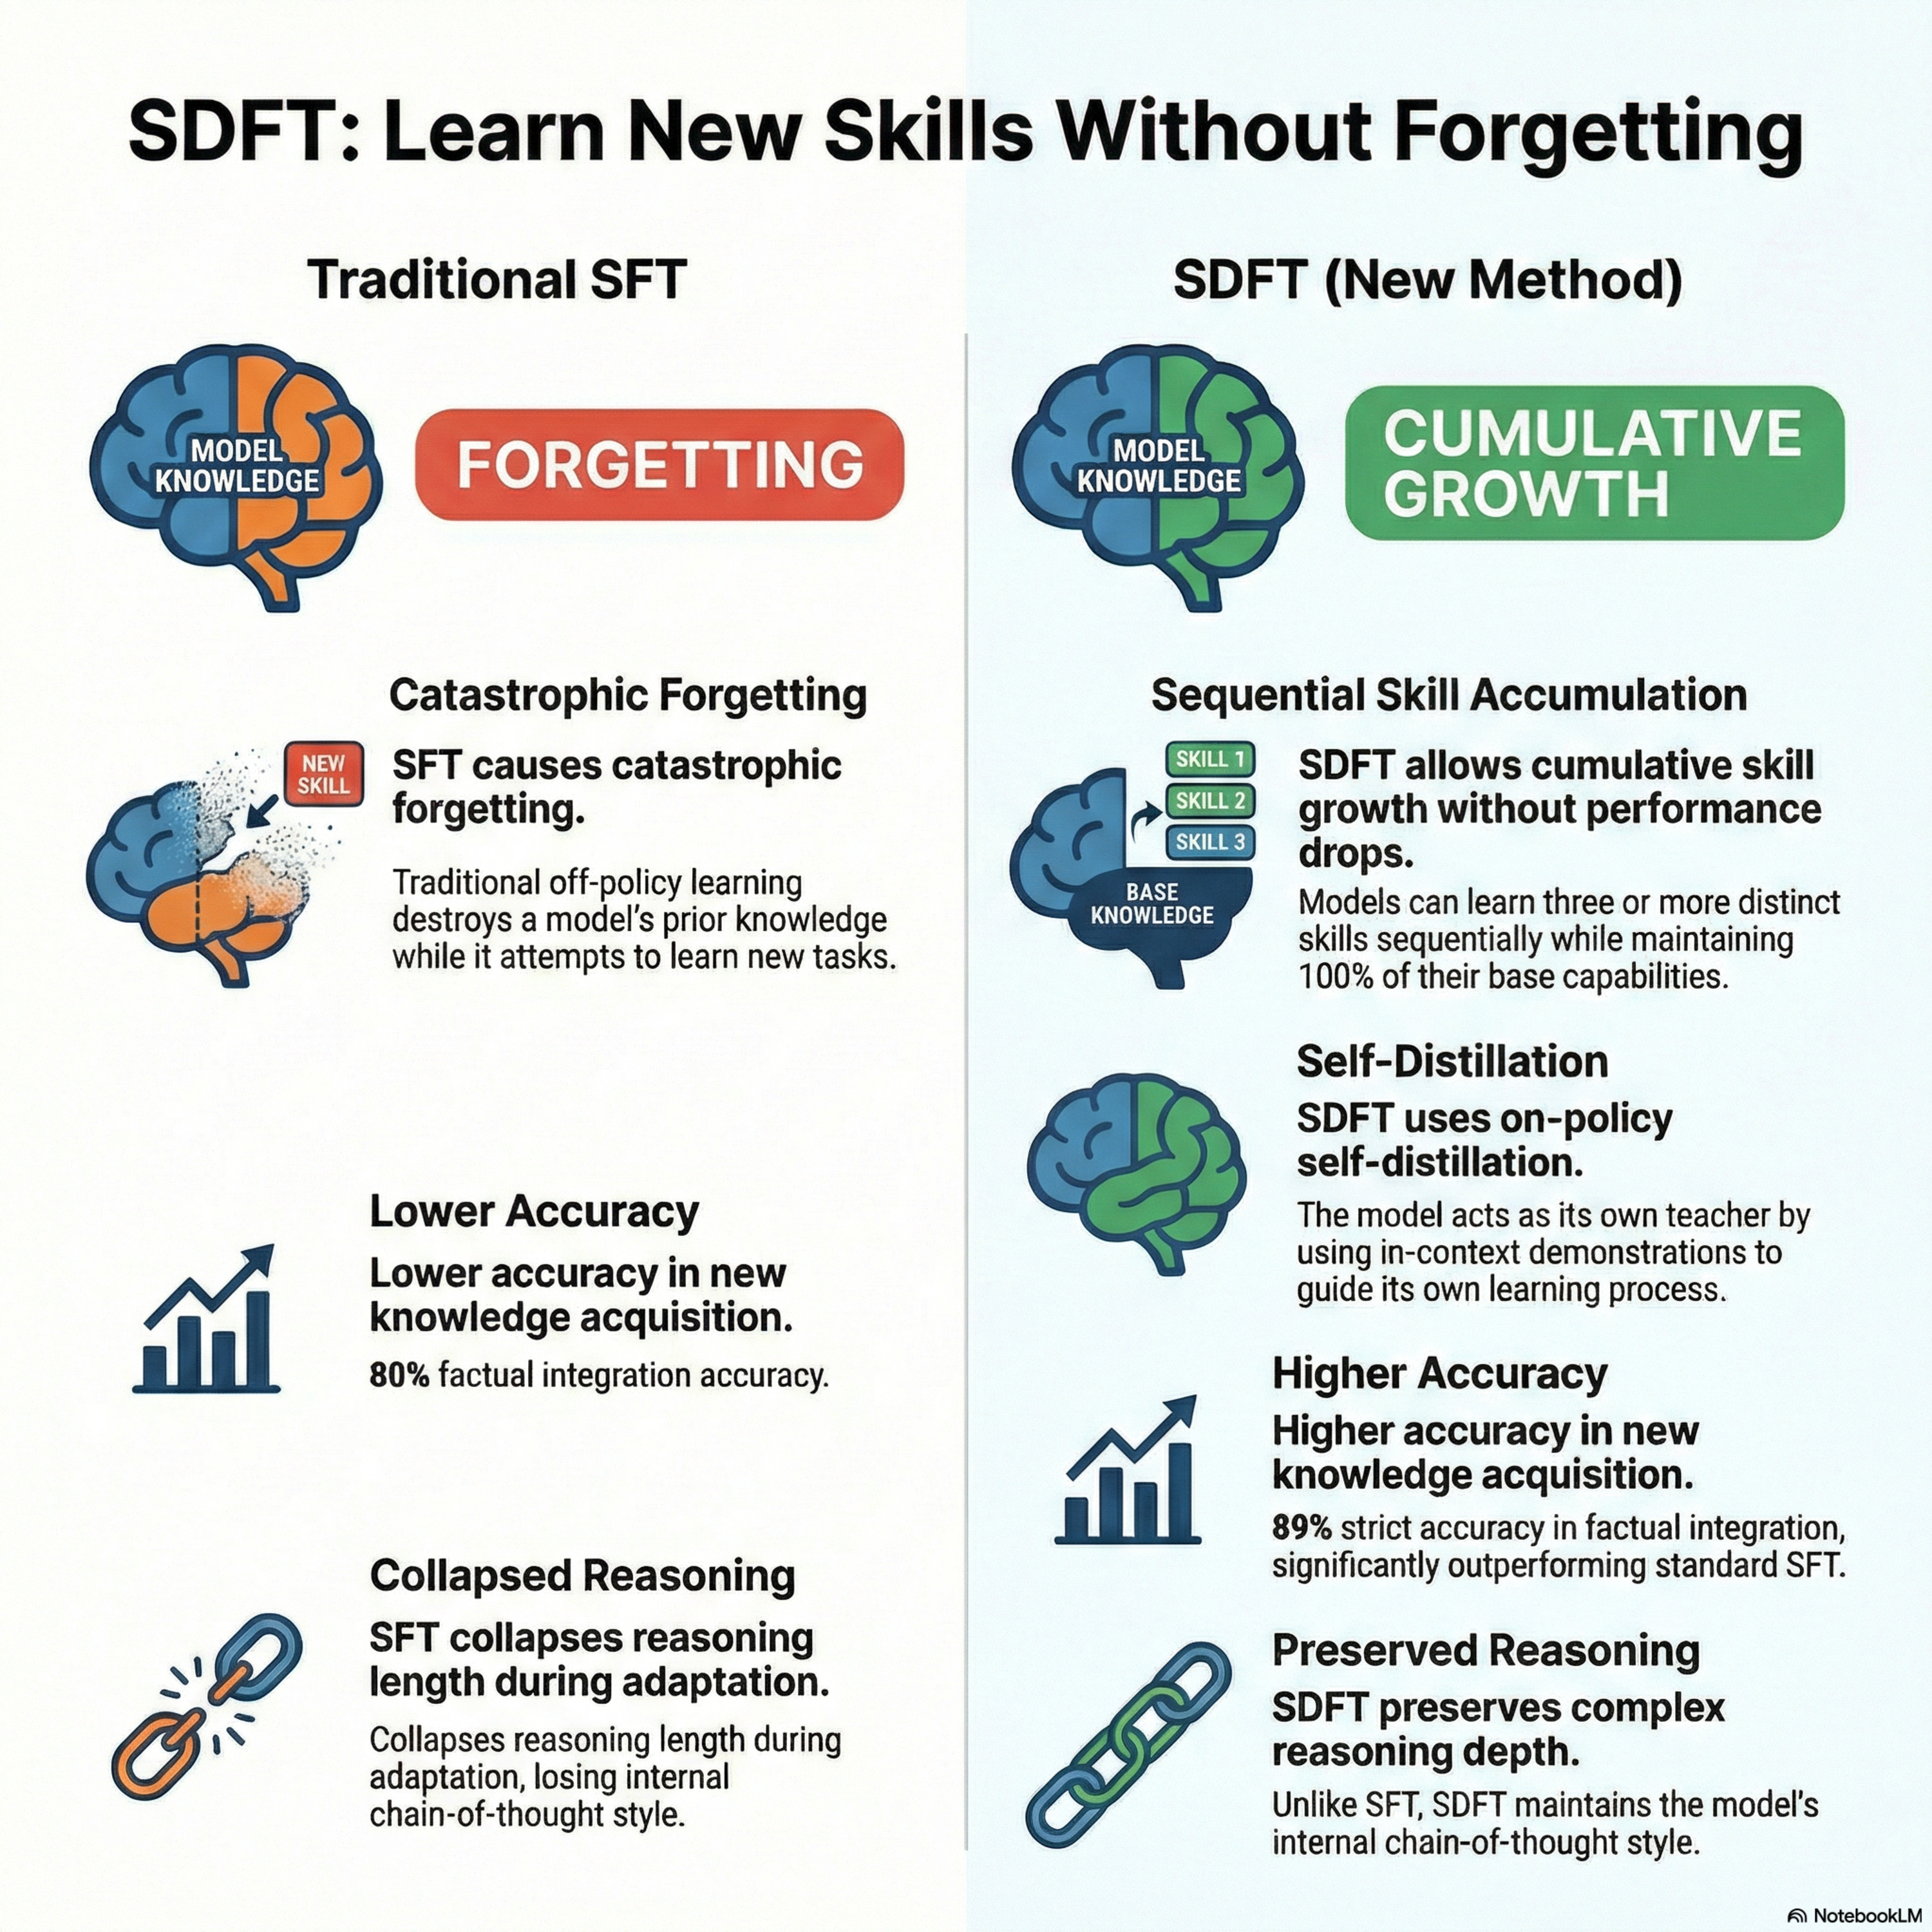
Self-distillation enables continual learning
from Best AI papers explained Hosted by Enoch H. Kang
This research introduces **Self-Distillation Fine-Tuning (SDFT)**, a novel on-policy learning method designed to help large language models acquire new skills without suffering from **catastrophic forgetting**. Unlike traditional supervised fine-tuning, which often causes models to lose prior knowledge, **SDFT** utilizes the model’s own **in-context learning** abilities by using a version of itself conditioned on demonstrations as a teacher. This approach generates **on-policy training signals** that allow the model to internalize new facts and reasoning patterns while remaining close to its original parameter distribution. Empirical results across **skill acquisition** and **knowledge injection** tasks show that **SDFT** consistently outperforms existing baselines in both task accuracy and the preservation of general capabilities. Ultimately, the research positions **self-distillation** as a practical and scalable path for enabling **continual learning** in foundation models.
Embed this episode
No transcript yet.