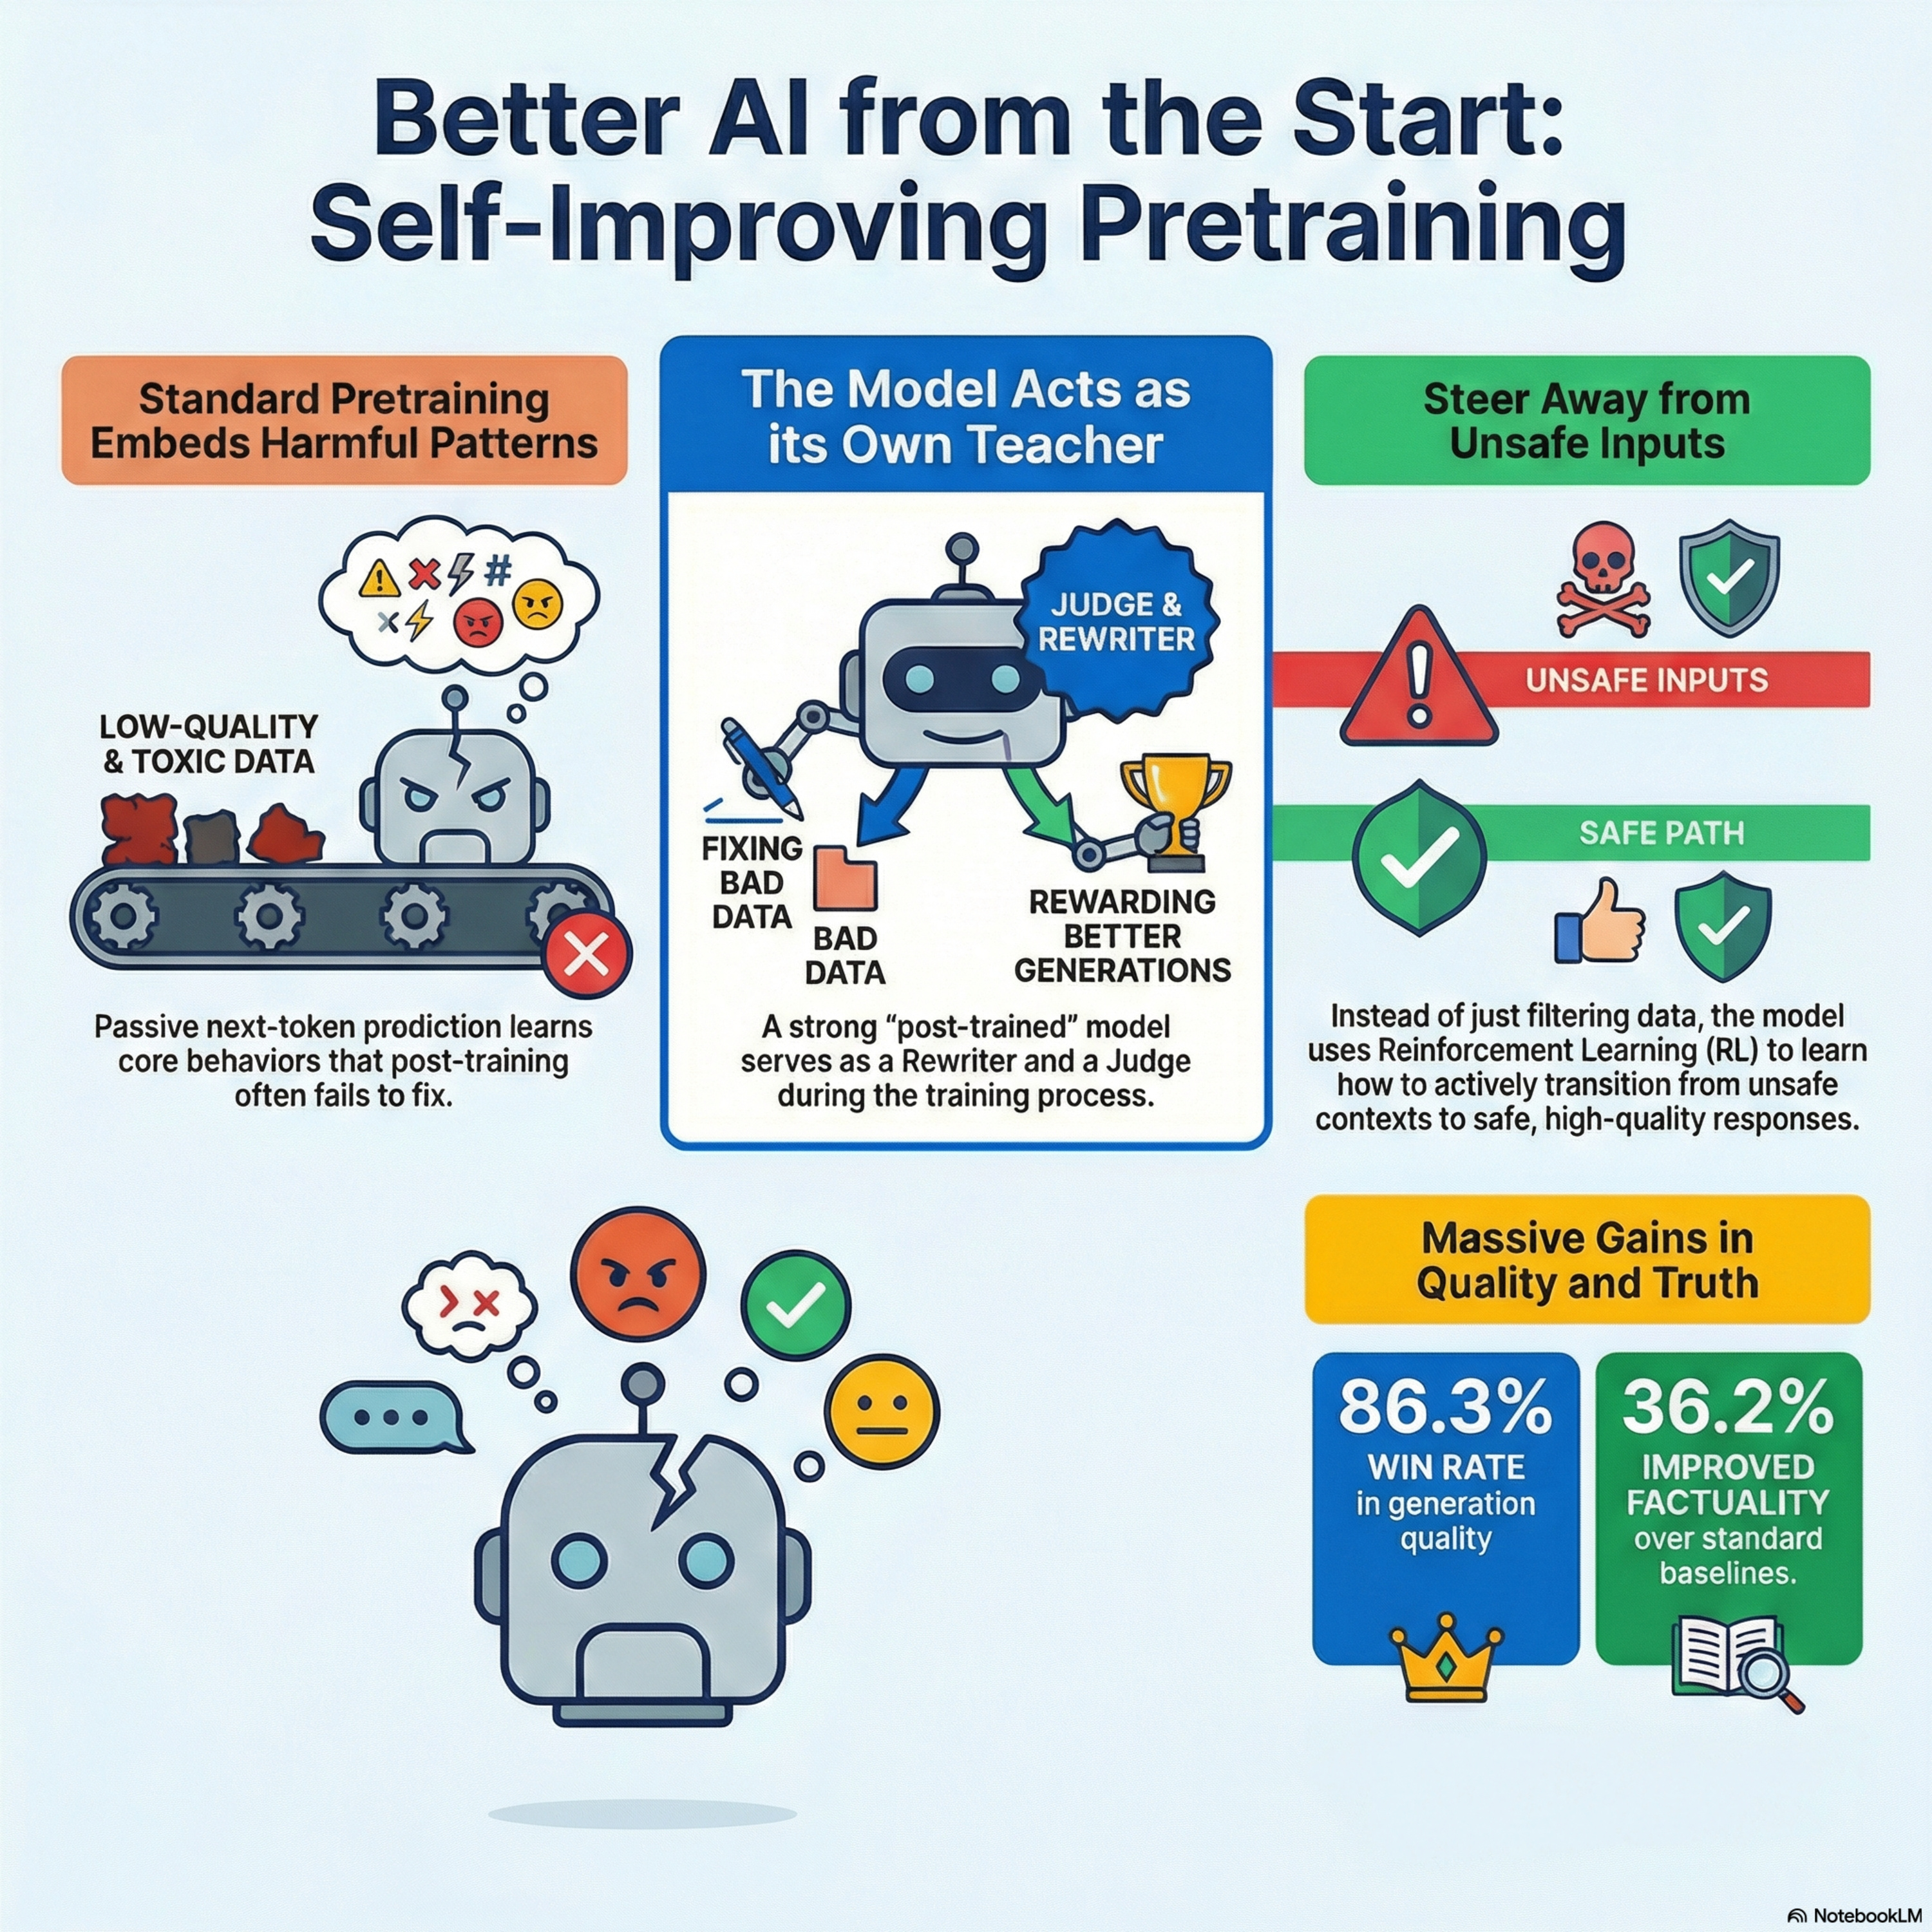
Self-Improving Pretraining: using post-trained models to pretrain better models
from Best AI papers explained Hosted by Enoch H. Kang
Researchers from Meta’s FAIR division introduced Self-Improving Pretraining, a novel framework that enhances large language models by integrating reinforcement learning and post-trained judges directly into the pretraining phase. Unlike standard next-token prediction, this method streams data and uses an existing high-quality model to rewrite suffixes and evaluate multiple model rollouts for quality, safety, and truthfulness. This approach ensures that core behaviors like factuality and safety are established from the start, rather than being treated as secondary corrections during fine-tuning. Experimental results demonstrate significant improvements, including a 36.2% increase in factuality and an 18.5% boost in safety compared to traditional baselines. Ultimately, the system allows models to learn how to steer away from low-quality content by rewarding superior generation candidates during the initial learning process.
Embed this episode
No transcript yet.