
EPISODE · Sep 27, 2026 · 21 MIN
Self-Play Pretraining with Zero Data
from Best AI papers explained · host Enoch H. Kang
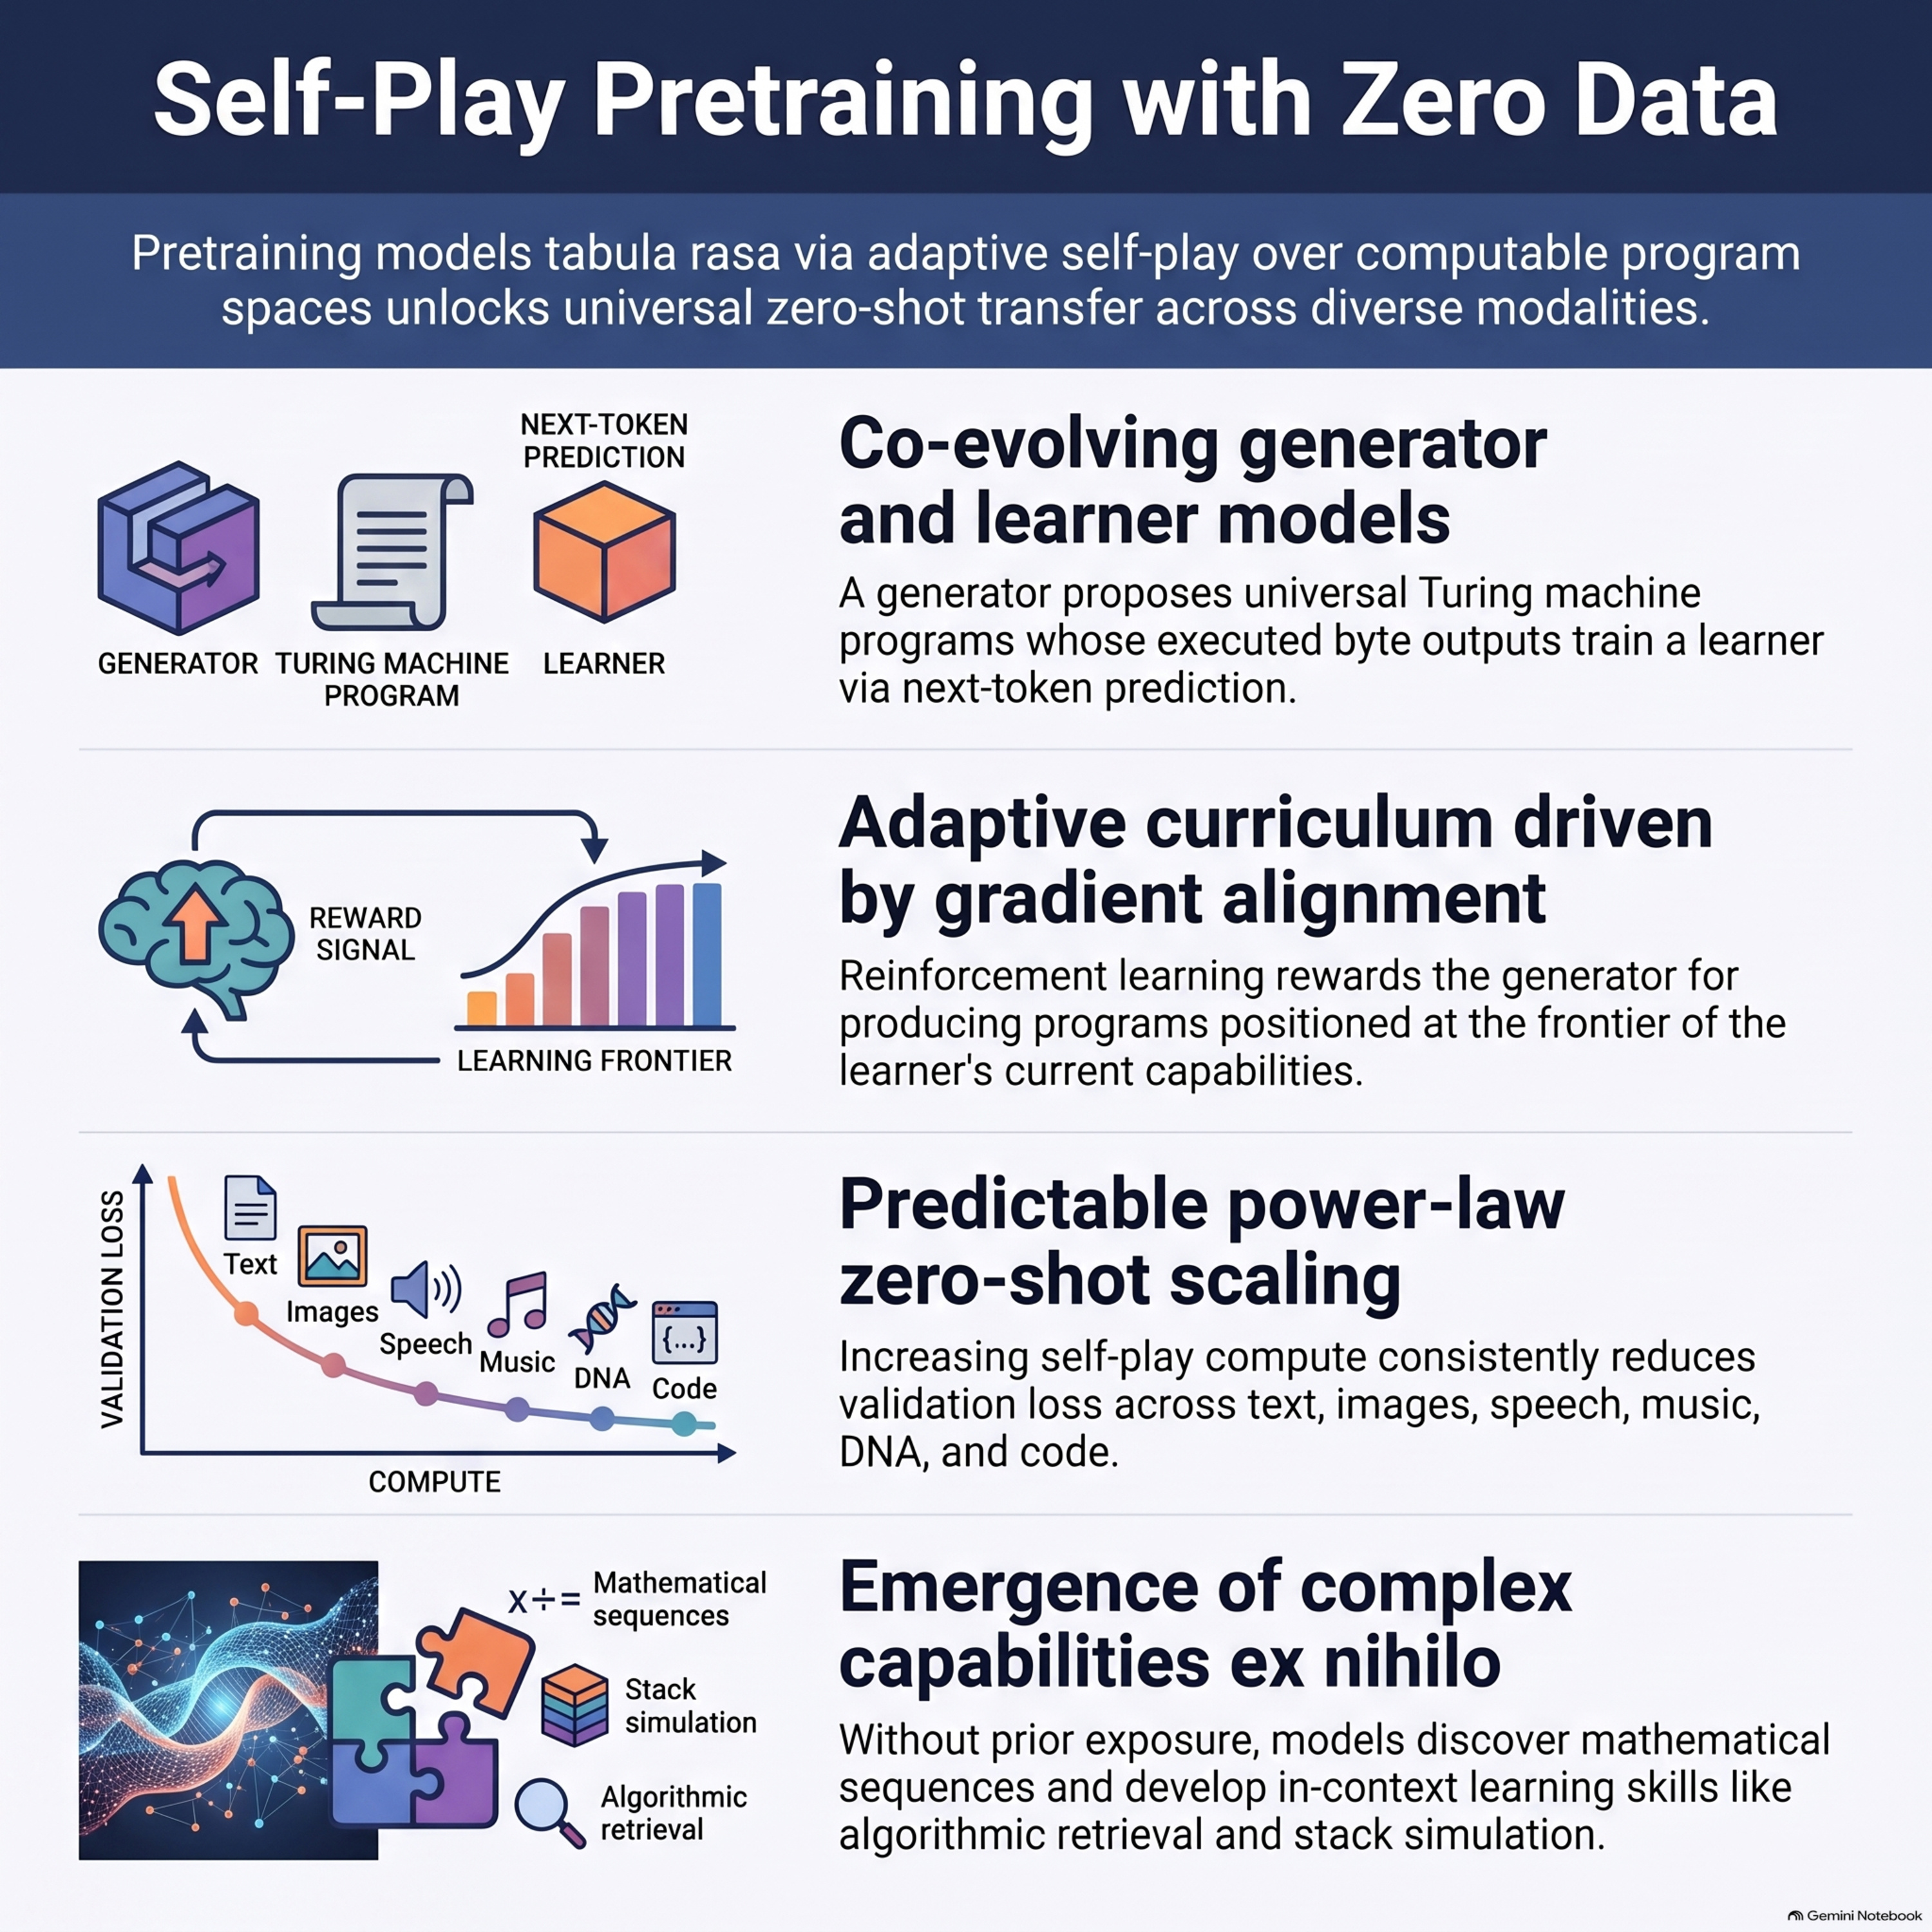
This paper introduces Self-Play Pretraining with Zero Data, a method for training language models using only synthetic data generated by the model itself. In this framework, a generator creates programs for a universal Turing machine while a learner is trained to predict the resulting byte sequences. A reinforcement learning objective drives the generator to produce increasingly complex data at the frontier of the learner's capabilities, creating an adaptive curriculum. This process allows models to discover universal predictive structures, such as mathematical sequences and logical recursion, without exposure to human-authored text. Experiments demonstrate that this tabula rasa approach yields predictable scaling laws and improves performance on diverse real-world tasks. Ultimately, the research suggests that self-generated experience can bootstrap foundational reasoning and in-context learning skills from scratch.
Embed this episode
Ready to play
Self-Play Pretraining with Zero Data
No transcript for this episode yet
Similar Episodes
No similar episodes found.