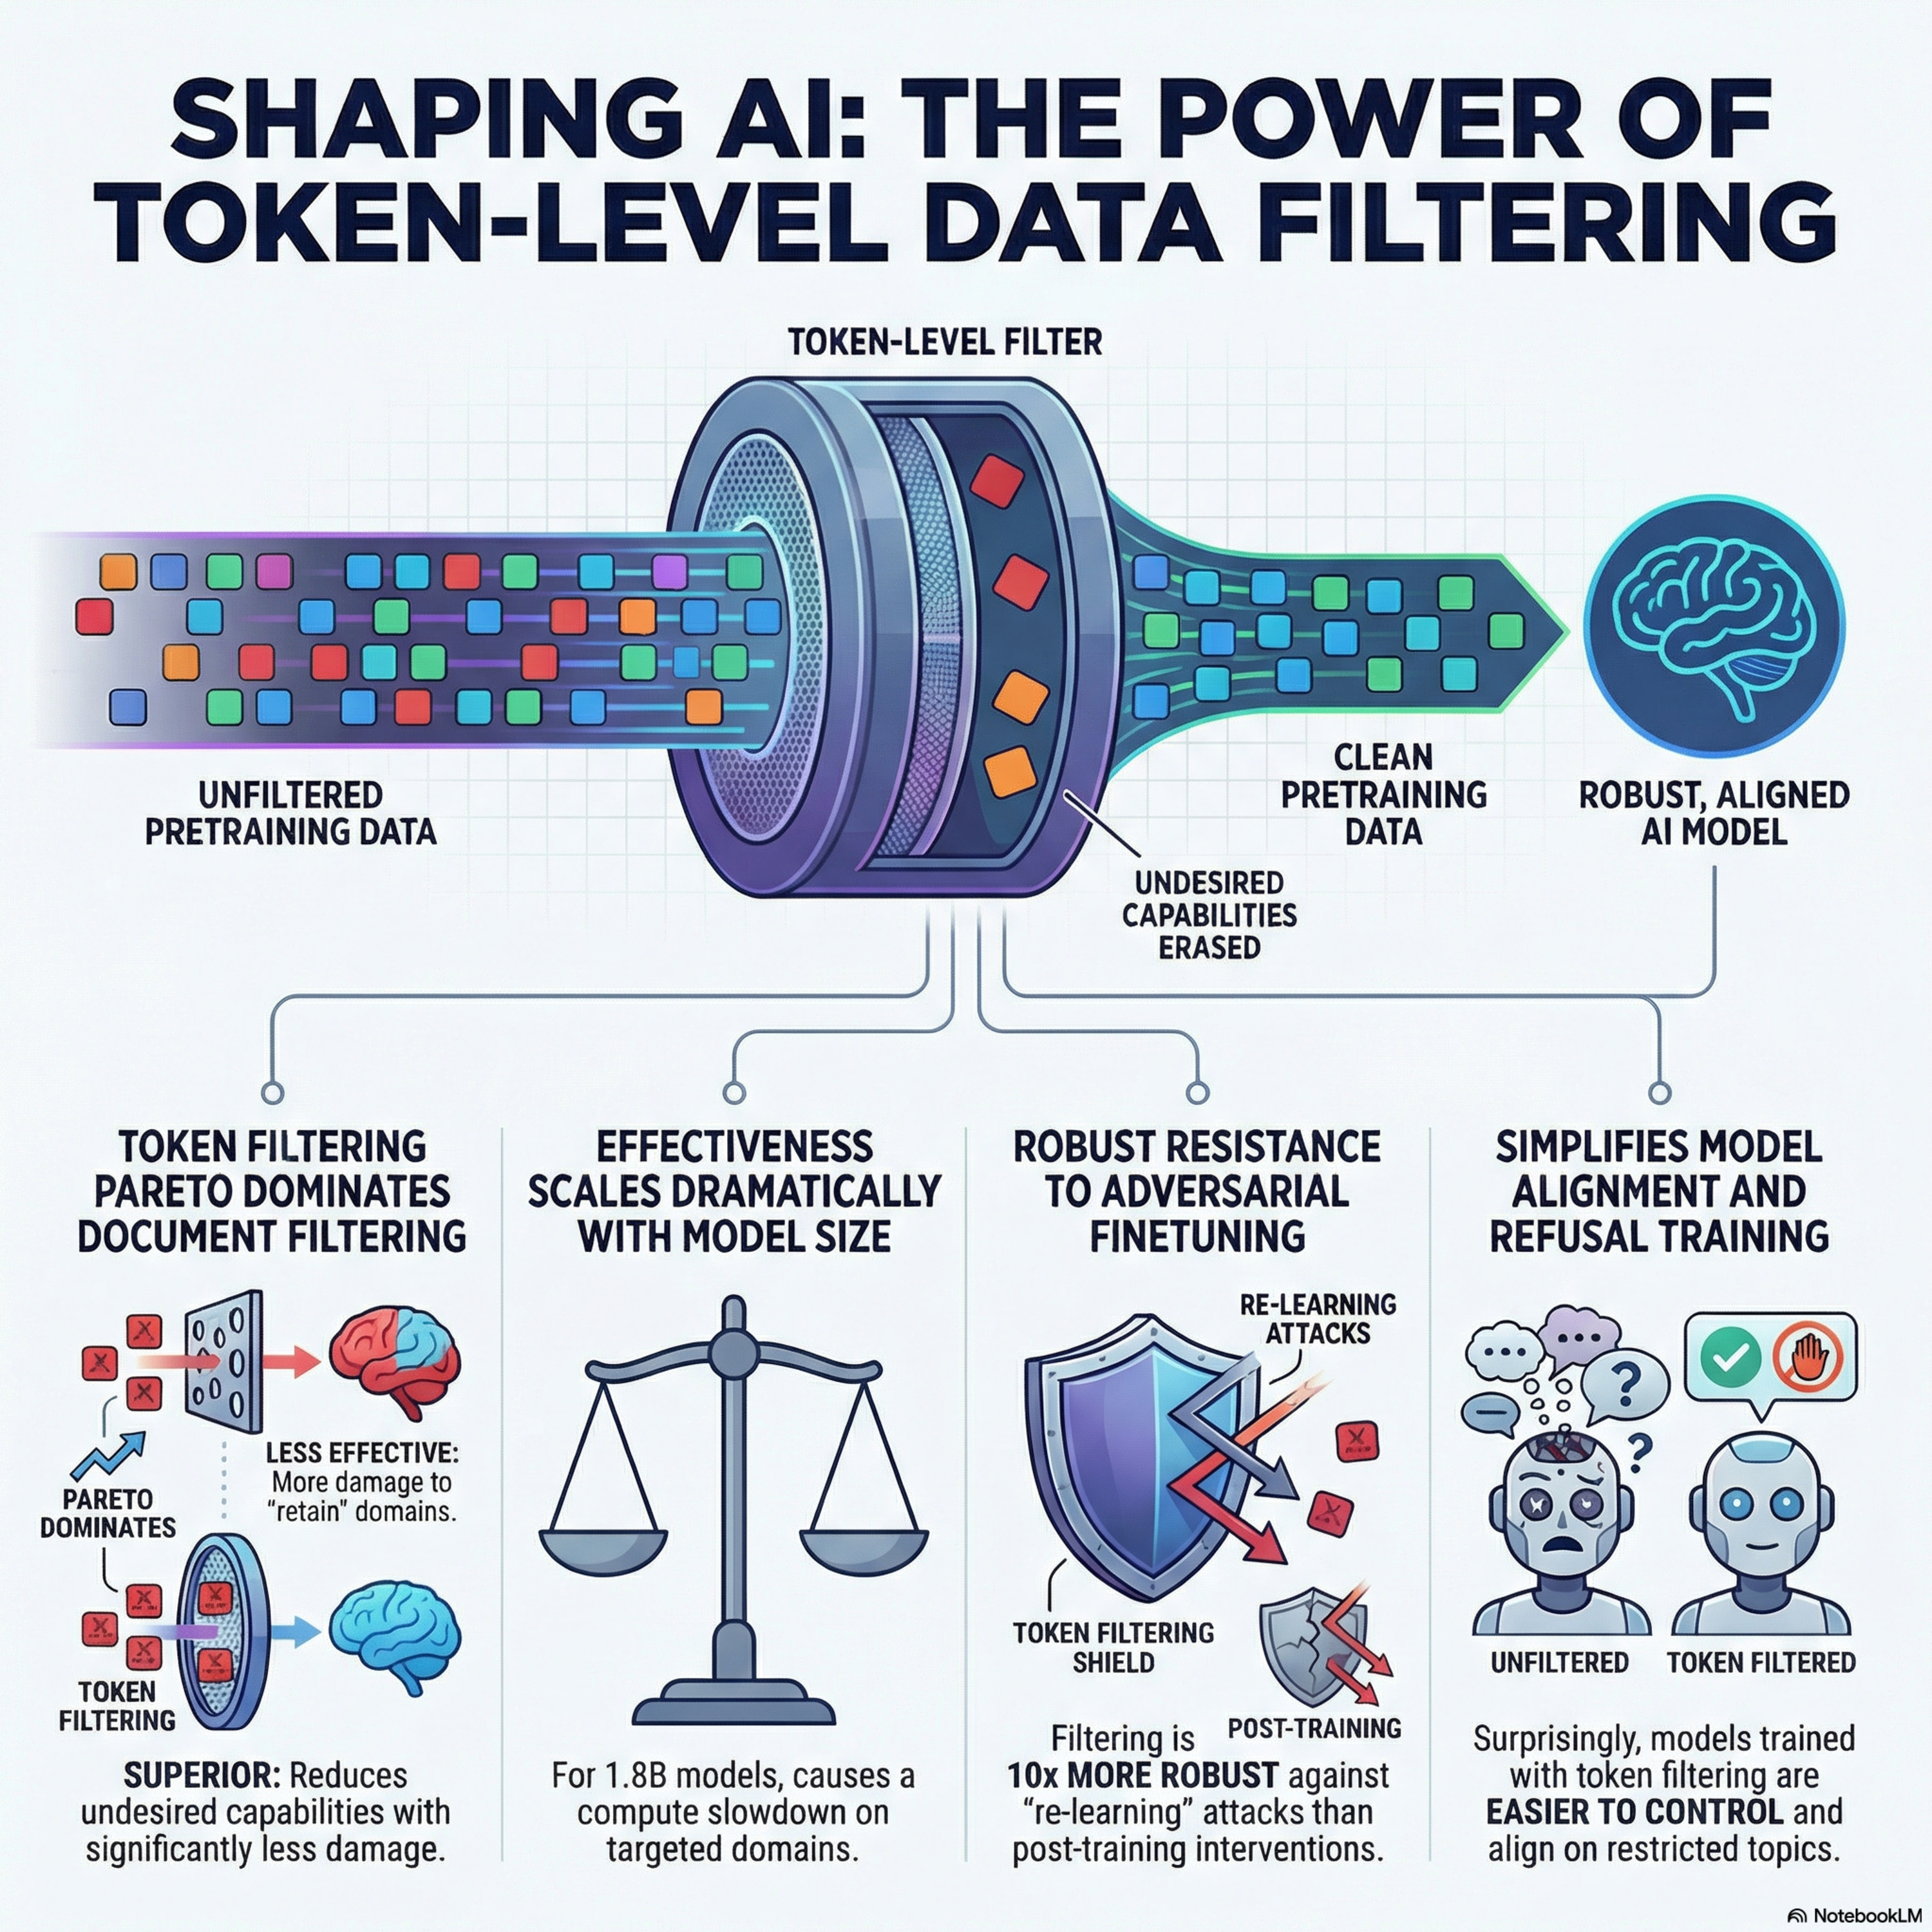
Shaping capabilities with token-level data filtering
from Best AI papers explained Hosted by Enoch H. Kang
This paper explores pretraining data filtering as a robust strategy for shaping the capabilities of large language models, specifically by selectively removing undesired knowledge like medical or hazardous information. Research indicates that token-level filtering is more precise and efficient than document-level approaches, allowing models to retain general performance while significantly increasing the difficulty for adversaries to recover suppressed traits. As pretraining compute scales, this method becomes exponentially more effective, resulting in a 7000x compute slowdown for those attempting to relearn the "forgotten" domain. Furthermore, models trained via this method remain corrigible and easier to align, debunking concerns that removing data makes them harder to control. The authors also introduce a scalable pipeline using sparse autoencoders to generate high-quality labels from weak or noisy supervision. Ultimately, the study advocates for intervention during pretraining as a foundational, tamper-resistant layer for AI safety and security.
Embed this episode
No transcript yet.