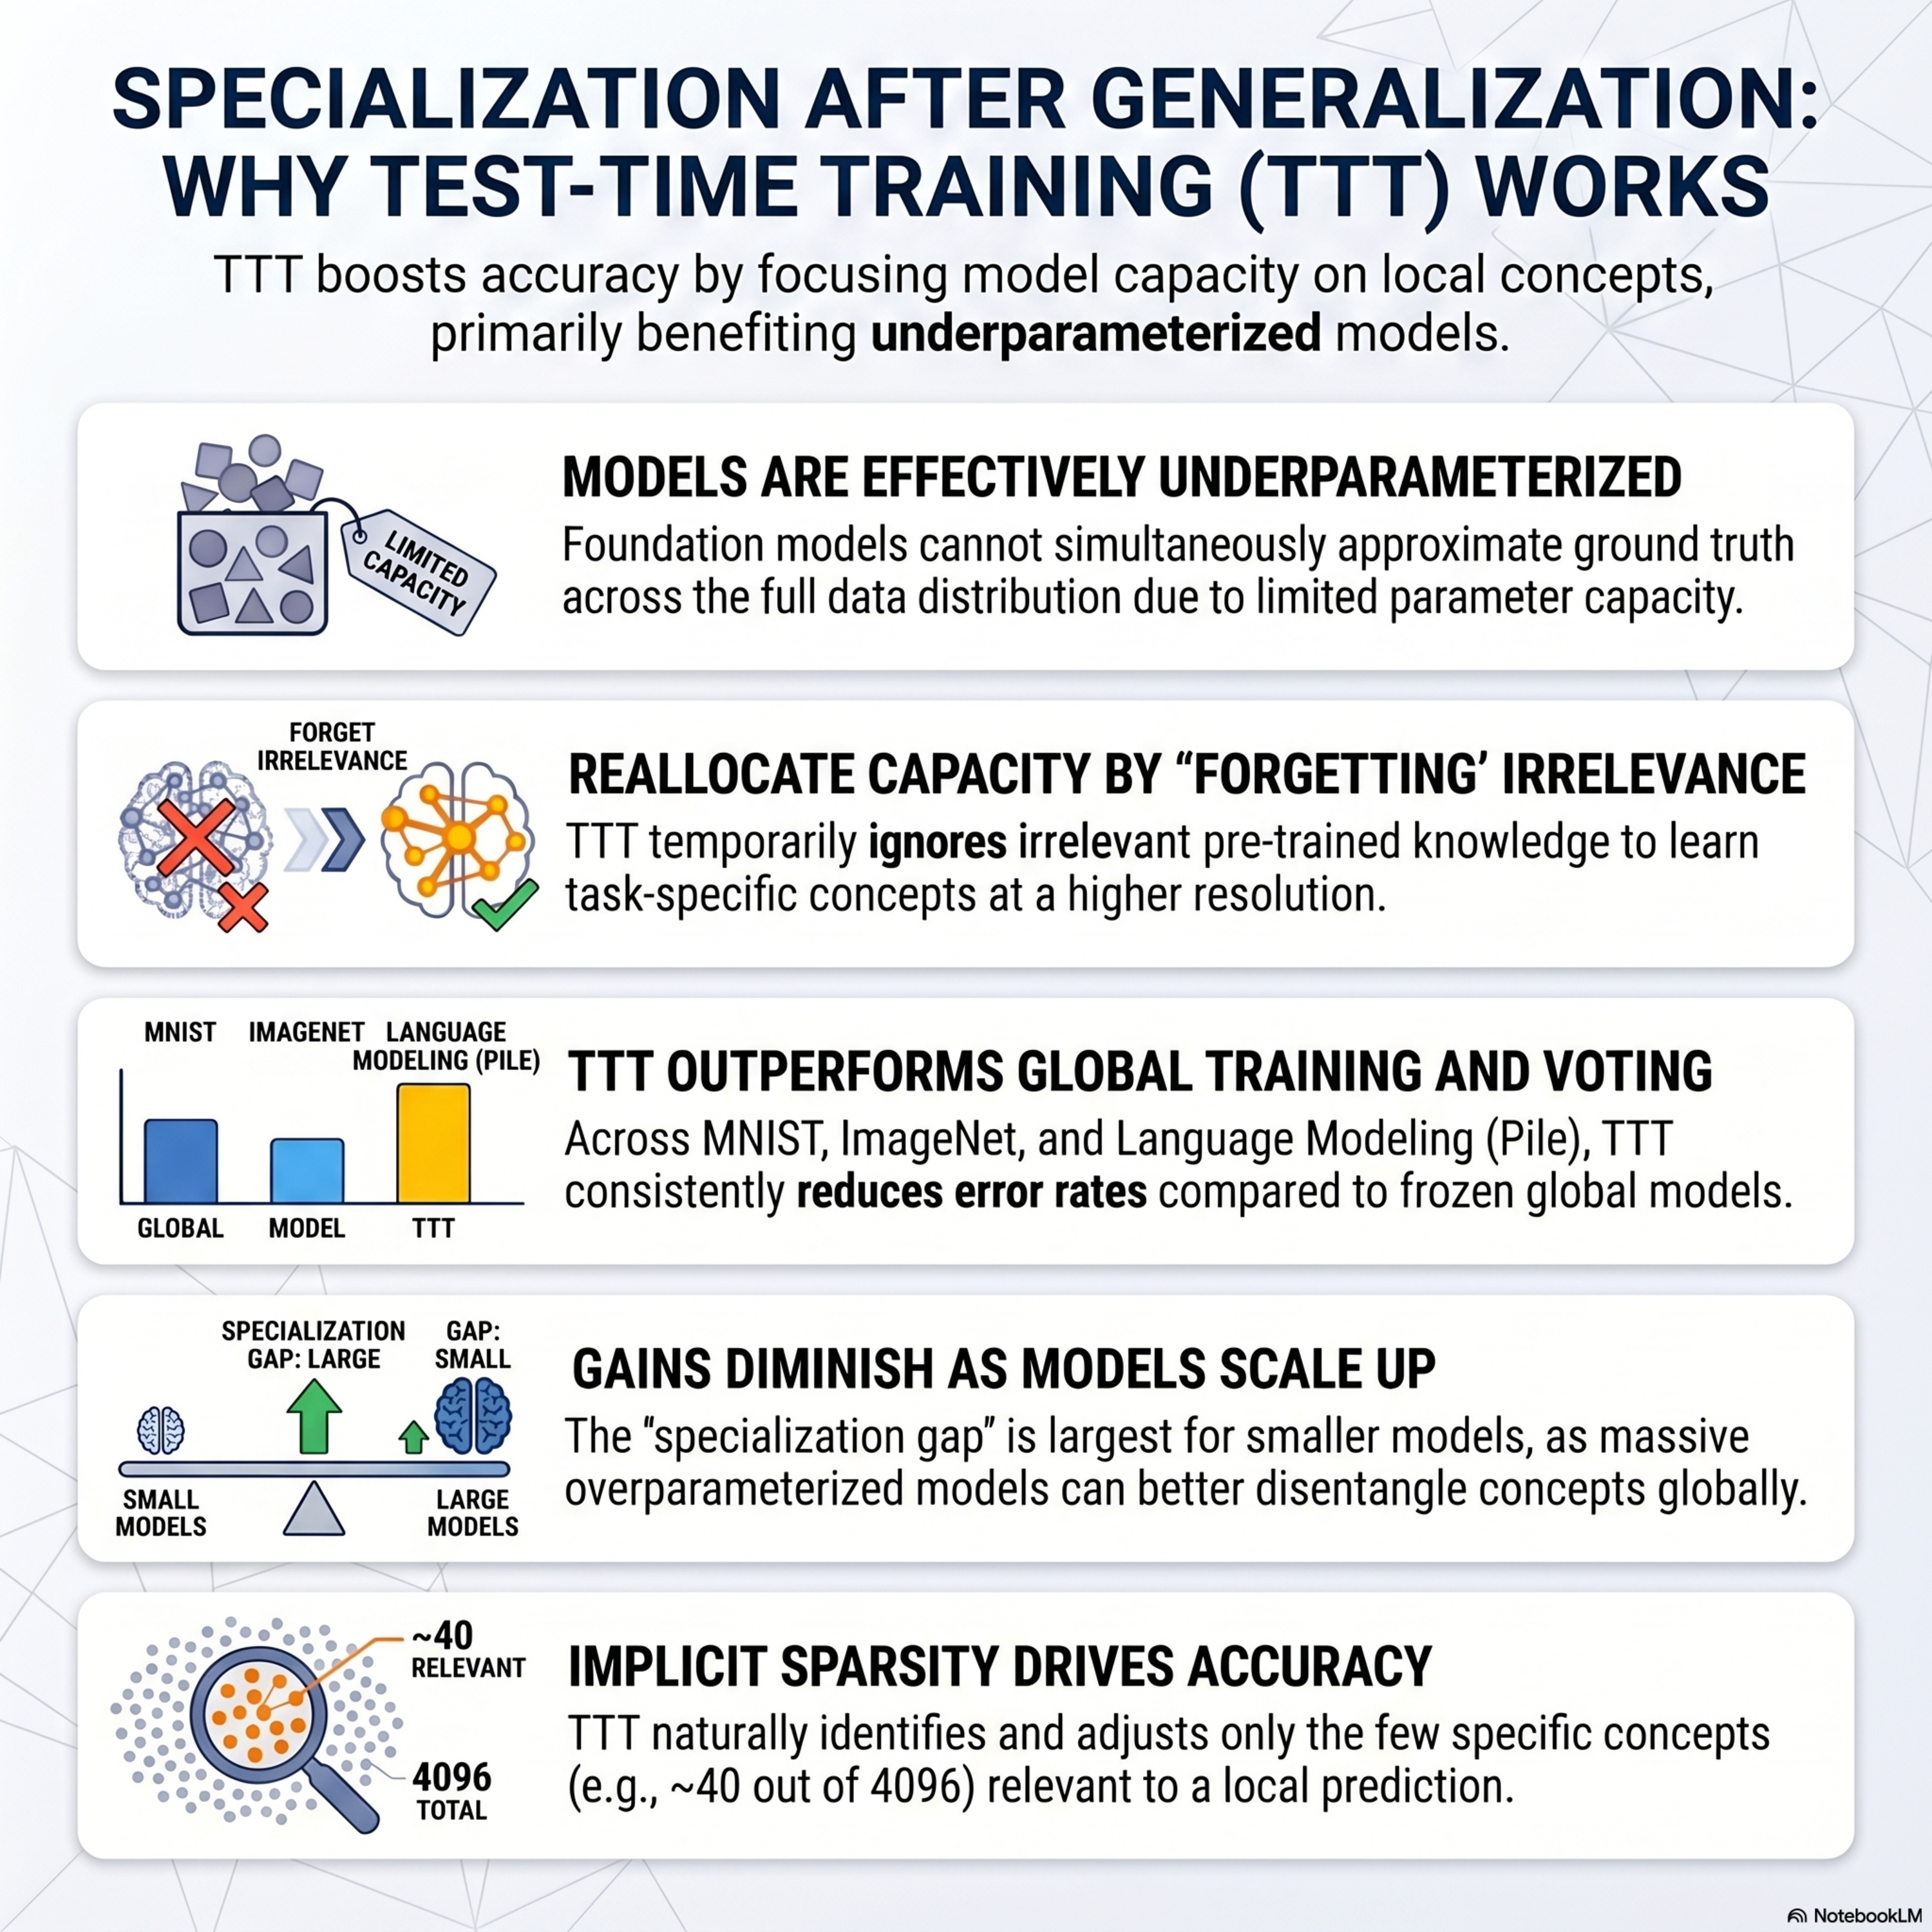
Specialization after generalization: towards understanding test-time training in foundation models
from Best AI papers explained Hosted by Enoch H. Kang
This research paper investigates test-time training (TTT) in foundation models, proposing that these large-scale networks remain globally underparameterized despite their massive size. The authors introduce the concept of specialization after generalization, where a model improves its performance by temporarily focusing its capacity on task-specific concepts. Using the linear representation hypothesis, the study demonstrates that TTT allows a model to effectively "disentangle" relevant semantic features that are otherwise superimposed in its dense activations. Empirical experiments on ImageNet, MNIST, and language modeling confirm that TTT yields significant accuracy gains, particularly when the model size is small relative to the complexity of the data. Ultimately, the work provides a theoretical and practical framework showing that test-time adaptation is a powerful mechanism for overcoming the capacity limitations of static, pre-trained models.
Embed this episode
No transcript yet.