Stabilizing Reinforcement Learning with LLMs: Formulation and Practices
from Best AI papers explained Hosted by Enoch H. Kang
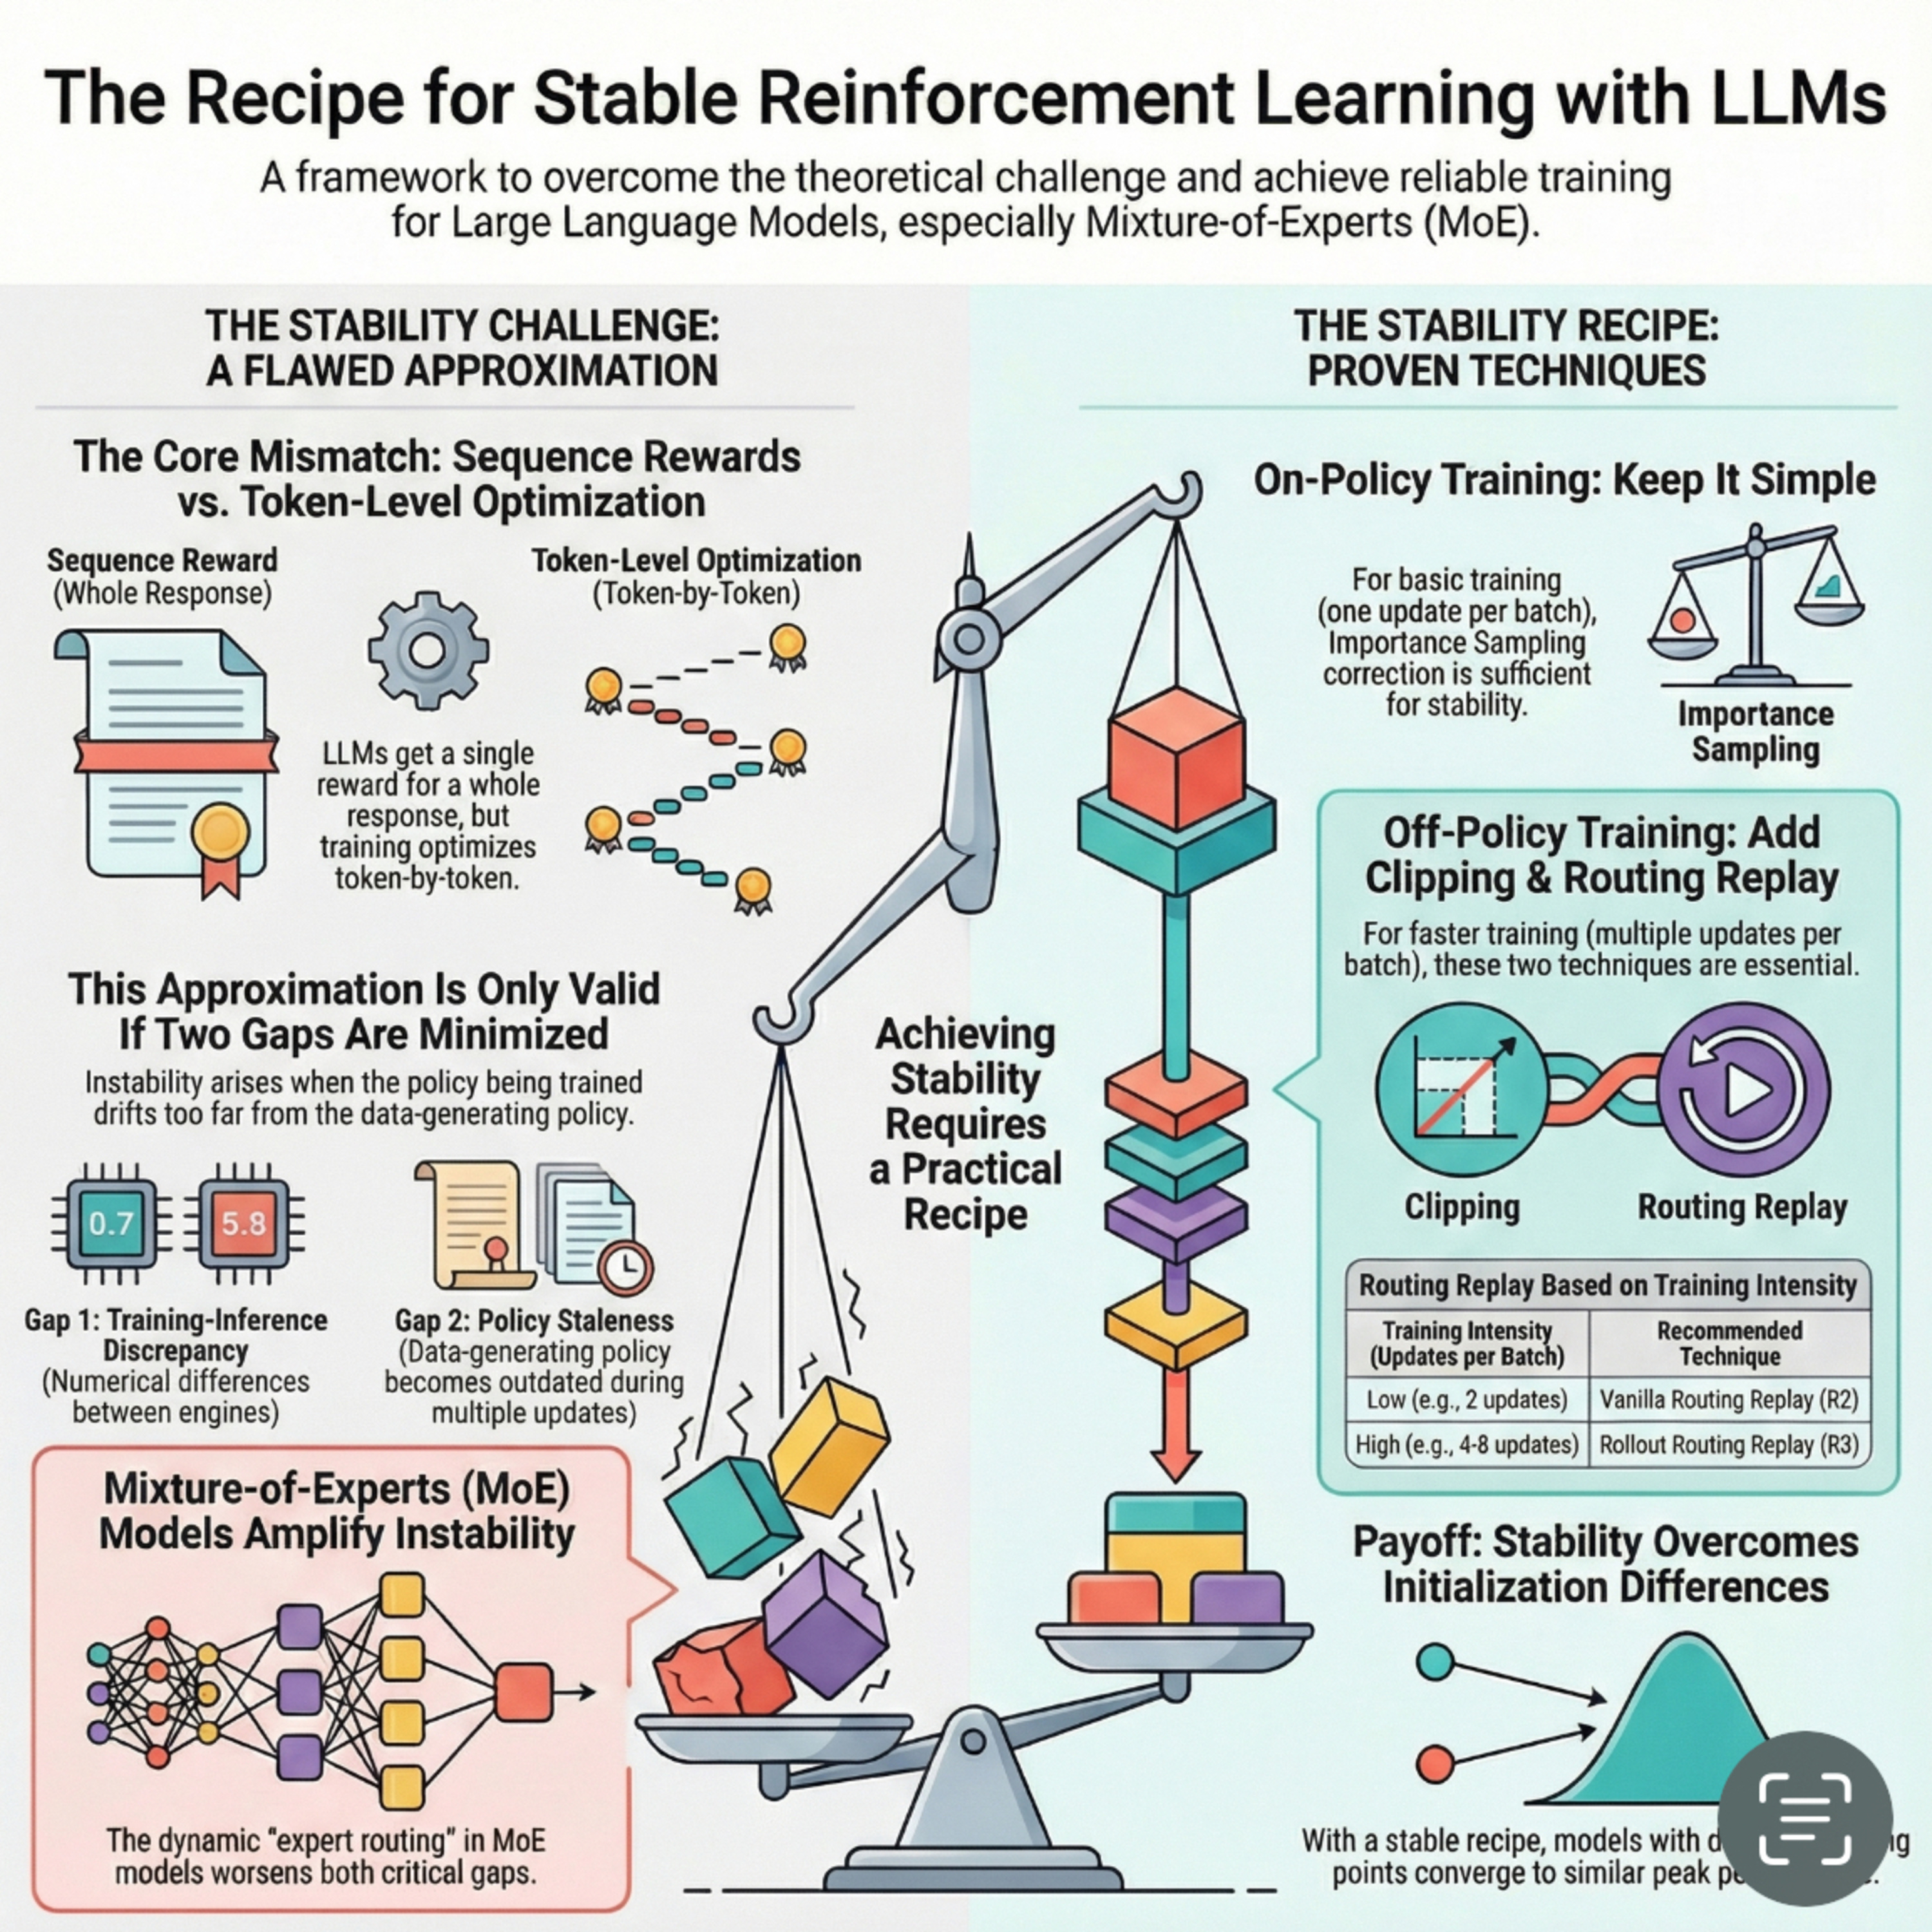
The research paper proposes a novel formulation for applying reinforcement learning (RL) to large language models (LLMs), specifically focusing on how a **sequence-level reward** can be optimized using a **surrogate token-level objective** in policy gradient methods. The authors theoretically justify this approximation, showing its validity relies on minimizing the **training-inference discrepancy** and **policy staleness**. Extensive experiments, conducted with a 30B Mixture-of-Experts (MoE) model named Qwen, empirically validate that techniques such as **importance sampling correction**, **clipping**, and particularly **Routing Replay** are crucial for achieving **stable RL training**. The findings suggest that stable training is a more decisive factor than cold-start initialization for achieving comparable final performance across different training setups.
Embed this episode
No transcript yet.