
EPISODE · Aug 3, 2025 · 13 MIN
The Great Undertraining: How a 70B Model Called Chinchilla Exposed the AI Industry's Billion-Dollar Mistake
from GenAI Level UP · host GenAI Level UP
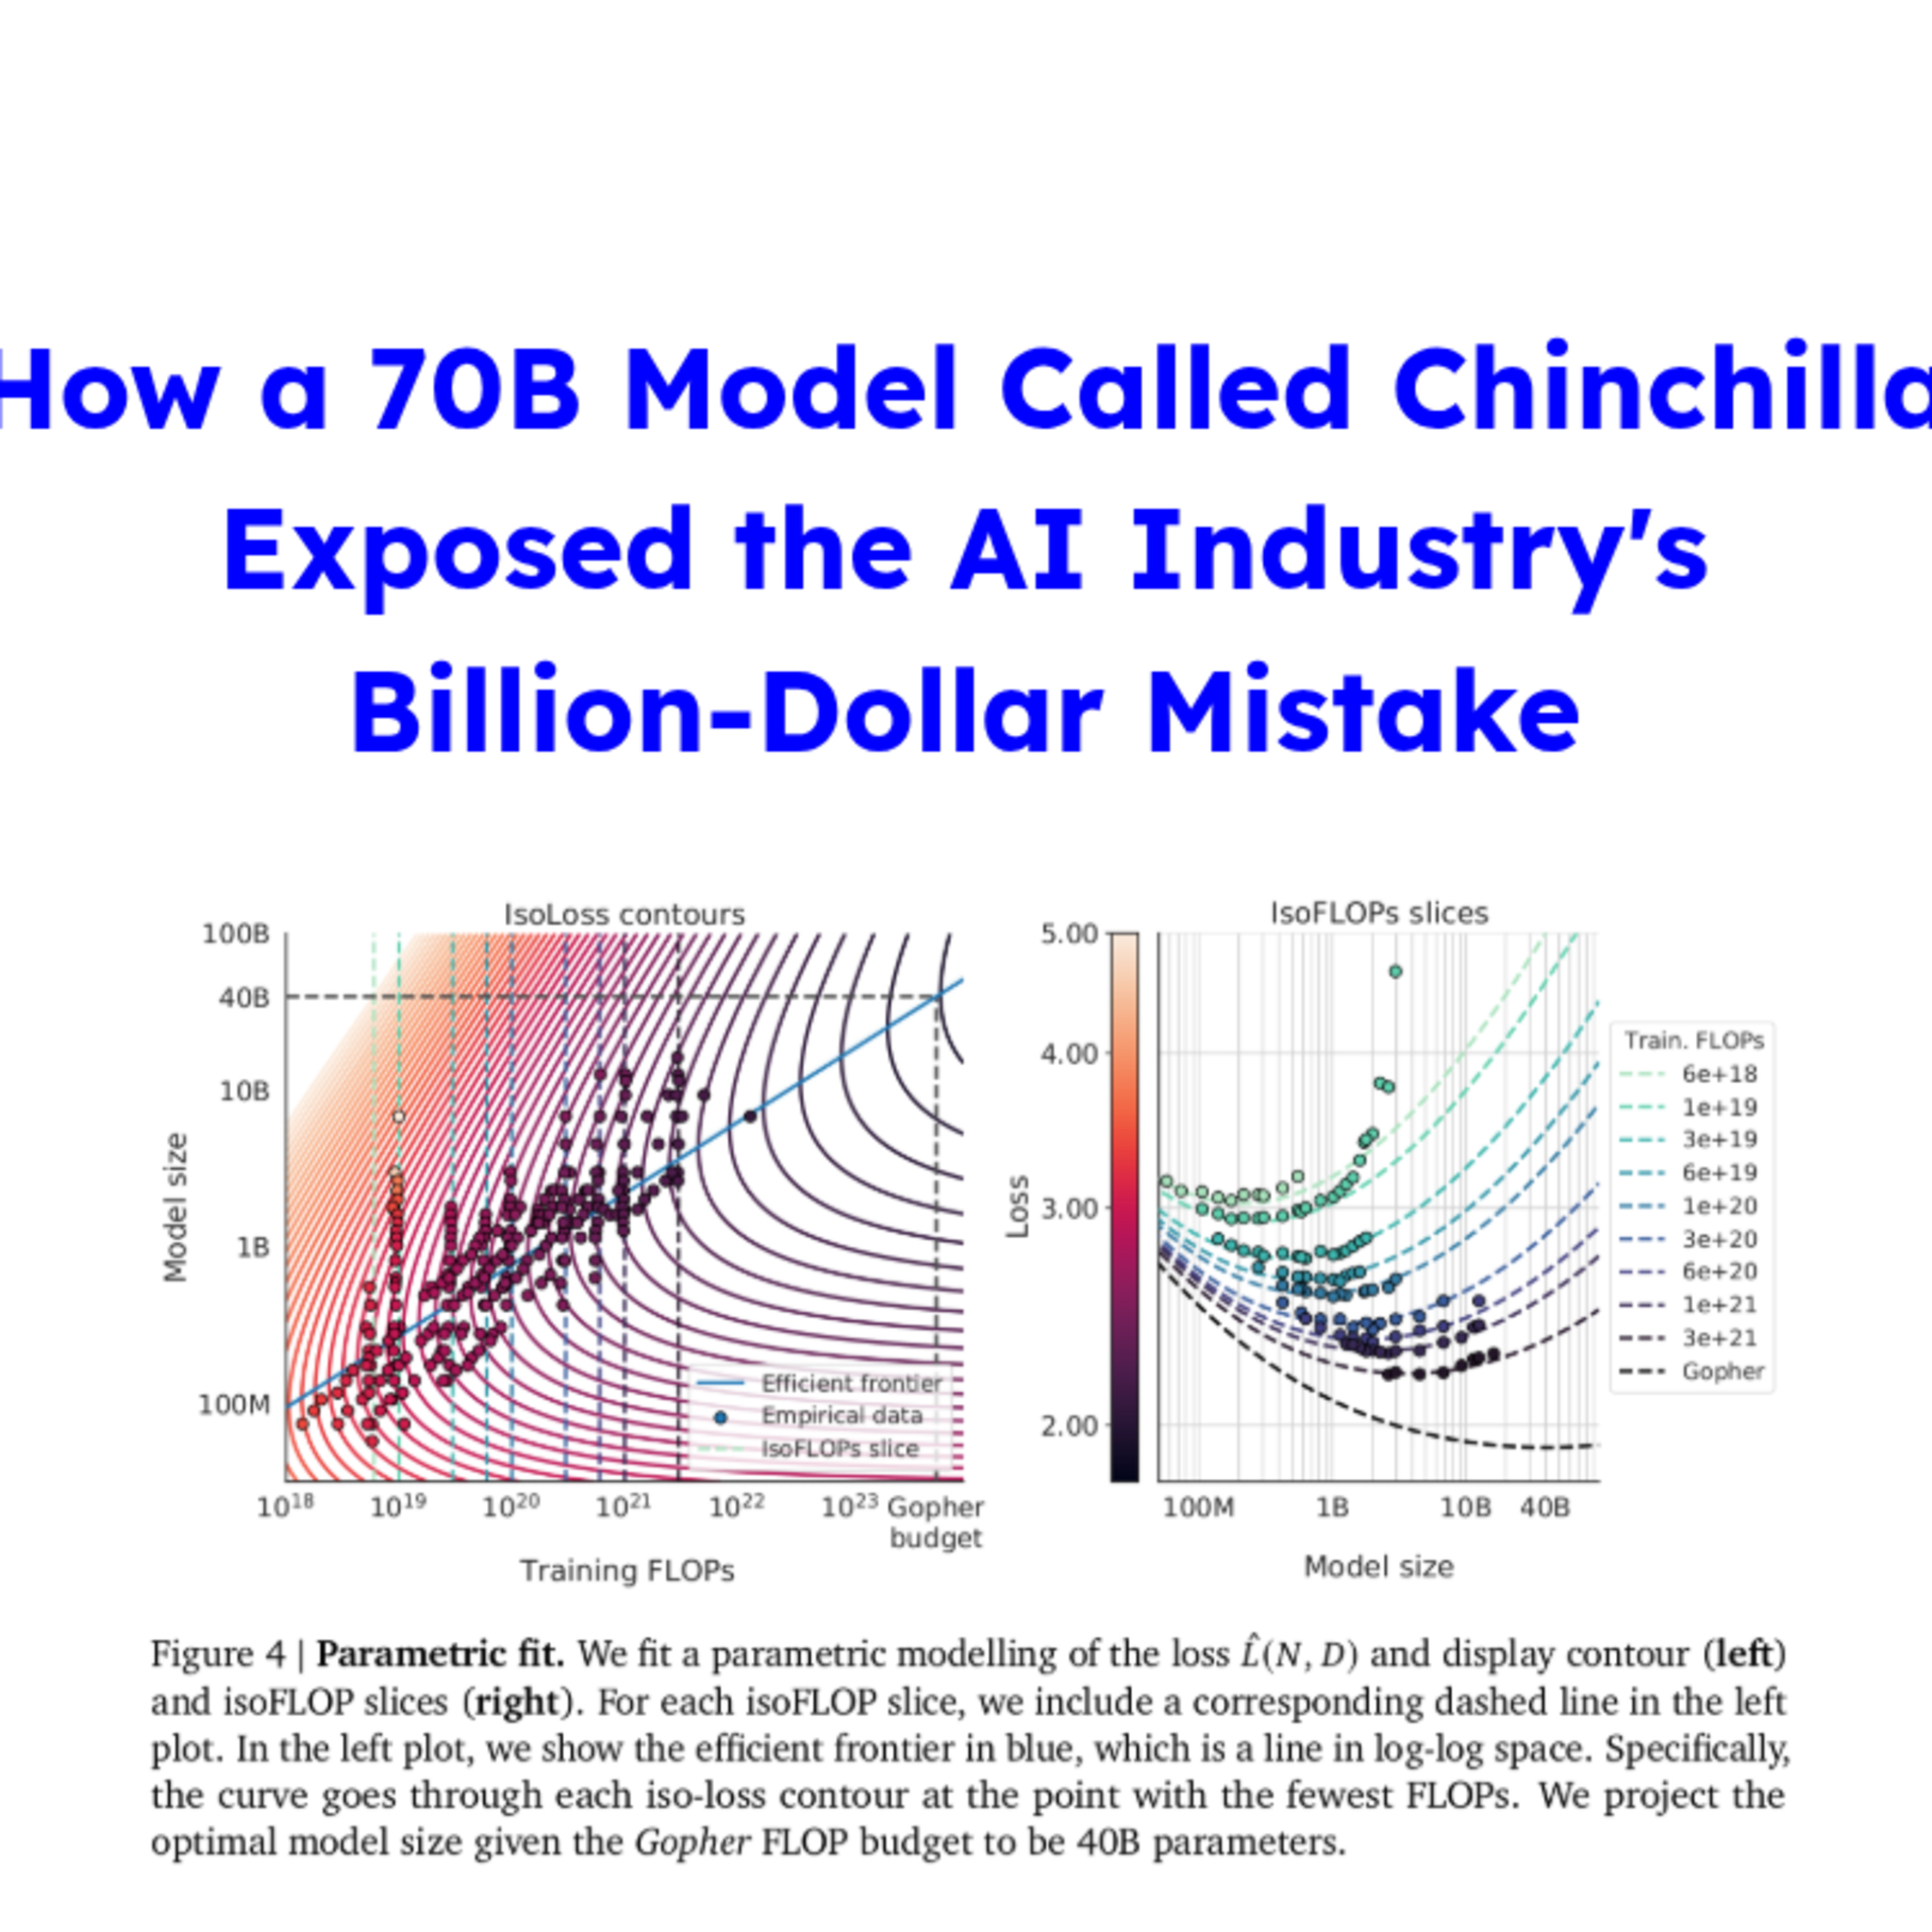
For years, a simple mantra has cost the AI industry billions: bigger is always better. The race to scale models to hundreds of billions of parameters—from GPT-3 to Gopher—seemed like a straight line to superior intelligence. But this assumption contains a profound and expensive flaw.This episode reveals the non-obvious truth: many of the world's most powerful LLMs are profoundly undertrained, wasting staggering amounts of compute on a suboptimal architecture. We dissect the groundbreaking research that proves it, revealing a new, radically more efficient path forward.Enter Chinchilla, a model from DeepMind that isn't just an iteration; it's a paradigm shift. We unpack how this 70B parameter model, built for the exact same cost as the 280B parameter Gopher, consistently and decisively outperforms it. This isn't just theory; it's a new playbook for building smarter, more efficient, and more capable AI. Listen now to understand the future of LLM architecture before your competitors do.In This Episode, You Will Learn:[01:27] The 'Bigger is Better' Dogma: Unpacking the hidden, multi-million dollar flaw in the conventional wisdom of LLM scaling.[03:32] The Critical Question: For a fixed compute budget, what is the optimal, non-obvious balance between model size and training data?[04:28] The 1:1 Scaling Law: The counterintuitive DeepMind breakthrough proving that model size and data must be scaled in lockstep—a principle most teams have been missing.[06:07] The Sobering Reality: Why giants like GPT-3 and Gopher are now considered "considerably oversized" and undertrained for their compute budget.[07:12] The Chinchilla Blueprint: Designing a model with a smaller brain but a vastly larger library, and why this is the key to superior performance.[08:17] The Verdict is In: The hard data showing Chinchilla's uniform outperformance across MMLU, reading comprehension, and truthfulness benchmarks.[10:10] The Ultimate Win-Win: How a smaller, smarter model delivers not only better results but a massive reduction in downstream inference and fine-tuning costs.[11:16] Beyond Performance: The surprising evidence that optimally trained models can also exhibit significantly less gender bias.[13:02] The Next Great Bottleneck: A provocative look at the next frontier—what happens when we start running out of high-quality data to feed these new models?
Embed this episode
Ready to play
The Great Undertraining: How a 70B Model Called Chinchilla Exposed the AI Industry's Billion-Dollar Mistake
No transcript for this episode yet
Similar Episodes
No similar episodes found.
Similar Podcasts
No similar podcasts found.