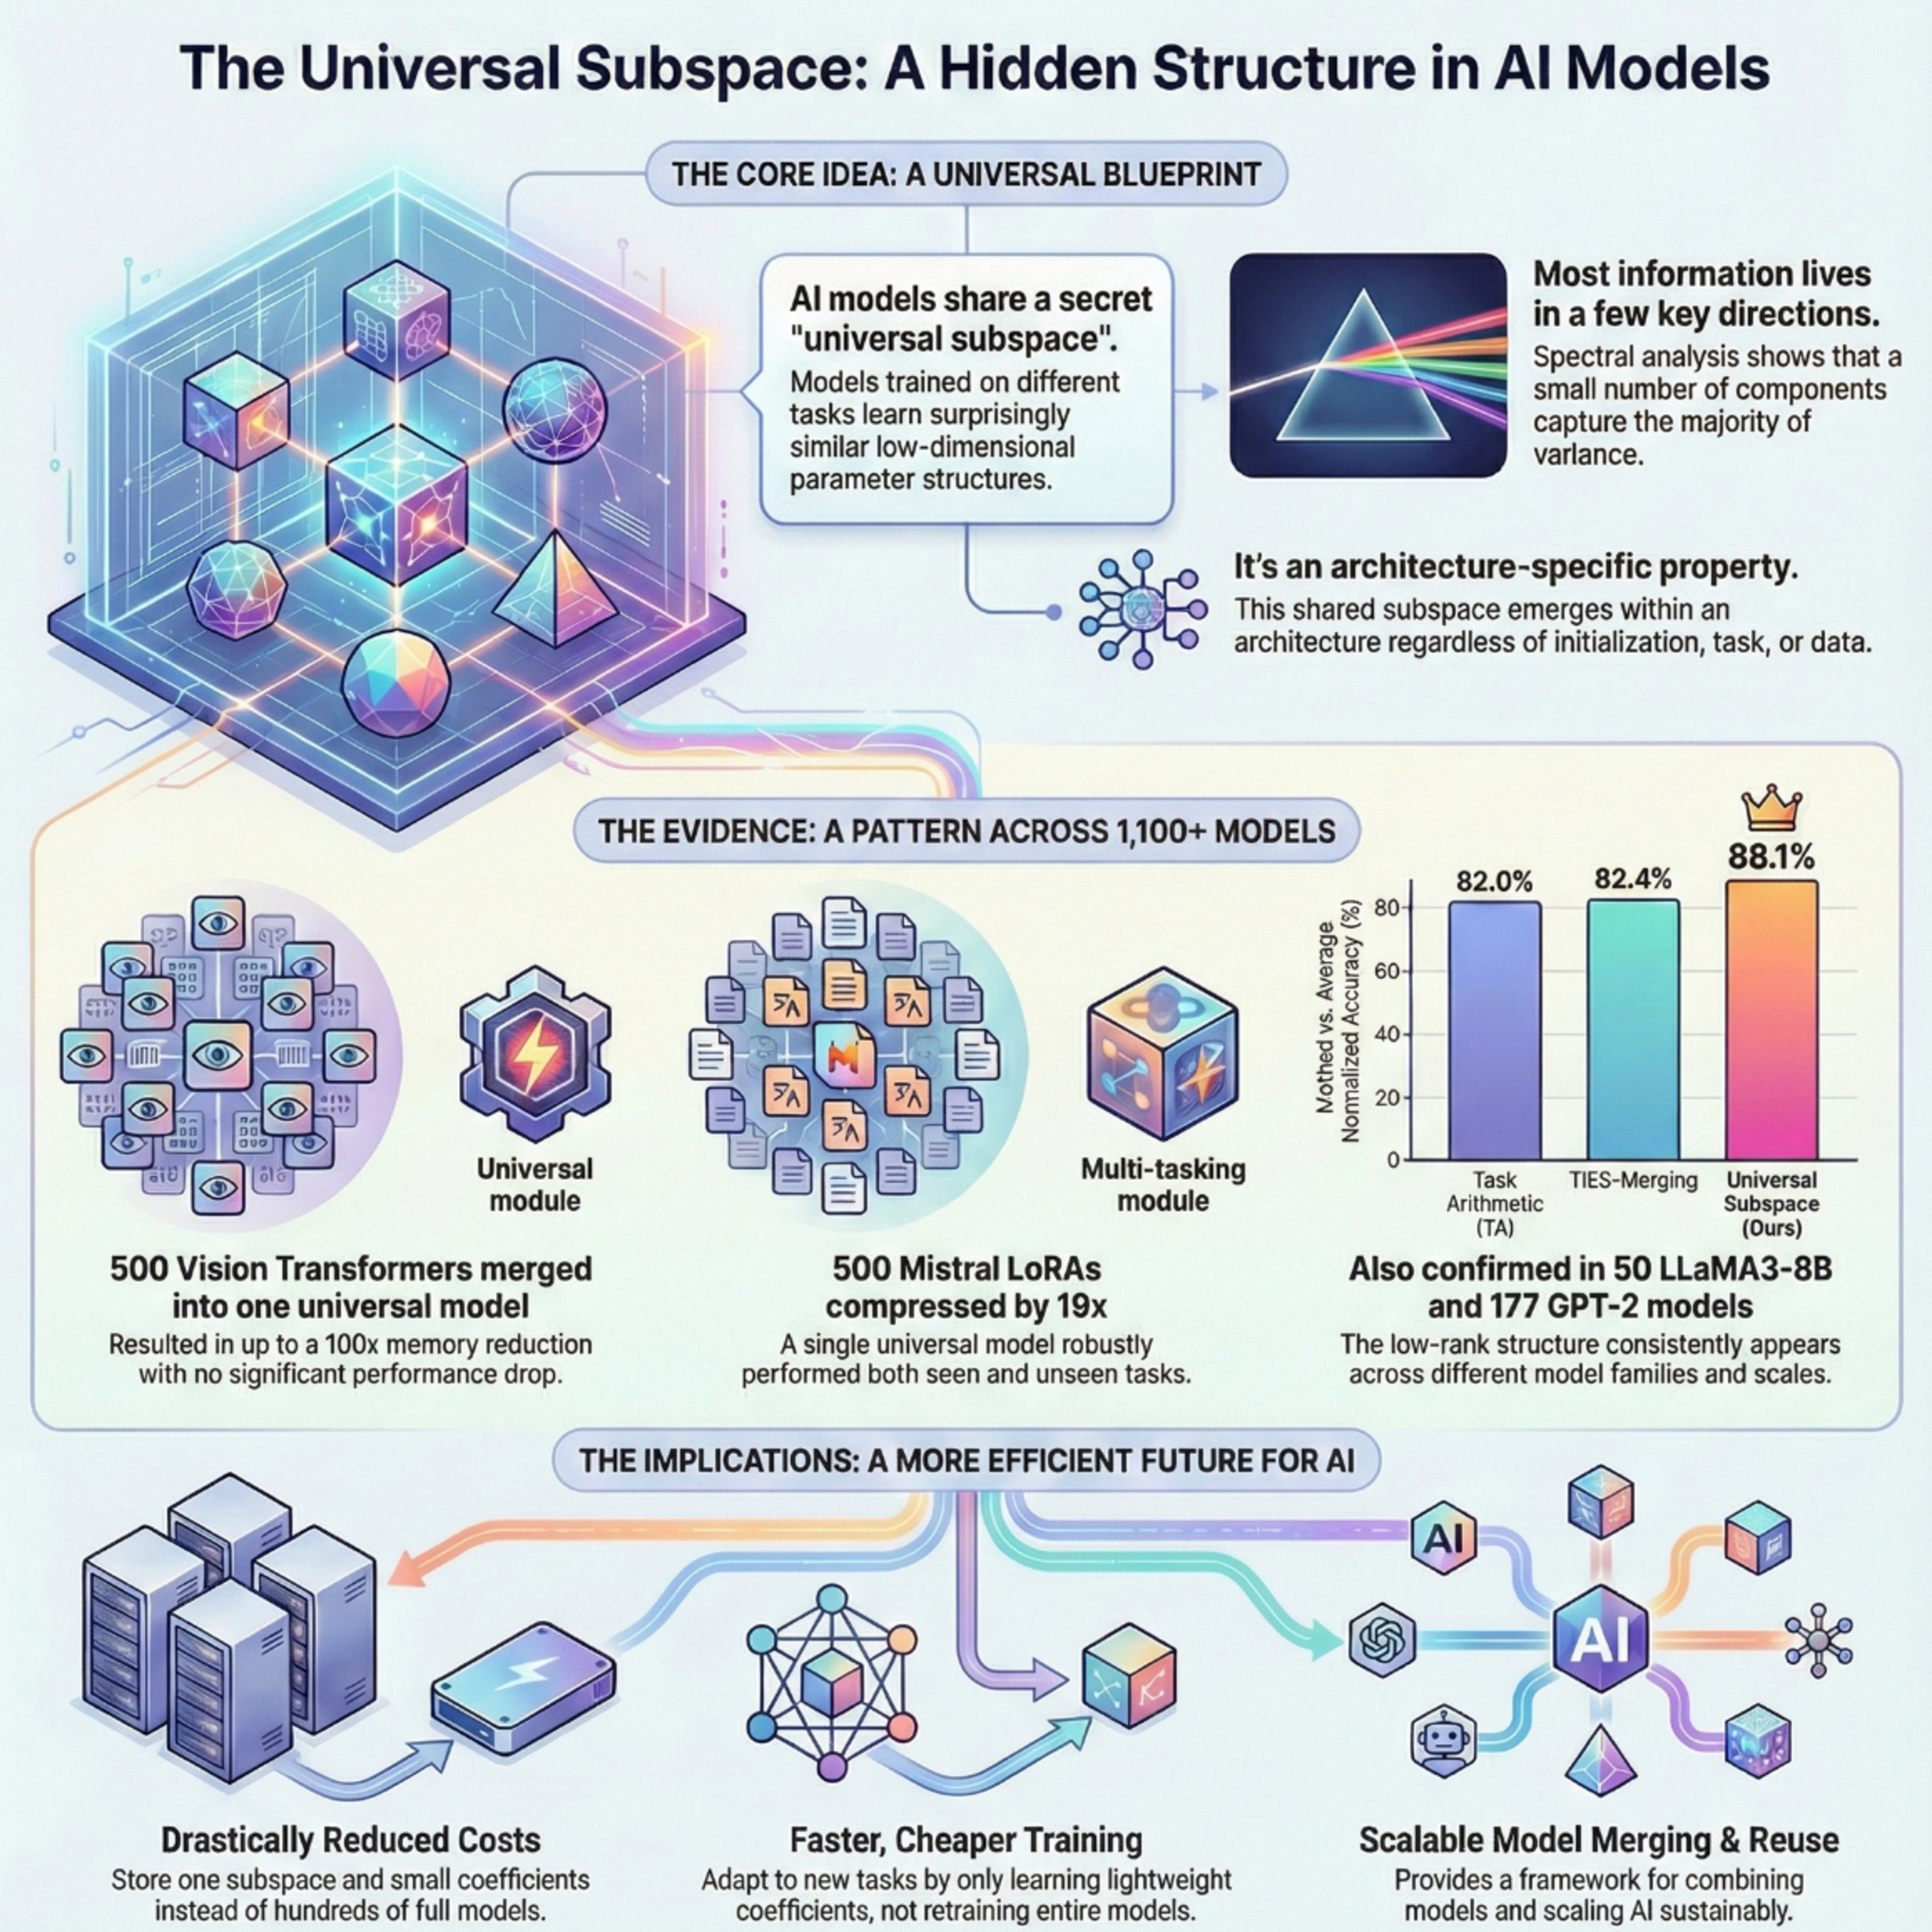
The Universal Weight Subspace Hypothesis
from Best AI papers explained Hosted by Enoch H. Kang
This paper presents a large-scale empirical analysis supporting **The Universal Weight Subspace Hypothesis**, which posits that deep neural networks, regardless of initialization, task, or domain, converge to remarkably similar low-dimensional parametric subspaces. This research demonstrates that a **small number of principal directions** consistently capture the majority of variance in the weight matrices of diverse architectures, including Vision Transformers, LLaMA, GPT-2, and LoRA adapters. Through spectral decomposition of over 1100 models, the authors identify these **sparse, joint subspaces**, suggesting that this inherent structure can be leveraged for significant gains in **model efficiency**, **compression**, **reusability**, and **faster adaptation** to new tasks. The findings are supported by **scree plots** and performance metrics showing that models projected onto this universal subspace retain competitive accuracy while dramatically reducing memory and computational requirements.
Embed this episode
No transcript yet.